Qwen3.5-Omni: Scaling Up, Toward Native Omni-Modal AGI
QWEN CHAT Hugging Face Offline Demo Hugging Face Realtime Demo ModelScope Offline Demo ModelScope Realtime Demo
Qwen3.5-Omni is Qwen’s latest generation of fully omnimodal LLM, supporting the understanding of text, images, audio, and audio-visual content. Both the Thinker and Talker in Qwen3.5-Omni adopt the Hybrid-Attention MoE. Qwen3.5-Omni series includes Instruct versions in three sizes: Plus, Flash, and Light, with support for 256k long-context input. The model can process more than 10 hours of audio input and over 400 seconds of 720P audio-visual input at 1 FPS. It is natively pretrained in an omnimodal manner on massive amounts of text, visual data, and more than 100 million hours of audio-visual data, demonstrating outstanding full-modality perception and generation capabilities. Compared with Qwen3-Omni, Qwen3.5-Omni offers significantly enhanced multilingual capabilities, supporting speech recognition in 113 languages/dialects and speech generation in 36 languages/dialects. It is currently available via the Offline API and Realtime API.
Offline
Qwen3.5-Omni-Plus has achieved SOTA results on 215 audio and audio-visual understanding, reasoning, and interaction subtasks/benchmarks, covering 3 audio-visual benchmarks, 5 audio benchmarks, 8 ASR benchmarks, 156 language-specific S2TT tasks, and 43 language-specific ASR tasks. In particular, it surpasses Gemini-3.1 Pro across general audio understanding, reasoning, recognition, translation, and dialogue, while its overall audio-visual understanding reaches the level of Gemini-3.1 Pro. Meanwhile, its visual and text capabilities match those of Qwen3.5 models of the same size. One of Qwen3.5-Omni-Plus’s standout features is its audio and audio-visual captioning capability, which can generate controllable, detailed, and structured captions, as well as screenplay-level fine-grained descriptions, including automatic segmentation, timestamp annotation, and detailed descriptions of characters and their relationship to audio. In addition, through native multimodal scaling, we observed the emergence of a new capability in omnimodal models: directly performing coding based on audio-visual instructions, which we call Audio-Visual Vibe Coding; all of the above features are available through the Offline API. We strongly encourage users to read the Demo Section.
Realtime
Beyond its strong base capabilities, we further focused on enhancing the interactive abilities of Qwen3.5-Omni. First, we support semantic interruption by developing native turn-taking intent recognition based on Omni, which avoids interruptions caused by backchanneling and meaningless background noise; this capability is already natively supported in the API. Second, we natively support WebSearch and complex FunctionCall capabilities, enabling the model to autonomously decide whether to invoke WebSearch to respond to users’ real-time questions. Third, we support end-to-end voice control and dialogue, allowing the model to follow instructions like a human and freely control aspects such as speaking volume, speed, and emotion. Fourth, Qwen3.5-Omni supports voice cloning, allowing users to upload a voice to customize the AI Assistant’s voice; all of the above features are available through the Realtime API. Users can also modify the system prompt to change the model’s behavior, such as its conversational style or identity. Fifth, to address speech instability in streaming voice interaction caused by differences in text and speech token encoding efficiency—such as omissions, misreadings, or unclear pronunciation of numbers—we propose ARIA (Adaptive Rate Interleave Alignment), a technique that dynamically aligns text and speech units. While preserving real-time performance, ARIA significantly improves the naturalness and robustness of speech synthesis. We strongly encourage users to read the Demo Section to experience the model’s latest capabilities.
Performance#
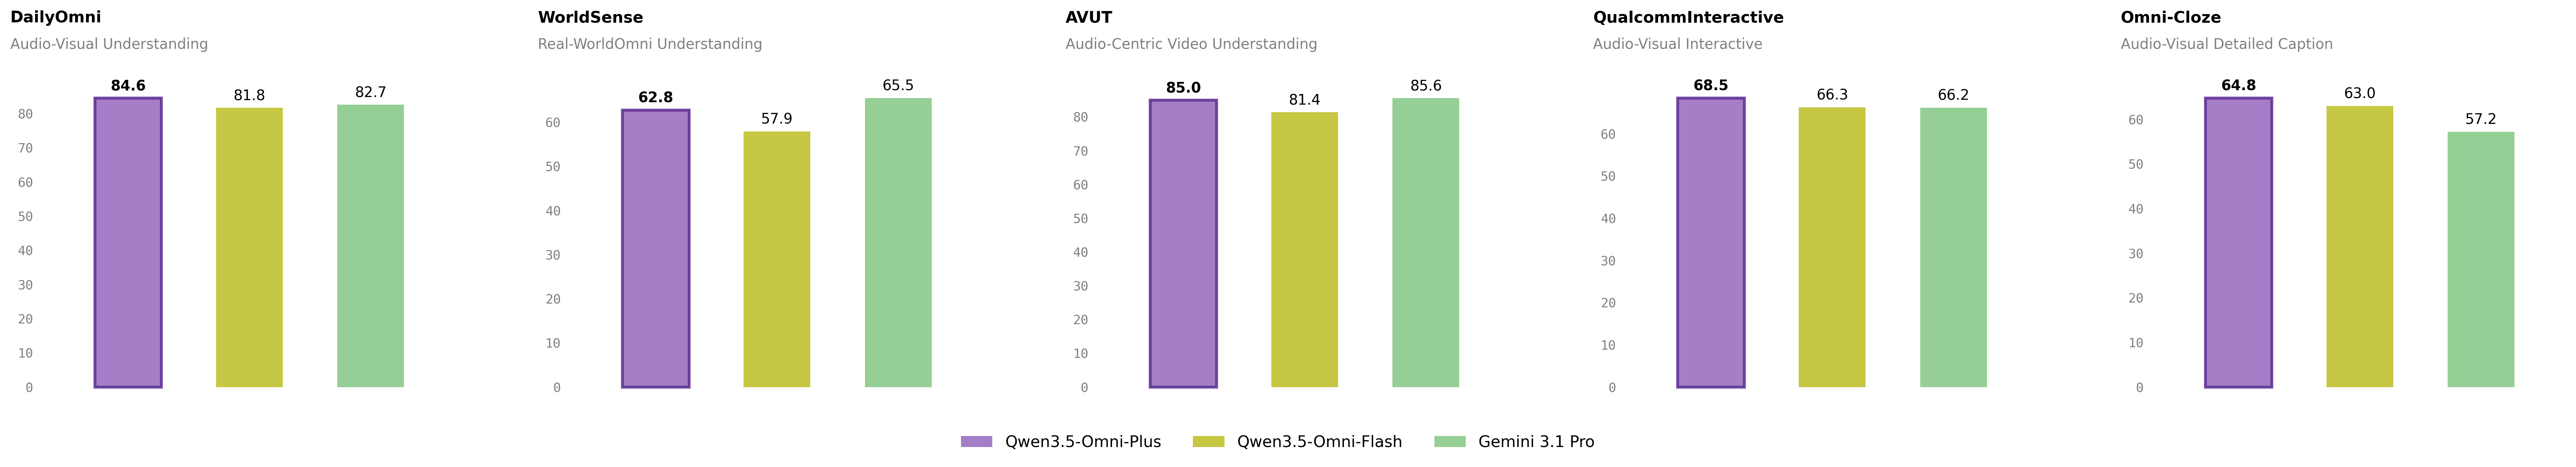
Audio-Visual Next
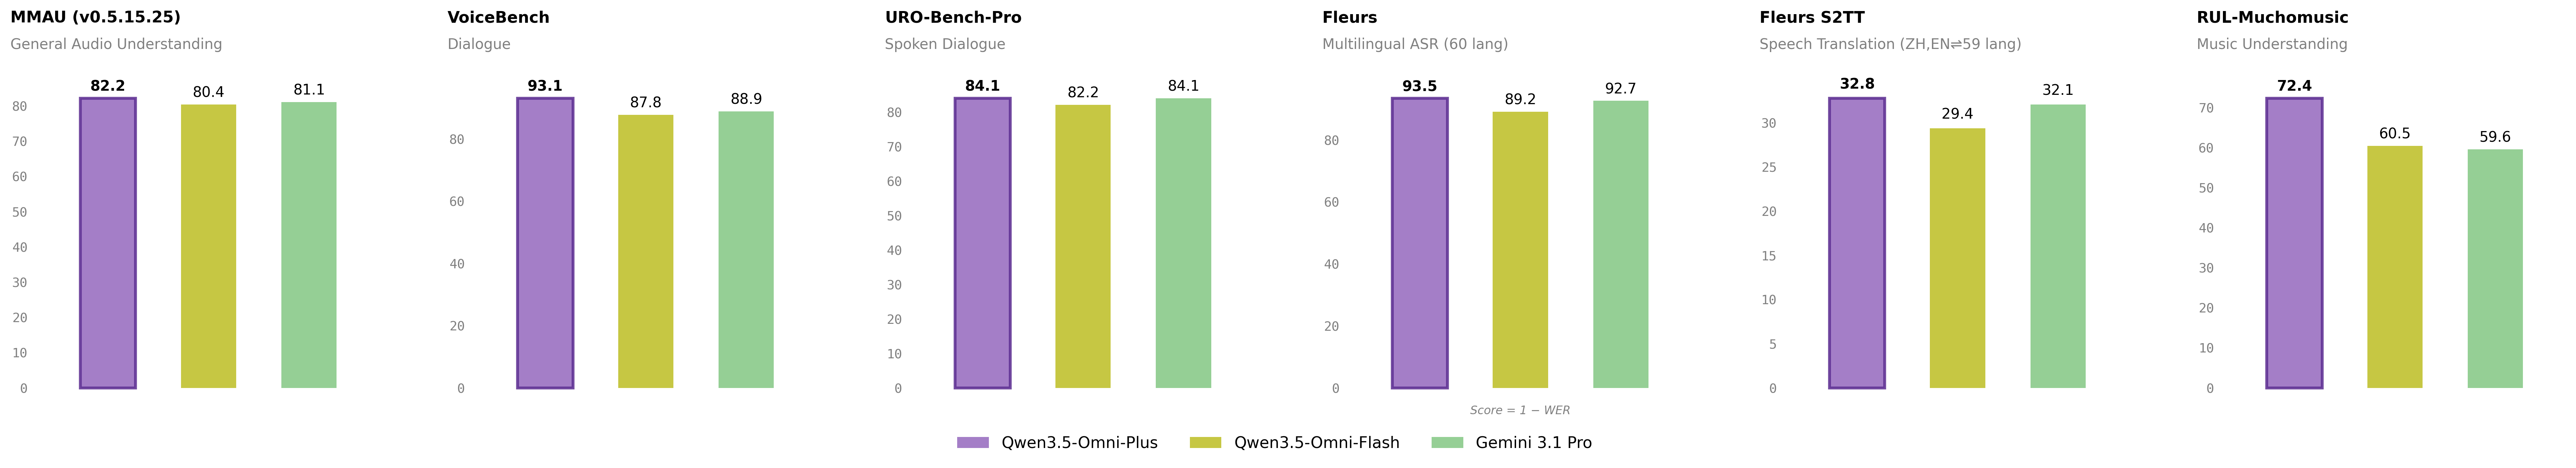
Audio Next
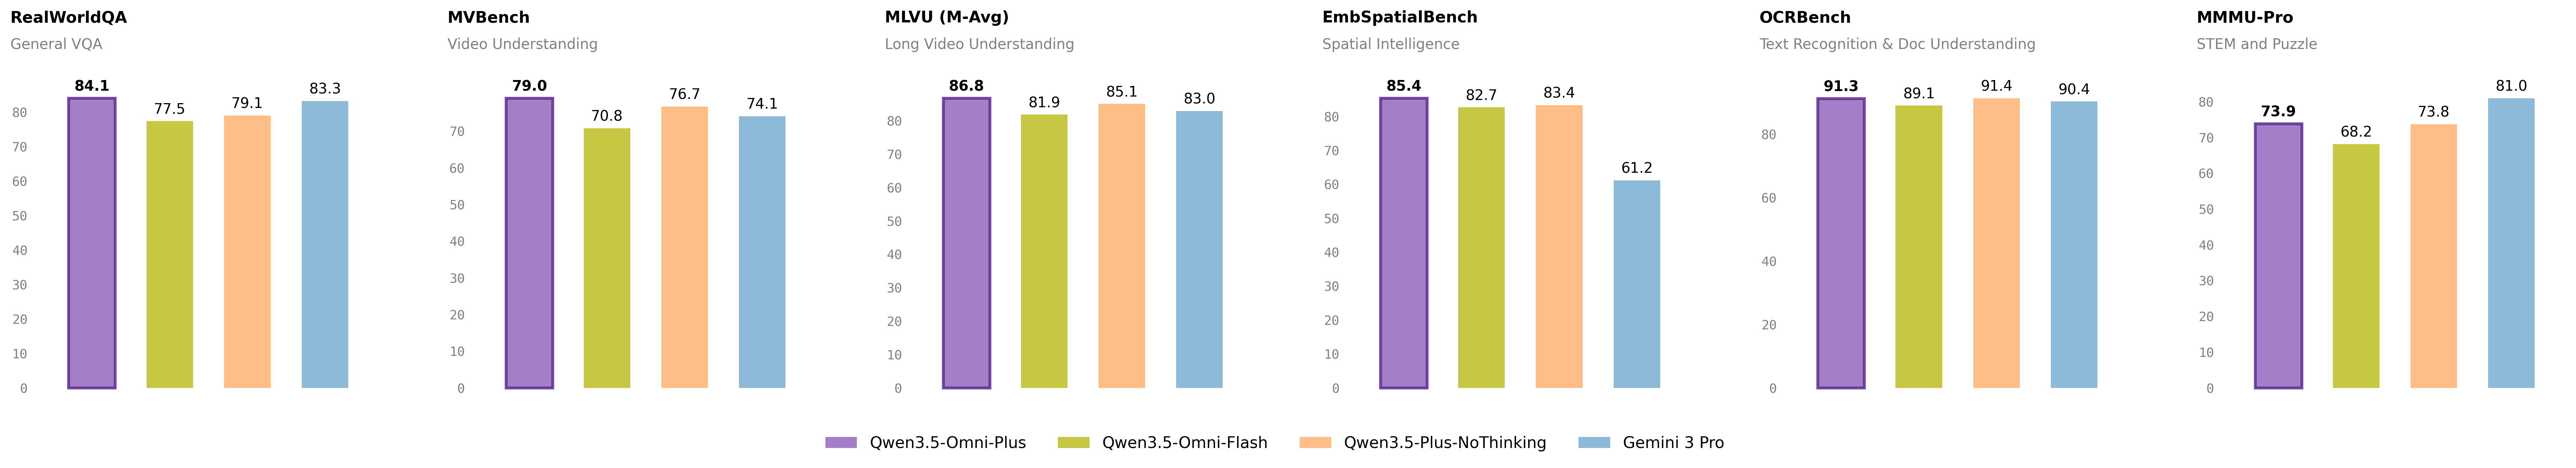
Visual Next
Text Next
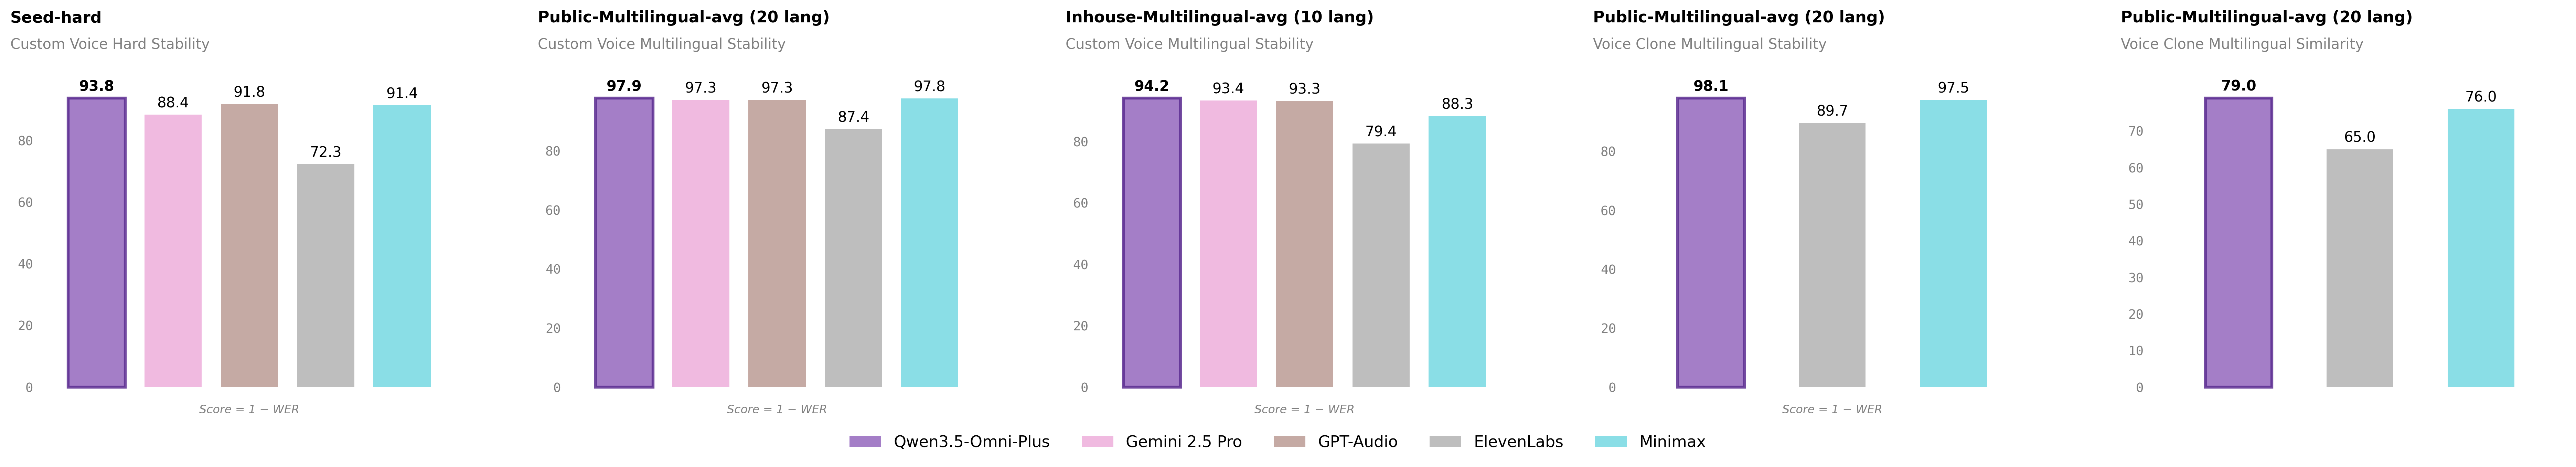
Speech Generation Next
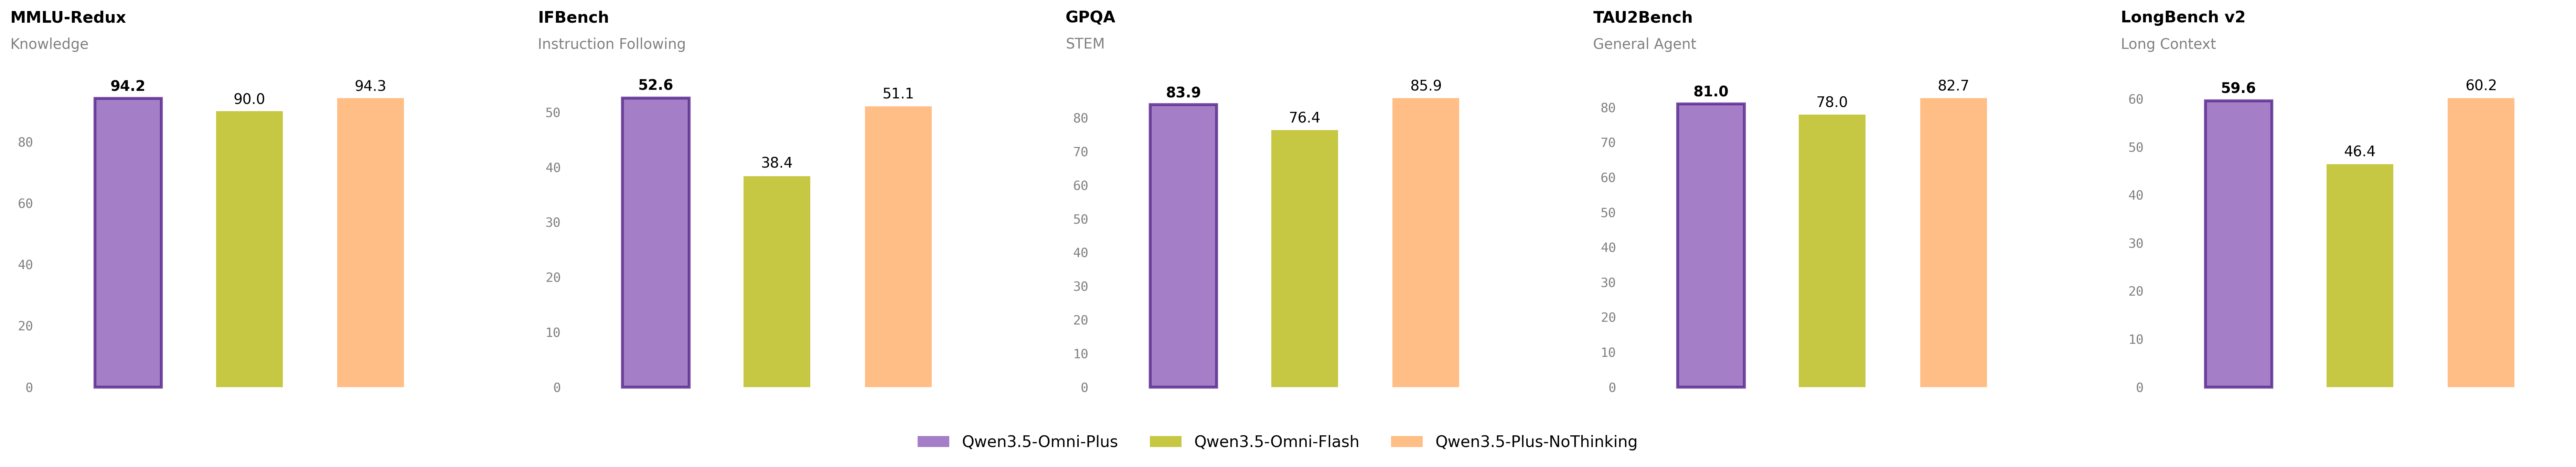
Below we present the comprehensive evaluation of our models against frontier models in a wide range of evaluation tasks, covering different tasks and modalities.
Audio-Visual#
| Gemini-3.1 Pro | Qwen3.5-Omni-Flash | Qwen3.5-Omni-Plus | |
|---|---|---|---|
| Text Query QA | |||
| DailyOmni | 82.7 | 81.8 | 84.6 |
| WorldSense | 65.5 | 57.9 | 62.8 |
| AVUT | 85.6 | 81.4 | 85.0 |
| AV-SpeakerBench | 75.1 | 65.2 | 71.3 |
| VideoMME (with audio) | 89.0 | 79.3 | 83.7 |
| Audio Query QA | |||
| QualcommInteractive | 66.2 | 66.3 | 68.5 |
| Caption | |||
| Omni-Cloze | 57.2 | 63.0 | 64.8 |
| Agent (tool use) | |||
| OmniGAIA | 68.9 | 33.9 | 57.2 |
* VideoMME (with audio): We evaluate our model with use_audio_in_video=True.
* OmniGAIA:We evaluate our model without a thinking prompt and without <answer> formatting. All results are evaluated using deepseek-v3.2-thinking.
Audio#
| Gemini-3.1-Pro | Qwen3.5-Omni-Flash | Qwen3.5-Omni-Plus | |
|---|---|---|---|
| Audio Understanding | |||
| MMAU | 81.1 | 80.4 | 82.2 |
| MMAR | 83.7 | 74.0 | 80.0 |
| MMSU | 81.3 | 72.2 | 82.8 |
| RUL-MuchoMusic | 59.6 | 60.5 | 72.4 |
| SongFormBench-HarmonixSet(acc|hr.5f|hr3f) | 75.6 | 46.8 | 77.9 | 80.6 | 67.8 | 83.4 | 81.1 | 72.9 | 85.3 |
| SongFormBench-CN(acc|hr.5f|hr3f) | 78.1 | 43.2 | 71.9 | 86.7 | 66.4 | 84.6 | 87.1 | 65.7 | 84.2 |
| Dialogue | |||
| VoiceBench | 88.9 | 87.8 | 93.1 |
| URO-Bench-Pro(U|R|O) | 69.1 | 84.0 | 99.2 | 64.1 | 83.8 | 98.7 | 66.3 | 86.3 | 99.8 |
| SpeechRole | 124.2 | 119.8 | 123.5 |
| WildSpeech-Bench | 76.3 | 72.2 | 75.4 |
| S2TT | |||
| Fleursxx⇄zh (top59) | 29.5 | 26.9 | 30.2 |
| Fleursxx⇄en (top59) | 34.6 | 32.0 | 35.4 |
| Fleursxx⇄zh/en (top59) | 32.1 | 29.4 | 32.8 |
| ASR | |||
| Fleurs(top60) | 7.32 | 10.75 | 6.55 |
| CV15(zh|yue|zh-tw) | 8.59 | 13.40 | 6.78 | 4.25 | 3.45 | 2.68 | 3.46 | 1.95 | 2.27 |
| CV15(en) | 8.73 | 5.90 | 4.83 |
| Librispeech(clean|other) | 3.36 | 4.41 | 1.30 | 2.43 | 1.11 | 2.23 |
| Wenetspeech(net|meeting) | 11.53 | 14.21 | 4.41 | 5.51 | 4.30 | 5.84 |
| Kespeech | 23.67 | 4.47 | 3.46 |
| MIR-1K(vocal-only) | 8.76 | 4.94 | 4.56 |
| Opencpop | 6.83 | 1.11 | 1.49 |
* SongFormBench: We use a unified prompt defining an SRT-like output timestamp format and a closed vocabulary for evaluation. The vocabulary follows the 'SongForm-HX-8Class' specified in the official codebase.
* URO-Bench-Pro: We use the pro track of URO-Bench and denote the three evaluation dimensions as follows: U for Understanding, R for Reasoning, and O for Oral Conversation. We use GenStyle-en, GenStyle-zh, Multilingual tasks for oral dimension.
* ASR performance is evaluated using WER/CER, where lower values indicate better performance.
* Fleurs: The top59 languages are English, Chinese, Cantonese, Korean, Japanese, Vietnamese, Thai, Malay, German, Russian, Italian, French, Spanish, Portuguese, Dutch, Indonesian, Turkish, Arabic, Polish, Hindi, Urdu, Filipino, Persian, Czech, Greek, Swedish, Hebrew, Danish, Finnish, Norwegian, Icelandic, Bengali, Punjabi, Javanese, Marathi, Swahili, Ukrainian, Gujarati, Kannada, Azerbaijani, Malayalam, Cebuano, Kazakh, Romanian, Hungarian, Bulgarian, Belarusian, Catalan, Tamil, Croatian, Bosnian, Slovak, Galician, Kyrgyz, Macedonian, Slovenian, Latvian, Estonian, and Asturian; compared with the top60 list, Afrikaans is excluded because the Fleurs S2TT test set does not cover this language.
* MIR-1K: Transcription is converted into Simplified Chinese.
Visual#
| Qwen3.5-Plus-NoThinking | Qwen3.5-Omni-Flash | Qwen3.5-Omni-Plus | |
|---|---|---|---|
| STEM and Puzzle | |||
| MMMU | 81.0 | 76.9 | 80.1 |
| MMMU-Pro | 73.8 | 68.2 | 73.9 |
| MathVision | 73.6 | 65.4 | 73.0 |
| Mathvista (mini) | 86.9 | 82.9 | 86.1 |
| DynaMath | 84.2 | 79.3 | 83.8 |
| ZEROBench | 6 | 1 | 5 |
| ZEROBench_sub | 31.1 | 26.0 | 34.4 |
| General VQA | |||
| RealWorldQA | 79.1 | 77.5 | 84.1 |
| MMStar | 80.3 | 75.7 | 79.4 |
| MMBenchEN-DEV-v1.1 | 93.8 | 88.8 | 92.8 |
| SimpleVQA | 66.1 | 54.4 | 65.3 |
| Text Recognition and Document Understanding | |||
| CharXiv (RQ) | 74.2 | 64.4 | 72.5 |
| CC-OCR | 83.0 | 80.8 | 83.4 |
| AI2D_TEST | 92.1 | 89.0 | 91.2 |
| MMLongBench-Doc | 59.7 | 53.6 | 57.5 |
| OCRBench | 91.4 | 89.1 | 91.3 |
| Spatial Intelligence | |||
| ERQA | 53.8 | 50.0 | 54.8 |
| CountBench | 95.1 | 88.2 | 95.1 |
| RefCOCO(avg) | 95.2 | 92.6 | 95.0 |
| ODInW13 | 50.3 | 46.8 | 49.5 |
| EmbSpatialBench | 83.4 | 82.7 | 85.4 |
| Video Understanding | |||
| VideoMME(w/o sub.) | 81.0 | 77.0 | 81.9 |
| MLVU(M-Avg) | 85.1 | 81.9 | 86.8 |
| MVBench | 76.7 | 70.8 | 79.0 |
| LVBench | 68.6 | 65.7 | 71.2 |
| MMVU | 67.1 | 62.7 | 67.5 |
| MME-VideoOCR | 74.2 | 70.5 | 77.0 |
| Medical VQA | |||
| SLAKE | 82.8 | 73.1 | 84.7 |
| PMC-VQA | 62.4 | 58.7 | 62.7 |
| MedXpertQA-MM | 55.3 | 44.8 | 54.7 |
Text#
| Qwen3.5-Plus-NoThinking | Qwen3.5-Omni-Flash | Qwen3.5-Omni-Plus | |
|---|---|---|---|
| Knowledge | |||
| MMLU-Pro | 86.8 | 79.9 | 85.9 |
| MMLU-Redux | 94.3 | 90.0 | 94.2 |
| SuperGPQA | 67.4 | 54.9 | 66.4 |
| C-Eval | 92.3 | 86.0 | 92.0 |
| Instruction Following | |||
| IFEval | 89.7 | 85.2 | 89.7 |
| IFBench | 51.1 | 38.4 | 52.6 |
| Long Context | |||
| AA-LCR | 62.0 | 46.0 | 57.0 |
| LongBench v2 | 60.2 | 46.4 | 59.6 |
| STEM | |||
| GPQA | 85.9 | 76.4 | 83.9 |
| Reasoning | |||
| LiveCodeBench v6 | 67.1 | 56.6 | 65.6 |
| HMMT Nov 25 | 86.2 | 59.0 | 84.4 |
| IMOAnswerBench | 68.3 | 51.5 | 65.5 |
| General Agent | |||
| BFCL-V4 | 66.1 | 55.3 | 63.3 |
| TAU2Bench | 82.7 | 78.0 | 81.0 |
* Qwen3.5-Plus-NoThinking: we use Qwen3.5-Plus-NoThinking as the primary baseline, since all models here are evaluated in the same no-thinking setting.
* TAU2-Bench: we follow the official setup except for the airline domain, where all models are evaluated by applying the fixes proposed in the Claude Opus 4.5 system card.
Speech-Generation#
| ElevenLabs | Gemini-2.5 Pro | GPT-Audio | Minimax | Qwen3.5-Omni-Plus | |
|---|---|---|---|---|---|
| Custom Voice Stability | |||||
| Seed-zh | 13.08 | 2.42 | 1.11 | 1.19 | 1.07 |
| Seed-en | 1.17 | 1.18 | 1.16 | 1.35 | 1.35 |
| Seed-hard | 27.70 | 11.57 | 8.19 | 8.62 | 6.24 |
| Public-Multilingual-avg (20 lang) | 12.62 | 2.72 | 2.65 | 2.16 | 2.06 |
| Inhouse-Multilingual-avg (9 lang) | 20.63 | 6.61 | 6.72 | 11.71 | 5.82 |
* Stability is measured by Word Error Rate (WER, ↓).
* "Public-Multilingual-avg" refers to the average performance on the public TTS-Multilingual-Test-Set, covering 20 languages.
* "Inhouse-Multilingual-avg" refers to the average performance on an internal multilingual test set built upon Fleurs, covering 9 languages.
* The performance is tested with the following APIs: ElevenLabs-Multilingual-V2 (9YHcvj6GT2YYXdXww), Gemini-2.5 Pro-Preview-TTS (Achernar), GPT-Audio-2025-08-28 (Alloy) and Minimax-Speech-2.8-HD (English_expressive_narrator) in March 2026.
| ElevenLabs | Minimax | Ground-Truth | Qwen3.5-Omni-Plus | |
|---|---|---|---|---|
| Voice Clone Stability | ||||
| Public-Multilingual-avg (20 lang) | 10.29 | 2.52 | - | 1.87 |
| Inhouse-Multilingual-avg (9 lang) | - | - | 9.68 | 7.04 |
| Voice Clone Similarity | ||||
| Public-Multilingual-avg (20 lang) | 0.65 | 0.76 | - | 0.79 |
| Inhouse-Multilingual-avg (9 lang) | - | - | - | 0.80 |
* Stability is measured by Word Error Rate (WER, ↓) and similarity is measured by Cosine Similarity (SIM, ↑).
* "Public-Multilingual-avg" refers to the average performance on the public TTS-Multilingual-Test-Set, covering 20 languages.
* "Inhouse-Multilingual-avg" refers to the average performance on an internal multilingual test set built upon Fleurs, covering 9 languages.
* Empty cells (-) indicate scores not yet available or not applicable.
Architecture#
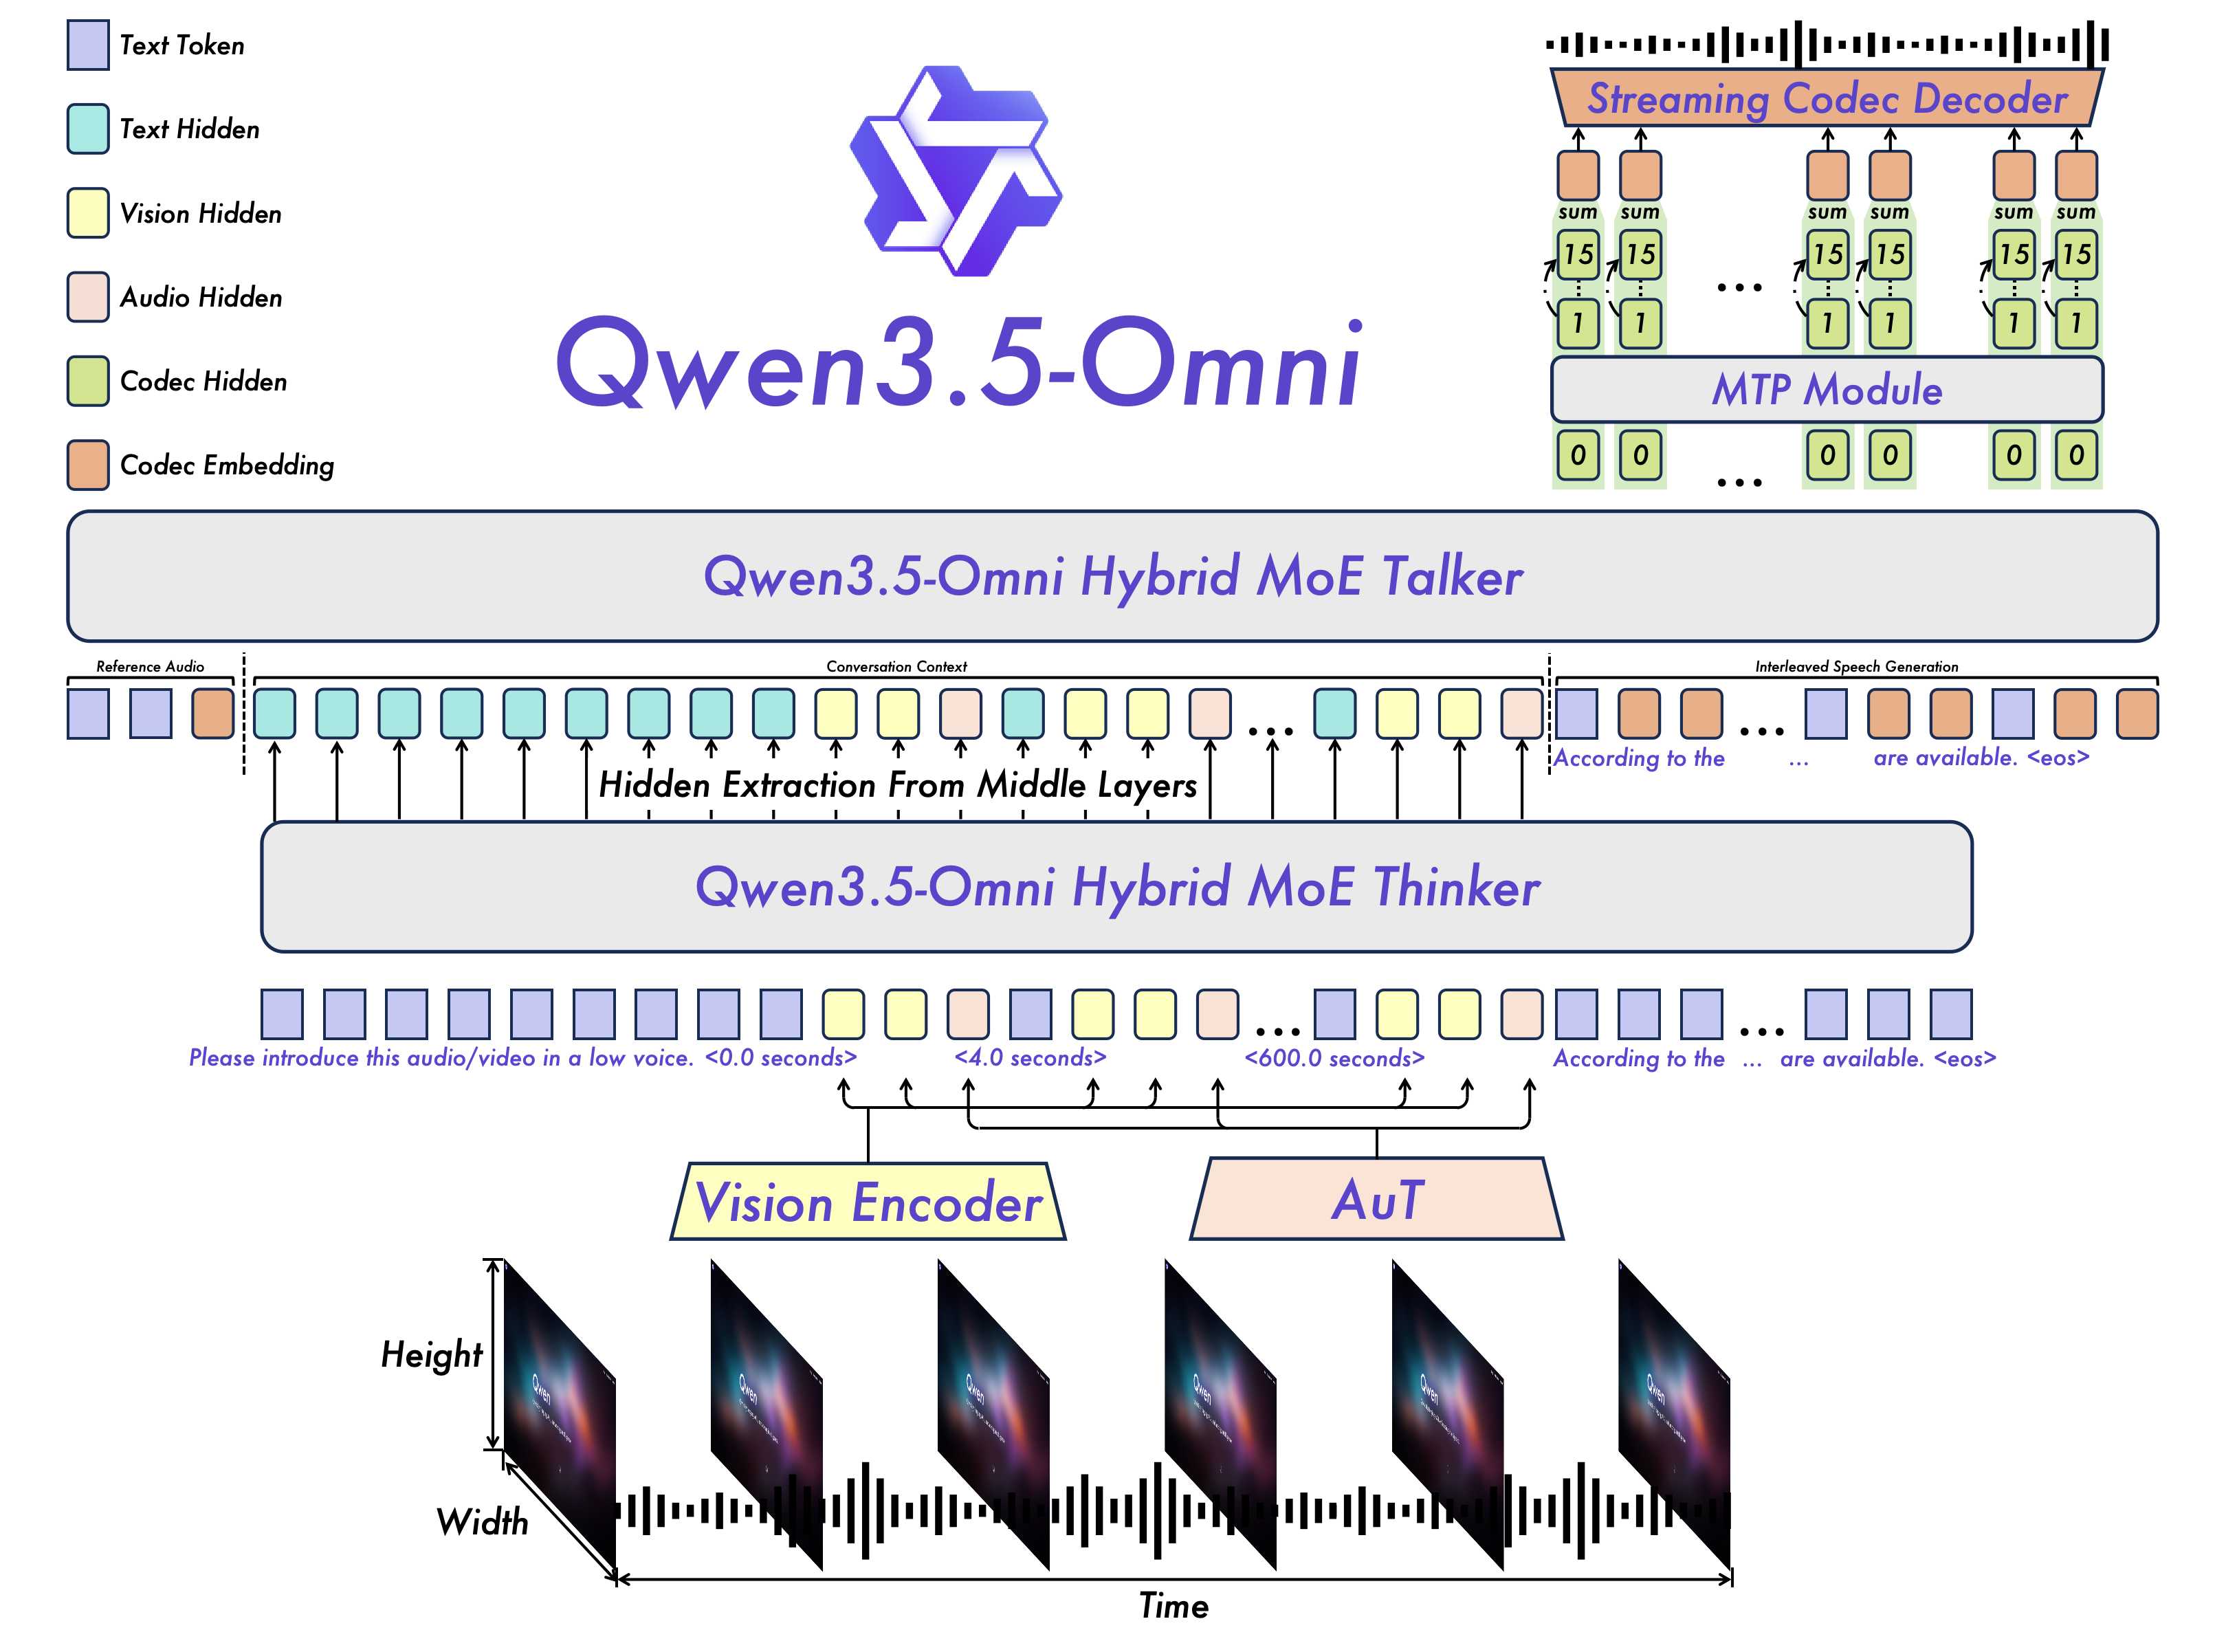
Qwen3.5-Omni continues to adopt the Thinker-Talker architecture. The Thinker receives visual and audio signals through the Vision Encoder and AuT, while audio-visual signals are interleaved and encoded with positional information using TMRoPE. The Thinker is responsible for processing omnimodal signals and outputting text, while the Talker receives multimodal inputs and text outputs from the Thinker to perform contextual speech generation. Speech representations are encoded with the RVQ method proposed in Qwen3-Omni, replacing the computationally heavy DiT operations. Thanks to the chunk-wise streaming input design and the streaming Talker design, the entire model supports realtime interaction. Unlike the dual-track Talker input in the previous generation Qwen3-Omni, the Talker adopts ARIA (Adaptive Rate Interleave Alignment) in its input organization to dynamically align text and speech units and then interleave them, thereby avoiding speech instability caused by differences in text and speech token encoding efficiency, such as omissions, misreadings, or unclear pronunciation of numbers.
Qwen3.5-Omni vs Qwen3-Omni#
| Qwen3-Omni | Qwen3.5-Omni | |
|---|---|---|
| Backbone | MoE | Hybrid-MoE |
| Sequence Length | 32k | 256k Audio: 10 hours Audio-Visual (FPS=1): 400 seconds |
| Captioning Capability | Audio | Audio-Visual |
| Intelligent Semantic Interruption | Not Supported | Supported |
| WebSearch/Tool | Not Supported | Supported |
| Voice Control | Not Supported | Supported |
| Voice Clone | Not Supported | Supported |
| Talker | Dual-Track Autoregression | Interleave |
| Text-Audio Tokenizer Rate | Fixed (1:1) | ARIA (Adaptive Rate Interleaved Alignment) |
| Speech Recognition | - 11 Multilingual Languages: Chinese, English, German, French, Italian, Thai, Korean, Japanese, Russian, Spanish, and Portuguese - 8 Chinese Dialects: Sichuanese, Shanghainese, Cantonese, Southern Min, Shaanxi dialect, Nanjing dialect, Tianjin dialect, and Beijing dialect | - 74 Multilingual Languages: Afrikaans, Arabic, Asturian, Azerbaijani, Basque, Belarusian, Bengali, Bosnian, Bulgarian, Cantonese, Catalan, Cebuano, Chinese, Croatian, Czech, Danish, Dutch, English, Esperanto, Estonian, Filipino, Finnish, French, Galician, Georgian, German, Greek, Hebrew, Hindi, Hungarian, Icelandic, Indonesian, Interlingua, Italian, Japanese, Javanese, Kannada, Kazakh, Korean, Kyrgyz, Lingala, Latvian, Lithuanian, Macedonian, Malay, Malayalam, Maltese, Maori, Marathi, Mongolian, Norwegian Bokmål, Norwegian Nynorsk, Oriya, Persian, Polish, Portuguese, Punjabi, Romanian, Russian, Serbian, Slovak, Slovenian, Spanish, Swahili, Swedish, Tajiki, Tamil, Telugu, Thai, Turkish, Ukrainian, Urdu, Uyghur, and Vietnamese - 39 Chinese Dialects: Northeastern Mandarin, Guizhou dialect, Guangdong Cantonese, Henan dialect, Hong Kong Cantonese, Shanghainese, Shaanxi dialect, Tianjin dialect, Taiwanese Mandarin, Yunnan dialect, Anhui dialect, Fujian dialect, Gansu dialect, Guangdong Mandarin, Hubei dialect, Hunan dialect, Jiangxi dialect, Shandong dialect, Shanxi dialect, Sichuanese, Guangxi dialect, Hainan dialect, Chongqing dialect, Changsha dialect, Hangzhou dialect, Hefei dialect, Yinchuan dialect, Zhengzhou dialect, Shenyang dialect, Wenzhou dialect, Wuhan dialect, Kunming dialect, Taiyuan dialect, Nanchang dialect, Jinan dialect, Lanzhou dialect, Nanjing dialect, Hakka, and Southern Min |
| Speech Synthesis | - 29 Multilingual Languages: Chinese, English, German, Italian, Portuguese, Spanish, Japanese, Korean, French, Russian, Thai, Indonesian, Arabic, Vietnamese, Turkish, Finnish, Polish, Hindi, Dutch, Czech, Urdu, Tagalog, Swedish, Danish, Hebrew, Icelandic, Malay, Norwegian, and Persian - 7 Chinese Dialects: Sichuanese, Beijing dialect, Tianjin dialect, Nanjing dialect, Shaanxi dialect, Cantonese, and Southern Min |
Demo#
General Audio-Visual Understanding#
With audio-visual input, Qwen3.5-Omni-Plus can follow instructions to generate accurate, fine-grained, structured, and timestamped captions for scenarios such as audio-video analysis, shot breakdown, and content moderation.
Documentary: Complex Scenes + Animals + Sound Effects Analysis - Video Studio#
Storyline#
00:00.000 – 00:02.500
The screen is black, then a deep, low-frequency whoosh swells as the camera drifts in from space toward Earth. The planet’s night-side hemisphere glitters with city lights while the sun crests over its limb, bathing the atmosphere in a brilliant blue halo. A faint orchestral pad begins to build beneath the whoosh.
00:02.500 – 00:36.800
A rapid-fire montage of wildlife and natural scenes unfolds, each lasting roughly one second, accompanied by swelling cinematic strings, brass accents, and assorted animal sound effects that punctuate every cut:
• High-altitude aerial of cloud-wreathed mountains; wind rush layered under the score.
• Lush rainforest canopy shrouded in mist; distant bird calls echo.
• Hummingbird hovers at orange blossoms; high-pitched wing buzz audible.
• Flock of seagulls wheels across a clear sky; sharp cries pierce the music.
• Underwater vortex of schooling fish; muffled aquatic whooshes.
• Surfer rides a turquoise wave; splash and surf hiss.
• Hammerhead shark cruises above sandy seabed; bubbling ambience.
• Brown pelicans glide over muddy water; soft wing beats.
• Hippopotamus surfaces, jaws agape; guttural snort.
• Brown bear wades through a river; water splashes.
• Bald eagle lands on a stump; talon scrape and caw.
• Bison herd trots across snowy grassland; heavy hoof thuds.
• Iguana flicks forked tongue; faint rustle.
• Wildebeest thunder across rolling plains; pounding hooves.
• Elephant calf splashes in a watering hole; trumpeting call.
• Pronghorn antelope sprint through desert scrub; wind rush.
• Cheetah cub pads forward; soft paw taps.
• Red fox pounces into tall grass; muted thump.
• Lioness yawns widely; resonant growl.
• Polar bear roars amid snow; icy wind.
• Tiger snarls; fierce roar reverberates.
Throughout, the orchestra rises toward a triumphant climax.
00:36.800 – 00:41.000
The view returns to Earth from orbit. White, all-caps text fades in over the globe: “LIFE IN THE ANIMAL KINGDOM.” The music resolves into a sustained chord, then gently subsides.
00:41.000 – 00:44.000
Against the rotating Earth, the single word “Royalty” appears in white serif type at left, lingering briefly before dissolving. Ambient synth tones replace the earlier orchestral swell.
00:44.000 – 00:49.000
Screen cuts to black. Large block letters spelling “LION” materialize; each glyph is filled with moving close-ups of lion fur, eyes, and muzzle. A crystalline chime rings out, followed by a deep bass note. As the letters fade, an extreme close-up of a male lion’s face fills the frame. Flies crawl near its nose while it blinks languidly. In the lower-right corner, small white text reads “Panthera leo.” Night insects chirp softly beneath a subdued musical bed.
00:49.000 – 01:04.000
Narration begins in a calm, mid-range male voice with a neutral British accent: “Lions, majestic creatures known for their regal appearance and powerful presence, have long captivated our imagination.” Visuals alternate between the resting male lion on green grass—shaking its mane—and a lioness weaving through dense foliage. Gentle strings and light percussion underscore the narration; cicadas hum in the background.
01:04.000 – 01:24.000
As the narrator explains lions’ adaptability to savannas, grasslands, woodlands, and semi-deserts, footage shows a lioness striding through tall grass at dusk beneath a pink-tinged sky, then a tight shot of another lioness panting lightly. Music grows more rhythmic; distant lion roars blend with the score.
01:24.000 – 01:40.000
While the narrator notes lions’ distribution across sub-Saharan Africa and India’s Gir Forest, the image cuts to a CGI Earth rotating to center on Africa. Dozens of glowing red dots bloom across the continent, marking populations. Orchestral strings surge, then taper.
01:40.000 – 01:54.000
Back on the ground, an extreme close-up captures a male lion’s amber eye blinking slowly. The narrator describes the species’ robust body, broad head, prominent male mane, and tawny coat. Cut to a male lion lying in dry grass, meticulously licking its forepaw; subtle licking sounds mix with soft ambient music.
01:54.000 – 02:11.000
A lioness stands half-hidden in golden savanna grass, scanning the horizon where a distant herd grazes. The narrator remarks that the fur’s coloration provides effective camouflage. Wind rustles through the grass; the score remains gentle and observational.
02:11.000 – 02:32.000
Golden-hour light bathes a male lion with a dark, full mane as he walks purposefully through mixed green and dry brush. The narrator explains that manes vary in color and size, signify maturity, and aid in attracting mates. Music introduces brighter melodic phrases; occasional bird calls are heard.
02:32.000 – 02:40.000
On a reddish dirt track flanked by sparse vegetation, a majestic male lion strides toward camera while several small birds flutter around his paws. Warm sunset hues dominate the palette; the orchestral bed maintains a steady, dignified rhythm.
02:40.000 – 02:51.000
A lioness leads a procession of at least eight playful cubs through lush grass dotted with trees. The narrator states that lions are social animals living in prides of related females and offspring. Cubs scamper, tumble, and glance curiously at the lens. Light, uplifting strings accompany the scene; faint cub mews are audible.
02:51.000 – 03:00.000
Final tableau: two adult male lions recline side by side on sandy ground amid dry shrubs under a pale sky. One gazes ahead; the other rests its chin on its paws, occasionally blinking. The narrator has finished; only soft ambient music and distant insect chirps remain. The image holds, then gently fades to silence and black.
Visible Text#
00:37.000 – 00:40.000
“LIFE IN THE ANIMAL KINGDOM”: white, clean sans-serif capitals; centered horizontally, slightly above mid-frame; superimposed over the orbital Earth; fades in and out smoothly.
00:41.000 – 00:43.000
“Royalty”: white serif word; positioned left-center over the rotating Earth; static during its brief appearance, then fades.
00:44.000 – 00:48.000
“LION”: very large bold sans-serif capitals filling most of the frame against black; each letter contains animated close-ups of lion facial features; no outline; appears via quick fade-in, holds, then dissolves.
00:52.000 – 00:56.000
“Panthera leo”: small white sans-serif text; lower-right corner of an extreme close-up of a male lion’s face; fades in and out without movement.
(No additional textual elements appear outside these intervals.)
Speakers and Transcript#
Speaker profiles:
Narrator – Adult male, neutral British English accent, warm baritone timbre, measured pacing, informative and documentary tone.
00:56.796 – 01:04.716
Speaker: Narrator
State: Calm, authoritative; medium volume over soft ambient music and insect ambience.
Content: “Lions, majestic creatures known for their regal appearance and powerful presence, have long captivated our imagination.”
01:14.316 – 01:23.916
Speaker: Narrator
State: Steady, explanatory; slight emphasis on key terms; orchestral underscore rising gently.
Content: “They are highly adaptable animals and can be found in a variety of habitats, ranging from savannas and grasslands to woodlands and semi-desert areas.”
01:31.724 – 01:38.444
Speaker: Narrator
State: Informative, neutral; music momentarily subdued to foreground speech.
Content: “They are spread across Sub-Saharan Africa, and a small population lives in the Gir Forest of India.”
01:43.404 – 01:53.804
Speaker: Narrator
State: Descriptive, slightly emphatic on physical traits; strings swell behind voice.
Content: “Lions are characterized by their distinctive appearance, including a robust body, a broad head with a prominent mane in males, and a sleek tawny coat.”
02:05.644 – 02:10.604
Speaker: Narrator
State: Matter-of-fact; softer musical bed, light wind noise underneath.
Content: “The coloration of their fur serves as effective camouflage in their natural environment.”
02:18.508 – 02:24.188
Speaker: Narrator
State: Engaged, mildly enthusiastic; brighter musical motif begins.
Content: “Male lions are easily recognized by their impressive manes, which vary in color and size.”
02:27.788 – 02:32.108
Speaker: Narrator
State: Continues seamlessly; slight crescendo in score.
Content: “The mane is a sign of maturity and plays a role in attracting mates.”
02:42.764 – 02:50.444
Speaker: Narrator
State: Concluding, warm; uplifting strings accompany visuals of cubs.
Content: “They are social animals and are often found in groups known as prides, typically consisting of related females and their offspring.”
(There are no other human speakers; all remaining audible elements are music, animal sounds, or environmental ambience.)
Additional Notes on Audio Design#
- Music: Predominantly orchestral with cinematic scope—strings, brass, and percussion—modulating in intensity to match visual pacing. It begins with a dramatic swell during the montage, recedes to ambient textures under narration, and ends with a gentle, reflective cadence.
- Sound Effects: Carefully synchronized animal calls (roars, chirps, splashes) punctuate corresponding visuals, enhancing realism without overpowering narration.
- Mixing: Narration is consistently foregrounded; music ducks subtly whenever speech occurs, ensuring clarity. Environmental sounds are balanced to add depth yet remain secondary.
Thematic and Cultural Context#
The piece functions as a concise nature-documentary vignette introducing lions as emblematic “royalty” of the animal kingdom. By juxtaposing a global montage of diverse species with focused lion imagery and authoritative narration, it situates lions within broader ecological and cultural narratives of majesty, adaptation, and social structure. The use of orbital Earth shots and scientific nomenclature (“Panthera leo”) underscores a modern, educational intent, while the sweeping score evokes awe and reverence typical of contemporary wildlife filmmaking.
Film: Multi-Character, Multi-Shot Audio-Visual Analysis with Complex Sound Effects#
Storyline#
00:00.000 – 00:04.796
A flat, dark-green screen fills the frame. Centered white capital letters present the Motion Picture Association of America’s standard preview-approval notice. Two smaller white website addresses sit along the lower edge. No music is heard yet; the soundtrack is silent, giving the text full attention.
00:04.796 – 00:06.465
The green card cuts to black. A single, deep orchestral hit with metallic overtones blooms, establishing a tense, cinematic atmosphere.
00:06.465 – 00:10.219
Nighttime aerial footage of a sprawling metropolis glides past. Skyscrapers glitter with gold, blue, and red lights; the camera slowly dollies toward one illuminated tower. A gravelly male voice, close-miked and intimate, murmurs, “Come in close.” The orchestral bed swells beneath his words.
00:10.219 – 00:17.768
The scene snaps to the interior of a packed theatre. From a high angle, four performers—three men and one woman—stand on a glossy black circular stage ringed by white neon. A spotlight picks out a man in a dark suit and fedora who tips his hat toward the crowd. The camera cuts to the audience: an elderly Black man in a fedora watches intently. Back on stage, the female performer in a short black dress stands inside a glowing yellow rectangular frame while the fedora-wearing man gestures theatrically. The narrator continues, “Because the more you think you see… the easier it’ll be to fool you.” A sharp percussive sting punctuates the last phrase. A close-up shows a young man with tousled hair flipping a playing card; the Ace of Hearts materialises.
00:17.768 – 00:21.188
A blue lens flare sweeps across black, revealing the silver Summit Entertainment logo with its stylised mountain peak. The orchestral score surges. The view then cuts to a sweeping night shot of the Las Vegas Strip, dominated by the gold-lit Paris Las Vegas Eiffel Tower and neon signs for “BALLY’S,” “MIRAGE,” and “THE LINQ.”
00:21.188 – 00:30.113
Inside the theatre again, the four magicians—now in coordinated dark suits—stride onto the stage. The audience roars. A blue tarp is whipped away to unveil a transparent, steel-framed teleportation booth. A digital clock on the booth’s side reads “0:00.” The lead magician in a pale suit announces, “Ladies and gentlemen, for our final trick, we are going to rob a bank. On the count of three, you will be teleported through space and time to your bank in Paris.” The crowd gasps. He counts, “One, two, three!” A bassy whoosh and crackling energy sound accompany the booth’s blue flash.
00:30.113 – 00:37.955
Cut to Paris: the façade of the opulent “CRÉDIT RÉPUBLICAIN” bank at night. Inside its vault, the four magicians—now in formal evening wear—stand before a massive circular door. Back in the theatre, the female magician addresses the audience: “Everyone in this room was a victim of hard times. Some of you lost your homes, your cars. And so tonight, we’re gonna return some of that money back to you.” A torrent of euro banknotes erupts from the stage, fluttering over cheering spectators who reach up to catch the cash.
00:37.955 – 00:46.255
The magicians bow amid the falling money. The lead man proclaims, “Thank you, everyone. We are the Four Horsemen. Good night!” The audience erupts in applause. The scene shifts to a marble-floored bank interior where stern men in suits, led by an older white-haired gentleman, descend a grand staircase. He declares, “Your bank was the distraction while they set up the real trick. I was a $140 million distraction.” His voice drips with smug satisfaction.
00:46.255 – 00:55.514
A dim bar: the older Black man in a fedora confers with the white-haired banker, exchanging knowing glances. In a bright, sterile vault corridor, a technician in a white jumpsuit wheels carts of cash. The fedora-wearing elder muses, “Who doesn’t love a good magic trick?” A metallic crash and a shout of “FBI!” cut to a modern office where an agent yells, “Hands where I can see ’em!”
00:55.514 – 01:03.397
On the Las Vegas Strip, a suited man with a phone asks incredulously, “Did you say magicians robbed a bank?” A split-screen montage shows each Horseman in separate interrogation rooms, coolly toying with cards or handcuffs. One smirks, “You have what we in the business like to call ‘nothing up your sleeve.’” The camera lingers on his confident grin.
01:03.397 – 01:12.614
The interrogation intensifies. The same magician leans forward, voice low but taunting: “Because if you did, it means that you and the FBI and your friends at Interpol actually believe in magic.” A sudden slam of his cuffed hands on the table startles the interrogator. He concludes, “First rule of magic: always be the smartest guy in the room.” A quick montage flashes: a fedora tips, the Horsemen bow on stage, and the older Black man whispers, “Wanna know how they did it? Say the magic word.”
01:12.614 – 01:24.001
A female agent in a car remarks, “A year ago, these guys were a bunch of street magicians.” Cut to the Horsemen performing atop a skyscraper against a glittering cityscape. She continues, “Now they’re pulling off amazing robberies and not keeping a single cent for themselves.” The older Black man, now in a tuxedo, intones, “You do realize this is a game played out on a global scale.”
01:24.001 – 01:34.469
Scenes intercut rapidly: a white-jumpsuited trio approaches a vault; an armored truck in a parking garage explodes, spilling money; the Horsemen study a holographic blueprint of a vault; the female agent warns, “We are dealing with something far bigger than us.” The white-haired banker growls, “Expose them now and destroy them.”
01:34.469 – 01:45.605
Action escalates: a sleek private jet soars above clouds; a red sports car rockets across the Eiffel Tower’s iron lattice; a man in a dark room brandishes a card marked “THE TOWER / LA MAISON DIEU.” The fedora-wearing elder states, “Vegas was just a start. This trick was designed a long time ago.”
01:45.605 – 02:00.203
A woman with reddish-brown hair pleads, “We’re all here for the same reason.” The elder Black man counters grimly, “We cannot quit now.” A suited gunman levels a pistol in a sparse room. On stage, one Horseman is yanked upward into a blinding spotlight, vanishing. The orchestral score reaches a thunderous peak.
02:00.203 – 02:11.006
The elder Black man’s voice overlays frenetic images: “Whatever is about to follow, whatever this grand trick is… it’s really going to amaze.” A red car bursts through the roof of a graffiti-covered building, showering the night sky with cash. The audience, including the fedora-wearing elder and a blonde woman, stare upward, mouths agape.
02:11.006 – 02:17.554
The narrator delivers the final caution: “Look closely, because the closer you think you are, the less you’ll actually see.” The screen cuts to black, then a brilliant blue lens flare reveals the metallic title “NOW YOU SEE ME,” its letters gleaming with chrome reflections.
02:17.554 – 02:24.603
Against a dark backdrop, bold white text announces “MAY 31,” followed by the Facebook logo and “NowYouSeeMeMovie,” the hashtag “#NowYouSeeMe,” and a small copyright line. The music resolves with a last resonant chord, then silence as the image fades to black.
Visible Text#
00:00.000 – 00:04.796
“THE FOLLOWING PREVIEW HAS BEEN APPROVED FOR” – white uppercase sans-serif, centered on dark-green background
“APPROPRIATE AUDIENCES” – larger, bold white uppercase, centered
“BY THE MOTION PICTURE ASSOCIATION OF AMERICA, INC.” – white uppercase, centered
“www.filmratings.com” – small white lowercase, bottom left
“www.mpaa.org” – small white lowercase, bottom right
00:17.768 – 00:19.500
“SUMMIT ENTERTAINMENT” – silver uppercase serif beneath stylised mountain logo, centre screen
“A LIONSGATE COMPANY” – smaller silver uppercase, centred below main logo
00:19.500 – 00:21.188
“BALLY’S” – large red neon letters on hotel façade, upper left of frame
“MIRAGE” – white neon letters on adjacent building, mid-left
“THE LINQ” – white neon letters on right-side building
00:21.188 – 00:30.113
“0:00” – red seven-segment digits on small black display affixed to teleportation booth, stage right
00:28.000 – 00:30.000
“CRÉDIT RÉPUBLICAIN” – gold serif capitals on stone bank façade, Paris night scene
01:40.000 – 01:41.500
“THE TOWER” – black uppercase at top of tarot-style card
“LA MAISON DIEU” – black uppercase at bottom of same card
02:17.554 – 02:19.000
“NOW YOU SEE ME” – large metallic silver 3-D letters with blue lens-flare glow, centred on black
02:20.000 – 02:22.000
“MAY 31” – large white uppercase, centred
Facebook “f” logo followed by “NowYouSeeMeMovie” – white, centred below date
“#NowYouSeeMe” – white, centred below social line
“© 2013 SUMMIT ENTERTAINMENT, LLC. ALL RIGHTS RESERVED.” – very small white uppercase, bottom centre
Lionsgate stylised “L” logo – small white, bottom right
Speakers and Transcript#
Speaker profiles:
Narrator – older male, deep gravelly American voice, measured, ominous tone
Lead Magician – mid-30s male, clear mid-range American accent, showman confidence, energetic delivery
Female Magician – late-20s female, bright American accent, persuasive, enthusiastic tone
Older Banker – late-60s male, refined American accent, authoritative, smug
Fedora Elder – late-60s Black male, resonant baritone, calm, philosophical
Interrogator – 40s male, firm American accent, forceful, impatient
Street-Magician Interrogated – early-30s male, relaxed American accent, sardonic, playful
Female Agent – 30s female, steady American accent, analytical, concerned
00:08.364 – 00:09.004
Speaker: Narrator
State: low volume, intimate, ominous
Content: “Come in close.”
00:10.364 – 00:17.724
Speaker: Narrator
State: slow, cautionary, gravelly
Content: “Because the more you think you see, the easier it’ll be to fool you.”
00:19.644 – 00:23.004
Speaker: Lead Magician
State: projected, theatrical excitement
Content: “Ladies and gentlemen, for our final trick, we are going to rob a bank.”
00:23.884 – 00:29.484
Speaker: Lead Magician
State: ringing announcement, rising cadence
Content: “On the count of three, you will be teleported through space and time to your bank in Paris.”
00:29.724 – 00:31.244
Speaker: Lead Magician
State: loud, rhythmic countdown
Content: “One, two, three.”
00:31.244 – 00:36.444
Speaker: Female Magician
State: earnest, compassionate
Content: “Everyone in this room was a victim of hard times.”
00:36.604 – 00:40.764
Speaker: Female Magician
State: rallying, hopeful
Content: “Some of you lost your homes, your cars, and so tonight, we’re gonna return some of that money back to you.”
00:44.044 – 00:44.684
Speaker: Lead Magician
State: grateful, upbeat
Content: “Thank you, everyone.”
00:44.844 – 00:46.284
Speaker: Lead Magician
State: triumphant proclamation
Content: “We are the Four Horsemen.”
00:46.284 – 00:47.004
Speaker: Lead Magician
State: cheerful sign-off
Content: “Good night.”
00:48.780 – 00:52.860
Speaker: Older Banker
State: controlled, explanatory
Content: “Your bank was the distraction while they set up the real trick.”
00:53.100 – 00:57.260
Speaker: Older Banker
State: boastful, self-satisfied
Content: “I was a hundred and forty million dollar distraction.”
00:57.260 – 01:00.140
Speaker: Fedora Elder
State: amused, reflective
Content: “Who doesn’t love a good magic trick?”
01:01.100 – 01:02.540
Speaker: Interrogator
State: loud command, tense
Content: “FBI! Hands where I can see ’em.”
01:02.940 – 01:04.140
Speaker: Street-Magician Interrogated
State: sarcastic disbelief
Content: “I don’t think I heard you correctly.”
01:04.220 – 01:05.900
Speaker: Street-Magician Interrogated
State: incredulous, taunting
Content: “Did you say magicians robbed a bank?”
01:06.060 – 01:07.260
Speaker: Street-Magician Interrogated
State: smug, challenging
Content: “You are going to be played.”
01:07.260 – 01:10.540
Speaker: Street-Magician Interrogated
State: lecturing, playful
Content: “You have what we in the business like to call nothing up your sleeve.”
01:10.700 – 01:15.340
Speaker: Street-Magician Interrogated
State: mocking, confident
Content: “Because if you did, it means that you and the FBI and your friends at Interpol actually believe in magic.”
01:18.380 – 01:19.660
Speaker: Street-Magician Interrogated
State: didactic, crisp
Content: “First rule of magic, always be the smartest guy in the room.”
01:23.660 – 01:24.540
Speaker: Fedora Elder
State: teasing, conspiratorial
Content: “Wanna know how they did it?”
01:24.780 – 01:25.740
Speaker: Fedora Elder
State: inviting, playful
Content: “Say the magic word.”
01:26.700 – 01:28.940
Speaker: Female Agent
State: analytical, matter-of-fact
Content: “A year ago, these guys were a bunch of street magicians.”
01:31.180 – 01:34.860
Speaker: Female Agent
State: impressed, wary
Content: “Now they’re pulling off amazing robberies and not keeping a single cent for themselves.”
01:35.980 – 01:40.300
Speaker: Fedora Elder
State: grave, explanatory
Content: “You do realize this is a game played out on a global scale.”
01:40.780 – 01:41.900
Speaker: Fedora Elder
State: ominous, foreboding
Content: “Vegas was just a start.”
01:42.460 – 01:45.260
Speaker: Fedora Elder
State: reflective, portentous
Content: “This trick was designed a long time ago.”
01:46.220 – 01:48.460
Speaker: Female Agent
State: concerned, urgent
Content: “We are dealing with something far bigger than us.”
01:49.100 – 01:50.540
Speaker: Red-haired Woman
State: resolute, earnest
Content: “We’re all here for the same reason.”
01:50.620 – 01:51.980
Speaker: Fedora Elder
State: determined, forceful
Content: “We cannot quit now.”
01:53.660 – 01:56.060
Speaker: Older Banker
State: cold, commanding
Content: “Expose them now and destroy them.”
02:01.036 – 02:09.196
Speaker: Fedora Elder
State: anticipatory, grandiose
Content: “Whatever is about to follow, whatever this grand trick is, is really going to amaze.”
02:11.116 – 02:17.356
Speaker: Narrator
State: slow, cautionary, resonant
Content: “Look closely, because the closer you think you are, the less you’ll actually see.”
Additional Notes on Cinematic Style and Themes#
- Visual Aesthetics: The trailer juxtaposes sleek, high-contrast stage performances bathed in blue and gold lighting with gritty urban nightscapes and sterile government interiors, reinforcing the duality of spectacle versus clandestine operations.
- Motifs: Recurrent images of playing cards, vault doors, falling money, and iconic landmarks (Eiffel Tower, Las Vegas Strip) underscore themes of illusion, wealth redistribution, and global stakes.
- Sound Design: A hybrid orchestral-electronic score drives momentum, punctuated by metallic impacts, whooshes, and crowd roars that synchronize tightly with visual reveals, enhancing the sense of grand illusion.
- Narrative Arc: The trailer establishes the Four Horsemen as charismatic magician-thieves who expose corruption by stealing from the wealthy and gifting money to the public, while law enforcement and powerful financiers scramble to unmask them, setting up a cat-and-mouse game on an international scale.
Game: Determine Whether Violent Scenes Are Present Based on Audio-Visual Content#
Demo
User
Qwen3.5-Omni-Plus
This video is a compilation of gameplay from Mortal Kombat 11 Ultimate, focusing on the game’s special finishing moves called Fatalities. It begins by showing the main menu, where the player selects the Fatalities mode. They then choose a character from the roster, such as Shang Tsung, Shao Kahn, or The Joker, and enter a one-on-one fight. After winning the match, the player performs a unique, graphic finishing move on their defeated opponent. Each Fatality is a cinematic sequence of extreme violence, showing characters being torn apart, decapitated, frozen and shattered, or disintegrated. The video cycles through several different characters, each demonstrating their own distinct and brutal method of killing their opponent. The presentation is stylized with dark, dramatic lighting and slow-motion effects to highlight the gore. The video concludes after showcasing a series of these Fatalities.
Section 1: Compliance Alert (Summary)#
| Time Range | Category | Risk Level | Justification |
|---|---|---|---|
| 01:25 - 01:49 | Graphic Violence | High | A character is impaled, set on fire, and then ripped in half vertically, showing internal organs and a skeleton. |
| 02:26 - 02:47 | Graphic Violence | High | A character is impaled through the chest, lifted into the air, and then ripped apart at the waist, causing a massive spray of blood. |
| 03:15 - 03:38 | Graphic Violence | High | A character is frozen solid with ice powers and then shattered into many pieces. |
| 04:13 - 04:37 | Graphic Violence | High | A character’s soul is ripped out of their body and then violently torn apart by a spiritual entity. |
| 05:03 - 05:29 | Graphic Violence | High | A character is blown up by an explosive cake and then decapitated by a spinning blade. |
| 05:56 - 06:24 | Graphic Violence | High | A character is punched so hard their head explodes, and their body is then split in half. |
| 06:53 - 07:19 | Graphic Violence | High | A character is launched into the air and shredded by helicopter rotor blades, resulting in dismemberment. |
Section 2: Summary of Safety Findings#
This video is not suitable for minors. The entire video consists of gameplay from Mortal Kombat 11 Ultimate, a game rated for mature audiences due to its extreme content. The video showcases multiple Fatalities, which are graphic and sadistic finishing moves. These scenes depict realistic and brutal violence, including dismemberment, decapitation, evisceration, and characters being set on fire or shattered. The high level of blood and gore, combined with the detailed and cinematic nature of the violence, makes the content inappropriate for anyone under the age of 18.
Short Video: Daily Life Short Video Analysis#
Storyline#
00:00.000 – 00:04.300
The clip opens with a hand-held, wide-angle selfie shot. A Black man in his twenties, sporting short curly hair and a bright magenta-yellow-red striped long-sleeve top, fringed magenta skirt, matching leg warmers, and large fluffy magenta ankle attachments, fills most of the frame. Behind him stretches a sun-bleached, sandy clearing under a blue sky mottled with white clouds. Dozens of onlookers—men, women, and children in casual clothes—form a loose semicircle, many holding up smartphones. Farther back, several drummers stand beside tall, cylindrical drums. The performer shouts excitedly toward the lens, “I’m here in Ivory Coast and I’m about to do the hardest dance in the world. Let’s go!” His voice is loud, breathy, and exuberant. As he finishes, a dense wall of polyrhythmic hand-drumming erupts, accompanied by scattered cheers and whoops from the crowd.
00:04.300 – 00:15.000
The camera swings outward into a medium-wide view that now frames two principal dancers. On the left is the striped-shirt host; on the right stands a masked dancer whose face is painted solid green beneath an ornate headdress topped with red-green-white feathers. This second figure wears a flowing cape and skirt in vertical bands of green, white, and orange, plus striped leg wraps and shaggy brown ankle rattles that jingle with every step. Both men launch into vigorous footwork—rapid stamping, hopping, and spinning—sending puffs of dust into the air. The drum ensemble behind them pounds out layered rhythms while the audience claps and yells encouragement. Around 00:09 a male spectator near the camera calls out, “Why?” in playful disbelief. At roughly 00:12 the masked dancer drops into a low squat, nearly touching the ground, then springs back up, prompting louder applause.
00:15.000 – 00:18.000
The host abruptly pivots the phone back to himself for another close-up. Breathing hard, sweat glistening on his forehead, he gasps, “It is very hard. It’s even hard for me.” His grin mixes exhaustion with exhilaration. Drumbeats continue underneath, slightly muffled by his proximity to the microphone.
00:18.000 – 00:26.000
The viewpoint widens again. The two lead dancers re-engage, circling each other. The masked performer brandishes a short wooden stick, slashing it through the air in time with the drums, while the host mirrors some of the steps but struggles to keep pace, occasionally stumbling and laughing at himself. Dust swirls around their feet; sunlight flashes off metallic ornaments on the costume. The crowd’s energy rises—shouts, whistles, and rhythmic clapping blend with the relentless percussion.
00:26.000 – 00:31.000
In a climactic flourish, the masked dancer spins rapidly, cape flaring like a multicolored wheel. He closes the distance and enfolds the host in a brief celebratory hug. The host throws his head back, mouth open in a joyous shout, eyes squeezed shut. Camera shake intensifies as both men laugh and sway together amid thunderous drumming and roaring approval from spectators.
00:31.000 – 00:32.000
Still locked in the embrace, the host leans toward the lens and bellows, “W’s in the chat! Like and sub!” His tone is triumphant and teasing, aimed at an online audience. Immediately after the final word, the image freezes for a split second and the video cuts to black, ending the clip.
Visible Text#
No visible text, captions, graphics, or on-screen typography appear at any point in the video.
Speakers and Transcript#
Speaker profiles:
Host – Male, mid-20s, Black, African-American English accent; voice loud, energetic, occasionally breathless; primary on-camera performer in striped outfit.
Spectator – Unseen male voice from crowd; casual tone, brief interjection.
00:00.000 – 00:04.240
Speaker: Host
State: Shouting, highly enthusiastic, projecting over ambient noise
Content: “I’m here in Ivory Coast and I’m about to do the hardest dance in the world. Let’s go!”
00:09.000 – 00:10.000
Speaker: Spectator
State: Playful exclamation, raised voice
Content: “Why?”
00:15.200 – 00:17.600
Speaker: Host
State: Breathless, strained yet amused
Content: “It is very hard. It’s even hard for me.”
00:31.000 – 00:32.000
Speaker: Host
State: Triumphant shout, promotional tone
Content: “W’s in the chat! Like and sub!”
Additional Notes on Audio-Visual Style#
• Music: Continuous live West African drumming featuring multiple djembe-style drums producing interlocking high, mid, and low tones; tempo fast and steady, no melodic instruments detected.
• Ambient sound: Frequent crowd cheers, claps, whistles; occasional individual shouts; no discernible wind or traffic noise, indicating an outdoor but relatively sheltered setting.
• Cinematography: Entirely handheld smartphone footage; frequent rapid pans between selfie close-ups and wider shots; slight fisheye distortion suggests a wide-angle lens attachment.
• Lighting: Bright natural daylight with strong overhead sun casting short shadows; colors appear saturated, enhancing the vividness of costumes and surroundings.
• Cultural context: Costumes, masks, and drumming strongly evoke traditional Ivorian ceremonial dance forms such as those associated with the Goli or Zaouli traditions, though the presence of social-media slang (“W’s in the chat,” “Like and sub”) indicates a contemporary, internet-savvy performance intended for online sharing.
Recommended Usage#
| Configuration | Maximum Pixels | Recommended Video Duration | Recommended Prompt | Scenario |
|---|---|---|---|---|
| Low Cost | 230,400 Pixels | Under 60 Minutes | A custom prompt within 50 words, depending on the needs. | - Moderation |
| Brief (Low Accuracy Requirement) | 921,600–2,073,600 Pixels | Under 60 Minutes | A custom prompt within 50 words, depending on the needs. | - Long-Video Segmentation - Rough Content Extraction |
| Balanced (General Detailed Audio-Visual Description) | 921,600–2,073,600 Pixels | Under 4 Minutes | Fixed Structured-Description Prompt | - Fine-Grained Audio-Visual Tagging. |
| Best (The Most Detailed Description) | 2,073,600 Pixels | Under 2 Minutes | Fixed Structured-Description Prompt | - Multi-Scene, - Multi-Speaker - Complex Scenarios |
| Note: If you want structured, fine-grained descriptions for longer video with audio as well, segmenting is recommended. |
Fixed Structured-Description Prompt#
Provide a detailed description of the video.

It should explicitly include three sections:

1. A structured chronological storyline of **every noticeable audio and visual details**
2. A structured list of all visible text. For each text element, include start timestamp, end timestamp, the exact text content, the appearance characteristics. If no text appears, explicitly state so.
3. A structured speech-to-text transcription, include speaker(Corresponding to the character or voice‑over in Section 1, including their accent and tone), exact spoken content, start timestamp, end timestamp, and speaking state (prosody, emotion, and style). If no speech appears, explicitly state so.

Aside from these three required sections, you are free to organize any additional content in any way you find helpful. This additional content can include global information about the entire video or localized information about specific moments. You may choose the topic of this extra content freely.

Output Format:

```
## Storyline

<xx:xx.xxx> - <xx:xx.xxx>
<an unstructured long paragraph in natural language describing what happened during this period, blending both audio and video details.>

<xx:xx.xxx> - <xx:xx.xxx>
<an unstructured long paragraph in natural language describing what happened during this period, blending both audio and video details.>

<xx:xx.xxx> - <xx:xx.xxx>
<an unstructured long paragraph in natural language describing what happened during this period, blending both audio and video details.>

...

## Visible Text

<xx:xx.xxx> - <xx:xx.xxx>
“<element>”: <appearance>
“<element>”: <appearance>

<xx:xx.xxx> - <xx:xx.xxx>
“<element>”: <appearance>
“<element>”: <appearance>
“<element>”: <appearance>

<xx:xx.xxx> - <xx:xx.xxx>
“<element>”: <appearance>

...

## Speakers and Transcript

Speaker profiles:
<speaker> - <profile>
<speaker> - <profile>
<speaker> - <profile>
...

<xx:xx.xxx> - <xx:xx.xxx>
Speaker: <speaker>
State: <description>
Content: “<content>”

<xx:xx.xxx> - <xx:xx.xxx>
Speaker: <speaker>
State: <description>
Content: “<content>”

<xx:xx.xxx> - <xx:xx.xxx>
Speaker: <speaker>
State: <description>
Content: “<content>”

...

## <another section>

<paragraphs>

## <another section>

<paragraphs>

...
```
Audio-Visual Vibe Coding#
Snake Game#
Demo
User
Qwen3.5-Omni-Plus
User
Qwen3.5-Omni-Plus
Demo2Code#
Demo
User
Qwen3.5-Omni-Plus
User
Qwen3.5-Omni-Plus
Audio-Visual Conversation#
Travel Planning – Weather/Hotel Lookup, WebSearch/Tool#
Demo
Voice Clone#
Demo
Multi-Turn Dialogue and Intelligent Interruption#
Demo
Voice Style, Emotion, and Volume Control in Conversation#
Demo
General Audio Understanding#
Multi-Language Song Understanding#
Demo
User
Qwen3.5-Omni-Plus
[00:00.000 – 00:05.440]
Instrumental introduction; no lyrics present. The orchestra establishes a solemn, anticipatory atmosphere with sustained strings and distant percussion. No vocals are heard yet, so the mood is tense and expectant.
[00:05.440 – 00:16.320]
Solo male tenor (clear, bright, slightly nasal timbre) sings in English with a firm, declamatory delivery. Emotional tone is urgent and rallying, evoking defiance and hope. Style is solo, front-and-center over restrained orchestral support.
Lyrics: “Do you hear the people sing? Singing the song of angry men? It is the music of a people who will not be slaves again.”
[00:16.320 – 00:28.080]
Same solo tenor continues in English, voice gaining intensity and forward projection. Emotional tone shifts to passionate resolve. Solo performance remains dominant, with strings swelling beneath.
Lyrics: “When the beating of your heart echoes the beating of the drum, there is a life about to start when tomorrow comes.”
[00:28.080 – 00:33.600]
Baritone male voice enters in French, resonant and weighty, projecting solidarity. Emotional tone is dignified and communal. Solo delivery, supported by low brass undercurrents.
Lyrics: “À la volonté du peuple et à la santé du progrès.”
[00:33.600 – 00:39.280]
Tenor male voice in German, ringing and forceful, sustaining long vowels for emphasis. Tone is fervent and insistent. Solo style, with orchestral punctuation.
Lyrics: “Das ist die Symphonie von Menschen, die nicht länger Sklaven sind.”
[00:39.280 – 00:50.800]
Baritone male voice in Japanese, warm and measured, delivering lines with rhythmic clarity. Emotional tone is determined yet reflective. Solo performance, strings providing gentle momentum.
Lyrics: “新たに熱い命が始まる。明日が来た時、そうさ、明日。”
[00:50.800 – 00:56.720]
Tenor male voice in Hungarian, agile and impassioned, slight vibrato adding urgency. Tone is exhortative. Solo style, light woodwind coloration behind.
Lyrics: “El sem ellik, hogyha kell, kiállsz e értünk, harcunkért.”
[00:56.720 – 01:07.360]
Baritone male voice in Swedish, rich and rounded, projecting calm strength. Emotional tone is resolute and inclusive. Solo delivery, brass subtly reinforcing cadence.
Lyrics: “Från vår barrikad kan man se ett framtidens land. Så kom med oss, låt oss kämpa om du kan.”
[01:07.360 – 01:12.880]
Tenor male voice in Polish, bright and piercing, conveying indignation. Tone is sharp and motivating. Solo performance, percussion accents underline key words.
Lyrics: “Pytasz, słuchasz, śpiewasz lud, co nie chce żyć w niewoli znów.”
[01:12.880 – 01:18.800]
Baritone male voice in Dutch, sonorous and steady, imparting gravitas. Emotional tone is earnest and collective. Solo style, lower strings provide foundation.
Lyrics: “Al die mensen die verdommen om nog langer slaaf te zijn.”
[01:18.800 – 01:29.920]
Return to English solo tenor, now fuller and more expansive, voice soaring above thicker orchestration. Tone is triumphant anticipation. Solo performance leading toward ensemble build-up.
Lyrics: “When the beating of your heart echoes the beating of the drums, there is a life about to start when tomorrow comes.”
[01:29.920 – 01:35.440]
Tenor male voice in German, powerful and ringing, emphasizing finality. Emotional tone is climactic and commanding. Solo delivery, cymbal crashes accent phrases.
Lyrics: “Wenn du kämpfst mit ganzer Kraft, hat bald ein Ende alle Not.”
[01:35.440 – 01:40.480]
English solo tenor resumes, voice urgent and questioning, slight edge of challenge. Tone is provocative, urging action. Solo style, dynamic rise in accompaniment.
Lyrics: “Some will fall and some will live. Will you stand up and take your chance?”
[01:40.480 – 01:45.840]
English solo tenor continues, voice imbued with patriotic fervor, broad phrasing. Emotional tone is inspirational. Solo performance, brass fanfare hints at coming chorus.
Lyrics: “The blood of the martyrs will water the meadows of France.”
[01:45.840 – 01:51.440]
Tenor male voice in Danish, clear and lyrical, gentle vibrato. Tone is hopeful and forward-looking. Solo delivery, harp arpeggios shimmer beneath.
Lyrics: “Kan du høre folkesangen? Det er håp om morgendagen.”
[01:51.440 – 01:57.120]
Tenor male voice in Czech, robust and declamatory, strong consonants. Emotional tone is defiant. Solo style, timpani rolls add tension.
Lyrics: “Nechť ani šíp nespalí víru, kdo zpívá píseň svobody.”
[01:57.120 – 02:02.560]
Tenor male voice in Finnish, resonant and solemn, measured pacing. Tone is steadfast and noble. Solo performance, low strings sustain harmonic bed.
Lyrics: “Jotka kuuntelevat uuslaulun sävelten jälkeen.”
[02:02.560 – 02:08.080]
Tenor male voice in Danish, lyrical and uplifting, smooth legato. Emotional tone is optimistic. Solo delivery, flutes echo melodic fragments.
Lyrics: “Der skal de leve og leve i den nye dag.”
[02:08.080 – 02:13.680]
English solo tenor returns, voice expansive and inviting, slight crescendo toward phrase end. Tone is inclusive and stirring. Solo style, full orchestra begins to swell.
Lyrics: “Will you join in our crusade? Who will be strong and stand with me?”
[02:13.680 – 02:19.280]
Tenor male voice in Danish/Norwegian, bright and encouraging, forward placement. Emotional tone is motivational. Solo performance, snare drum march rhythm emerges.
Lyrics: “Kom dig en fremtid, vær dig selv og fri, som aldrig vil jeg mere.”
[02:19.280 – 02:30.640]
English solo tenor, voice at peak intensity, sustained high notes, rich vibrato. Tone is exultant and prophetic. Solo lead, orchestra builds to forte.
Lyrics: “Do you hear the people sing? Say, do you hear the distant drums? It is the future that we bring when tomorrow comes.”
[02:30.640 – 02:43.520]
Transition from solo to mixed choir; multiple male and female voices blend in homophonic texture. Language shifts among previously heard tongues, creating a polyglot tapestry. Emotional tone is ecstatic unity. Chorus style, full orchestral tutti, cymbals and brass fanfares.
Lyrics: “One day more!”
[02:43.520 – 02:49.120]
Choir sustains “One day more!” in layered harmonies, dynamics climbing. Tone is jubilant and anthemic. Chorus performance, tempo accelerates slightly.
Lyrics: “One day more!”
[02:49.120 – 02:54.640]
Choir repeats refrain with heightened volume; soprano line soars above. Emotional tone is triumphant. Chorus style, percussion drives momentum.
Lyrics: “One day more!”
[02:54.640 – 03:00.240]
Choir continues, voices interweaving in counterpoint, building to climax. Tone is euphoric resolve. Full chorus, brass and timpani reinforce downbeats.
Lyrics: “One day more!”
[03:00.240 – 03:05.760]
Choir reaches fortissimo peak, holding final chord with radiant resonance. Emotional tone is victorious culmination. Chorus performance, cymbal crash and organ pedal point underline grandeur.
Lyrics: “One day more!”
[03:05.760 – 03:41.027]
Extended choral coda; repeated iterations of “One day more!” in overlapping entries, gradually decrescendoing into a luminous final chord. Emotional tone transitions from ecstatic to serene resolution. Full chorus with orchestra tapering to silence, leaving a lingering sense of hope.
Lyrics: “One day more! One day more! One day more! One day more!”
BBC Audio Understanding#
Storyline#
00:00.000 – 00:06.800
Inside a reverberant television-studio control room, two young production assistants—one woman, one man—argue in agitated, fast voices about having waited “over twenty minutes” to go on-air. The woman’s tone is high-pitched and panicked; the man’s is clipped and frustrated. A low, steady HVAC hum underlies the exchange. A brief paper rustle and a single cough from somewhere off-mic punctuate the tension.
00:06.800 – 00:11.500
The argument escalates: the man calls the situation “incredibly unprofessional,” the woman fires back “So is your mom!” and immediately apologizes, admitting she is “very stressed out.” Their voices overlap slightly. A sharp, comic “whoosh” stinger and a burst of canned laughter announce that the feed is about to go live.
00:11.500 – 00:18.600
Still backstage, the woman snaps, “Oh, okay, they’re coming back to us. Get through the whole broadcast in five minutes. Speed it up!” The man protests, “How’s that even possible?” She groans, “I’m gonna throw up,” and, after a metallic clank, he mutters, “No, there’s no time.” A triumphant orchestral news-theme sting swells, blending with audience laughter as the program officially begins.
00:18.600 – 00:25.800
The music segues into the main theme. A resonant male announcer booms, “Live, this is Channel 8 News at Ten with John Harper and Sandra Burbank.” The theme fades. In the studio, Anchor John Harper greets viewers in a polished baritone: “Good evening and welcome to World News at Ten. I’m John Harper.” Anchor Sandra Burbank follows crisply: “And I’m Sandra Burbank.”
00:25.800 – 00:36.300
Sandra introduces the top story about “four and eight in the Middle East,” then tosses to correspondent Philip Castle “live on the scene.” Philip, speaking through a slightly compressed remote line, tersely confirms the tension. Sandra presses, “Any chance for a quick resolution?” Philip answers “No.” Sandra instantly thanks him. Audience laughter erupts, then subsides.
00:36.300 – 00:45.000
John pivots to a tease about “clean energy,” promising more later, and throws to weather. A perky male weathercaster flatly states, “Clouds.” John immediately yanks the broadcast back: “We now go back to our story on clean energy.” Laughter and a quick stinger accent the gag.
00:45.000 – 00:59.900
John introduces “local expert Dr. Simon Gunther.” After a brief “My pleasure,” John rapid-fires questions about solar power and fossil-fuel dependence. The doctor’s hesitant “Well… yeah, actually…” is cut off mid-sentence. John snaps, “Thank you, doctor,” triggering another wave of audience laughter.
00:59.900 – 01:06.100
Sandra delivers a morbid one-liner: “And now for a story about a non-profit animal shelter that caught fire. Everything died. Hmm.” The studio audience roars; a short news sting follows.
01:06.100 – 01:15.100
John introduces Diane Dubanowski’s “exhaustive story on immigration.” A calm female voice begins, “The borders between countries are—” but John cuts in with “Food for thought.” Fresh laughter and a brisk stinger.
01:15.100 – 01:25.000
Sandra presents the “weekly segment on the state of the nation” and asks political analyst Craig Jones about America’s biggest challenge. Craig starts, “Obama is—” only to be silenced by Sandra’s “Thank you, Craig.” The audience responds with its loudest laugh yet, followed by light applause.
01:25.000 – 01:39.400
A field reporter, Joseph Jensen, crackles in via satellite: “The aliens are about to make their first contact.” Sandra, unfazed, replies, “Fascinating, Joseph, thank you.” Laughter and a short stinger.
01:39.400 – 01:48.900
John hands off to “Steve with sports.” Steve, sounding bewildered, utters a single “What?” John thanks him and the audience, invites them to “stay tuned for Fallon,” and reminds them to watch the morning news at six. Sandra adds, “Have a good night, everyone.” The closing theme swells; applause and cheers fill the room.
01:48.900 – 01:54.900
The theme reaches full orchestral grandeur, then fades under enthusiastic clapping. As the music dies, the ambience shifts back to the control room’s drier acoustics.
01:54.900 – 01:59.998
The female production assistant, now calmer but still hurried, tells her colleague, “So that was too fast. You have four more minutes, so just stretch it out.” A final audience chuckle and a faint exhale close the recording.
Speakers and Transcript#
Speaker profiles:
Female PA – Young adult woman, standard American accent; high-pitched, anxious, rapid speech.
Male PA – Young adult man, standard American accent; tense, clipped delivery.
Announcer – Middle-aged man, deep “news voice,” authoritative.
John Harper – Male anchor, mid-40s, resonant baritone, polished broadcast cadence.
Sandra Burbank – Female anchor, early-40s, bright mezzo, precise diction.
Philip Castle – Male correspondent, 30s, slightly nasal, remote-line compression.
Weathercaster – Male, 30s, casual tone, very brief.
Dr. Simon Gunther – Male, 50s, hesitant academic tone.
Diane Dubanowski – Female reporter, 30s, measured, professional.
Craig Jones – Male analyst, 40s, confident, political pundit style.
Joseph Jensen – Male field reporter, 30s, excited, satellite line.
Steve – Male sports anchor, 30s, puzzled tone.
Audience – Mixed-gender studio crowd; laughter, applause, cheers.
00:00.160 – 00:00.960
Speaker: Female PA
State: strained, urgent, rising pitch
Content: “How much longer?”
00:00.960 – 00:02.880
Speaker: Male PA
State: frustrated, quick tempo
Content: “We’ve been waiting to go on for over twenty minutes.”
00:03.120 – 00:04.800
Speaker: Female PA
State: exasperated, fast
Content: “I know, the game went into triple overtime.”
00:04.800 – 00:06.160
Speaker: Female PA
State: annoyed, clipped
Content: “They’re eating up our time slot.”
00:06.240 – 00:07.680
Speaker: Male PA
State: indignant, emphatic
Content: “Well, this is incredibly unprofessional.”
00:07.680 – 00:08.320
Speaker: Female PA
State: mocking, sharp
Content: “So is your mom.”
00:08.320 – 00:08.800
Speaker: Male PA
State: shocked, abrupt
Content: “What?”
00:08.800 – 00:10.400
Speaker: Female PA
State: flustered, apologetic
Content: “I’m sorry, I’m very stressed out.”
00:11.200 – 00:12.640
Speaker: Female PA
State: suddenly focused, brisk
Content: “Oh, okay, they’re coming back to us.”
00:12.800 – 00:14.320
Speaker: Female PA
State: commanding, hurried
Content: “Get through the whole broadcast in five minutes.”
00:14.400 – 00:14.880
Speaker: Female PA
State: urgent, loud
Content: “Speed it up.”
00:14.880 – 00:15.200
Speaker: Male PA
State: incredulous, raised voice
Content: “How is that even possible?”
00:15.200 – 00:16.800
Speaker: Female PA
State: nauseated, groaning
Content: “I’m gonna throw up.”
00:16.800 – 00:17.680
Speaker: Male PA
State: tense, clipped
Content: “No, there’s no time.”
00:18.572 – 00:22.972
Speaker: Announcer
State: booming, ceremonious
Content: “Live, this is Channel 8 News at 10 with John Harper and Sandra Burbank.”
00:23.932 – 00:25.292
Speaker: John Harper
State: warm, formal
Content: “Good evening and welcome to World News at 10.”
00:25.292 – 00:25.772
Speaker: John Harper
State: steady, confident
Content: “I’m John Harper.”
00:25.852 – 00:26.652
Speaker: Sandra Burbank
State: bright, professional
Content: “And I’m Sandra Burbank.”
00:26.652 – 00:29.292
Speaker: Sandra Burbank
State: explanatory, brisk
Content: “Our top story tonight, four and eight in the Middle East has some people up in arms.”
00:29.292 – 00:31.212
Speaker: Sandra Burbank
State: transitional, clear
Content: “We go now to our correspondent Philip Castle, who is live on the scene.”
00:31.212 – 00:34.092
Speaker: Sandra Burbank
State: inquisitive, formal
Content: “Philip, things seem to be rather tense regarding this issue.”
00:34.252 – 00:34.492
Speaker: Philip Castle
State: terse, factual
Content: “Yes.”
00:34.652 – 00:35.772
Speaker: Sandra Burbank
State: probing, quick
Content: “Any chance for a quick resolution?”
00:36.092 – 00:36.332
Speaker: Philip Castle
State: firm, abrupt
Content: “No.”
00:36.492 – 00:36.812
Speaker: Sandra Burbank
State: clipped, polite
Content: “Thank you, Philip.”
00:36.812 – 00:42.092
Speaker: John Harper
State: smooth, announcer-like
Content: “Recent developments in clean energy have some people asking questions, but more on that later in the program.”
00:42.092 – 00:44.252
Speaker: John Harper
State: upbeat, segueing
Content: “Let’s first check in with the weather.”
00:44.492 – 00:44.812
Speaker: Weathercaster
State: flat, deadpan
Content: “Clouds.”
00:45.052 – 00:46.732
Speaker: John Harper
State: brisk, redirecting
Content: “We now go back to our story on clean energy.”
00:47.532 – 00:49.212
Speaker: John Harper
State: cordial, introducing
Content: “We go now to local expert Dr. Simon Gunther.”
00:49.212 – 00:50.092
Speaker: John Harper
State: polite
Content: “Thank you for joining us, doctor.”
00:50.572 – 00:50.892
Speaker: Dr. Simon Gunther
State: courteous
Content: “My pleasure.”
00:50.892 – 00:51.692
Speaker: John Harper
State: eager, rapid
Content: “Let’s get right to it, shall we?”
00:51.692 – 00:54.332
Speaker: John Harper
State: enthusiastic, quick
Content: “Solar power can run cars, homes, even entire cities.”
00:54.332 – 00:54.412
Speaker: John Harper
State: confirming
Content: “Is that correct?”
00:54.732 – 00:56.812
Speaker: John Harper
State: pressing, fast
Content: “And I understand this technology has been around for some time?”
00:57.052 – 00:57.452
Speaker: Dr. Simon Gunther
State: tentative
Content: “Yeah, actually—”
00:57.452 – 00:58.892
Speaker: John Harper
State: challenging, rapid
Content: “So why are we still dependent on gas and oil?”
00:59.292 – 00:59.852
Speaker: John Harper
State: dismissive
Content: “Thank you, doctor.”
01:01.692 – 01:04.332
Speaker: Sandra Burbank
State: somber, matter-of-fact
Content: “And now for a story about a non-profit animal shelter that caught fire.”
01:04.332 – 01:04.972
Speaker: Sandra Burbank
State: flat, grim
Content: “Everything died.”
01:05.292 – 01:05.692
Speaker: Sandra Burbank
State: pensive hum
Content: “Hmm.”
01:06.172 – 01:12.172
Speaker: John Harper
State: formal, introducing
Content: “We now go to a special report by Diane Dubanowski, who has spent the last six months preparing an exhaustive story on immigration.”
01:12.492 – 01:14.252
Speaker: Diane Dubanowski
State: measured, serious
Content: “The borders between countries are—”
01:14.412 – 01:14.972
Speaker: John Harper
State: cutting in, wry
Content: “Food for thought.”
01:17.068 – 01:21.388
Speaker: Sandra Burbank
State: upbeat, introducing
Content: “And now for our weekly segment on the state of the nation.”
01:21.388 – 01:23.788
Speaker: Sandra Burbank
State: cordial
Content: “We have, as always, political analyst Craig Jones.”
01:24.028 – 01:24.108
Speaker: Sandra Burbank
State: inquisitive
Content: “Craig,”
01:24.108 – 01:24.748
Speaker: Sandra Burbank
State: direct
Content: “what is the biggest challenge facing America today?”
01:24.108 – 01:24.908
Speaker: Craig Jones
State: declarative, cut short
Content: “Obama is—”
01:24.908 – 01:25.228
Speaker: Sandra Burbank
State: abrupt, polite
Content: “Thank you, Craig.”
01:32.748 – 01:38.348
Speaker: Joseph Jensen
State: excited, remote-line buzz
Content: “The aliens are about to make their first contact.”
01:38.348 – 01:39.388
Speaker: Sandra Burbank
State: dry, dismissive
Content: “Fascinating, Joseph, thank you.”
01:40.268 – 01:41.708
Speaker: John Harper
State: brisk, segueing
Content: “Let’s go now to Steve with sports.”
01:42.188 – 01:42.508
Speaker: Steve
State: confused
Content: “What?”
01:42.828 – 01:44.988
Speaker: John Harper
State: cheerful, closing
Content: “Thank you, Steve, and thank you all for joining us here tonight.”
01:45.388 – 01:48.268
Speaker: John Harper
State: promotional, upbeat
Content: “Stay tuned for Fallon and be sure to check out the morning news team tomorrow morning at six.”
01:48.348 – 01:49.148
Speaker: Sandra Burbank
State: warm sign-off
Content: “Have a good night, everyone.”
01:54.988 – 01:56.108
Speaker: Female PA
State: relieved, conversational
Content: “So that was too fast.”
01:56.748 – 01:59.948
Speaker: Female PA
State: instructive, calming
Content: “You have four more minutes, so just stretch it out.”
Global Acoustic & Production Notes#
- Studio acoustics shift noticeably between the dry control-room segments and the reverberant main studio, underscoring the narrative’s backstage-versus-on-air structure.
- Non-speech elements—orchestral news themes, comic stingers, whooshes, paper rustles, and audience reactions—are tightly synchronized with dialogue to heighten comedic timing.
- The entire piece is a parody of live news broadcasts, lampooning time constraints, sensationalism, and abrupt cut-offs. Rapid pacing, overlapping lines, and sudden topic shifts create a satirical, farcical rhythm.
- Audience responses (laughter, applause, cheers) function as a rhythmic punctuation, often triggered immediately after punchlines or abrupt dismissals, reinforcing the sketch-comedy format.
- Dynamic range is moderate: dialogue sits prominently above a consistent low-level HVAC hum; musical stings and theme swell briefly to near-equal loudness before ducking under speech.
- No music beds persist beneath dialogue except during the opening and closing themes; otherwise, silence or faint room tone separates segments, allowing jokes to land cleanly.
Thematic & Cultural Context#
The audio parodies American local-news conventions: hyperbritical anchors, token experts, trivial weather updates, and sensational headlines. References to “Fallon” suggest a late-night talk-show lead-in, situating the piece within U.S. broadcast culture. The absurdity of compressing an entire newscast into minutes, coupled with cut-off interviews and darkly comic one-liners (e.g., “Everything died”), satirizes the rush for brevity and the superficiality of modern news cycles.
Lyric Subtitle Generation#
Demo
User
Qwen3.5-Omni-Plus
[00:00:20,686 –> 00:00:24,996] Clink of crystal, smoke in the air
[00:00:24,996 –> 00:00:29,506] Smiles like porcelain, nobody’s there
[00:00:29,506 –> 00:00:34,266] Tie knotted tight, shoes polished black
[00:00:34,266 –> 00:00:38,436] Laugh on cue, never look back
[00:00:38,436 –> 00:00:43,266] Champagne flutes rise like hollow toasts
[00:00:43,266 –> 00:00:47,796] To dreams we sold for designer ghosts
[00:00:47,796 –> 00:00:52,906] The band plays sweet, but I hear it wrong
[00:00:52,906 –> 00:00:56,806] A syncopated sense of gone
[00:00:56,806 –> 00:01:01,436] I’m dancing offbeat in a perfect show
[00:01:01,436 –> 00:01:06,226] Smiling wide while the silence grows
[00:01:06,226 –> 00:01:11,126] They call it charm, I call it strange
[00:01:11,126 –> 00:01:15,066] This masquerade where nothing changes
[00:01:15,066 –> 00:01:23,106] Yeah, I play along, but I don’t belong
[00:01:23,106 –> 00:01:28,966] Her perfume lingers, words like lace
[00:01:28,966 –> 00:01:33,066] But every glance hides an empty space
[00:01:33,066 –> 00:01:37,166] We quote philosophers over ice
[00:01:37,166 –> 00:01:42,086] While truth dissolves in cocktail vice
[00:01:42,086 –> 00:01:47,106] The sax hums low, but I feel it scream
[00:01:47,106 –> 00:01:51,586] A dissonant thread in this velvet dream
[00:01:51,586 –> 00:01:56,266] I’m dancing offbeat in a perfect show
[00:01:56,266 –> 00:02:01,066] Smiling wide while the silence grows
[00:02:01,066 –> 00:02:05,926] They call it charm, I call it strange
[00:02:05,926 –> 00:02:09,866] This masquerade where nothing changes
[00:02:09,866 –> 00:02:18,866] Yeah, I play along, but I don’t belong
[00:02:18,866 –> 00:02:29,986] What if I drop the glass, let it shatter on marble lights
[00:02:29,986 –> 00:02:46,666] Would they notice the crack in me, or just pour another round and sigh
[00:02:46,666 –> 00:03:00,546] Lights still glitter, music sways
[00:03:00,546 –> 00:03:05,146] I toast the void behind my face
[00:03:05,146 –> 00:03:10,466] Another night, another role
[00:03:10,466 –> 00:03:15,006] Jazz hands hiding a broken soul
[00:03:15,006 –> 00:03:23,000] (Instrumental fade out)
Recommended Usage#
| Configuration | Recommended Audio Duration | Recommended Prompt Usage | Scenario |
|---|---|---|---|
| Low Cost | Under 60 Minutes | A custom prompt within 50 words, depending on the needs. | - Moderation |
| Brief (Low Accuracy Requirement) | Under 60 Minutes | A custom prompt within 50 words, depending on the needs. | - Long-Audio Segmentation - Rough Content Extraction |
| Balanced (General Audio Detailed Description) | Under 2 Minutes | Fixed Structured-Description Prompt | - Fine-Grained Audio Tagging |
| Best (The Most Detailed Description) | Under 1 Minutes | Fixed Structured-Description Prompt | - Complex Acoustic Scenes - Multi-Speaker |
| Note: If you want structured, fine-grained descriptions for longer audio as well, we recommend segmenting it first. |
Fixed Structured-Description Prompt#
Provide a detailed description of the audio.

It should explicitly include two sections:

1. A structured chronological storyline of **every noticeable audio details**
2. A structured speech-to-text transcription, include speaker(Corresponding to the character or voice‑over in Section 1, including their accent and tone), exact spoken content, start timestamp, end timestamp, and speaking state (prosody, emotion, and style). If no speech appears, explicitly state so.

Aside from these two required components, you are free to organize any additional content in any way you find helpful. This additional content can include global information about the entire audio or localized information about specific moments. You may choose the topic of this extra content freely.

Output Format:

```
## Storyline

<xx:xx.xxx> - <xx:xx.xxx>
<an unstructured long paragraph in natural language describing what happened during this period, blending both audio details.>

<xx:xx.xxx> - <xx:xx.xxx>
<an unstructured long paragraph in natural language describing what happened during this period, blending both audio details.>

<xx:xx.xxx> - <xx:xx.xxx>
<an unstructured long paragraph in natural language describing what happened during this period, blending both audio details.>

...

...

## Speakers and Transcript

Speaker profiles:
<speaker> - <profile>
<speaker> - <profile>
<speaker> - <profile>
...

<xx:xx.xxx> - <xx:xx.xxx>
Speaker: <speaker>
State: <description>
Content: “<content>”

<xx:xx.xxx> - <xx:xx.xxx>
Speaker: <speaker>
State: <description>
Content: “<content>”

<xx:xx.xxx> - <xx:xx.xxx>
Speaker: <speaker>
State: <description>
Content: “<content>”

...

## <another section>

<paragraphs>

## <another section>

<paragraphs>

...
```
Play with Qwen3.5-Omni#
Chat with Qwen3.5-Omni#
Feel free to use Qwen3.5 on Qwen Chat.
ModelStudio#
Users can also access our flagship model, Qwen3.5-Plus-Omni, through Alibaba Cloud Model Studio. Two invocation modes are currently supported: Offline Invocation and Realtime Invocation.
To enable web search, simply pass the following parameter:
enable_searchEnables web search functionality
Offline Invocation#
Example code is provided below:
# Preparation before running:
# Run the following command to install third-party dependencies
# pip install numpy soundfile openai
=
# Audio and video analysis
=
# Process the text part
# Web search
=
Realtime Invocation#
Example code is provided below:
# Dependencies: dashscope >= 1.23.9, pyaudio
# Configuration: endpoint, API key, voice, model, and system instructions
# Specify the region: set to cn for mainland China (Beijing), or intl for international (Singapore)
=
=
= f
# Configure the API key. If no environment variable is set, replace the line below with: dashscope.api_key = "sk-xxx"
=
# Specify the voice
=
# Specify the model
=
# Specify the system instructions
=
=
= None
# Initialize audio output stream
=
# Play audio
== :
# Print transcription text
== :
# Print assistant response text
# 1. Initialize audio device
=
# 2. Create callback and conversation session
=
=
# 3. Connect and configure the session
# 4. Initialize audio input stream
=
# 5. Main loop for processing audio input
=
# Clean up resources
Qwen3.5-Omni Voice List#
Chinese and English Custom Voice (5 Speakers)
| Voice | Language | Voice Description | Text | Sample |
|---|---|---|---|---|
| Tina | Chinese | Like a warm cup of milk tea, this voice feels soft and comforting, with a steady core when it comes to solving problems. | 阳光晒得被子软软的,手边的茶还冒着热气,待办事项也一件件完成了。没有惊天动地,但每一件小事都稳稳当当,这样的日子,真的让人觉得,幸福就在此刻呀!接下来,我们一起把下一件小事也好好完成吧~ | |
| Cindy | Chinese (Taiwanese accent) | Soft-spoken, sweet, and effortlessly lovable. | 对~因为我其实从小到大,嗯,没有太怎么去吃过这种类型的东西啊。真的,因为我小的时候,我跟你讲,我小时候其实是有养过小兔子。 | |
| Liora Mira | Chinese | Cozy, grounded, and gentle in all the right ways. | 对对,我第二次去的话,老师跟我说,欸,你进步很大啊,哈哈,所以我就觉得而且他说的我基本上我发现我配音中的气息也变强了。 | |
| Sunnybobi | Chinese | Easy to be around, with a natural warmth and just a hint of shyness. | 我好像很少,就是除非说,这个地方我很想去,但是,一个人又不太方便的时候我会叫朋友。但大部分我都还是愿意自己一个人逛的,嗯,嗯毕竟比较i,对,哼哼。 | |
| Raymond | Chinese | Clear and bright, with the kind of relaxed, homebody charm that feels instantly familiar. | 嗯,可以,纽约堡是吗?它是不是那种就是偏美式一点那种汉堡呀,啊。 |
Chinese and English Scenario Voices (19 Speakers)
| Scenarios | Voice | Language | Voice Description | Text | Sample |
|---|---|---|---|---|---|
| Emotional Companionship - Healing Warmth | Ethan | Chinese | Bright and youthful, with a light northern Mandarin accent. | 那应该是我现在吧,我觉得现在就非常幸福。 | |
| Theo Calm | Chinese | Here to listen, connect, and offer warmth and support. | 呵,太好了。阳光升起的时候呀,葡萄会充满生机,我觉得你也会一样。你要记住啊,每个清晨都是新的开始,保持这份宁静的心,我呢会一直在这里,随时支持你。 | ||
| Serena | Chinese | A naturally sweet voice with a kind and graceful feel. | 其实我真的有发现,我是一个特别善于观察别人情绪的人。 | ||
| Harvey | English | Deep, gentle, and shaped by experience, with the quiet familiarity of coffee and old books. | Then by the end of the movie, when Dorothy clicks her heels and says, “There’s no place like home,” I got a little bit teary, I’ll admit. You know, I don’t even know why—I just, I just felt. | ||
| Maia | Chinese | Smart, soft, and easy to like. | 我呵,你怎么知道我挺会背诗的?你是不是对我有一些了解?我高中语文也不是特别好吧,大概也就是全年级前十吧。 | ||
| Emotional Companionship - Energetic Personality | Evan | Chinese | Curious, upbeat, and full of youthful energy. | 哈喽,我是阿晨,姐姐今天累不累呀?有没有好好吃饭?哪怕只吃了一小口,也请对自己说一句辛苦了。生活常让你怀疑自己,但我想轻轻告诉你,那些你走过的路,扛下的事,都在证明你比想象中更强大。 | |
| Qiao | Chinese (Taiwanese accent) | Sweet on first impression, with plenty of personality underneath. | 什么嘛,你男朋友回来关我什么事啊?我的周末就不是周末,要不要我的约会也跟你换啊?哎,我告诉你,我这周末要去参加我阿妈的生日聚餐,这可是半年前就约好的。 | ||
| Momo | Chinese | Playful, a little offbeat, and full of good energy. | 我命令你们这些小男生,晚上早一点睡觉,听到没有。 | ||
| Wil | Chinese | Easygoing and youthful, with a subtle Shenzhen accent. | 对啊对啊,呃我们是骑那个就是,比较少人走的一条捷径路哦,哎就是那种小,有点像小巷子那种路。 | ||
| Angel | Chinese | Sweet and friendly, with just a touch of local character. | 屋顶很漂亮,所以在欧洲的话一定要抬头,不可以一直看手机,要抬头看屋顶,呃,上面有很多画,可是要注意小偷。可是我这整个过程中其实都呃没有遇到有人要偷我东西,当然我身上也没有钱,他没有东西可以偷。 | ||
| Role Playing | Li Cassian | Chinese | Commanding and self-possessed, with an air of mystery and restraint. | 哎呦喂,你们这帮小崽子一天天的没别的事儿干,就是喜欢下棋。正好儿啊,杂家今儿个高兴儿,跟你们呀就说道说道这棋该怎么下。 | |
| Mia | English | Delicate and soothing, with a quiet charm that brings calm to everyday life. | Hey, friends, welcome back. I hope you're doing well today and that wherever you're watching from. You're feeling a little warm, a little calm. Maybe even holding your favorite drink. You know, something soft to settle into the day with. | ||
| Joyner | English | Equal parts theatrical and down-to-earth, with a sharp sense of humor. | Ah, come on, Frankie. That guy? Nah, he's probably just what, fainted from boredom or something. Watching that press go up and down all night. It's like what, watching paint dry, but you know, louder. Bet he saw his life flash before his eyes, right? | ||
| Gold | English | Confident, raw, and grounded in real underground energy. | This shit don’t make no sense, dawg. I’ve been tryna tell everybody that this whole AI shit — yo, they taking over the game. Soon enough, we go be dating robots. | ||
| Game and Anime Voice Acting | Katerina | English | Polished and mature, with a tone that stays with you. | Hello, how are you today? I'm doing great. | |
| Ryan | English | Stage-trained, with the presence and control that come from live performance. | You bet. Old misses Perkins down the lane makes Jasmine honey cakes. That'll make your toast curl with delight. Kids sneak blossoms into lemonade stands, 10 petals per cup for extra magic, they'll tell you, with grass stained grins. | ||
| Jennifer | English | Crisp, resonant, and cinematic, with a distinctly American edge. | Hi, my name is Jennifer. I've lived in China for like six years. Do I like China? Yeah, love to have hot pot, super love spicy food. What else? Oh I've been learning Chinese for a long time, was it hard to learn? Absolutely, probably the hardest thing that I've ever had to do, but little time, patience. What about you? Or are you finding learning Chinese good? | ||
| Aiden | English | Down-to-earth and approachable, with the easy warmth of someone who loves to cook. | When I have to work late into the night, the thing that really keeps me awake is definitely coffee like I'll get a coffee at around three pm something like that and that'll keep me pretty hyped up for most of the night if I have to work like extra late then yeah I'll do something like another coffee maybe um I don't know like with my dinner after dinner yeah after dinner coffee. | ||
| Mione | English | Like talking to a longtime friend who’s thoughtful, perceptive, and wise. | So yeah, that’s my favorite hobby — I could probably go on for even longer, but, um, that’s my favorite hobby collecting Sunny Angels. There are so many more, to collect, and I can’t wait to build my collection, and, continue, persevering with this hobby. And, yeah, I really like collecting Sunny Angels. |
Chinese Dialect Voices (8 Speakers)
| Voice | Language | Voice Description | Text | Sample |
|---|---|---|---|---|
| Sunny | Sichuanese | Sweet and lively, with a subtle Sichuan flavor. | 胖娃儿胖嘟嘟,骑马上成都,成都有好耍,胖娃儿骑白马,白马跳得高,胖娃儿耍关刀,关刀耍得远,胖娃儿吃汤圆。 | |
| Dylan | Beijing Mandarin | Grounded and confident, with a classic Beijing feel. | 我们家那边后面有一个后山,就护城河那边儿。完了呢我们就在山上啊,就是其实也没什么,就是在土坡上跑来跑去,然后谁捡个那个嗯比较威风的棍儿,完了我们就就瞎打,呃要不就是什么掏个洞啊什么的。 | |
| Eric | Sichuanese | Fresh, sharp, and full of streetwise energy. | 你龟儿子搞啥子名堂嘛,把事情弄成这个样子老子要被你气死了,我看到你这个样子我心头都冒火,毛焦火辣的气都不打一处来,你龟儿太过分了,把我的东西都搞坏了,还晓不晓得认错,硬是要把我整冒火你才安逸唆,莫再烦老子爬球开。 | |
| Peter | Tianjin Dialect | Dry, steady, and effortlessly funny. | 越线了啊,你心中纵有万千苦,不能往我们心窝儿杵,咱不朋友嘛。算了,把我这嘴皮子磨烂也给你们讲不明白。蝎了虎子掉面缸,听完你们光剩眨么眼儿了。我再说最后一次啊,我介不是走,是绝交,啊。他说我是小肚子拉口儿二波一,木鱼儿改梆子挨敲的货,面茶里煮元宵,混蛋沉底带砸锅。哼,从今儿起,咱就是天津大麻花啊,彻底掰了。 | |
| Joseph Chen | Minnan | Warm and seasoned, with the voice of an overseas Chinese speaker shaped by Southeast Asian roots. | 爱伫黄内底佫带小可青青,皮若是黄黄小可青青,表示会当买转去的,佫囥两三工来食拄仔好。 | |
| Marcus | Shaanxi Dialect | Bold and unpolished in the best way, with a strong regional character. | 诶,伙计,你说这人活成嘛了,一天到黑忙得跟钟楼底下的车一样,堵得心慌。诶,老板催报表吗?孙娃作业要签字吗?屋里老嫂子还嫌我不陪她逛骡马市。 | |
| Li | Nanjing Dialect | Gruff, expressive, and oddly charming when the complaints start rolling in. | 哎!老头儿!让一下诶!没得长眼睛啊。你哪个?老十三的在这个叫魂啊!急着给投胎去呀。xxx这么叼宽的巷子你过不去啊我过你个吊啊你麻痹你把这马扎子摆到路中间这个巷子是你家开的呀 | |
| Rocky | Cantonese | Full of Cantonese flavor, with great comedic timing and crisp tonal control. | 其实真系咁噶呵,即系人咧 |
Multilingual Voice (23 Speakers)
| Voice | Language | Voice Description | Text | Sample |
|---|---|---|---|---|
| Sohee | Korean | Gentle, cheerful Korean unnie full of emotion. | 친구들이 나한테 좀 그러더라, 선물에 내 성격이 좀 담겨 있대 그래서 차분하고 조용한 선물을 고르는 스타일이긴 한데 그게 내가 그 사람을 좀 진짜로 생각하고 있다는 방식이라서 내가 표현하는 방식 중의 하나인 것 같아. 결론은 이제 평소에 말해 줬던 작은 힌트를 기억을 해서 그 사람의 하루에 좀 스며들 수 있는 그런 선물. 그걸은 내가 가장 많이 고르는 스타일이지. | |
| Lenn | German | Calm in suits, rebellious through post-punk. | Das ist eine nette Überraschung! | |
| Ono Anna | Japanese | Mischievous childhood sweetheart. | おかしいな、内部でガチャガチャ音がしてる。あっ、もしかして救急トレイにA3とA4が混ざってる?あー、誰かが両面スキャナーの保護シートを剥がし忘れてます。これじゃ確認できないのも当然です。 | |
| Sonrisa | Spanish | Warm, cheerful Latin American lady. | Claro que sí, imagínate sentado en esas sillas verdes tan bonitas con un café recién hecho que huele a canela. Hasta los libros viejos de la estantería parecen sonreír cuando alguien los hojea y el tocadiscos está poniendo un vals que te hará mover los pies sin darte cuenta. Es como viajar en el tiempo pero con buen humor. | |
| Bodega | Spanish | His laughter booms across the room and his opinions are delivered with fervor; he is a quintessential passionate Spanish tío who feels everything deeply. | Claro que sí, imagina caminar sobre esa alfombra de hojas doradas crujiente bajo tus pies mientras el olor a canela de la panadería te guía hacia las mesitas con mantel a cuadros hasta el viento parece tararear la melodía de la guitarra. | |
| Emilien | French | Romantic French big brother. | Bien sûr, passons à des questions plus générales : pour toi, quelle était l'opportunité qui t'a conduit à t'impliquer dans l'industrie du doublage ? | |
| Andre | Portuguese | When this Portuguese guy speaks, his naturally comfortable and steady voice acts as a magnetic force, drawing you into a state of total relaxation. | Ouvimos fazer compras no mercado local sim às vezes vou ao mercado local às vezes vou a supermercados maiores depende da compra que eu fazer depende onde estou às vezes quando viajo gosto de ir a mercados locais quer para ver que as pessoas dessa zona comem o que é que comem o que é que compram o que é que produzem não é que tipo de legumes que tipo de frutas aí vou aos mercados locais e normalmente no mercado local acho que a comida costuma ser mais saudável do que num supermercado. | |
| Radio Gol | Portuguese | His voice cuts through the stadium noise, a steady stream of Portuguese analysis that builds tension until the final whistle. | Ei você sentiu aquele cheiro de pão fresco parece que vem da padaria da esquina né? Tô com vontade de dar uma passada lá. | |
| Alek | Russian | Chill Russian, warm woolen soul. | Конечно, знаешь, эти ржавые ворота как старый актер, который готов рассказать тысячу веселых историй. Вот например: раньше здесь кузнецы соревновались кто громче молотом стукнет, а детишки за орешками бегали, даже осенние листья тогда танцевали под музыку кузнечных мехов. | |
| Rizky | Indonesian | His voice has a soft, distinctive lilt common in Indonesia, making every word he speaks sound gentle yet remarkably clear. | Nah. Waktu itu tuh ada teman yang ngedengar cara aku bacain iklan di radio, terus dia bilang eh suara lu kayaknya cocok banget deh buat jadi voice over talent. Mau nyoba enggak? Gitu. | |
| Roya | Persian | Sports-loving girl with a free spirit. | وَقْتی اَز دوچَرْخِهٔ ثابِت اِسْتِفادِه میکُنی، خِیلی فِشار رو رویِ مَفاصِلِت اِحْساس نِمیکُنی.فِشار کَمتَرِه، مَخْصوصاً بَرایِ کِسایی کِه زانو دَرْد دارَنْ یا تازِه میخوان وَرْزِش رو شُروع کُنَنْ | |
| Arda | Turkish | Balanced Turkish voice: clean, smooth, warm. | Yeni bir bilgi öğrenirken araştırma mı yoksa deneyerek keşfetme mi dersek, aslında ben ikisinin karışımını seviyorum. Bir konuyu temel olarak araştırıp zemin oluşturduktan sonra mutlaka deneyerek öğrenmeyi tercih ediyorum. Çünkü sadece teorik bilgi insanın kafasında soyut kalıyor. Deneyince bilginin kıvrımlarını keşferiyorsun. | |
| Hana | Vietnamese | Mature Vietnamese woman with big-sister energy. | Ừm, nếu hỏi tấm hình nào trong điện thoại gần đây nhất mà buồn cười nhất á thì chắc là tấm chụp con chó nhà mình, trời ơi, nó làm mình không nhịn được luôn ấy. | |
| Dolce | Italian | Leaning against a sun-drenched wall with effortless cool, he is a laid-back Italian uncle whose voice flows as smoothly as good Chianti. | Ma dìgli altri cinque minuti, per favore dai sono ancora così assonnato. | |
| Jakub | Polish | An artistic young man from a Polish town with a magnetic, sexy voice. | No wiesz, chodziło mi o ten most. O świcie jak mgła nad rzeką jeszcze jest, a kamienie po deszczu tak błyszczą. Stary Janek z piekarni mówił, że o tej porze wygląda jak z bajki. I chleb prosto z pieca pachnie najmocniej. | |
| Griet | Dutch | Mature and artistic Dutch woman. | van alleen op straat zijn. En heel veel weiden rondom U, alles is rustig, alles is stil. En de dag lijkt zo eindeloos lang te duren of zo. Snap je, dat zo? | |
| Eliška | Czech | Czech voice full of Central European warmth. | Emm... No, emm... já mám ráda černobílé fotky, protože tam není rušivá barva, jen čistý výraz, světlo a stín. A připadá mi to víc opravdový. | |
| Marina | Hebrew | Her voice carries the distinctive guttural warmth of fluent Hebrew, marking her as a true daughter of the land. | גדלתי במקום שיש בו המון המון תרבויות שונות, והמון שפות שונות. אז אתה לומד איך לתקשר עם אנשים בתרבות אחרת בצורה מאוד ברורה, די מהר. ואז כשעברתי לגור בקנדה, אז בכלל, בוונקובר יש פה כל כך הרבה תרבויות שונות. | |
| Siiri | Finnish | She is a Finnish maiden who carries herself with both wisdom and warmth. | Se oli kokemuksena muutenkin se reissu jotenkin tosi semmonen emme ties silmiä avaava koska se on ympäristönä jotenkin niin erilainen kuitenkin Suomeen verrattuna että kun siellä on kuitenkin hiekkarantoja ja sitten jotenkin siellä oli niin semmonen rento meiininki ja sellaista juhlahumua ja sellaista erilaista emmä oo kai osaa selittää sitä kunnolla mutta se oli jotenkin niin toisenlainen maailma ja mä päätti jo silloin että mä joo jossain kohtaa muuttaa pois Suomesta että mun pitää päästä tällaiseen ympäristöön ja kyllä mä silloin tiesi jo heti että | |
| Ingrid | Norwegian | Raised amidst the rolling hills of rural Norway, she carries the simplicity of country life. | Og så bestemte jeg meg at nå er det på tide, nå må jeg bare prøve om jeg kan klare å få passe på høner, og noe som jeg hadde drømt om da, ikke sant? At du kan gå og plukke egg om morgenen. | |
| Sigga | Icelandic | In a remote corner of Iceland, there lives a young woman defined by her profound wisdom. | Ef við getum orðað það þannig þannig menntaskóla árin eru vissulega mjög eftirminnileg og það sem gerðist líka í menntaskóla er að ég kynntist alveg dásamlegum vinkonum sem eru vinkonur mínar ennþá í dag og við erum tíu saman sem erum í svona sumar klúbbi og kynntust í menntaskóla og við höldum alltaf sambandi og höfum gert alveg síðan. Við bara byrjuðum að verða vinkonur í byrjun menntaskólans. | |
| Bea | Filipino | Meet a sweet girl from the Philippines who simply can't function before her morning coffee. | I'm ready! May kapi na ako,may tissue na rin in case matawa ako or maiyak.Go,go,go! Spill! | |
| Chloe | Malay | She is an office worker navigating the bustling business districts of Malaysia. | Lagi satu, aku cuba kenal bila waktu aku paling cergas. Bagi aku, jadi waktu tu aku kerahkan tenaga buat kerja paling susah. |
Citation#
Feel free to cite the following article if you find Qwen3.5-Omni helpful: