Qwen3-Omni-Flash-2025-12-01:Hear You. See You. Follow Smarter!
QWEN CHAT HUGGING FACE MODELSCOPE DASHSCOPE GITHUB PAPER HUGGING FACE DEMO MODELSCOPE DEMO
Qwen3-Omni is a next-generation native multimodal large model capable of seamlessly processing multiple input modalities—including text, images, audio, and video—and generating both text and natural-sounding speech outputs simultaneously via real-time streaming responses. This version introduces multiple enhancements to improve model performance and efficiency.
Qwen3-Omni-Flash-2025-12-01 is a comprehensively upgraded iteration built upon Qwen3-Omni.
Key highlights of this upgraded version include:
-
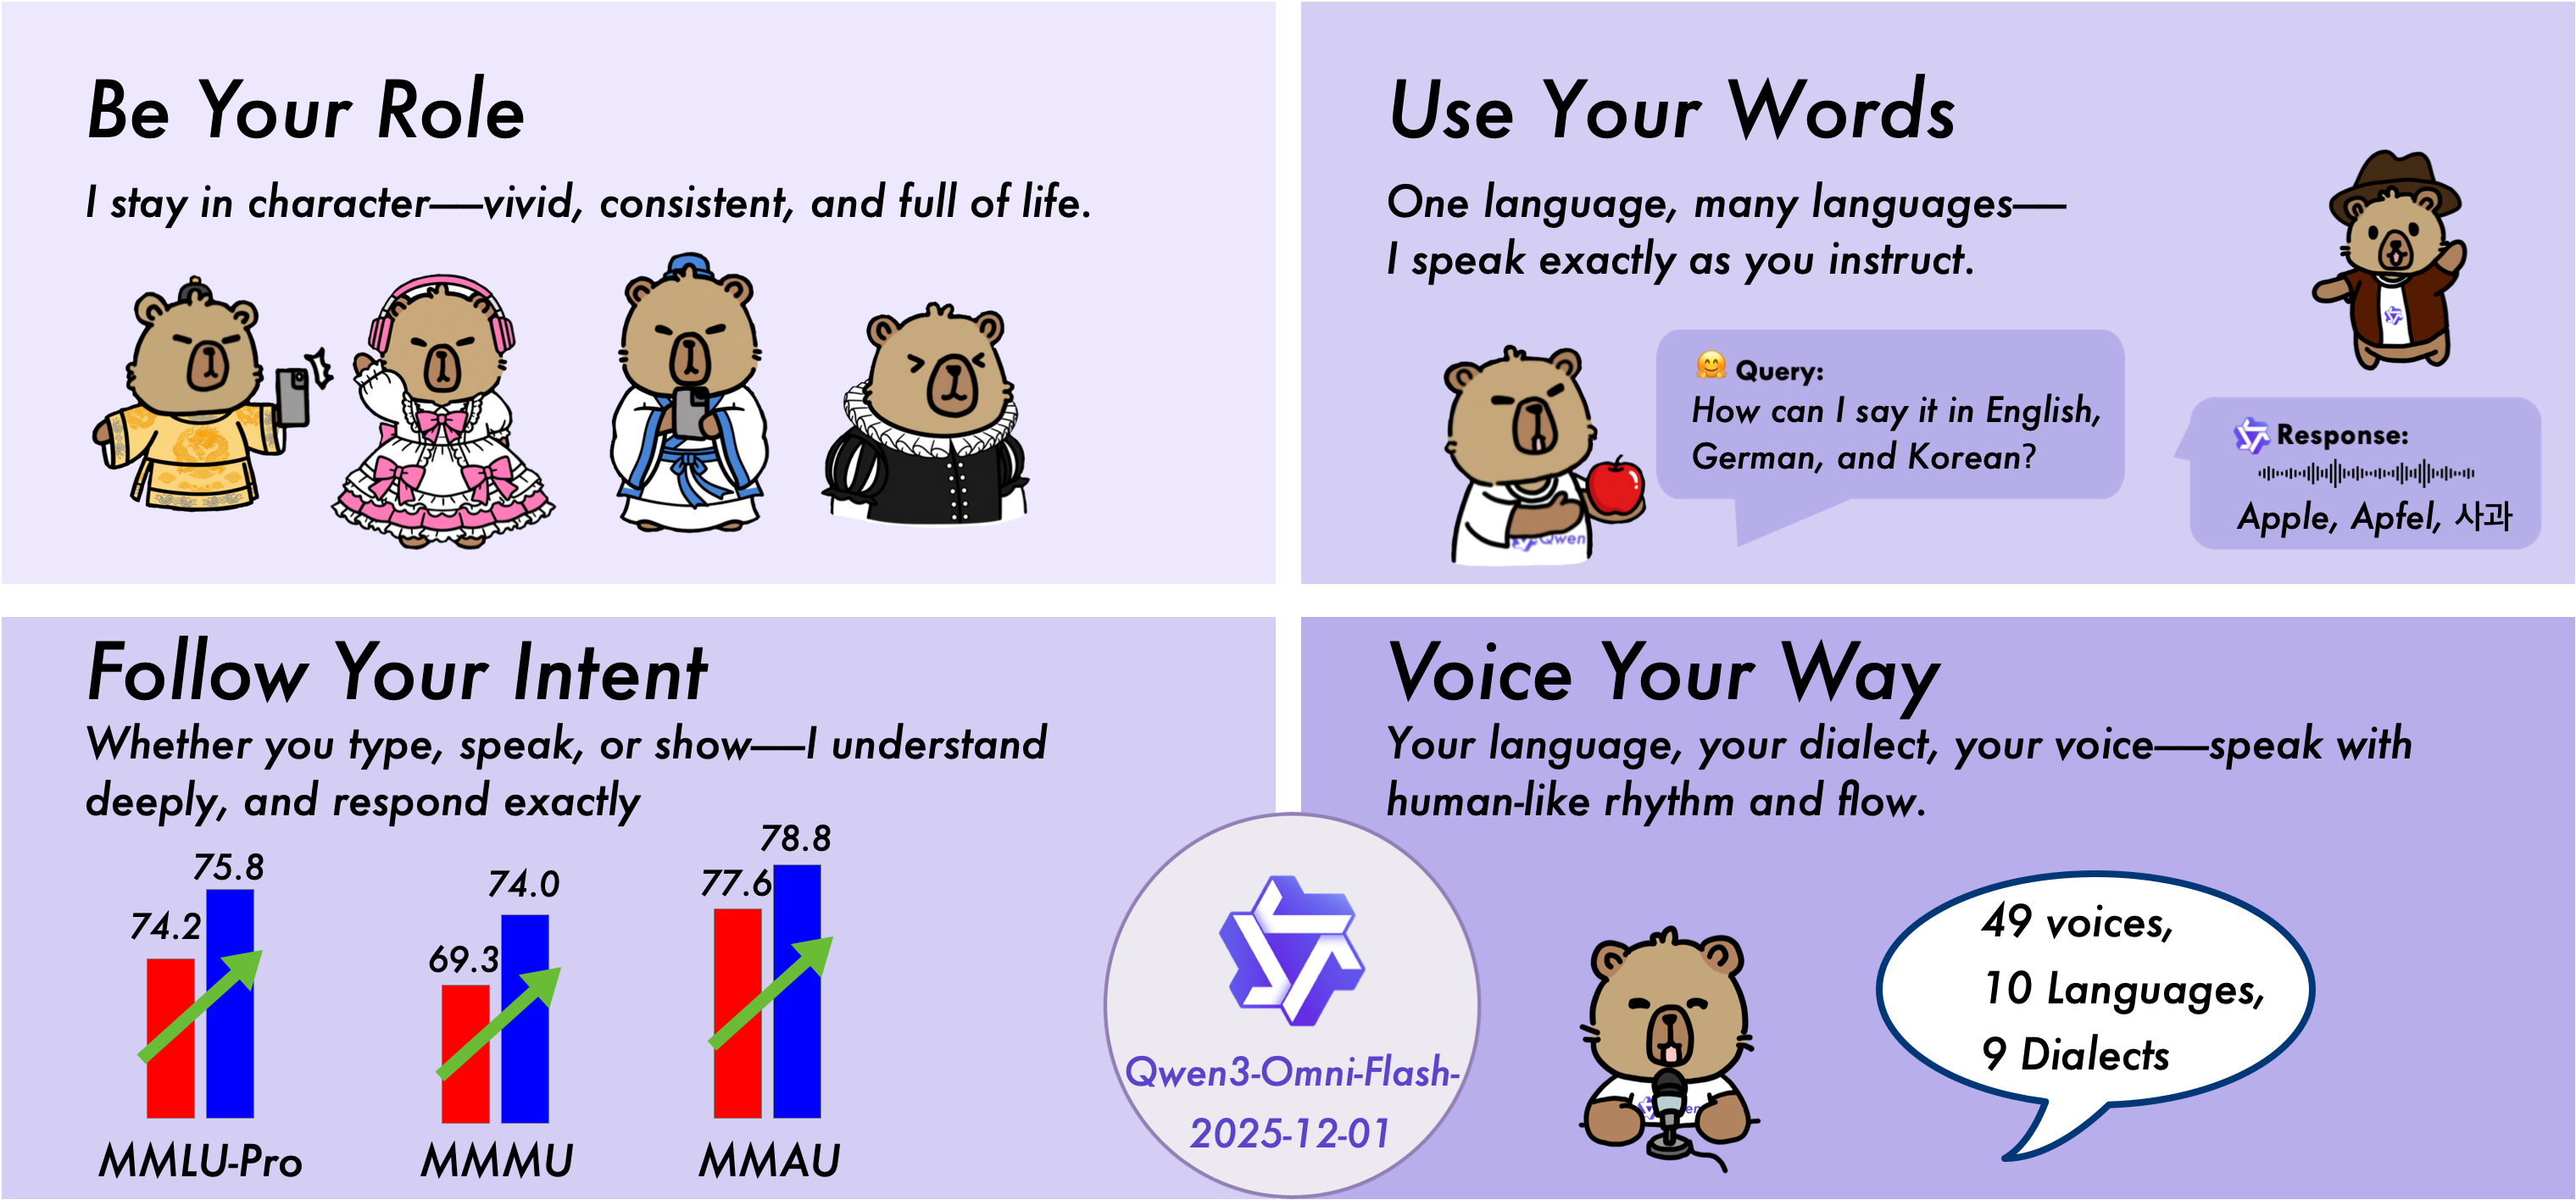
Greatly Enhanced Audio-Visual Interaction Experience: Dramatically improved understanding and execution of audio-visual instructions, effectively resolving the “intelligence drop” issue commonly seen in casual spoken scenarios. Multi-turn audio-visual conversations now achieve significantly higher stability and coherence, enabling more natural and seamless interactions.
-
Strengthened System Prompt Control: Full customization of system prompts is now supported, enabling precise control over model behavior. Whether it’s persona style (e.g., sweet, cool, anime-inspired), colloquial tone preferences, or output length constraints—every detail can be finely tuned, offering unprecedented command over response characteristics.
-
More Reliable Multilingual Compliance: Supports text-based interaction in 119 languages, speech recognition in 19 languages, and speech synthesis in 10 languages. Language-following instability from the previous version has been fully addressed, ensuring accurate and consistent performance across diverse linguistic contexts.
-
More Human-Like and Fluent Speech Synthesis: Eliminates sluggish or robotic speech by significantly enhancing adaptive control over prosody. The model now intelligently adjusts speaking rate, pauses, and intonation based on textual context, delivering expressive, natural-sounding voice output that closely mimics real human speech.
Performance#
On objective benchmarks, Qwen3-Omni-Flash-2025-12-01 achieves substantial improvements across all modalities compared to Qwen3-Omni-Flash:
-
🧠 Stronger Text Understanding & Generation:
Major gains in logical reasoning (ZebraLogic +5.6), code generation (LiveCodeBench-v6 +9.3, MultiPL-E +2.7), and holistic writing quality (WritingBench +2.2), enabling more reliable execution of complex, multi-step instructions. -
👂 More Accurate Speech Understanding:
Significantly lower word error rate on Fleurs-zh, along with a +3.2 improvement on VoiceBench, reflecting enhanced comprehension of spoken language in real-world dialogue scenarios. -
🎙️ More Natural Speech Synthesis:
Higher-quality, human-like voice generation across multiple languages—especially in Chinese and multilingual contexts—with improved prosody, pacing, and pausing that closely mirrors natural human speech. -
👁️ Deeper Image Understanding:
Breakthrough performance on visual reasoning tasks, including +4.7 on MMMU, +4.8 on MMMU-Pro, and +2.2 on MathVision_full, demonstrating a stronger ability to “see,” interpret, and reason about complex visual content—from diagrams to mathematical figures. -
🎬 More Coherent Video Understanding:
Steady improvement in video semantic comprehension (MLVU +1.6), further strengthened by tighter audio-visual synchronization, laying a solid foundation for seamless real-time video conversations.
With this upgrade, Qwen3-Omni-Flash-2025-12-01 truly embodies the vision of “Hear You. See You. Follow Smarter.”—delivering an AI interaction experience that is more natural, precise, and vivid than ever before.

What’s Next#
We are eager to hear your feedback and see the innovative applications you create with Qwen3-Omni. In the near future, we will further advance the model along multiple axes, including multi-speaker ASR, video OCR, audio–video proactive learning, and enhance support for agent-based workflows and function calling.
Citation#
If you find our model helpful in your research, we’d appreciate a citation!