Qwen3.8-LiveTranslate: Names the speaker. Carries the meaning.
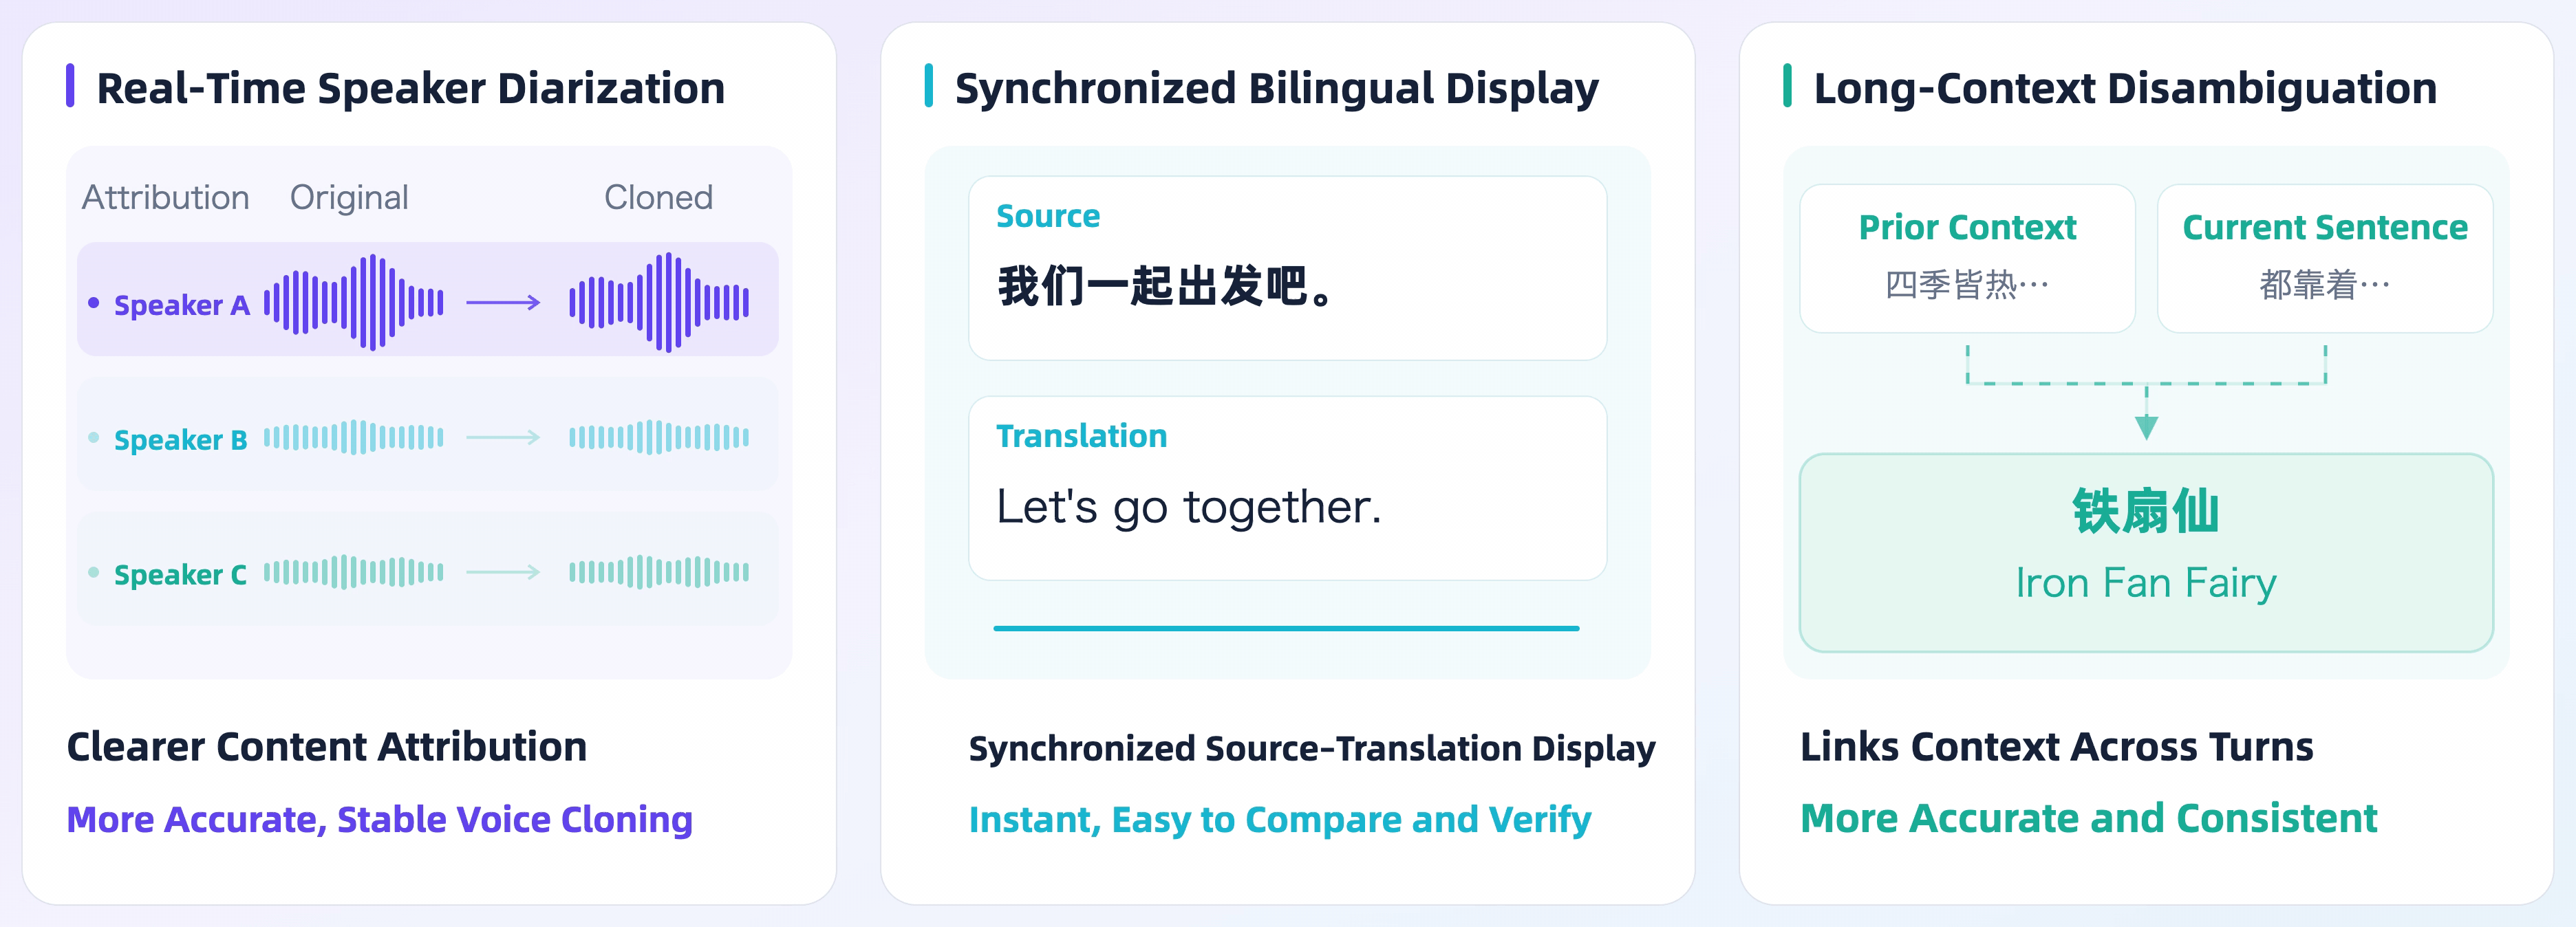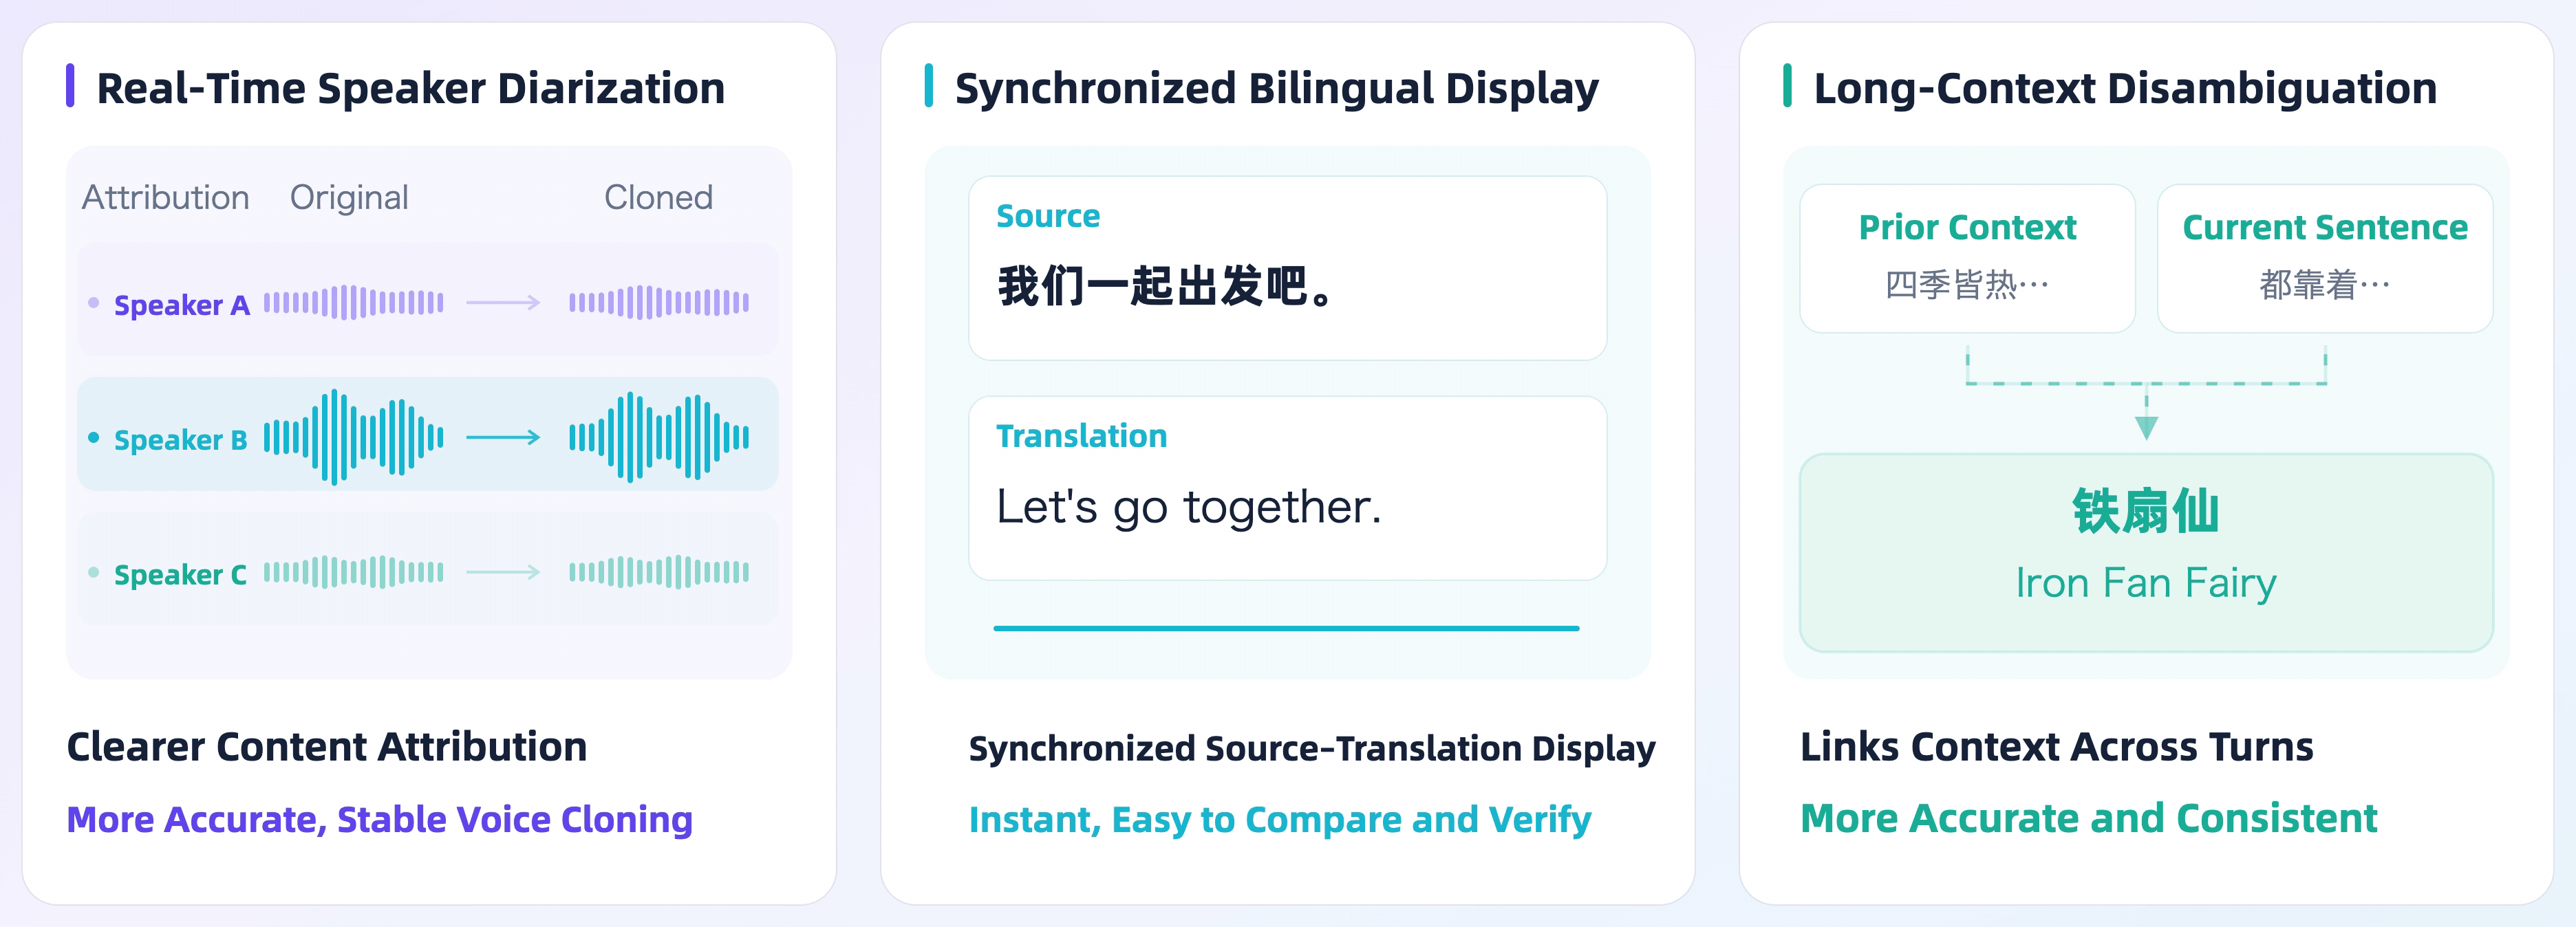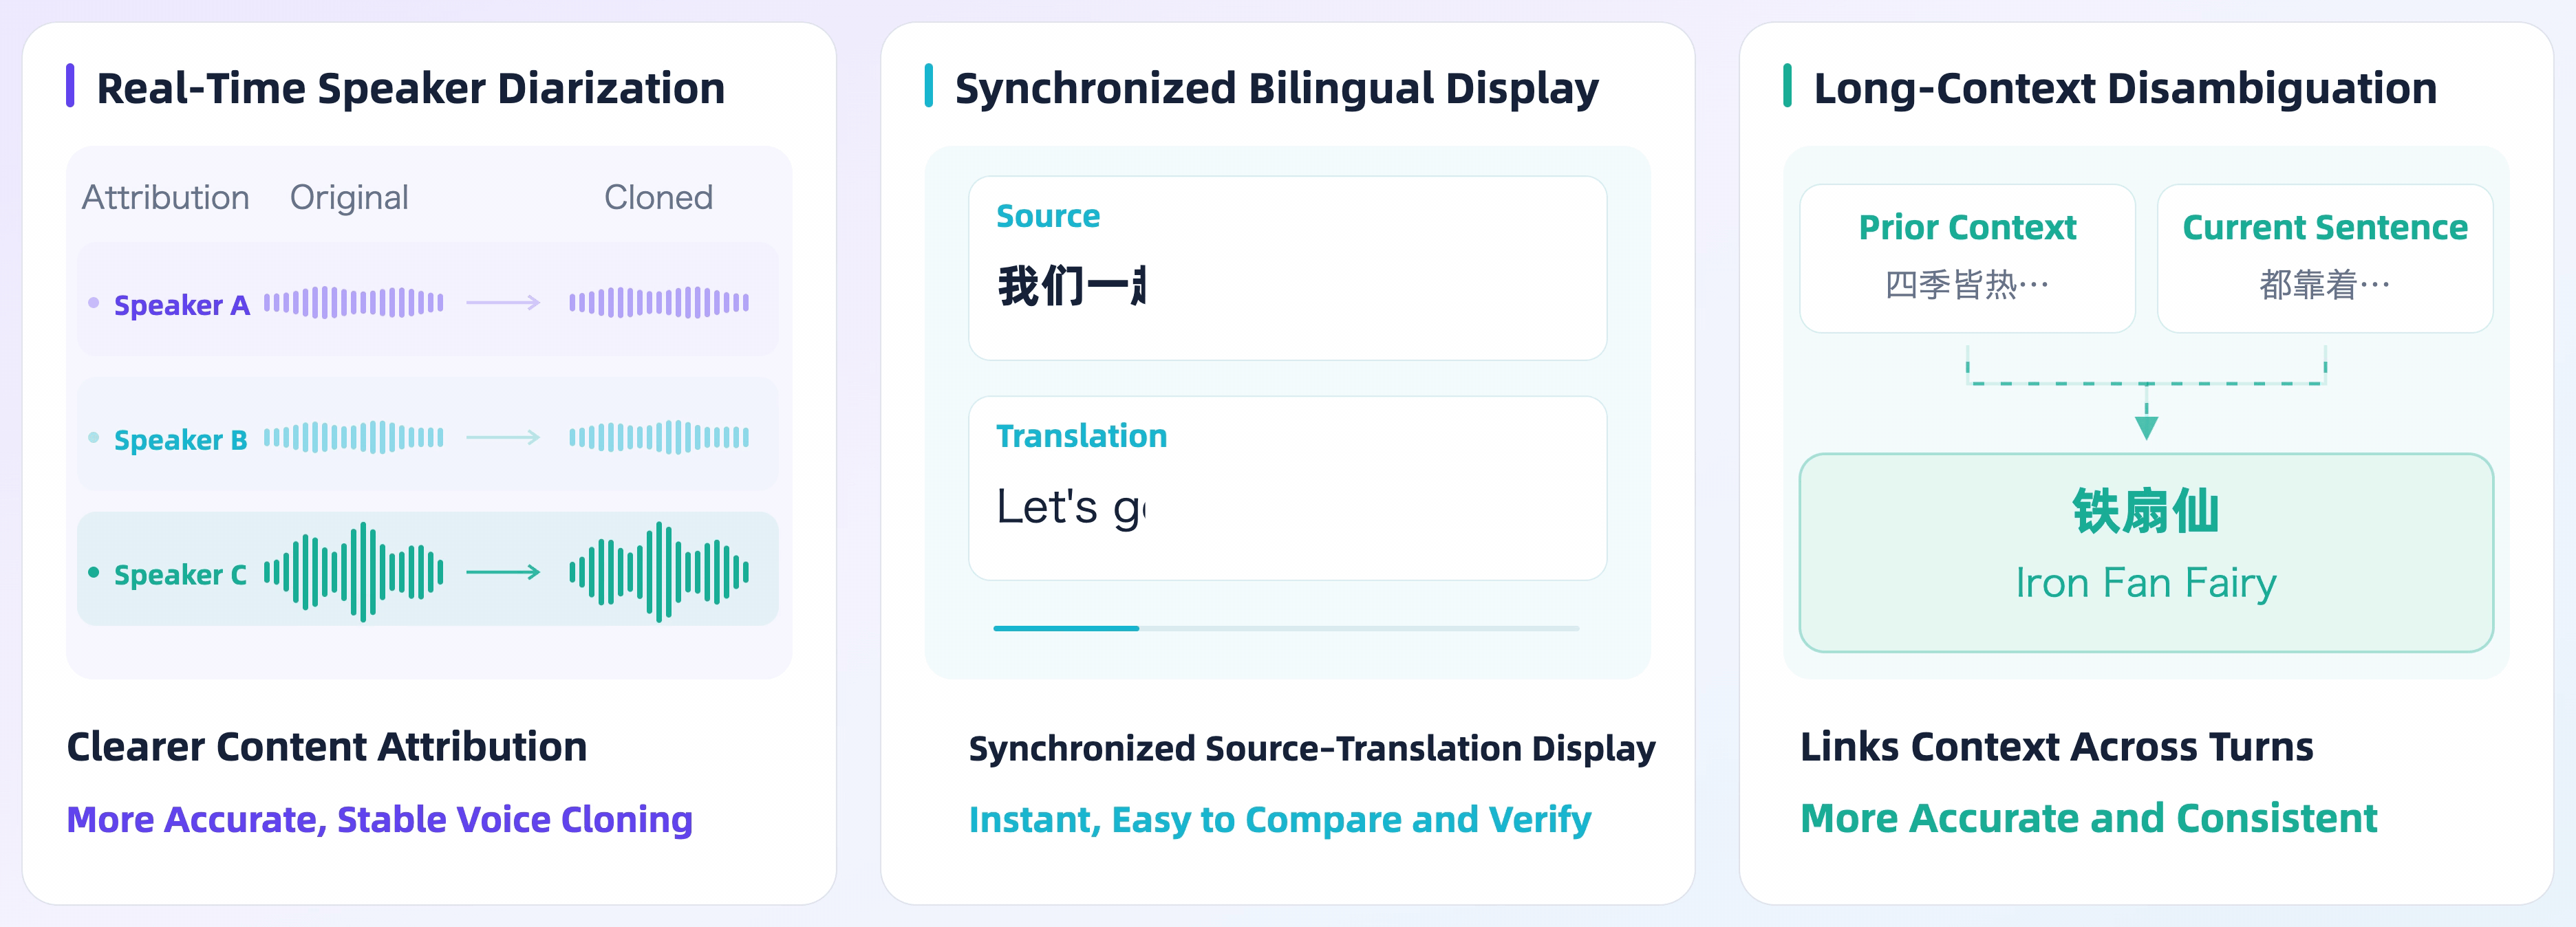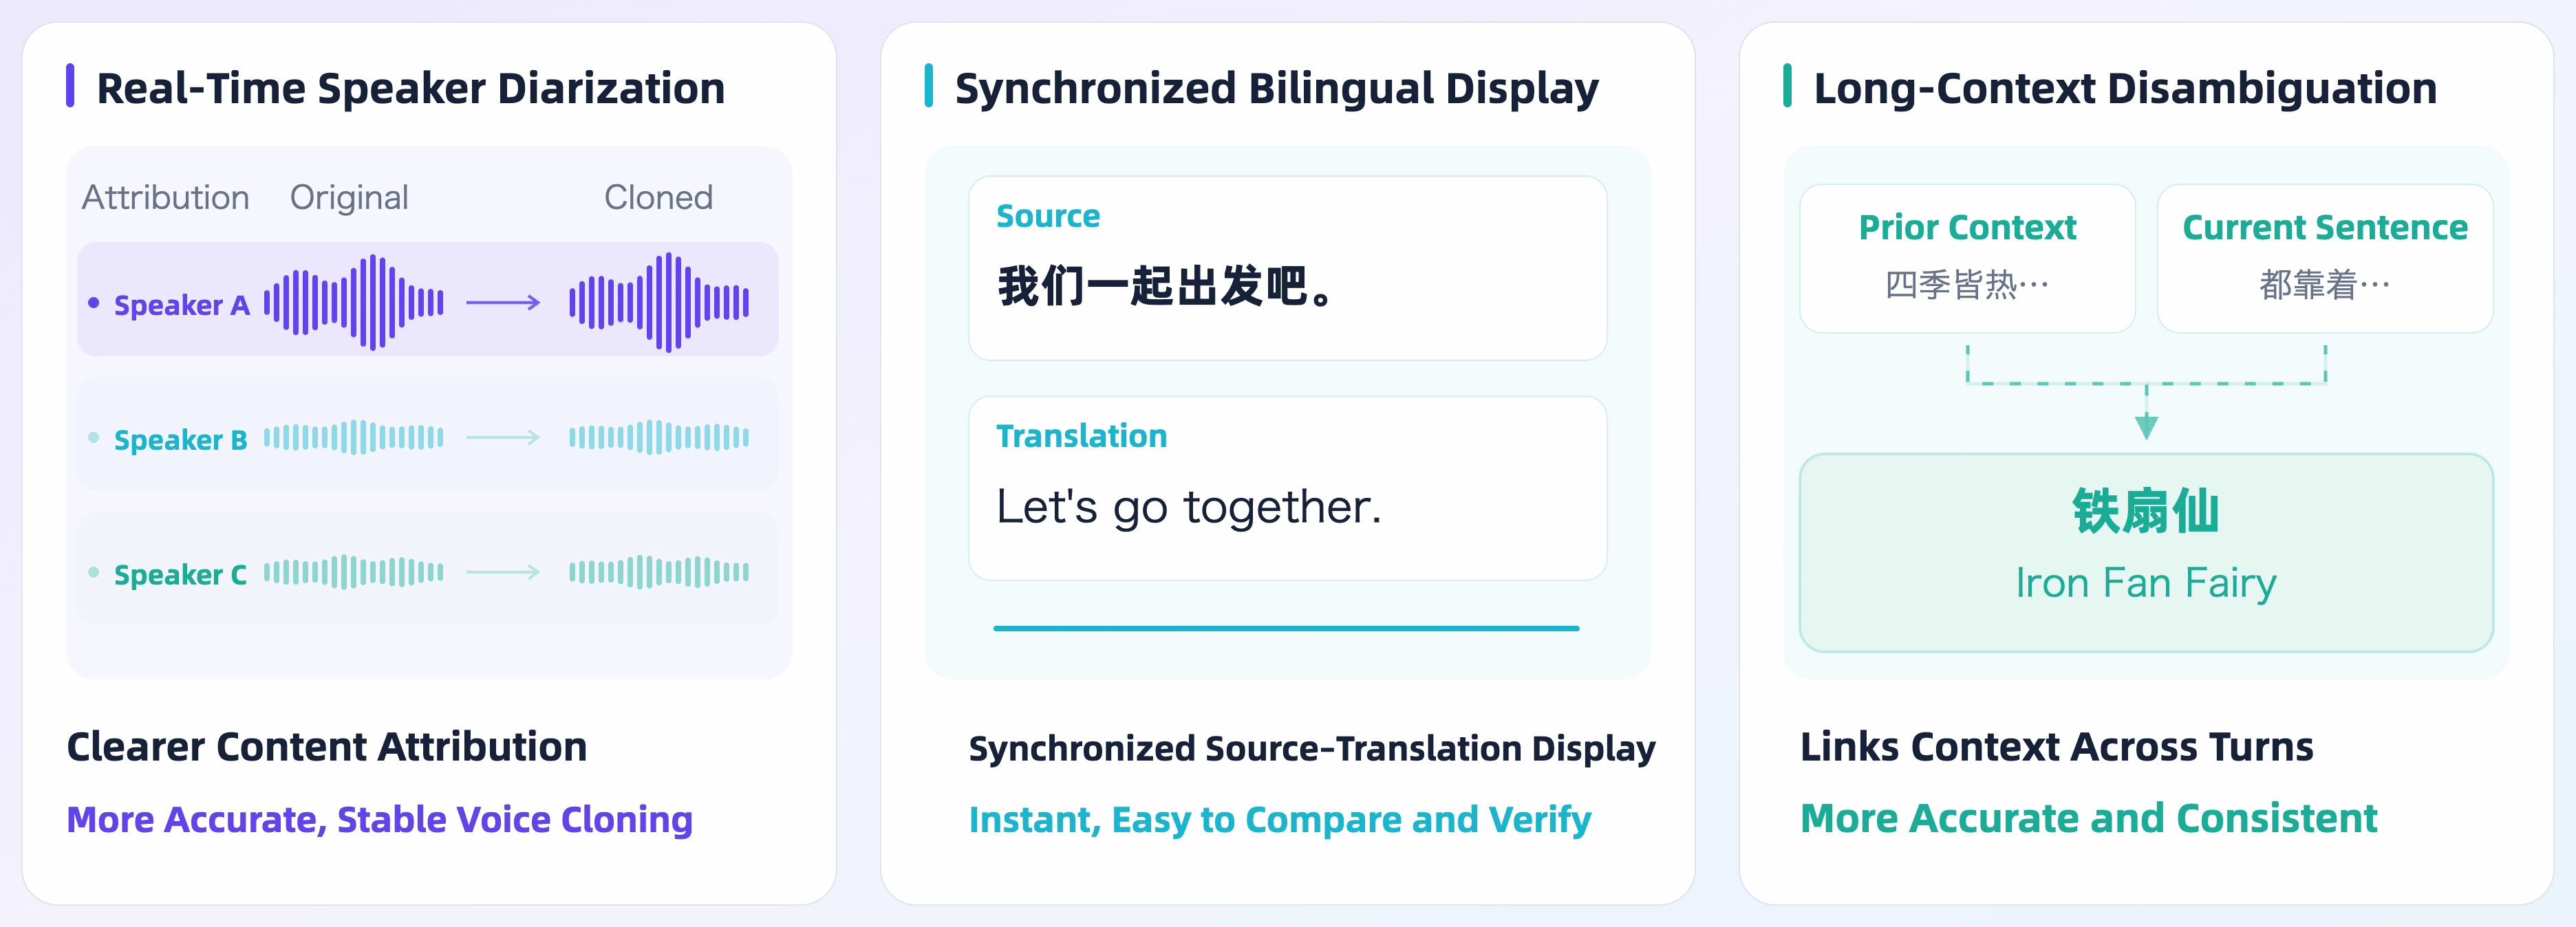
Simultaneous interpretation is not only about translating fast — it must also hear clearly and translate accurately. Qwen3.8-LiveTranslate rebuilds real-time simultaneous interpretation with an Interleave architecture, improving faithfulness, fluency, and conciseness across the board, while average lagging (LAAL) drops from 2.8 seconds to 2.3 seconds. We want simultaneous interpretation to convey not only language but also the people and context behind a conversation. Building on support for 60 languages, Qwen3.8-LiveTranslate adds three capabilities that bring simultaneous interpretation to a wider range of real-world scenarios: real-time speaker separation, with clear attribution for every sentence and more stable voice cloning; synchronized source-and-translation output on one bilingual screen; and long-context disambiguation that reads the present in light of what came before, making names and terminology more precise.
Key Highlights#
-
Interleave architecture: audio and text woven together, higher quality and lower latency. This generation recasts simultaneous interpretation as a single audio-text interleaved stream; both the audio already heard and the translation already produced can be cached and reused, so translation quality improves markedly over the previous generation while average lagging (LAAL) drops from 2.8 seconds in the previous generation to 2.3 seconds.
-
Real-time speaker separation: clearer content attribution, more stable voice cloning. When several people speak in turn, the model distinguishes different speakers and what each of them says, and helps the translated speech preserve each speaker’s timbre more accurately and stably.
-
Synchronized source and translation. Bilingual alignment during interpretation supports both instant comprehension and source checking, laying a foundation for follow-on features such as subtitle display, content organization, and retrieval — with broader room for application.
-
Long-context disambiguation: linking history across turns for more precise translation. By drawing on prior text and historical context, the model eases the ambiguity of proper nouns, references, and the like in complex scenarios, keeping expression consistent.
Model Architecture#
Qwen3.8-LiveTranslate adopts a Hybrid-MoE-based Thinker–Talker two-module design, connecting streaming understanding, text output, and speech generation through interleaving. Here, the Thinker arranges video, audio, source text, and translation into a single causal sequence — interleaved in temporal order and produced end to end — so that understanding and translation happen within one sequence; the Talker then combines the translation and the source audio to synthesize the translation into speech that preserves the original speaker’s timbre.
Performance#
Multi-Speaker Long-Audio#
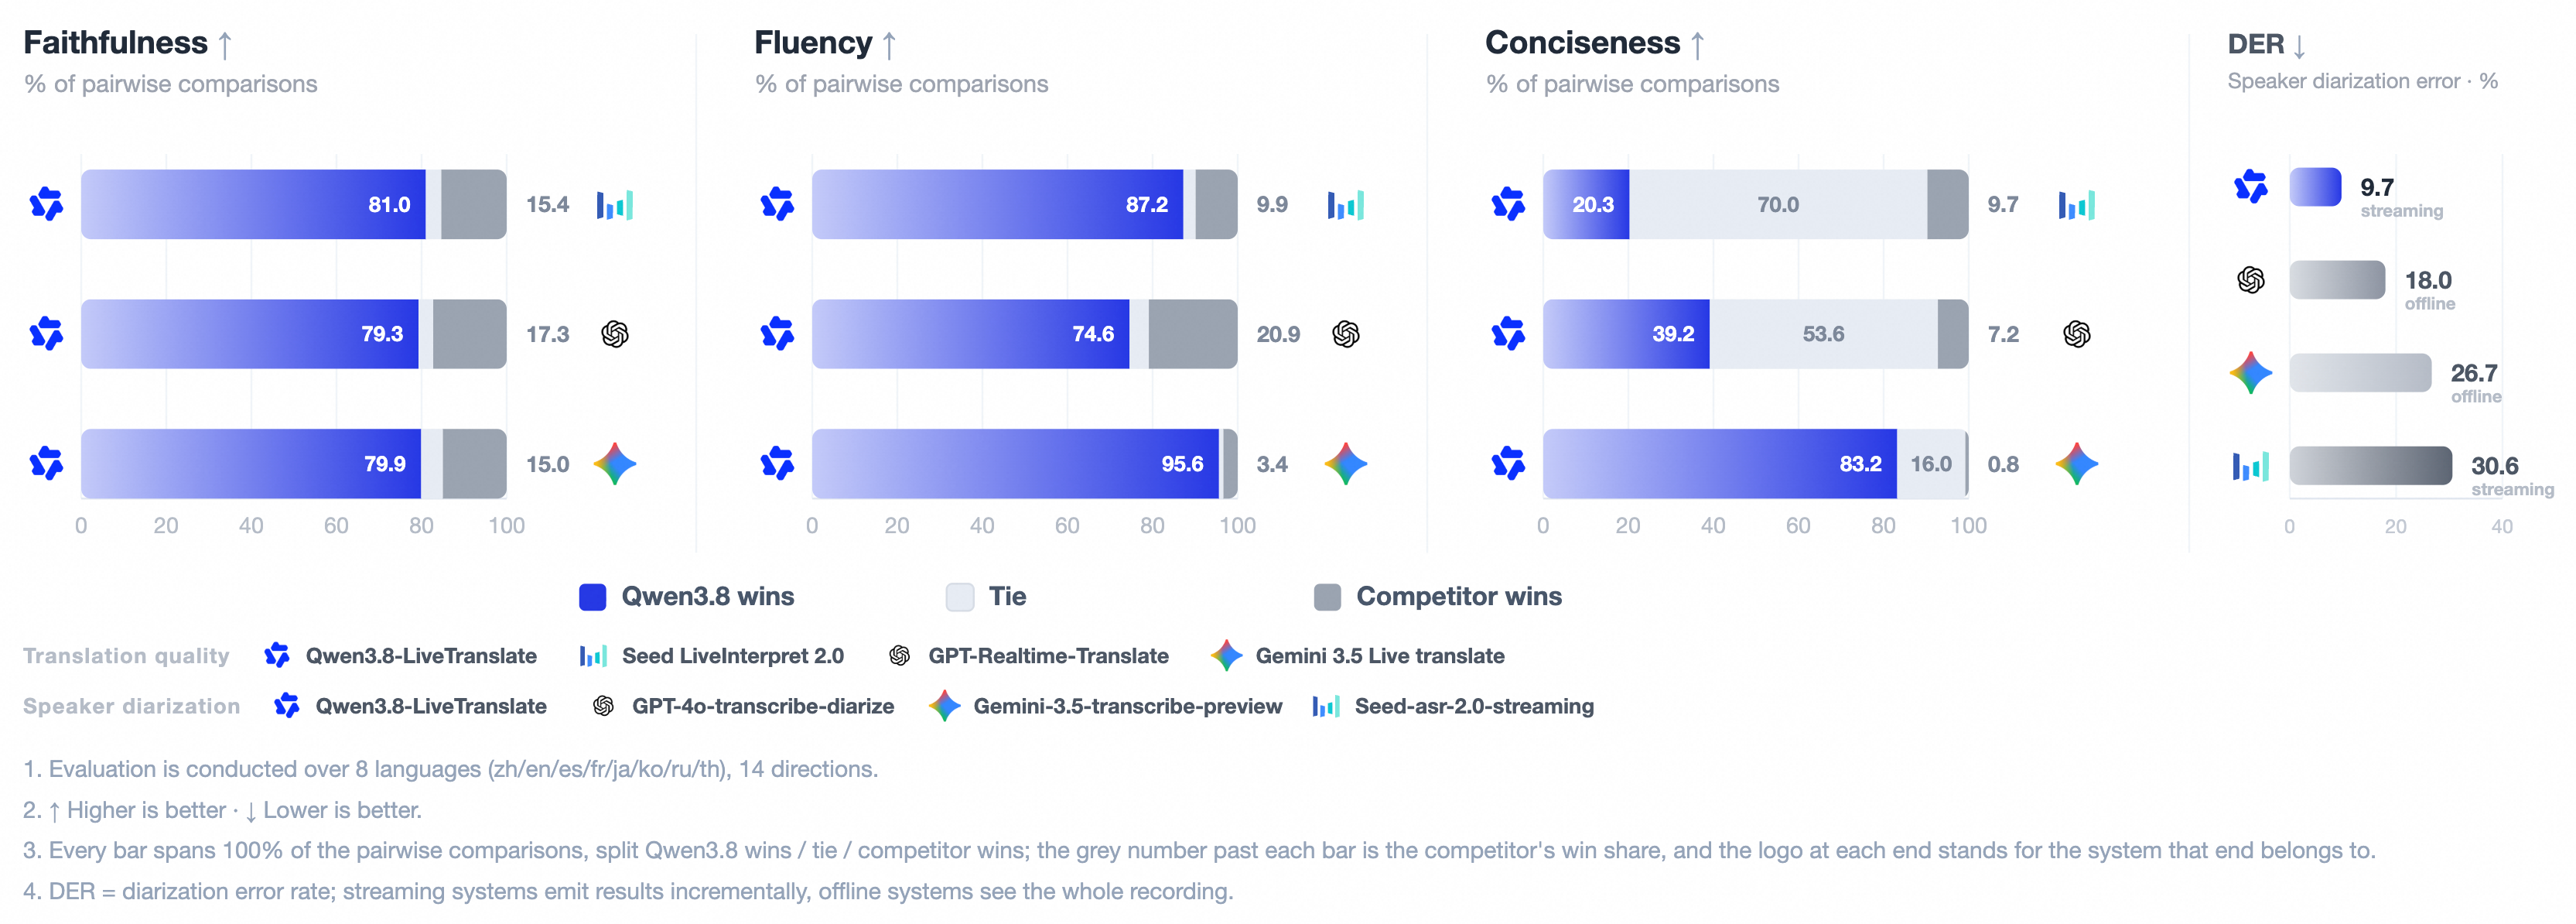
On Omnilingua-MSpeaker, a multi-speaker long-audio evaluation set covering 14 language directions, Qwen3.8-LiveTranslate outperforms today’s mainstream real-time interpretation systems across four dimensions: translation faithfulness, fluency, and conciseness, together with the Diarization Error Rate (DER).
Multilingual Performance#
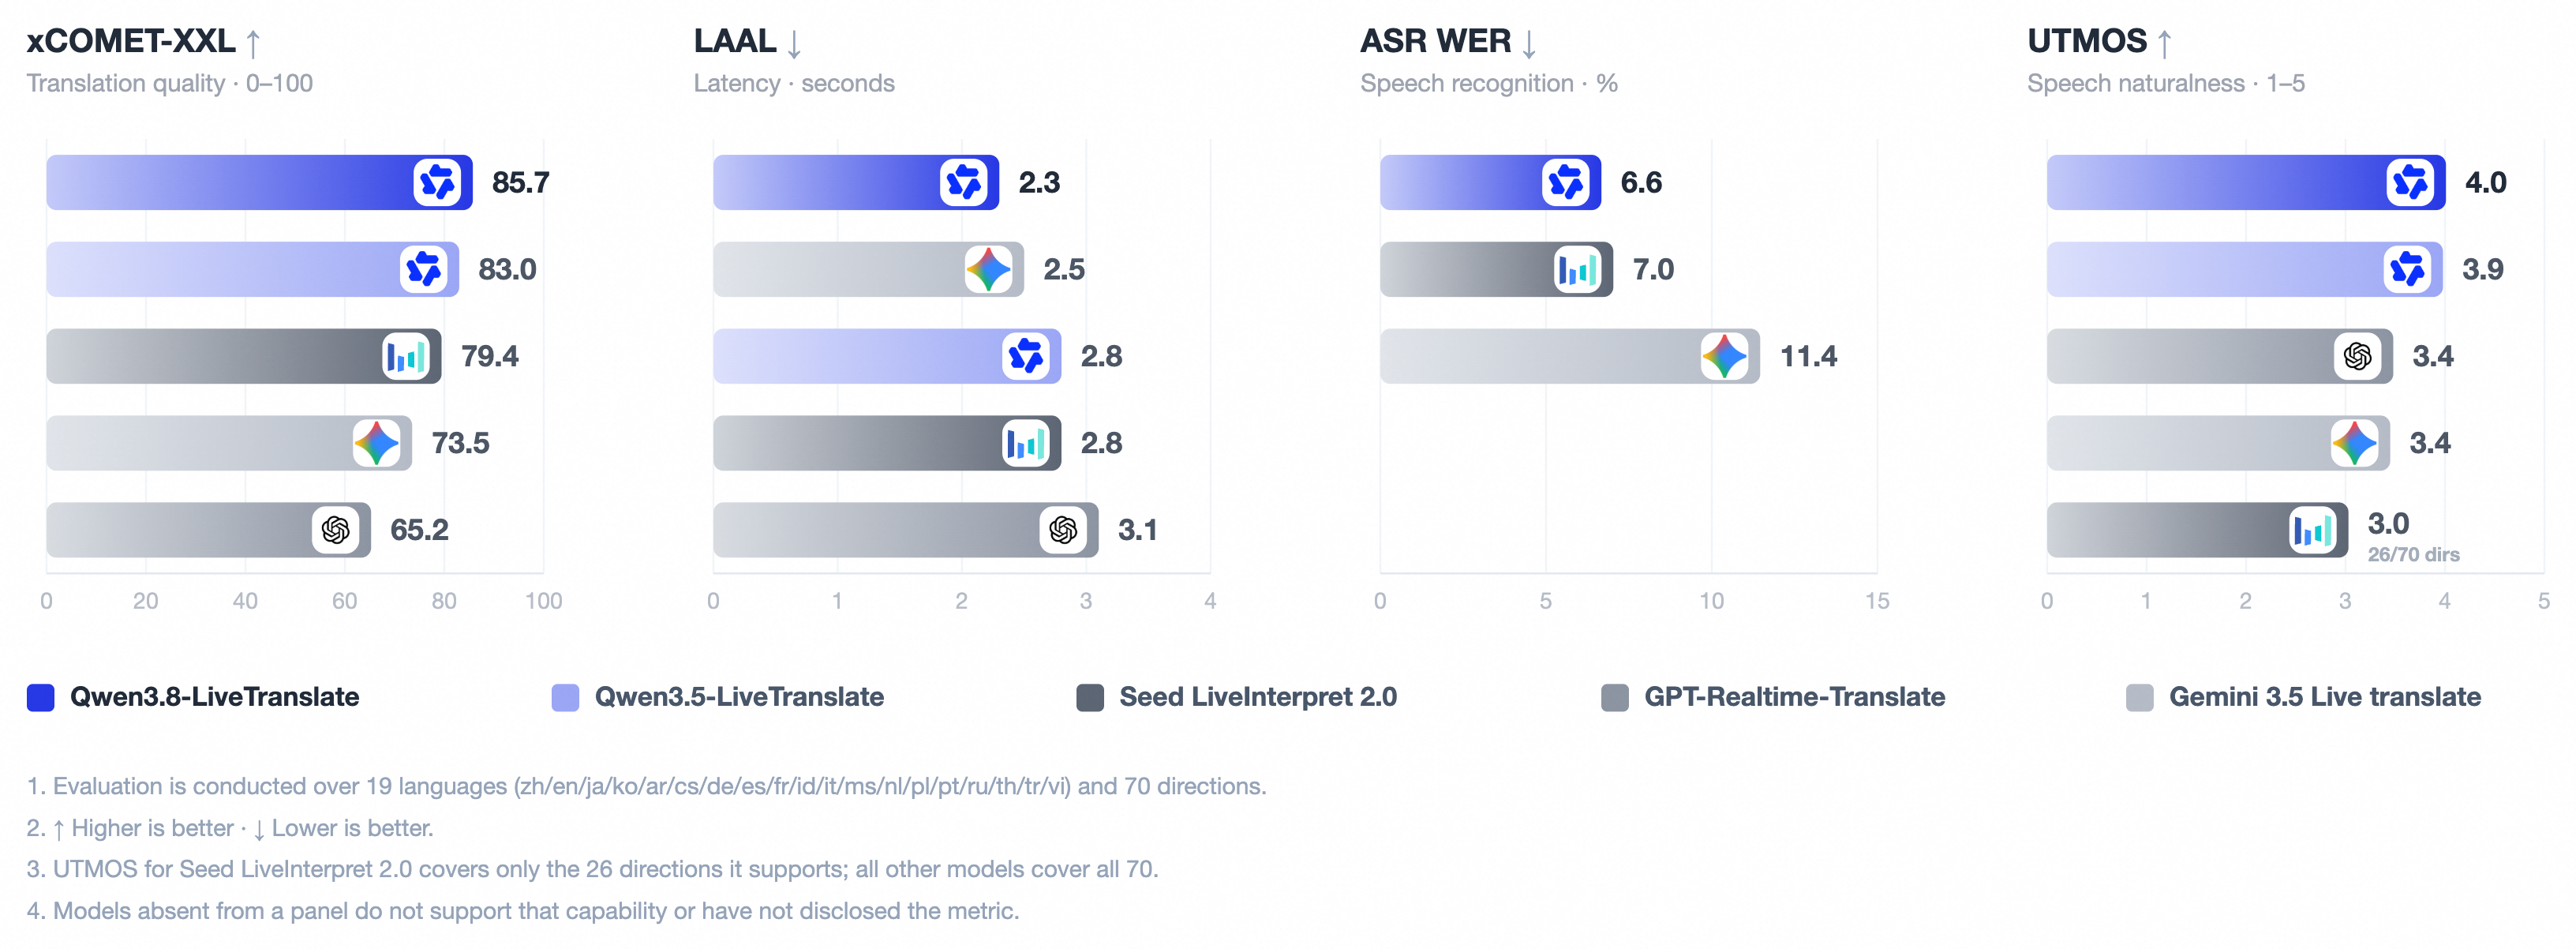
We evaluate real-time interpretation performance across 70 language directions on the public FLEURS audio test set. Qwen3.8-LiveTranslate leads both the previous generation and current mainstream real-time interpretation systems across four dimensions: translation quality, average lagging, speech recognition accuracy, and speech synthesis quality.
🎬 See It in Action#
Using two dialogues from Journey to the West and a set of homophone examples, the demos below showcase speaker attribution and voice cloning, synchronized bilingual output, and how context and visual information help with translation disambiguation.
Supported Languages#
| Category | Supported languages |
|---|---|
| Input audio & output text | 60 languages Chinese, English, German, Italian, Portuguese, Spanish, Japanese, Korean, French, Russian, Thai, Indonesian, Arabic, Vietnamese, Turkish, Finnish, Polish, Hindi, Dutch, Czech, Urdu, Filipino, Swedish, Danish, Hebrew, Icelandic, Malay, Norwegian, Persian, Afrikaans, Asturian, Azerbaijani, Belarusian, Bengali, Bosnian, Bulgarian, Cantonese, Catalan, Cebuano, Croatian, Estonian, Galician, Gujarati, Greek, Hungarian, Javanese, Kannada, Kazakh, Kyrgyz, Latvian, Macedonian, Malayalam, Marathi, Punjabi, Romanian, Slovak, Slovenian, Swahili, Tajik, Ukrainian |
| Output audio | 29 languages Chinese, English, German, Italian, Portuguese, Spanish, Japanese, Korean, French, Russian, Thai, Indonesian, Arabic, Vietnamese, Turkish, Finnish, Polish, Hindi, Dutch, Czech, Urdu, Filipino, Swedish, Danish, Hebrew, Icelandic, Malay, Norwegian, Persian |
Using Qwen3.8-LiveTranslate via DashScope API#
Below is a complete real-time interpretation client example: it captures microphone audio, streams it to the server, and receives and plays back the translation. This generation’s new speaker separation and synchronized source-and-translation output capabilities are both enabled through session configuration; the server returns the speaker identifier and the source-language text alongside the translation, with no need to call a separate ASR interface.
"""Client for the DashScope live-translation service: captures mic audio, sends it to the server, and plays back the translated speech."""
=
=
=
=
= None
# URL for the China (Beijing) region; replace {workspace_id} with your Model Studio workspace ID. URLs differ by region.
=
# Audio input parameters (microphone capture)
= 16000
= 1600
=
= 1
# Audio output parameters (local playback)
= 24000
= 2400
=
= 1
# Runtime state and playback resources
= False
= None
=
=
# Set once the server returns session.finished, so close() can wait for a clean shutdown.
=
"""Open a WebSocket connection to the translation service."""
=
= await
= True
await
= False
"""Configure the translation session: target language, audio formats, and optional features."""
=
await
"""Base64-encode an audio chunk and send it to the server."""
return
=
await
"""Send an image frame to the server as visual context for translation."""
return
=
=
await
"""Background thread task: drain PCM chunks from the playback queue and write them to the speaker output stream."""
=
=
# sentinel: stop the playback loop
break
continue
"""Spin up the background audio playback thread (no-op when audio output is disabled)."""
return
=
"""Continuously receive and dispatch event messages pushed by the server."""
=
=
=
=
== :
=
# Receive source-language ASR results (requires input_audio_transcription.model to be enabled)
# elif event_type == "conversation.item.input_audio_transcription.delta":
# delta = event.get("delta", "") # incremental transcript
# print(f"[Recognizing] {delta}", end="", flush=True)
# elif event_type == "conversation.item.input_audio_transcription.completed":
# transcript = event.get("transcript", "") # final transcript for an utterance
# print(f"[Source] {transcript}")
# In voice + text mode, the incremental translation text arrives alongside synthesized audio
== :
# In text-only mode, the incremental translation arrives via response.text.delta
== :
# The server acknowledges session.finish and completes the shutdown handshake
== :
= False
= False
"""Continuously capture microphone audio and stream it to the server in real time."""
=
= await
await
"""Gracefully close the WebSocket connection and release audio resources."""
# Ask the server to finish the session, then wait for its session.finished acknowledgement.
=
await
await
= False
await
# signal the playback thread to exit
"""Collect runtime parameters from the user via CLI: output mode and target language."""
=
=
=
=
=
=
return ,
"""Program entry point: connect, configure the session, and drive the live-translation loop."""
=
return
=
return
, =
=
# Callback fired as translated text arrives — stream it to stdout, character by character
await
# Launch the audio playback thread (only does real work when audio output is enabled)
# Run two coroutines concurrently: server-message handling + microphone audio upload
=
=
# Microphone capture is the translation input source — required regardless of output mode
=
await
await
Future Directions#
Simultaneous interpretation is far from its final destination. Guided by “hear it more fully, convey it more faithfully, use it more widely,” we are looking toward the following directions:
- Approaching the latency limit of simultaneous interpretation: keep compressing end-to-end latency, pushing the gap between “hearing” and “translating” toward its limit.
- Long-term memory across sessions: carry memory across sessions into the next conversation for the same project and the same group of people, getting better the more it is used.
- Covering more languages: keep extending coverage to more long-tail languages and regional dialects, so real-time interpretation can serve everyone in the world.
Citation#
Feel free to cite the following article if you find Qwen3.8-LiveTranslate helpful: