zml/llmd 20261029.0
Article
Le Chonk.
October 29, 2026 inference / serving / mistral / chonk / glm / lfm
We are pleased to announce the release of zml/llmd 20261029.0. This week, we are bringing more models:
- Mistral Large 4
- GLM 5.2 and GLM 5.3 series
- LFM 3 series
Mistral Large 4 – Le Chonk 
In coordination with Mistral, we are pleased to announce Day 0 support for Mistral Large 4.
Mistral Large 4 Le Chonk (Le Chonk) is a 1-trillion-parameter multimodal model, now available with improved coding, cybersecurity, and reasoning efficiency. It leads open-weight benchmarks in coding and defensive security while offering three reasoning modes for cost-performance balance. Fully open-weight and European-trained, it empowers sovereign AI with customizable, self-hosted deployment options.
The native DSpark Speculative decoding is also supported via the --speculative-drafter-model=native flag.
Decode throughput, mistralai/Mistral-Large-4-1T-A52B, bs=1, 4xGB300 (tok/s)
Sadly, we could not bring it to AMD due to a bug in the amdgpu driver that’s now been fixed but not released. We are actively monitoring the situation.
Even though it should work, we haven’t tested it on Google TPUs because, again, we could not get any.
GLM 5.2 and GLM 5.3#
This release also brings support for the GLM 5.2 and GLM 5.3 series of models.
LFM 3#
This release brings support for the LFM 3 series of models, in all flavours (BF16, FP8 and NVFP4).
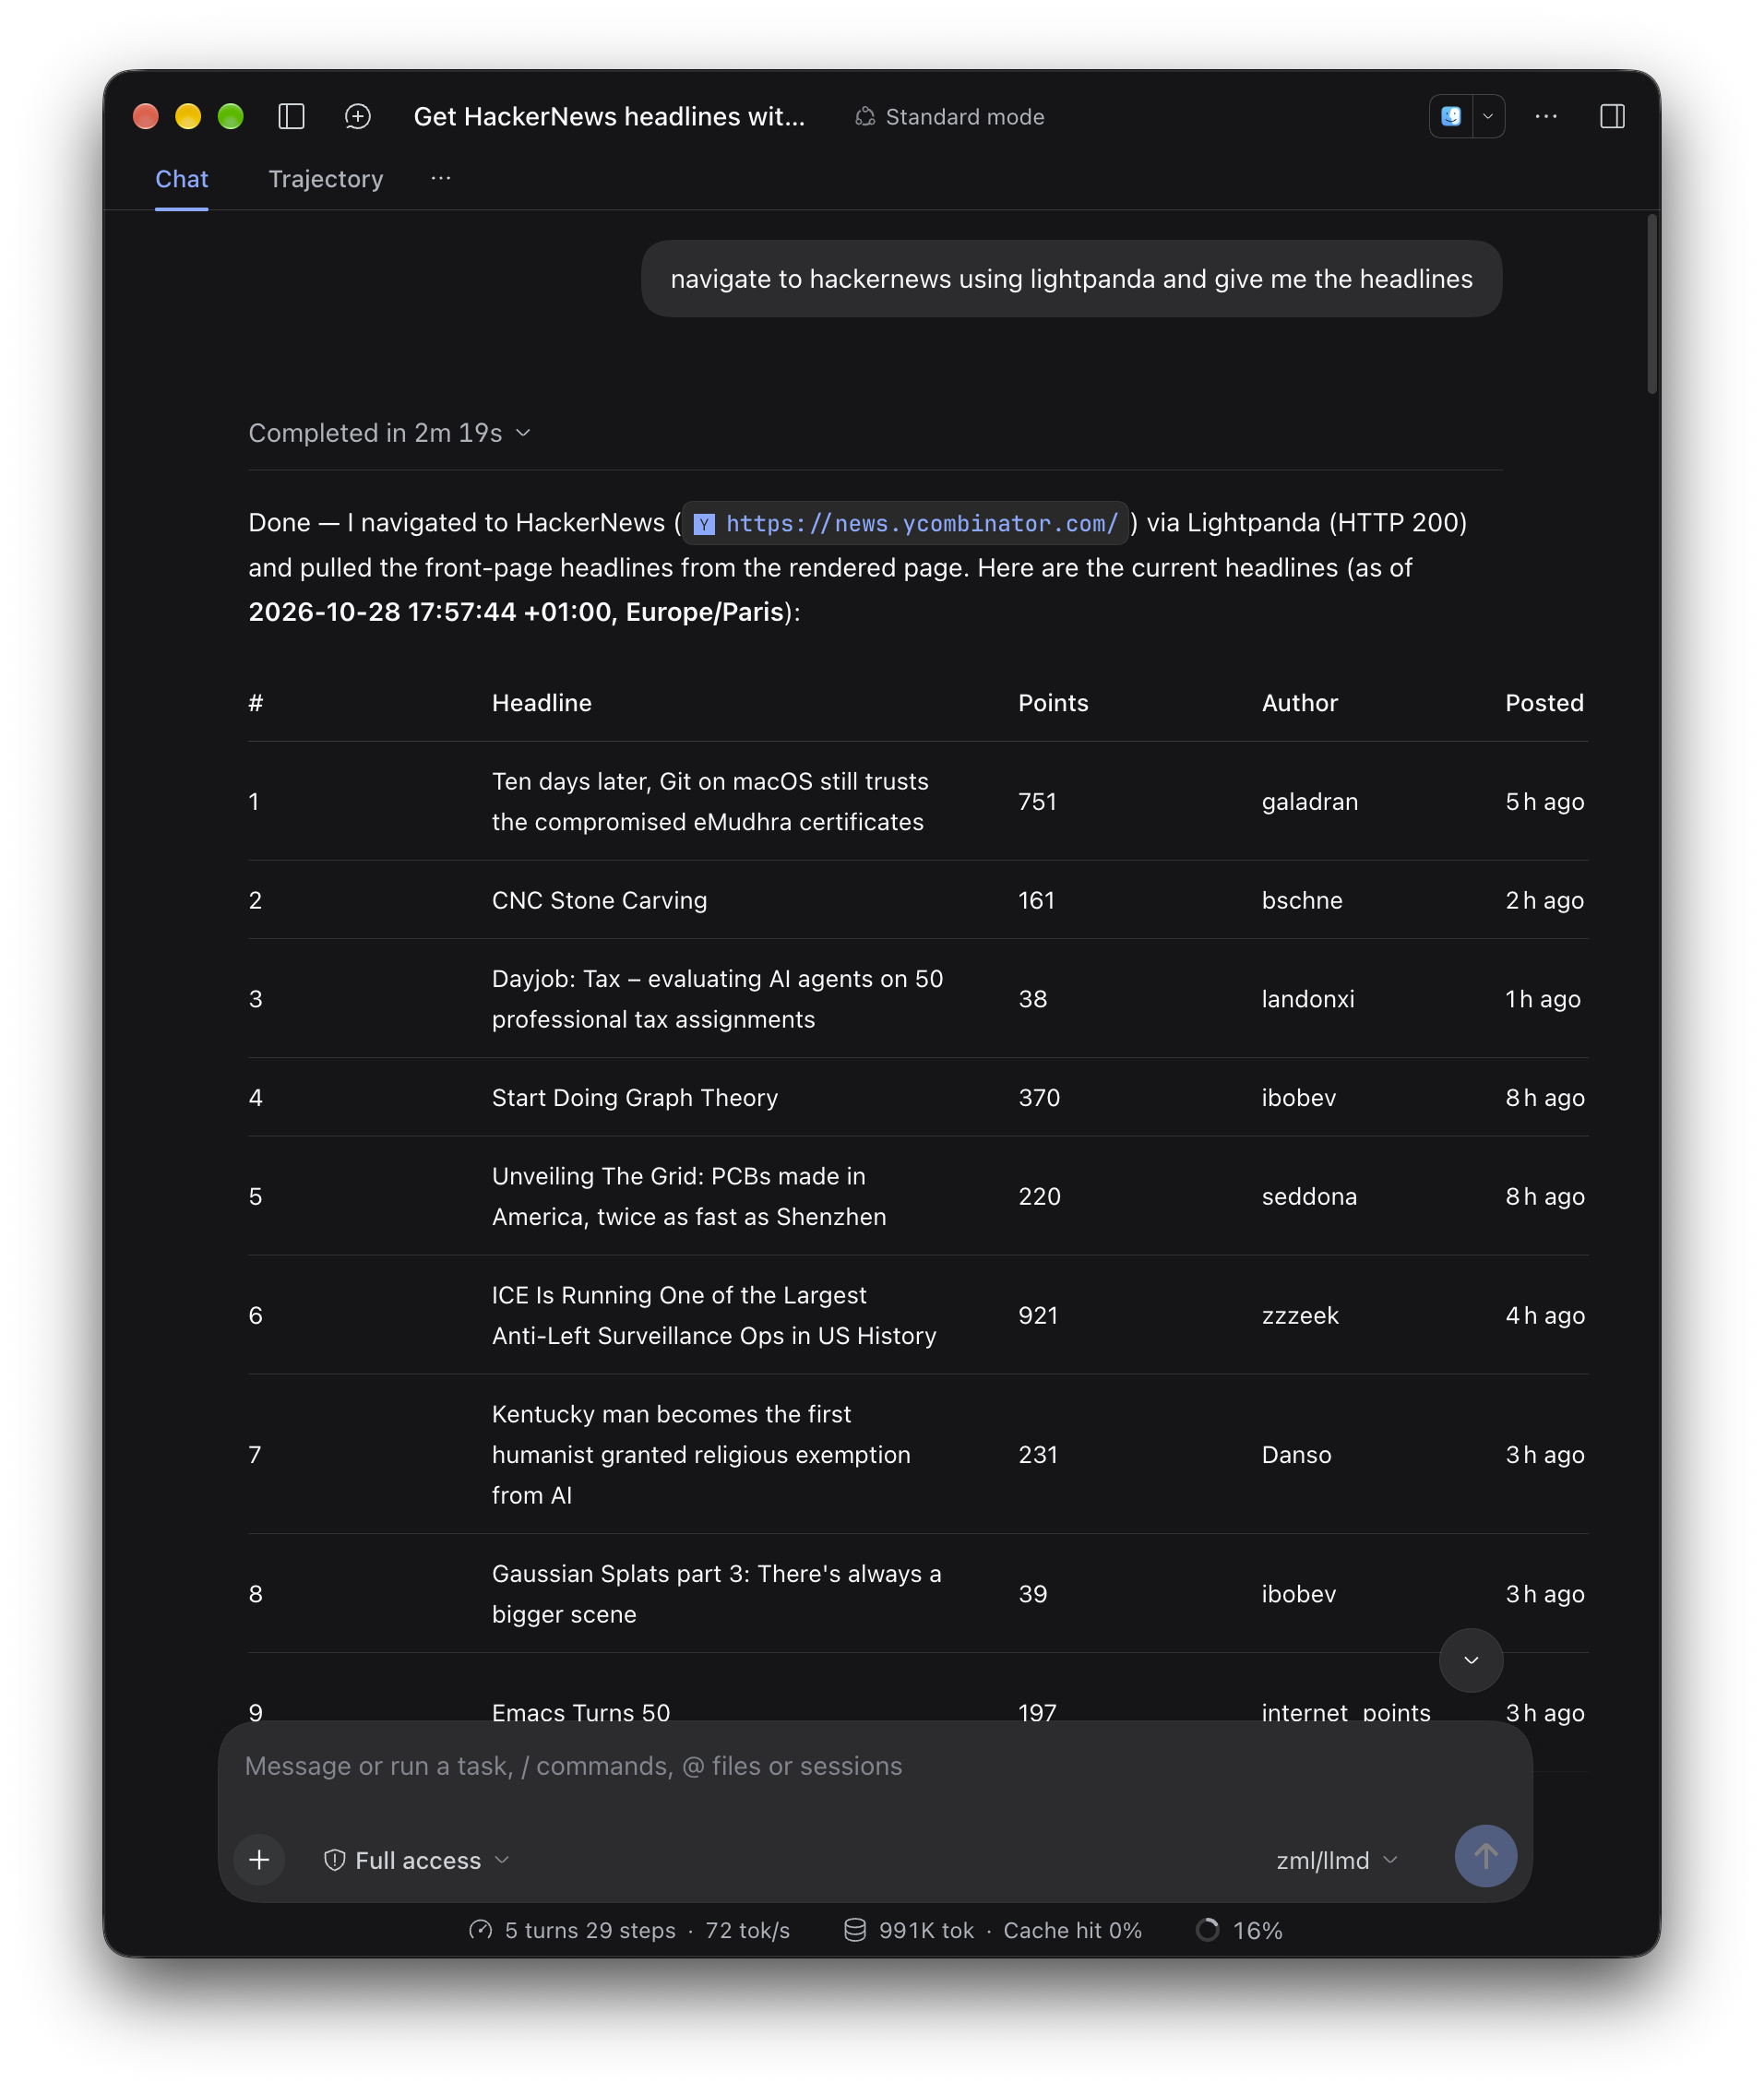
This model is great at agentic tasks and following instructions. Combined with our NVFP4 support on Metal, it makes for a great fully local combination, especially when paired with the Lightpanda MCP:
Decode throughput, LiquidAI/LFM3-1.7B, bs=1, zml/llmd 20261029.0, M3 Max (tok/s)
Try it today#
NVIDIA#
AMD#
Intel#
Google TPU#