ZML/LLMD 20261009.0
Article
Performance is all around me, and so the feeling grows.
October 9, 2026 inference / serving / NVIDIA / AMD / TPU / Metal / Intel
Another week, another release. We’re happy to announce the release of zml/llmd 20261009.0, which brings considerable performance improvements across the board.
Faster Compilation#
In this release, we have spent a considerable amount of effort improving compilation performance. Notably, in configurations with multiple GPUs, autotuning is now done in parallel across GPUs. This has a significant impact on cold-start performance, as shown below.
These changes impact NVIDIA, AMD, Intel and Apple Metal backends.
Cold Start, deepseek-ai/DeepSeek-V4.1-Flash, 4xGB300, less is better
And here is a visual representation of the compilation time improvements (BEFORE / AFTER): 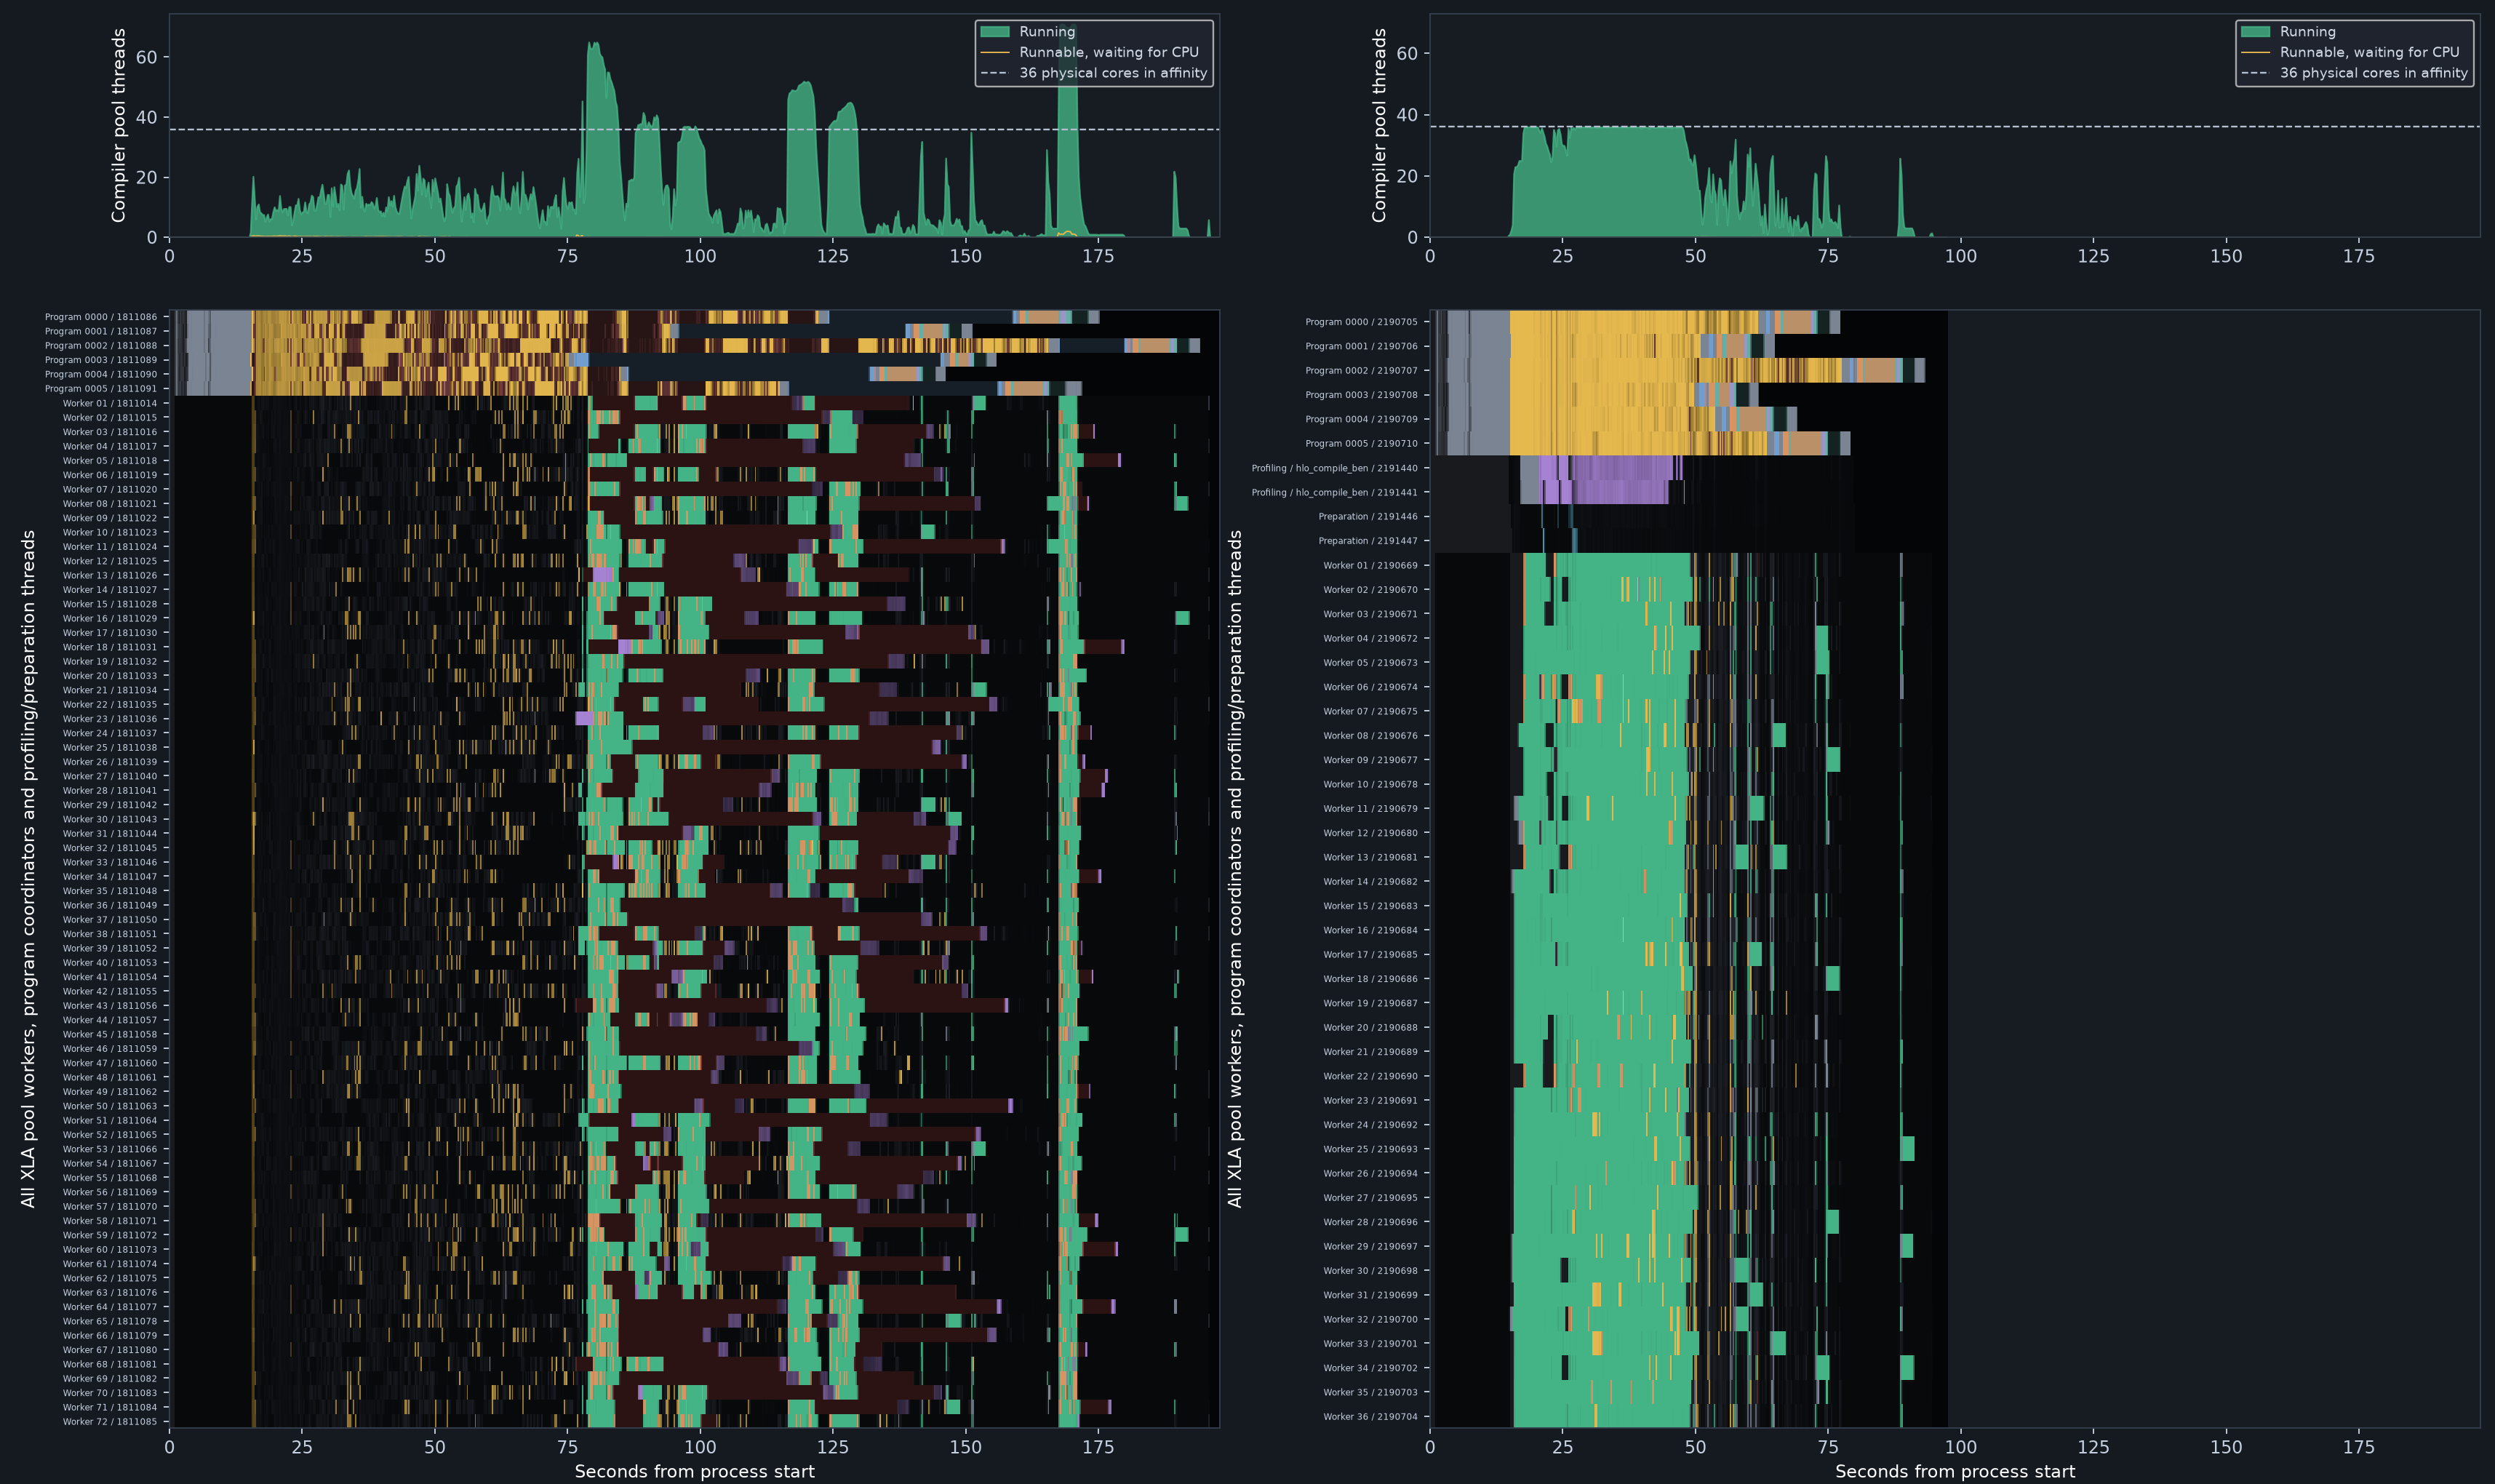
Faster Qwen3.8-27B#
In this release, we have decided to focus on some fundamental performance work and apply it to Qwen/Qwen3.8-27B as a testing ground.
We chose to benchmark it with the ridiculous bs=1024 pure decode path because we found it tends to highlight inefficiencies better.
Token Generation, Qwen/Qwen3.8-27B, w16a16, bs=1024, 4xGB300, more is better
Apple M3 Max, nvidia/Qwen3.8-27B-NVFP4, pp1024/tg128, bs=1, more is better (tg tok/s)
Command lines
zml/llmd#
SGLang#
Faster DeepSeek-V4.1-Flash#
As stated in the previous blog post, we chose to release DeepSeek-V4.1-Flash early, even though we were not yet at the performance level we can achieve. This release brings incremental performance improvements to DeepSeek-V4.1-Flash, as shown below.
Token Generation, deepseek-ai/DeepSeek-V4.1-Flash, bs=1, 4xGB300 (tok/s)
We had missed enabling speculative decoding on Metal in the previous release. This release brings it back, and it works well. DFlash, DFlash2 and DSpark are all supported. If the model natively supports it, you can also pass the --speculative-drafter-model=native flag to enable it.
ZIO is now the default I/O backend#
This release now enables ZIO as the default Zig std.Io backend.
ZIO is an asynchronous runtime for Zig, in the same spirit as Go’s runtime or Tokio: it schedules lightweight coroutines onto a pool of OS threads, and gives you blocking-looking network, file, and process I/O that’s actually backed by non-blocking, event-driven OS APIs under the hood.
Thanks to it, zml/llmd runs on top of kqueue on macOS and epoll or io_uring on Linux (detected at runtime).
ZIO is exactly what we wanted to build ourselves (and had started to prior to std.Io in older zml/zml versions). So a huge shout-out to Lukáš Lalinský. Great job.
The old std.Io.Threaded backend is still available and can be enabled with the --io-impl=threaded flag.
Try it today#
NVIDIA
AMD
Intel
Google TPU
Apple Metal