Qwen3.8-Flash-Next: A New Architecture, Towards Ultimate Cost-Efficiency
HUGGING FACE MODELSCOPE TECH REPORT FLASHQLA DISCORD
Introduction#
In this release we are opening the weights of Qwen3.8-Flash-Next, a multimodal MoE model that also serves as an early preview of the architecture used in Qwen4. It plays the same role that Qwen3-Next played for Qwen3.5: the hybrid Gated DeltaNet + Gated Attention design introduced at that time has since been used across the Qwen3.5, Qwen3.6, Qwen3.7 and Qwen3.8 series. We are again releasing the architectural changes early, so that the community can examine them before the full Qwen4 model family is built on top of them.
Qwen3.8-Flash-Next upgrades the model systematically along four aspects — attention, residual, embedding and optimization — improving model capability while further optimizing computational efficiency, model capacity and training stability:
- Attention: A GDN + QSA hybrid architecture. Gated DeltaNet (GDN) compresses the history efficiently; Qwen Sparse Attention (QSA) uses a compressed lightweight indexer to select the important context at micro-block granularity, substantially reducing the cost of attention on long sequences.
- Residual: Gated Residual (GR) widens the residual stream into 4 branches and controls reads and writes with a dynamic gate, strengthening cross-layer information flow and training stability.
- Embedding: N-gram Embedding looks up a table using the local context to scale model capacity with very little extra computation; the embedding table can be offloaded to host memory and overlapped with model computation through asynchronous prefetching.
- Optimization: The Muon optimizer is used, refined around orthogonalization accuracy, the division of labour between Muon and AdamW, and the splitting of fused parameters, with the scaling law refitted for the new architecture.
Qwen3.8-Flash-Next features a 125B-parameter main model, supplemented by an additional 51B N-gram embeddings, with 6B parameters activated per token. Compared with Qwen3.7-Plus, Qwen3.8-Flash-Next substantially reduces both training and inference cost — training takes only about 1/9 as much, yet it delivers superior capabilities in coding and office tasks.
It natively supports 262,144 tokens of context and is extensible to 1,000,000 tokens with YaRN. For more technical details on the architecture, training methodology, and experimental analysis of Qwen3.8-Flash-Next, please refer to the technical report in our GitHub repository.
Qwen3.8-Flash-Next weights are now available on Hugging Face and ModelScope. The production version, with 1M context by default and official built-in tools, is served as Qwen3.8-Flash on QwenCloud, priced at 0.15 USD per million input tokens and 0.47 USD per million output tokens.
Performance#
Language#
| Qwen3.8-Flash-Next | Qwen3.8-27B | Qwen3.7-Plus | DeepSeek-V4-Flash-0731 | Claude-Opus-4.6 (Max) | |
|---|---|---|---|---|---|
| # Params | 125B | 27B | 397B | 284B | -- |
| # Activated params | 6B | 27B | 17B | 13B | -- |
| # N-gram embedding params | 51B | -- | -- | -- | -- |
| Coding | |||||
| Agentic coding DeepSWE 1.1 | 58.7 | 42.2 | 16.5 | 54.4 | -- |
| Agentic coding SWE-bench Pro | 62.5 | 61.7 | 55.8 | 56.0 | 53.4 |
| Multilingual software engineering SWE-bench Multilingual | 81.0 | 73.8 | 75.8 | -- | 77.5 |
| Repo-level code generation NL2Repo-Bench | 48.1 | 42.3 | 41.1 | 54.2 | 47.6 |
| Agent | |||||
| Long-horizon office work CoWorkBench | 73.9 | 70.7 | 65.1 | 45.1 | 68.2 |
| Professional job tasks JobBench | 55.7 | 33.4 | 27.6 | 41.3 | 36.6 |
| Frontier agentic tasks Agents' Last Exam | Pass@1 24.3 Score 51.2 | Pass@1 20.4 Score 42.9 | Pass@1 13.2 Score 33.6 | Pass@1 25.2 Score -- | -- |
| Real-world tool use Toolathlon Verified (Pass@1) | 73.5 | 67.1 | 50.6 | 70.3 | -- |
| General | |||||
| Instruction following IFBench | 81.3 | 79.5 | 79.1 | 79.2 | 62.5 |
| Scientific reasoning GPQA Diamond | 91.7 | 89.2 | 90.3 | 90.8 | 91.3 |
| Multidisciplinary reasoning HLE | 35.9 | 30.8 | 34.7 | 33.8 | 40.0 |
| Competitive coding LiveCodeBench v6 | 91.9 | 90.3 | 89.6 | 90.6 | 88.8 |
1. DeepSWE 1.1: evaluated with the Claude Code and mini-SWE-agent harnesses, temp=1.0, top_p=0.95, 256K context window. We report the highest score across the two harnesses; notably, Qwen3.8-Flash-Next performs best on mini-SWE-agent.
2. SWE-bench Pro: except for Claude-Opus-4.6 (Max), for which we report the officially published score, all models are evaluated with the Claude Code harness, temp=1.0, top_p=0.95, 256K context window. Problematic tasks were corrected and all baseline models were re-evaluated on the refined benchmark.
3. SWE-bench Multilingual: evaluated with the mini-SWE-agent harness, temp=1.0, top_p=0.95, 256K context window.
4. NL2Repo-Bench: evaluated with the Claude Code harness. To prevent reward hacking, we disable Bash commands that attempt to access the specific repository, such as pip download, pip install and git clone.
5. CoWorkBench: an in-house cowork benchmark for evaluating long-horizon office and productivity agent tasks across computer science, finance, law, medical and other productivity domains.
6. HLE: judged by GPT-4o.
7. The best result in each row is shown in bold.
8. Empty cells (--): scores are not yet available or are not applicable.
Vision Language#
| Qwen3.8-Flash-Next | Qwen3.8-27B | Qwen3.7-Plus | Claude-Opus-4.6 (Max) | |
|---|---|---|---|---|
| Agentic Multimodal Intelligence | ||||
| Multimodal tool use ClawEval-MM | Pass@3 64.4 Average 60.4 | Pass@3 57.4 Average 56.9 | Pass@3 57.4 Average 60.1 | Pass@3 52.5 Average 54.7 |
| Application recreation RecreationBench | 49.9 | 47.1 | 30.2 | -- |
| Mobile use AndroidWorld | 84.5 | 81.9 | 81.0 | 62.0 |
| Computer use OSWorld 2.0 | Binary 19.4 Partial 52.3 | Binary 19.4 Partial 48.0 | Binary 2.8 Partial 21.5 | -- |
| Visual web development Vision2Web | 64.0 | 62.9 | 42.1 | -- |
| General Multimodal Intelligence | ||||
| Embodied intelligence ERQA | 72.3 | 65.5 | 69.8 | 40.8 |
| Long video understanding LVBench | 76.6 | 72.4 | 76.2 | 63.0 |
| Real-world perception RealWorldQA | 88.5 | 85.9 | 86.9 | 73.9 |
| Visual math problem solving MathVision | Without CI 90.6 With CI 95.7 | Without CI 90.0 With CI 94.6 | Without CI 90.3 With CI 88.7 | Without CI 65.5 |
| Scientific chart analysis CharXiv (RQ) | Without CI 84.6 With CI 90.6 | Without CI 83.7 With CI 90.2 | Without CI 85.8 With CI 85.9 | Without CI 66.0 |
1. ClawEval-MM: scores are reported as "pass@3 / average score". Pass@3 measures the percentage passed in at least one of three trials, and the average score is the mean score across the three trials.
2. RecreationBench: an in-house long-horizon application-recreation benchmark for evaluating hybrid-agent abilities spanning five platforms — desktop (Ubuntu, macOS, Windows), mobile (Android) and web.
3. OSWorld 2.0: scores are reported as "binary / partial". The binary score is the percentage of tasks that receive the full task reward, while the partial score aggregates the partial rewards obtained across all tasks.
4. Vision2Web: scores are reported as the average over the frontend, webpage and website categories, using the Claude Code harness and judged by gpt-5.4-2026-03-05.
5. MathVision, CharXiv (RQ): scores are reported as "without CI / with CI". A small number of incorrect ground-truth annotations in MathVision were corrected after manual verification. Our model's score is evaluated using a fixed prompt, e.g. "Please reason step by step, and put your final answer within \boxed{}." For other models, we report the higher score between runs with and without the \boxed{} formatting.
6. The best result in each row is shown in bold.
7. Empty cells (--) indicate scores not yet available or not applicable.
Model Architecture#
Attention: GDN + QSA for Efficient Memory and Precise Retrieval#
Traditional Full Attention provides direct access to all previous tokens, but as the context grows longer, both computation and KV Cache memory-access costs increase substantially.
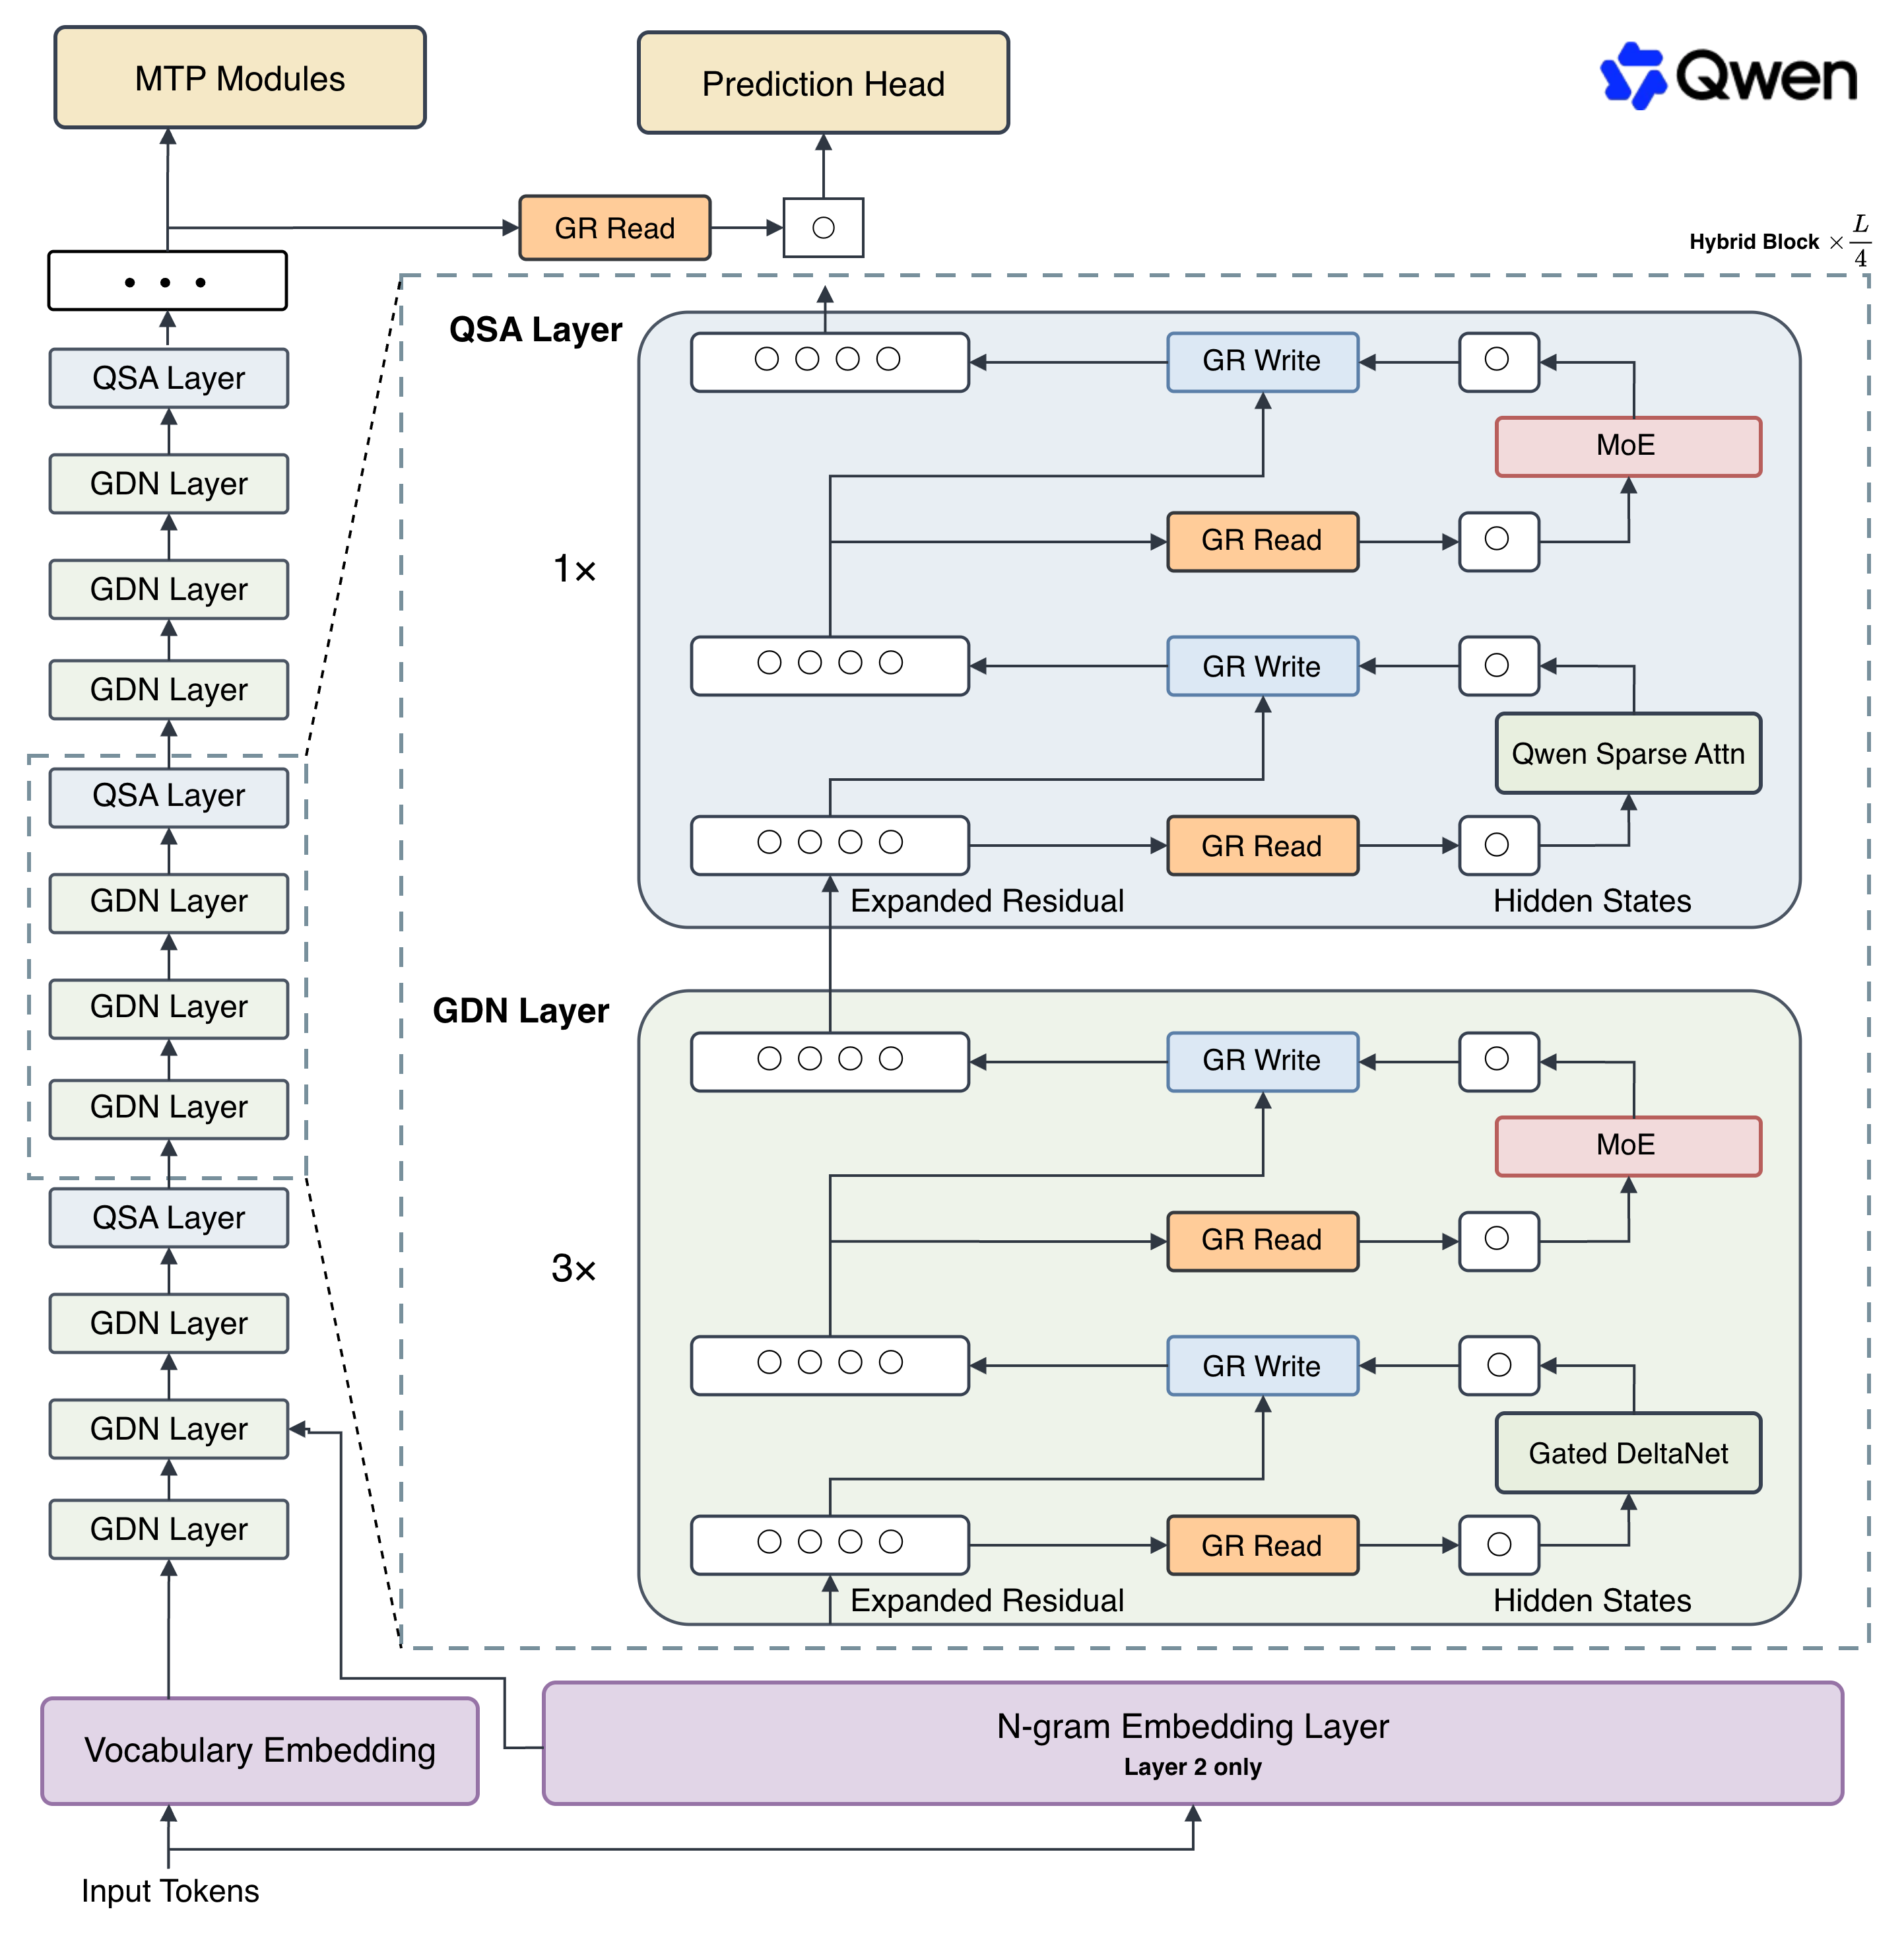
Following the architecture design introduced in Qwen3.5, Qwen3.8-Flash-Next adopts a GDN [1] + Attention Hybrid architecture: three out of every four layers use Gated DeltaNet (GDN) to continuously compress historical information into a fixed-size state, while the remaining layer uses global Attention for precise retrieval of information across the full context.
For global Attention, we further introduce Qwen Sparse Attention (QSA). Sparse Attention reduces long-sequence computation by attending only to important context. However, existing approaches such as DSA [2] still rely on a token-level indexer to identify important positions; as the context grows, the indexer itself becomes a non-negligible source of computation.
QSA further compresses this process: a lightweight indexer first aggregates the sequence into micro-blocks, estimates context importance at the block level, and then selects the most relevant regions for Attention. This reduces not only the cost of Attention itself, but also the indexing overhead required to identify important context. Compared with approaches that share indices across layers [3], QSA performs sequence compression independently within each layer, reducing its dependence on cross-layer Attention similarity and making it particularly well suited to Hybrid architectures where GDN and Attention layers are interleaved.
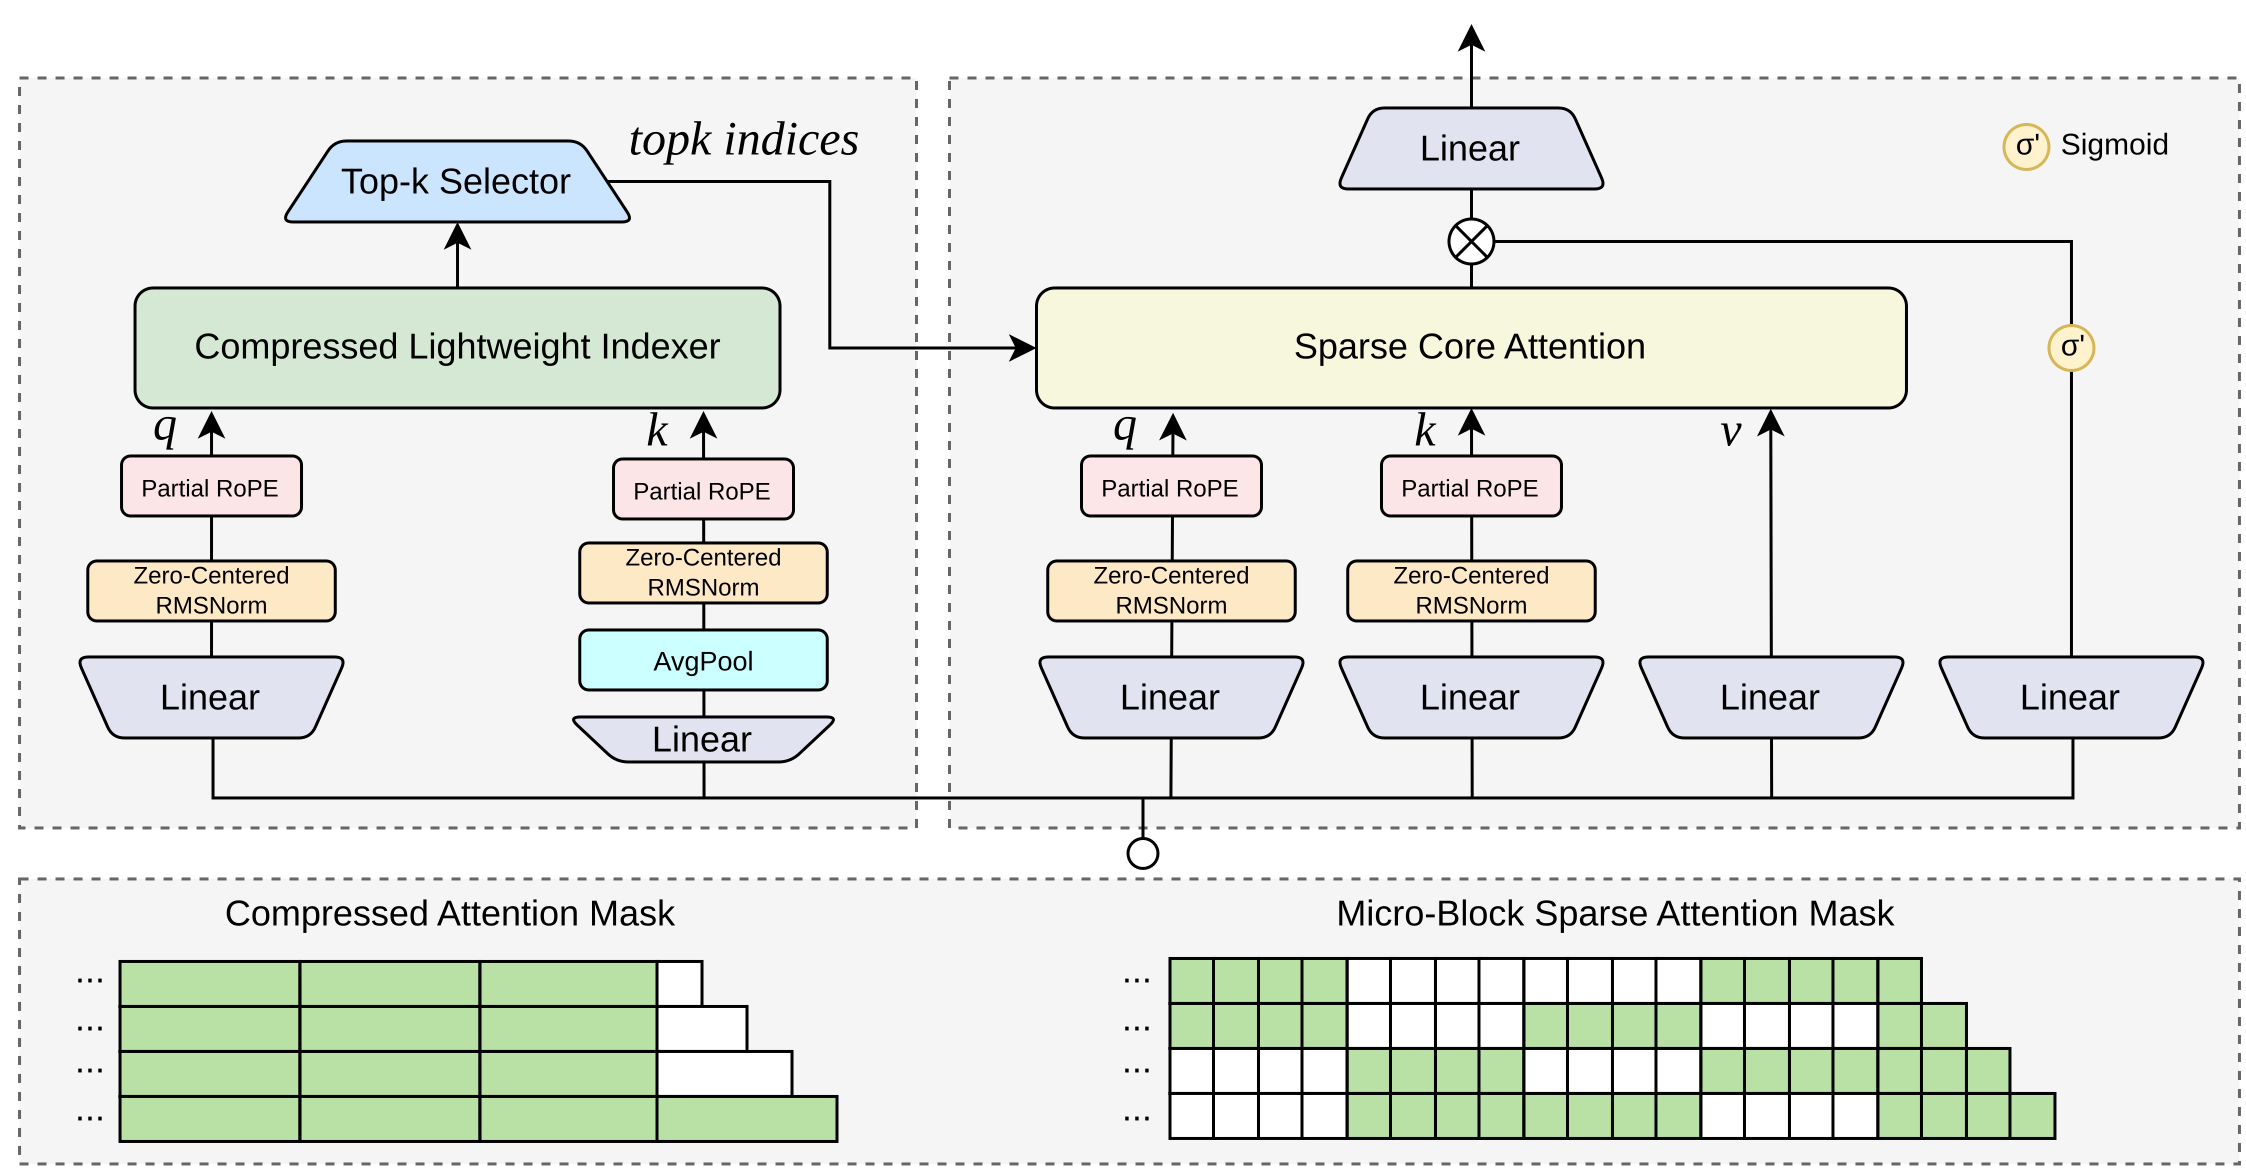
Put simply: GDN efficiently “remembers,” while QSA precisely “retrieves.”
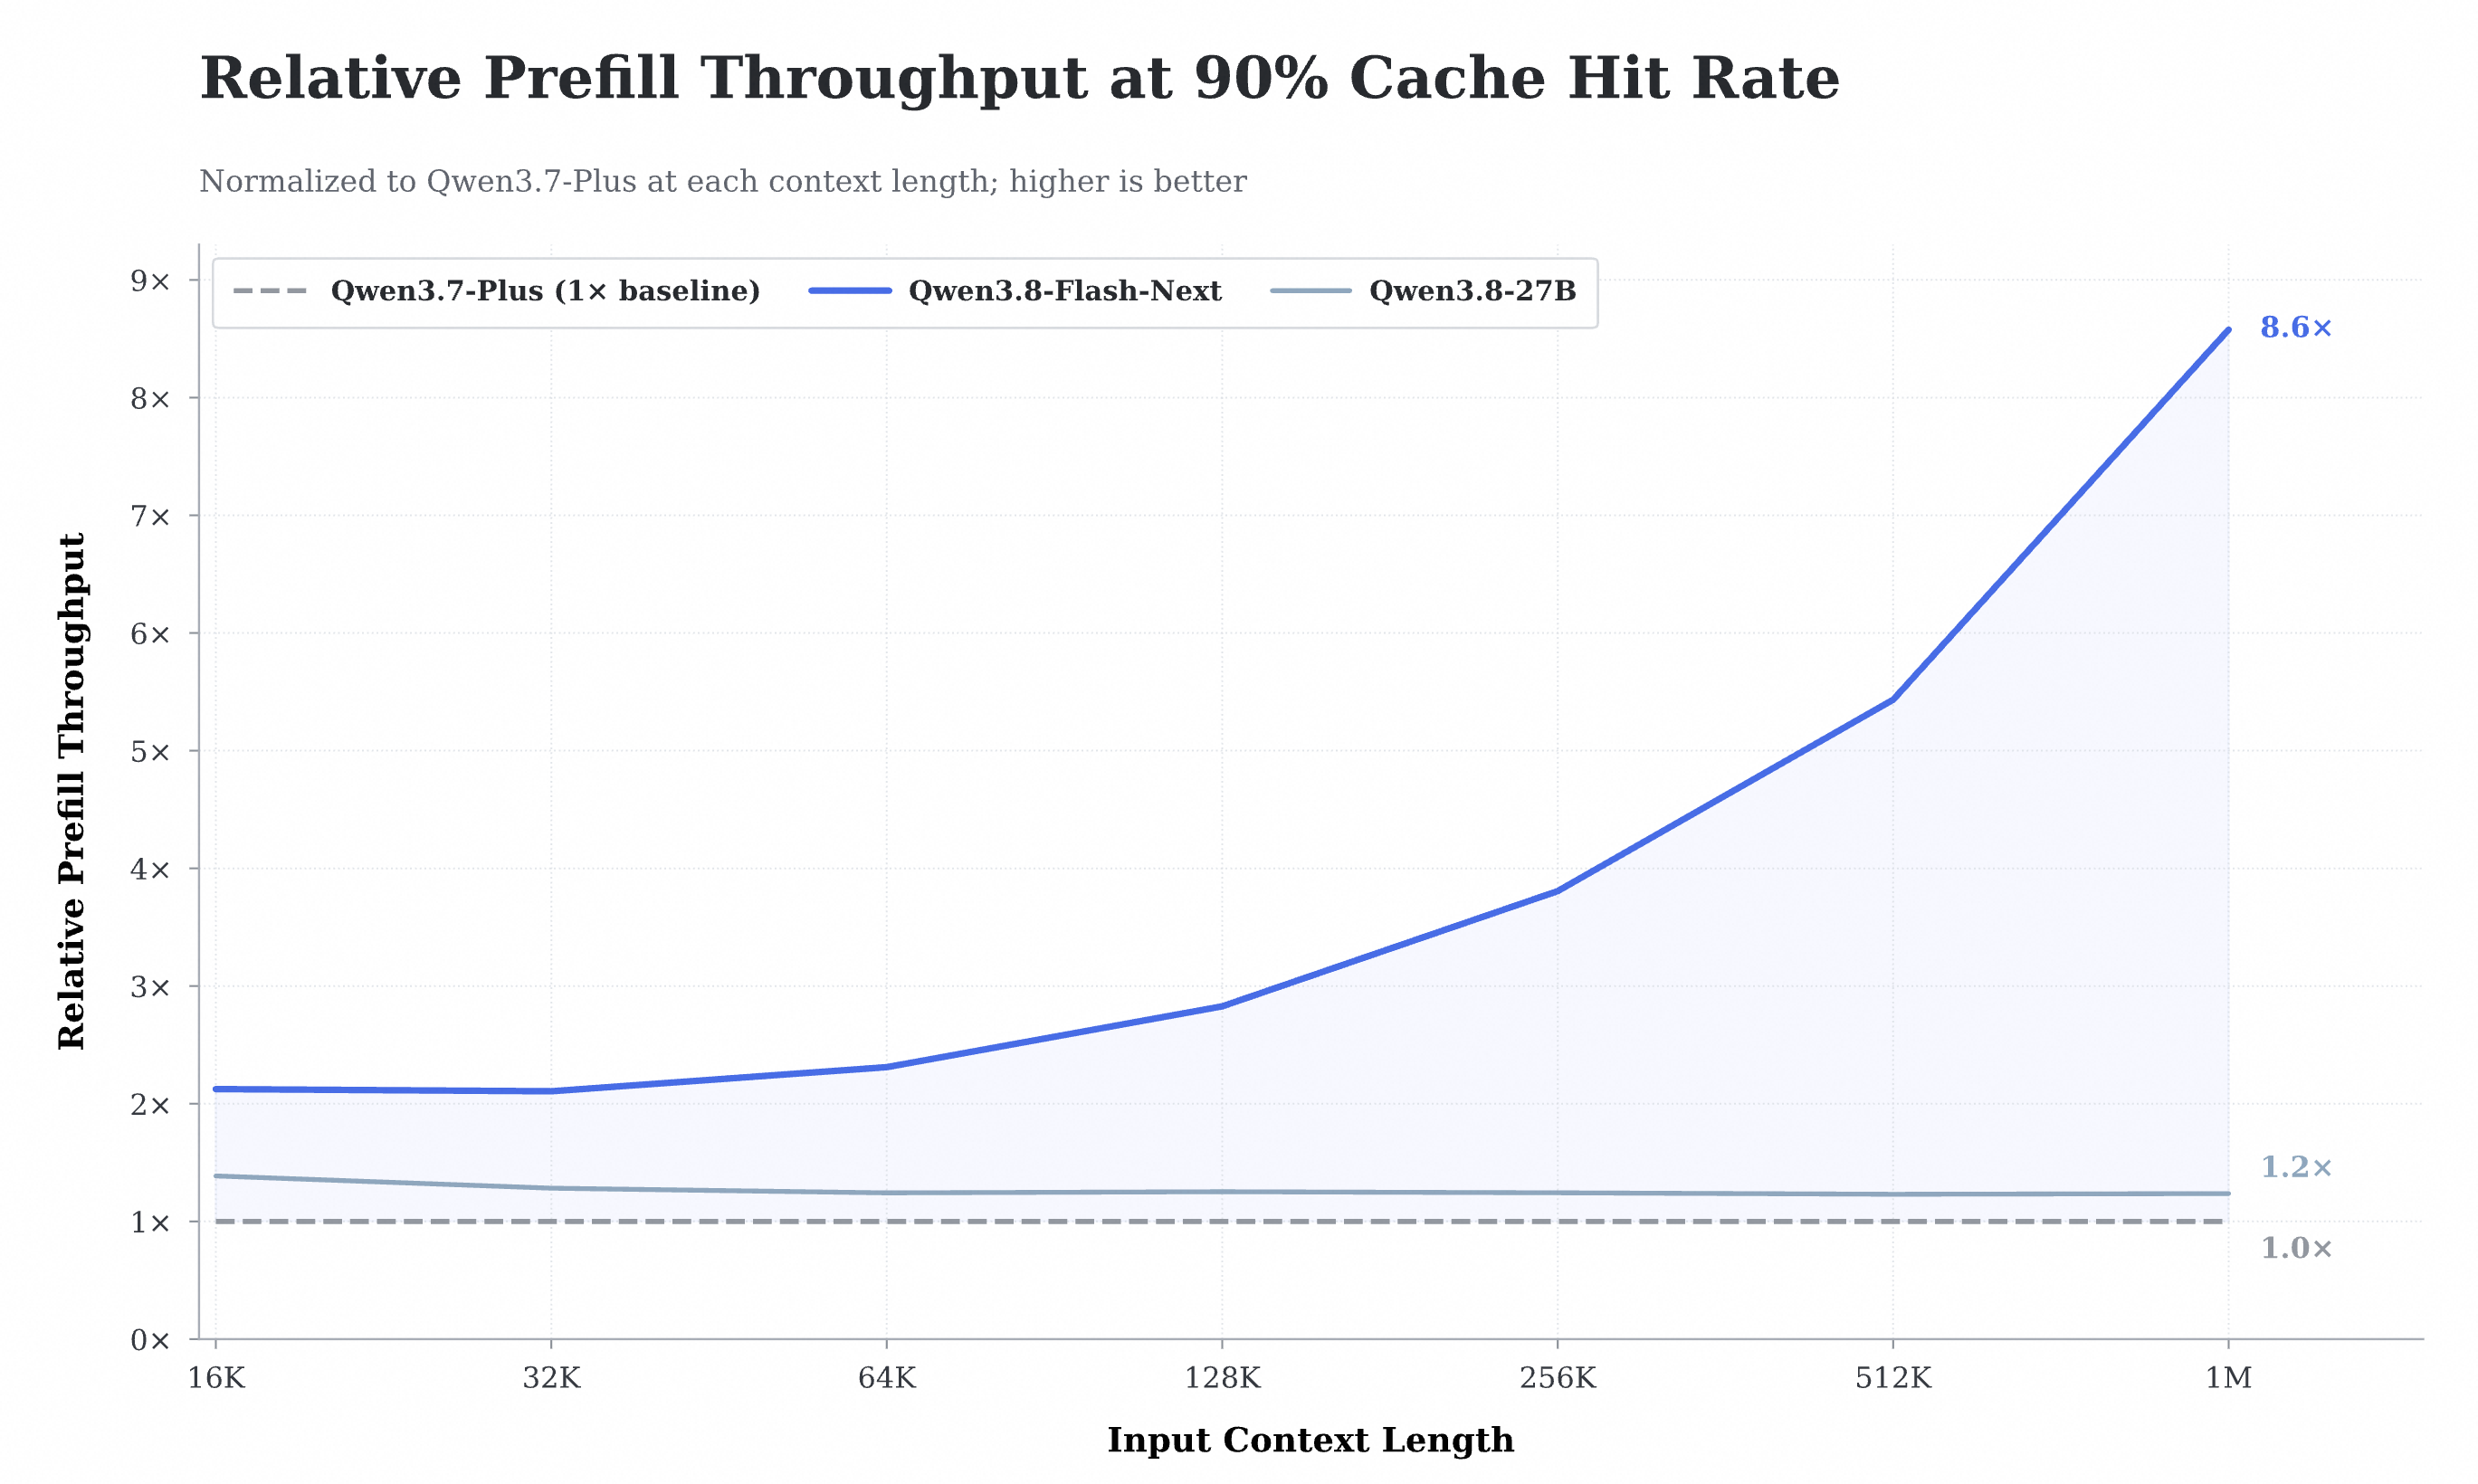
At 1M tokens, QSA’s Attention Kernel achieves up to 7.6× and 4.9× speedups in Prefill and Decode, respectively. In an experimental setup representative of online serving scenarios with high cache reuse (a 90% Prefix Cache hit rate), Qwen3.8-Flash-Next achieves 8.6× the Prefill throughput of Qwen3.7-Plus at a 1M-token context length.
Gated Residual: More Paths for Information Flow#
In a traditional Transformer, all layers continuously read from and write to the same Residual Stream. As the network becomes deeper, early features are repeatedly mixed with later information, making important signals more likely to be gradually diluted.
Gated Residual (GR) can be viewed as a combination of two ideas: it follows Hyper-Connection [4] in widening the residual stream into multiple branches, while incorporating the element-wise dynamic gating of GatedNorm [5] into the residual read. The original single residual stream is expanded into four parallel branches, allowing the model to dynamically determine how much information to read from each branch and how much to write back to each branch based on the current content.
This can be conceptualized as expanding a single information channel into multiple parallel pathways: some branches handle local information flow, while others preserve early information directly deep into the network layers. Empirical analysis also reveals that one of these branches naturally emerges as a long-range pathway connecting the first Attention layer to most of the middle and subsequent layers.
GR also further simplifies Hyper-Connection. Once the read and write operations are expressive enough, additional branch mixing yields no significant benefits and can thus be directly removed, thereby reducing memory access overhead and sources of instability. The Gate also effectively suppresses activation outliers and improves training stability. In addition, the Residual State supports FP8 storage, further reducing memory-access overhead.
N-gram Embedding: Expanding Model Capacity at Low Cost#
Inspired by Per-Layer Embedding in Gemma 3n and works such as DeepSeek Engram [6], we further introduce N-gram Embedding to scale model capacity beyond the parameters of the Transformer backbone.
A standard Embedding performs a lookup based on a single token. N-gram Embedding instead performs lookups using the local context formed by the current token and several preceding tokens, providing additional representations for common phrases and local patterns.
Its key advantage is that it can add a large number of parameters with almost no additional computation per token.
Qwen3.8-Flash-Next introduces an additional 51B N-gram Embedding parameters. Because lookup locations can be determined in advance, these parameters can be stored in Host Memory and asynchronously prefetched in parallel with model computation, without permanently occupying GPU memory.
The final model uses only a single N-gram Embedding layer near the beginning of the network, effectively adding a large-scale “local-pattern memory” at relatively low additional cost.
Optimization: Co-designing Architecture and Optimization#
Qwen3.8-Flash-Next is trained with the Muon Optimizer [7], with further improvements around three key aspects of applying Muon to large-scale model training: orthogonalization accuracy, parameter assignment between Muon and AdamW, and splitting fused parameter matrices.
For parameters that genuinely act as two-dimensional linear maps, such as the main weights in Attention, GDN, and MoE Experts, we use Muon. Embeddings, the MoE Router, and the low-rank parameters in GR continue to use AdamW. For QKV, SwiGLU, and GDN projections that are fused in the implementation, we first split them according to the independent linear transformations they represent, and then perform orthogonalization separately.
For the new architecture and Optimizer, we refit the Scaling Law. The results show that the model can stably use larger Learning Rates and Batch Sizes, further improving convergence efficiency and large-scale parallel training throughput.
We also find that Batch Size Warmup, a common practice in large-scale model training, is no longer necessary: gradually increasing from a small Batch to the target Batch does not improve the final result, but instead requires 18.8% more optimizer steps. In the final training Recipe, we therefore start directly with the target Batch Size.
Other Architecture Optimizations#
The remaining components follow the design established in Qwen3-Next and refined through the Qwen3.5–Qwen3.8 series.
- Ultra-sparse MoE: With global load balancing [8], increasing total expert parameters while keeping the number of activated experts fixed steadily reduces training loss. Qwen3.8-Flash-Next therefore uses a large expert pool with a small number of routed experts per token, together with one shared expert.
- Multi-Token Prediction: The MTP module is trained with multiple steps, maintaining consistency between training and inference and thereby improving the acceptance rate of speculative decoding in real scenarios, while also enhancing the performance of the backbone. Its full-attention layers are replaced with QSA as well.
- Training stability: Zero-centered RMSNorm with weight decay applied to norm weights, the attention output gating mechanism [9], and normalized MoE router initialization are retained. These designs make small-scale ablations more reliable and help large-scale training run smoothly.
Base Model Performance#
We compare Qwen3.8-Flash-Next-Base with the base models of Qwen3.8-27B and Qwen3.7-Plus.
| Qwen3.8-Flash-Next-Base | Qwen3.8-27B-Base | Qwen3.7-Plus-Base | |
|---|---|---|---|
| # Params | 125B | 27B | 397B |
| # Activated params | 6B | 27B | 17B |
| # N-gram embedding params | 51B | -- | -- |
| General tasks | |||
| MMLU | 90.36 | 87.51 | 90.43 |
| MMLU-Redux | 90.68 | 87.26 | 91.47 |
| MMLU-Pro | 73.23 | 68.60 | 70.90 |
| SuperGPQA | 51.36 | 44.86 | 48.42 |
| BBH | 90.87 | 89.56 | 89.41 |
| Math & STEM tasks | |||
| GPQA | 51.42 | 45.01 | 51.52 |
| GSM8K | 93.29 | 93.18 | 92.95 |
| MATH | 72.78 | 60.54 | 74.38 |
| Coding tasks | |||
| EvalPlus | 78.76 | 76.05 | 78.06 |
| MultiPL-E | 79.09 | 74.50 | 81.68 |
| SWEBench-Pretrain | 50.99 | 41.66 | 49.24 |
| Multilingual tasks | |||
| MGSM | 89.33 | 86.37 | 85.42 |
| MMMLU | 84.86 | 79.74 | 84.53 |
| INCLUDE | 78.40 | 74.37 | 78.90 |
1. The best result in each row is shown in bold.
2. Empty cells (--): scores are not yet available or not applicable.
With 6B activated parameters, Qwen3.8-Flash-Next-Base achieves the best result on 8 of the 14 benchmarks, including MMLU-Pro, SuperGPQA, BBH, GSM8K, EvalPlus, SWEBench-Pretrain, MGSM and MMMLU, and remains close to Qwen3.7-Plus-Base on MMLU, MMLU-Redux, GPQA, MATH and MultiPL-E. The 51B N-gram embedding parameters are deterministically addressed and do not enter the per-token matrix-multiplication budget.
Develop with Qwen3.8-Flash-Next#
Qwen3.8-Flash-Next is available as an open-weight model on HuggingFace and ModelScope, with official managed APIs on QwenCloud. Designed to balance capability, latency, and cost, it is well suited for high-volume applications, tool-driven workflows, and coding & coworking assistants. In the following, you can explore how to call the QwenCloud API and integrate Qwen3.8-Flash-Next into agentic systems and coding assistants.
API Usage#
Qwen3.8-Flash-Next is available via API:
QwenCloud#
On QwenCloud, the model is served under the name qwen3.8-flash. QwenCloud supports industry-standard protocols, including OpenAI-compatible Chat Completions and Responses APIs, alongside an Anthropic-compatible interface.
"""
Environment variables:
DASHSCOPE_API_KEY: Your API Key from https://home.qwencloud.com/
DASHSCOPE_BASE_URL: (optional) Base URL for compatible-mode API.
- Beijing: https://dashscope.aliyuncs.com/compatible-mode/v1
- Singapore: https://dashscope-intl.aliyuncs.com/compatible-mode/v1
- US (Virginia): https://dashscope-us.aliyuncs.com/compatible-mode/v1
"""
=
=
=
=
=
=
= False
continue
= .
+=
= True
+=
Agent Frameworks & Coding Assistants#
Qwen3.8-Flash-Next integrates seamlessly with popular agent frameworks and coding assistants:
QwenWork#
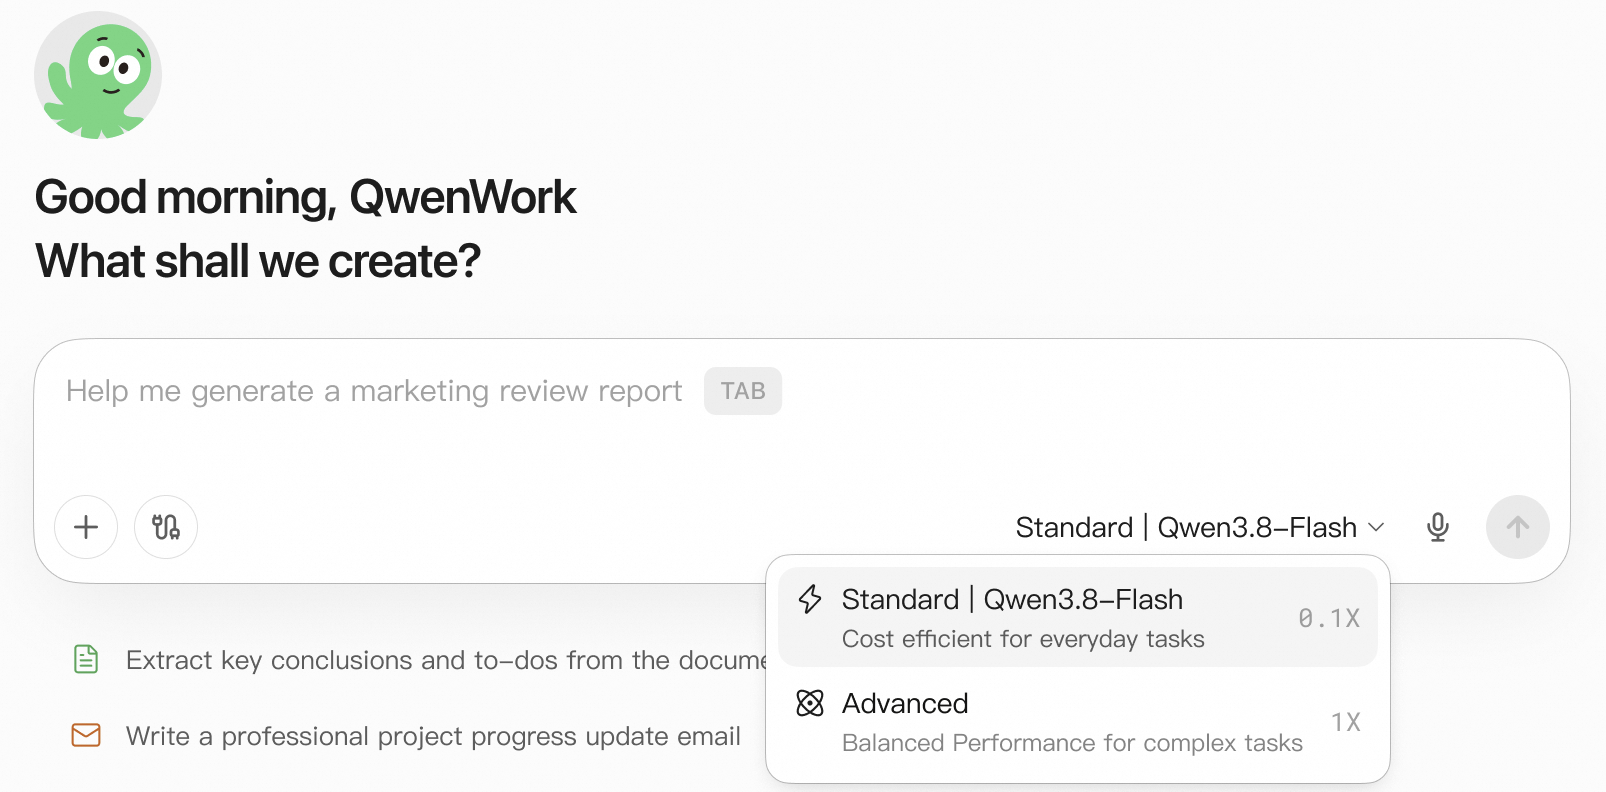
QwenWork is Alibaba’s flagship AI productivity platform, designed to help individuals and enterprises automate daily tasks and accelerate operational efficiency.
We are excited to share that QwenWork has integrated Qwen3.8-Flash-Next to power its newly launched “Standard” mode, leveraging the model’s cutting-edge capabilities to deliver a seamless, cost-effective experience that sets a new standard for AI agents in the workplace.
Learn more in the official documentation!
Claude Code#
Qwen APIs support the Anthropic API protocol, enabling direct use with Claude Code:
Codex#
Qwen APIs support the OpenAI Responses protocol, enabling use with Codex:
In ~/.codex/model-catalog.local.json
In ~/.codex/config.toml
model_catalog_json = "~/.codex/model-catalog.local.json"

model_provider = "QwenCloud"
model = "qwen3.8-flash"

[model_providers.QwenCloud]
name = "QwenCloud"
base_url = "https://dashscope-intl.aliyuncs.com/compatible-mode/v1"
env_key = "OPENAI_API_KEY"
wire_api = "responses"
Qoder CLI#
Qoder co-evolves with Qwen for agentic coding:
|
Qwen Code#
Qwen Code is deeply optimized for the Qwen series:
OpenClaw#
Connect to OpenClaw via QwenCloud:
|
Configure ~/.openclaw/openclaw.json:
Summary#
Qwen3.8-Flash-Next extends the hybrid architecture introduced in Qwen3-Next along four directions: attention, residual, embedding and optimization. QSA compresses the sequence into micro-blocks within each layer, reducing both the attention cost and the indexing cost at long context while keeping precise retrieval. Gated Residual widens the residual stream into several parallel branches and controls reads and writes with an elementwise, data-dependent gate, improving cross-layer information flow and training stability at negligible arithmetic cost; the residual state can additionally be kept in FP8, which further reduces memory traffic. N-gram embedding scales capacity through deterministically addressed lookup memory, which can be scaled with negligible per-token computation and offloaded to host memory. On the optimization side, Muon is used as the main optimizer, with orthogonalization accuracy, parameter assignment and fused-matrix splitting as the decisive implementation choices, and the scaling law refitted for the new architecture.
We release these weights early so that the architecture can be evaluated independently by the community, as we did with Qwen3-Next, and we will continue to refine it towards Qwen4.
Citation#
References#
[1] Gated Delta Networks: Improving Mamba2 with Delta Rule
[2] DeepSeek-V3.2: Pushing the Frontier of Open Large Language Models
[3] IndexCache: Accelerating Sparse Attention via Cross-Layer Index Reuse
[4] Hyper-Connections
[5] A Unified View of Attention and Residual Sinks: Outlier-Driven Rescaling is Essential for Transformer Training
[6] Conditional Memory via Scalable Lookup: A New Axis of Sparsity for Large Language Models
[7] Muon: An Optimizer for Hidden Layers in Neural Networks
[8] Demons in the Detail: On Implementing Load Balancing Loss for Training Specialized Mixture-of-Expert Models
[9] Gated Attention for Large Language Models: Non-linearity, Sparsity, and Attention-Sink-Free