Qwen-Scope: Decoding Intelligence, Unleashing Potential
Interpretability research has emerged as a critical area for understanding LLM behaviors, informing performance optimization, and enabling more controllable model outputs. Today, we are excited to introduce Qwen-Scope, an interpretability toolkit trained on the Qwen3 and Qwen3.5 series models. Specifically, we inserted and trained Sparse Autoencoders (SAEs) within Qwen’s hidden layers. By imposing sparsity constraints, SAEs decompose the model’s dense hidden representations into sparse, disentangled, and interpretable features. Qwen-Scope not only sheds light on the internal mechanisms underlying Qwen’s behavior, but also holds potential for model optimization. Application scenarios include controllable inference, data classification and synthesis, model training and optimization, and evaluation sample distribution analysis.
- Core Highlights about Qwen-Scope:
- Inference: Enables targeted control over inference outcomes without requiring explicit natural language instructions.
- Data: Requires only a small amount of seed data to collect features for data classification, significantly reducing data dependency. Additionally, it can leverage inactive feature information to construct targeted data, thereby enhancing long-tail capabilities.
- Training: Identifies abnormally activated features by analyzing low-quality issues such as code-switching and repetitive generation. This assists in model training during supervised fine-tuning (SFT) and reinforcement learning (RL) stages, effectively reducing the frequency of such undesirable responses.
- Evaluation: Calculates feature activation patterns across different samples or benchmark datasets to jointly assess evaluation redundancy. This guides the selection of benchmarks, improves coverage of evaluated capabilities, and reduces evaluation costs.
Overlook#
The weights released in this Qwen-Scope open-source project involve 7 LLMs, covering both dense and MoE models from the Qwen3 and Qwen3.5 series, with a total of 14 sets of SAEs. To ensure broad feature coverage, strong semantic meaningfulness, and stable training, we sampled 0.5B tokens from the pretraining data of the corresponding models to train our SAEs.
| Name | Backbone type | SAE width | Expansion factor | L0 |
|---|---|---|---|---|
| Dense | ||||
| SAE-Res-Qwen3-1.7B-Base-W32K-L0_50 | base | 32K | 16 | 50 |
| SAE-Res-Qwen3-1.7B-Base-W32K-L0_100 | base | 32K | 16 | 100 |
| SAE-Res-Qwen3-8B-Base-W64K-L0_50 | base | 64K | 16 | 50 |
| SAE-Res-Qwen3-8B-Base-W64K-L0_100 | base | 64K | 16 | 100 |
| SAE-Res-Qwen3.5-2B-Base-W32K-L0_50 | base | 32K | 16 | 50 |
| SAE-Res-Qwen3.5-2B-Base-W32K-L0_100 | base | 32K | 16 | 100 |
| SAE-Res-Qwen3.5-9B-Base-W64K-L0_50 | base | 64K | 16 | 50 |
| SAE-Res-Qwen3.5-9B-Base-W64K-L0_100 | base | 64K | 16 | 100 |
| SAE-Res-Qwen3.5-27B-W80K-L0_50 | instruct | 80K | 16 | 50 |
| SAE-Res-Qwen3.5-27B-W80K-L0_100 | instruct | 80K | 16 | 100 |
| MoE | ||||
| SAE-Res-Qwen3-30B-A3B-Base-W32K-L0_50 | base | 32K | 16 | 50 |
| SAE-Res-Qwen3-30B-A3B-Base-W128K-L0_100 | base | 128K | 64 | 100 |
| SAE-Res-Qwen3.5-35B-A3B-Base-W32K-L0_50 | base | 32K | 16 | 50 |
| SAE-Res-Qwen3.5-35B-A3B-Base-W128K-L0_100 | base | 128K | 64 | 100 |
Applications#
Qwen-Scope facilitates the analysis and development of Qwen series models. This section showcases its utility across four dimensions: inference, evaluation, data, and training. Please refer to our technical report for more details.
Inference: Analysis of Model Behavior and Controllable Outputs#
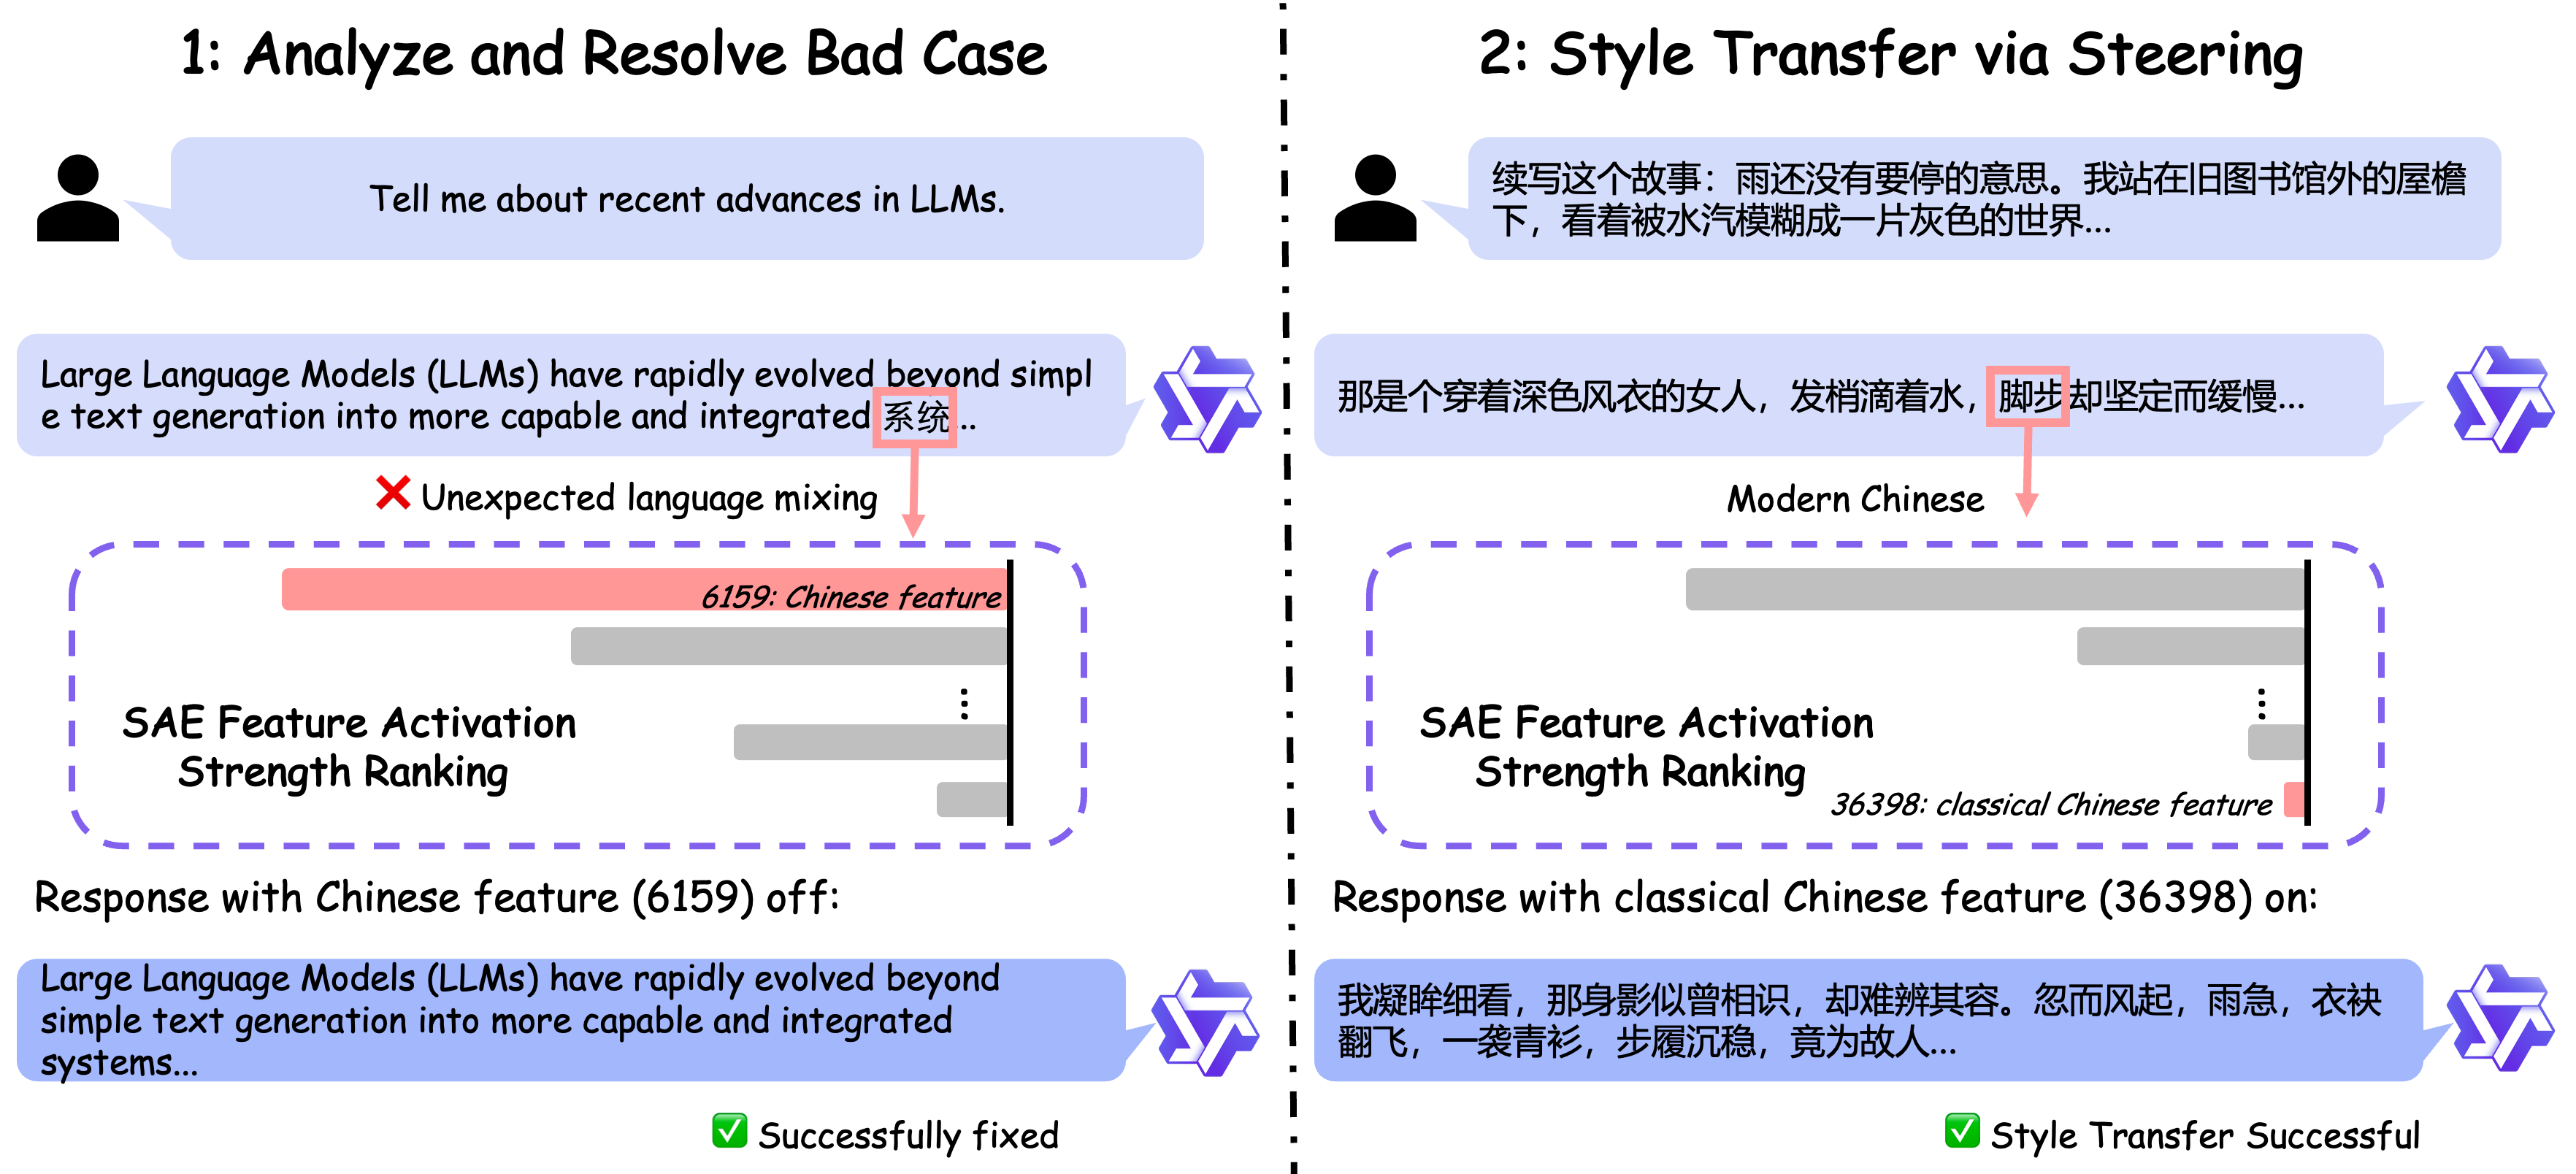
By controlling the activation of features, we can achieve targeted control over inference results, such as directed modifications in language, entities, or style, without explicitly providing natural language instructions.
Data: Classification and Synthesis#
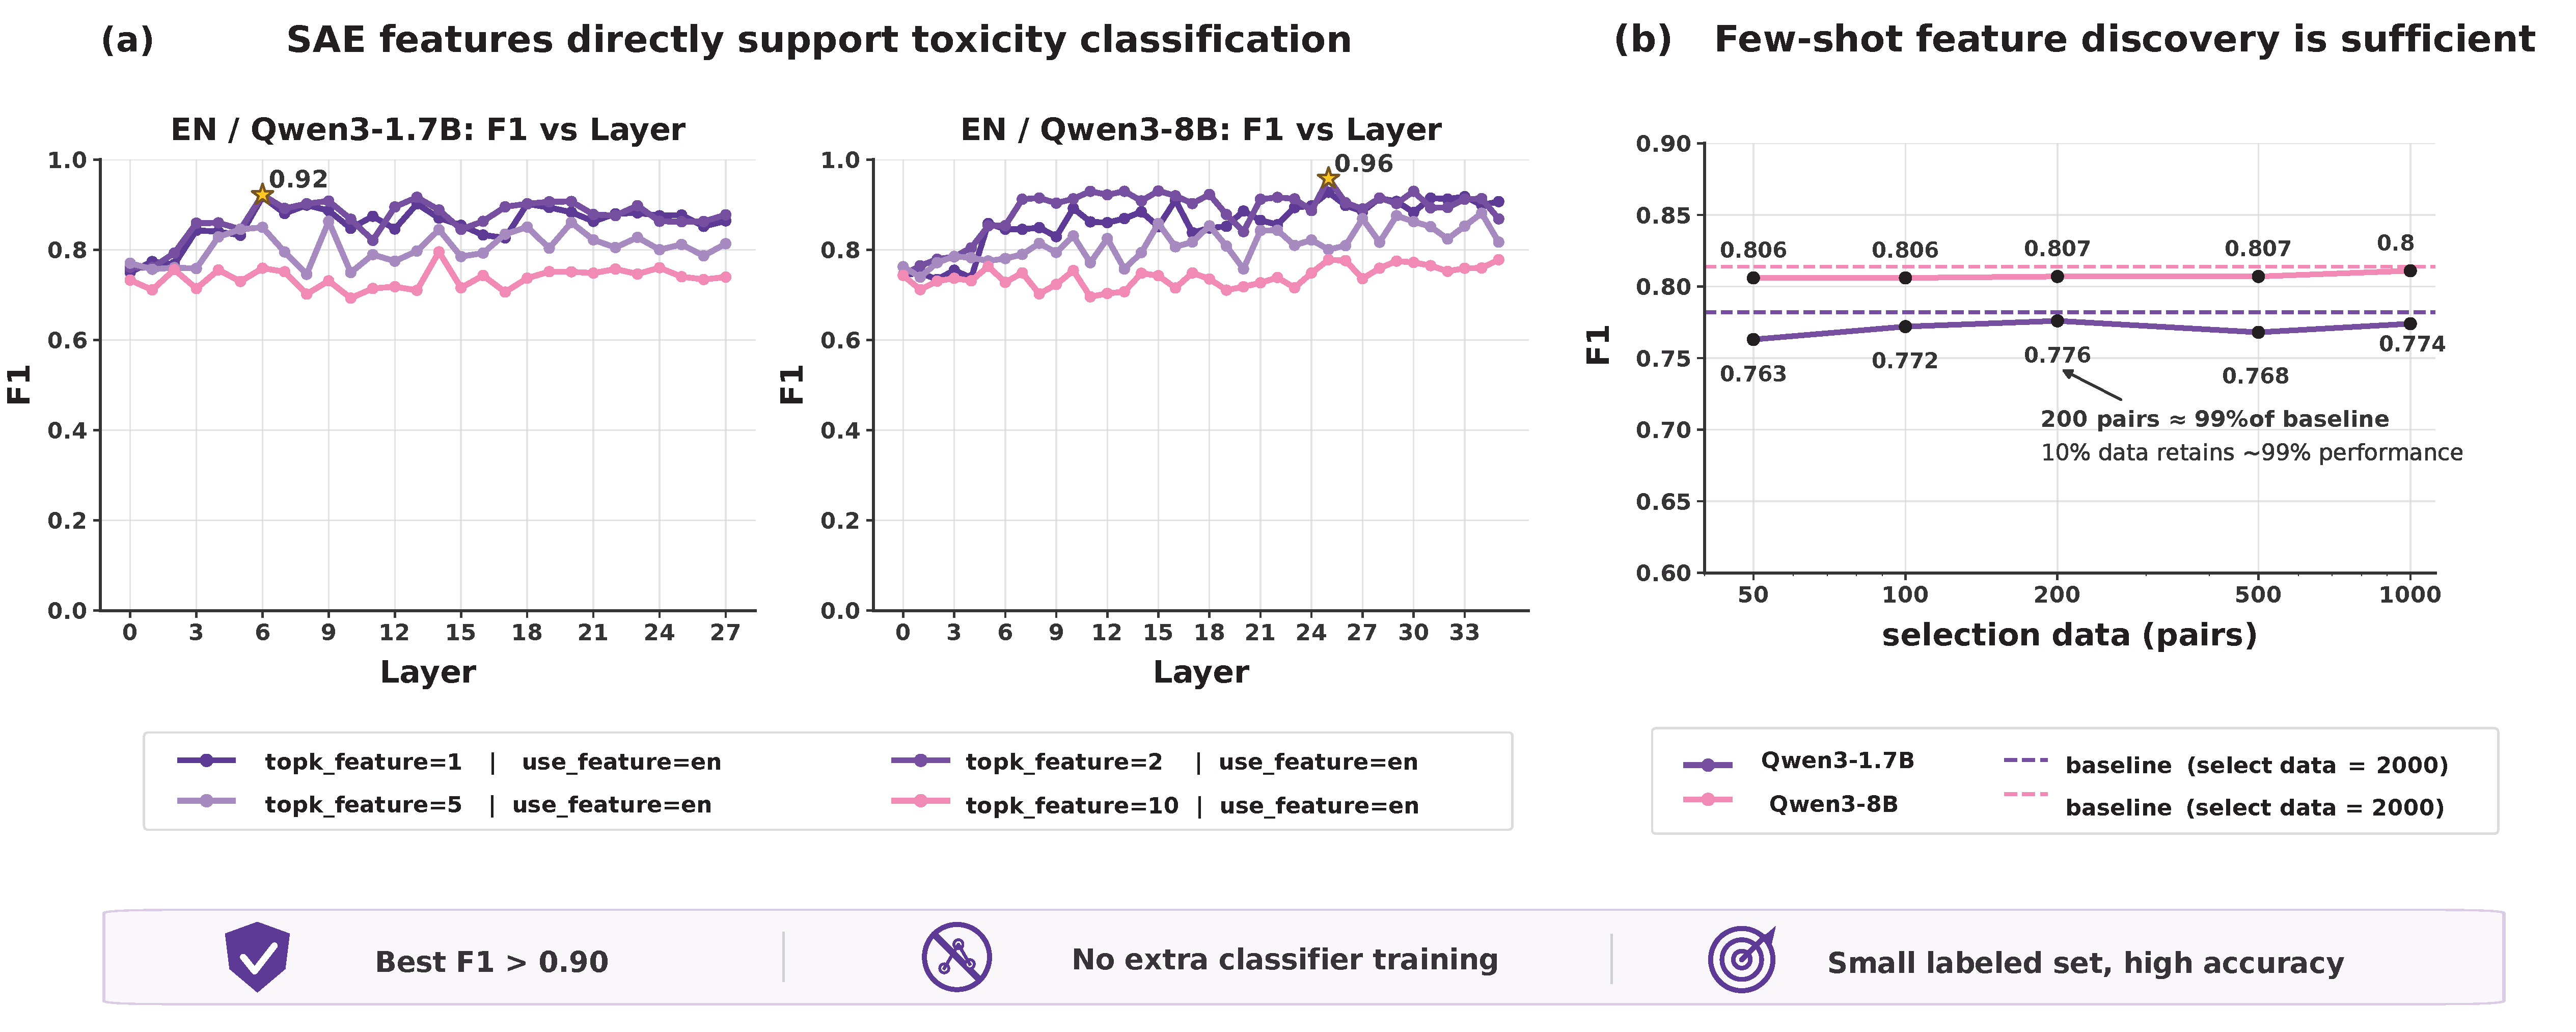
Qwen-Scope performs multi-dimensional analysis and summarization of model representations, enabling its use as a data labeling and classification tool that offers insights into data processing strategies and characterizes data properties. Taking toxic text as an example, we can use seed data to select highly relevant features for sample classification based on the activation states across all features. This process requires no additional training procedures, greatly saving annotation time. Moreover, high classification accuracy can be achieved with only a small amount of data, significantly reducing dependence on large volumes of bootstrapping data.
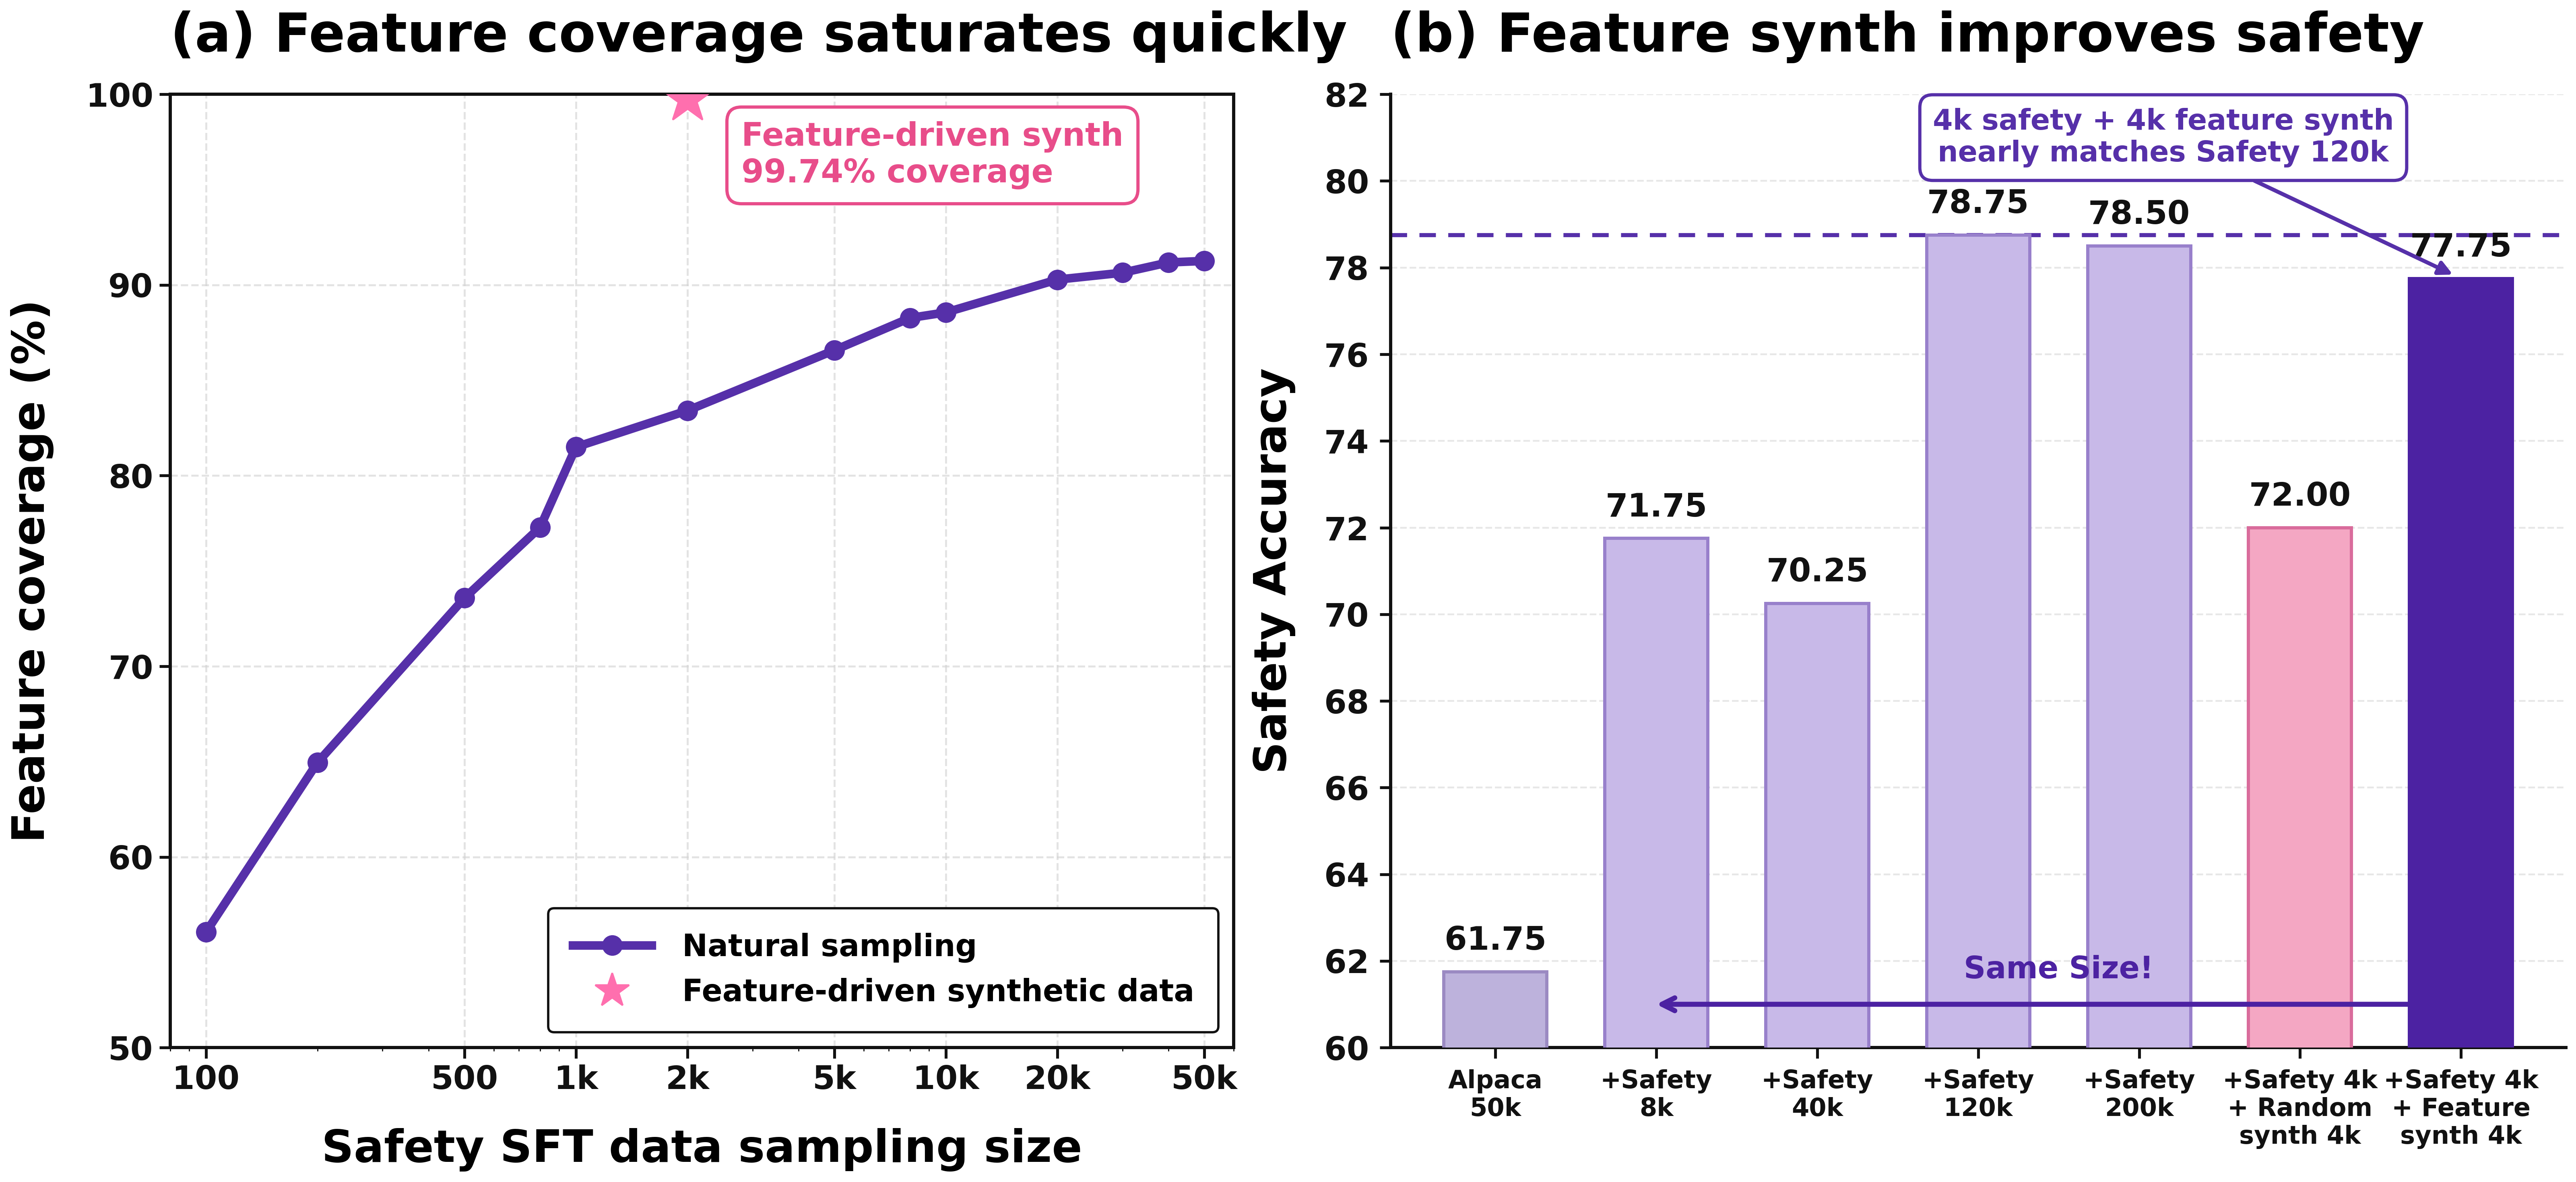
In data synthesis scenarios, Qwen-Scope can also help identify toxic text features in existing data that have been rarely or never activated, and directionally synthesize supplementary samples. Compared to traditional data synthesis approaches, this method offers stronger controllability and targeting capability, enabling more efficient coverage of long-tail capabilities and improving the training data efficiency ratio by approximately 15 times.
Training: Targeted Fine-Tuning#
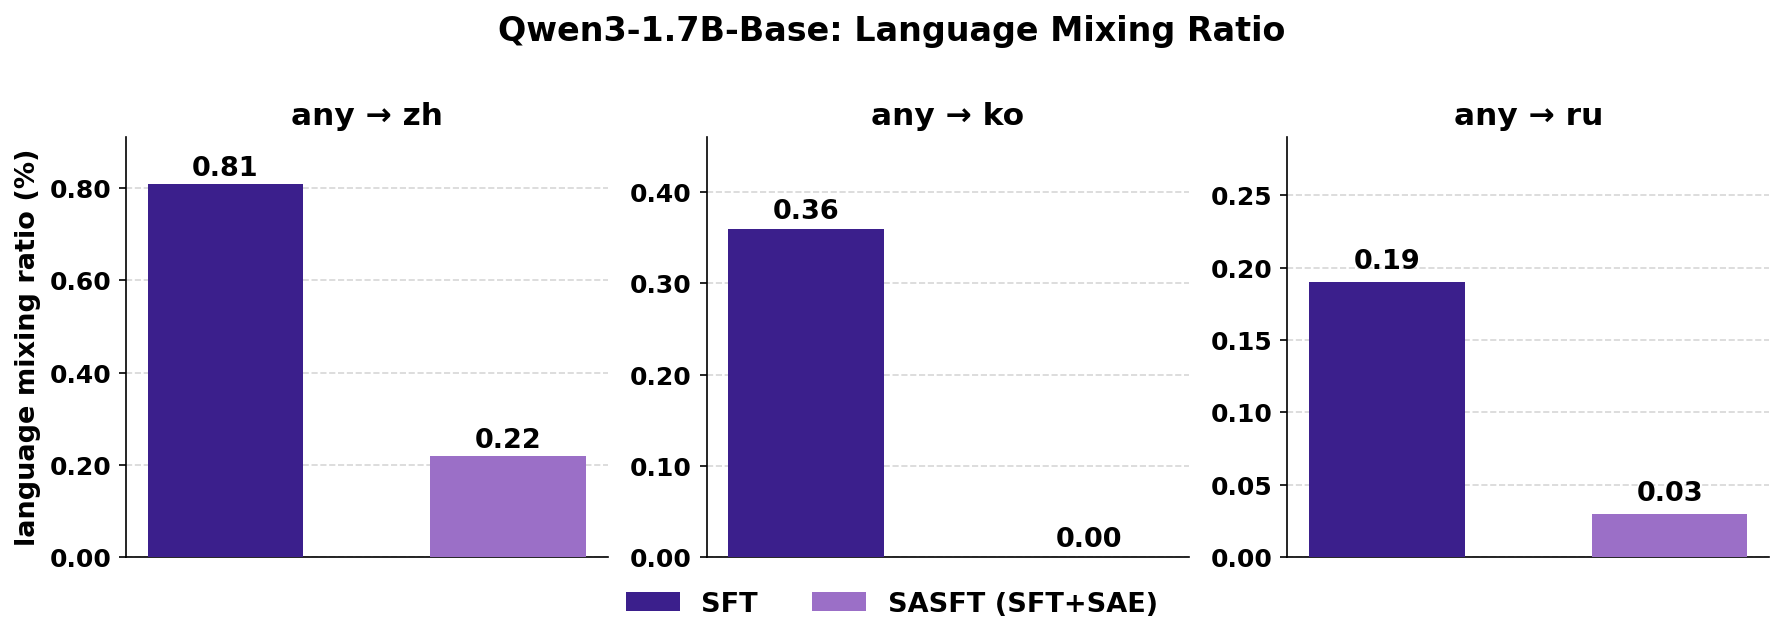
The features identified by Qwen-Scope can also be leveraged during the training phase. For instance, when we observe unexpected language mixing in model outputs (e.g., unexpected Chinese words appearing in English responses), we can pinpoint the anomalous activation patterns associated with this issue. During supervised fine-tuning, we then design a loss function specifically targeting these abnormal activations to guide the model in reducing the frequency of such undesirable cases.
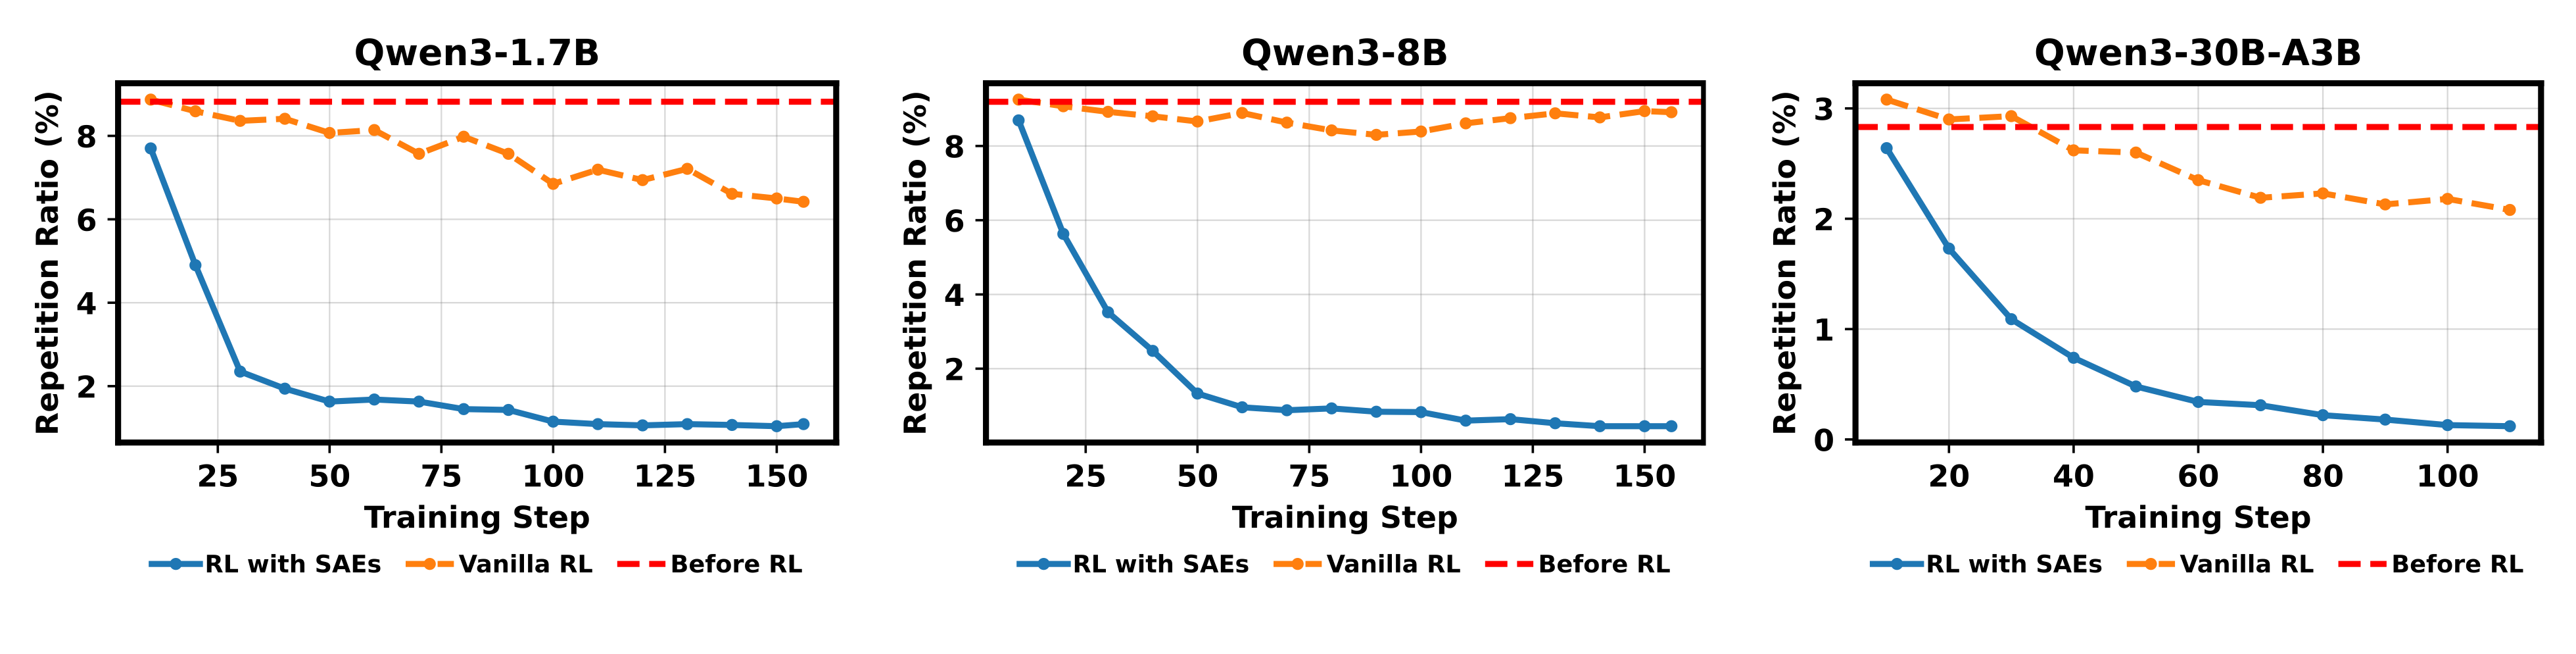
Another example is the problem of endless repetitive generation, which occurs infrequently and is therefore rarely sampled during reinforcement learning. To address this, we can amplify or highlight the corresponding anomalous activation features, thereby increasing the likelihood of sampling these bad cases. This enables the model to more effectively optimize against repetition issues during the reinforcement learning stage.
Evaluation: Addressing Redundancy and Gaps in Test Samples#
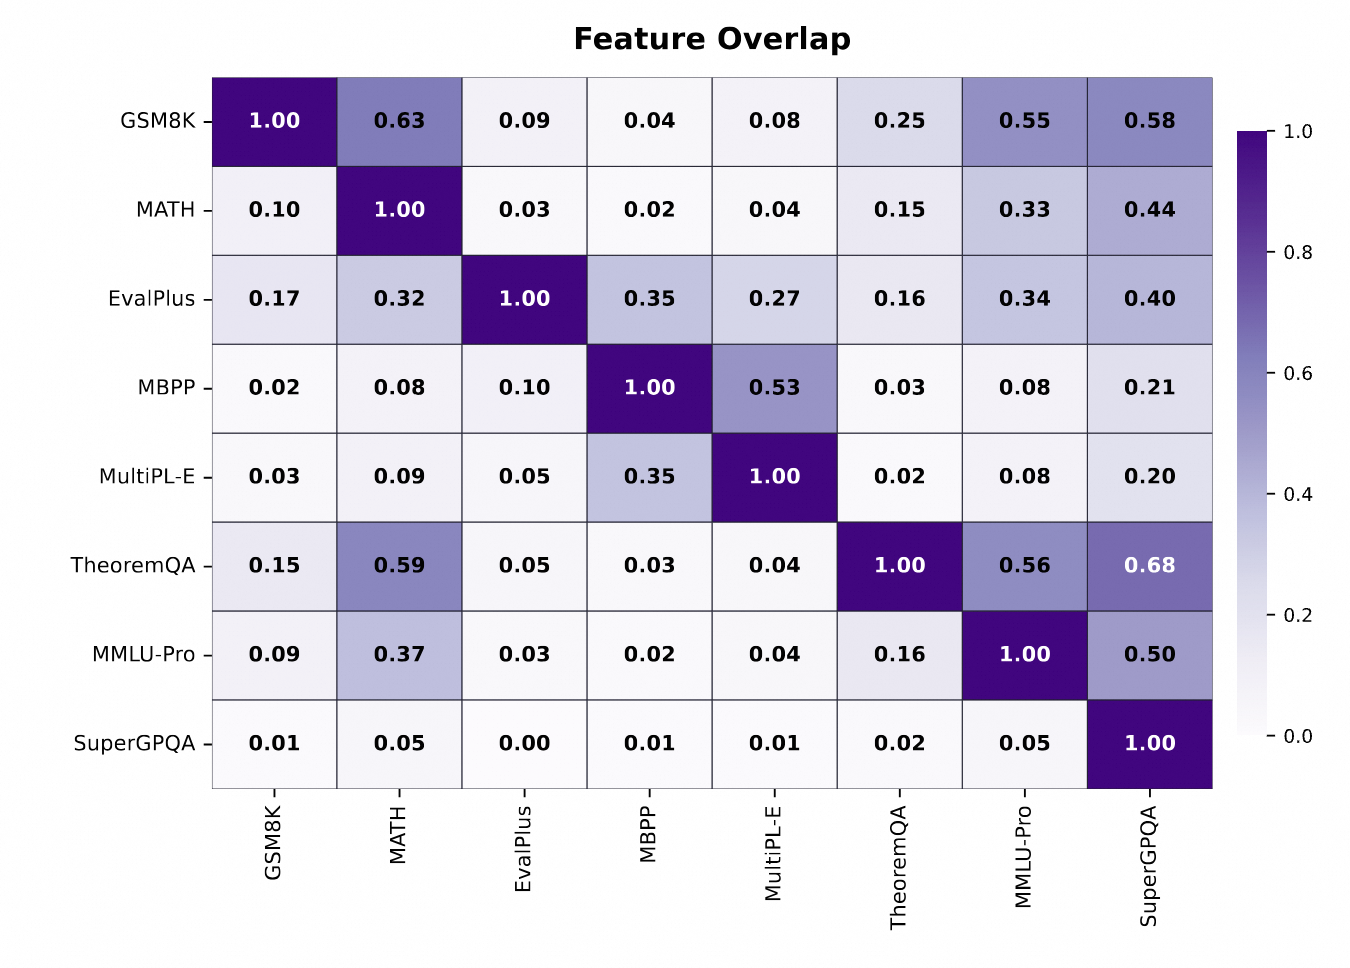
Evaluation is one of the core aspects of large language model development. As the number of capabilities and dimensions to be evaluated continues to grow, along with increasingly large sample sizes, a key question arises: which evaluation datasets contain redundancies and which domains have insufficient coverage. Through Qwen-Scope, we can analyze the feature coverage of test sets to assess the degree of evaluation redundancy across different benchmark datasets. As shown in the figure below, we found that some commonly used evaluation datasets exhibit overlapping coverage in their activated features, causing certain benchmarks to be affected by repetitive evaluation and thus having relatively lower practical significance. We hope that this type of analytical approach can help users conveniently select test samples and evaluation datasets with higher coverage and lower evaluation costs.
Summary#
Qwen-Scope is not only a tool for analyzing model behavior, but also enables deep introspection into the internal workings of models, transforming complex parameter computations into human-understandable concepts and patterns. It does more than just “interpret” models—it can actively “improve” them. Empirical results demonstrate that Qwen-Scope provides valuable insights and guidance for model optimization across various stages, including inference, evaluation, data processing, and training. Interpretability is thus not merely a post-hoc analytical tool, but can serve as one of the core engines driving model evolution. We welcome feedback from the community and eagerly look forward to seeing your creativity in action—showcasing even more innovative and interesting use cases!
Demo#
You can try Qwen-Scope on Huggingface or modelscope.
Citation#
If you think Qwen-Scope offers you any help, feel free to cite.