
Article
\nIntegrating with the IREE tokenizer for a 10x uplift in tokenization performance.
\nApril 7, 2026 monitoring / iree / tokenizer / tiktoken / huggingface / tokenizers / performance
\nToday we merged a pretty nice performance improvement to ZML.
\nPR #416 switches zml.tokenizer.Tokenizer from using the Hugging Face tokenizers crate to using the IREE project tokenizer when using Hugging Face tokenizer.json files.
Tokenizers performance is often overlooked, but it can have a significant impact on the overall latency of LLM inference. In some cases, it can even become the bottleneck of the entire system. This is particularly important as context are becoming bigger and bigger. For code generation, a 1M context window is regular. But a 1M context means 4MB of data (u32).
A bad (de)tokenization strategy can severely impact the overall latency of the system, and as such, it’s crucial to have a fast and efficient tokenizer.
\nZML handles 2 types of tokenizers: Hugging Face tokenizer.json files and SentencePiece models. This is exposed through the zml.tokenizer.Tokenizer union type, which makes this transparent to the user:
var tokenizer: zml.tokenizer.Tokenizer = try .fromFile(allocator, io, "tokenizer.json");\ndefer tokenizer.deinit();\nconst token_id = tokenizer.tokenId("<|im_start|>") orelse return error.TokenNotFound;\nThe zml.tokenizer.Tokenizer types also support the Encoder and Decoder types for streaming purposes. We are also iterating on a std.Io.Reader/Writer based APIs for great composability.
For SentencePiece, we use the official google/sentencepiece implementation.
\nFor Hugging Face, we leverage the tokenizers crate via a C trampoline.
\nThe IREE tokenizer, introduced by Stella Laurenzo in her LinkedIn post is a C reimplementation of the Hugging Face and TikToken tokenizers. The interesting part is that it was generated by agents, orchestrated and reviewed by Ben Vanik.
\nIt also happens to be 10x faster than everything else.
\n
We’re sold.
\nAt its core, the IREE tokenizer is a pretty straightforward C API. Simple right? Well, as always, there are strings attached. However, because ZML and IREE are built with Bazel, and thanks to our native translate-c support in rules_zig, integration was super easy.
IREE being a pretty big project. We had to be careful to only pull in the tokenizer and its dependencies. This is done via a git sparse checkout and a little patch to shim or remove a few graph dependencies. No biggie.
\nAfter that, we just had to depend on a few targets, bind it to our abstractions and we were good to go.
\nWith all said and done, here are the benchmarks when integrated in ZML with a ~100k tokens text:
\n| Model | \nHugging Face (ms) | \nIREE oneshot / stream (ms) | \nSpeedup | \n
|---|---|---|---|
| liquidai/LFM2.5-1.2B-Instruct | \n40.5 | \n8.5 / 7.3 | \n4.8x / 5.5x | \n
| Qwen/Qwen3.5-9B | \n59.4 | \n6.0 / 8.2 | \n9.9x / 7.2x | \n
| mistralai/Ministral-3-3B-Reasoning-2512 | \n59.2 | \n7.4 / 6.9 | \n8x / 8.6x | \n
We’re pretty happy with the IREE tokenizer. It has been a long discussion at ZML on wether we should rewrite our own implementation in Zig, mostly because we had some ideas to optimize the tokenization process. That said, the performance uplift is so significant that we don’t think it’s worth it for now.
\nAs such, we’ll be removing the Rust implementation and it will be done in a separate PR.
\nHappy hacking!
\n", "content_markdown": "Article\n\nIntegrating with the IREE tokenizer for a 10x uplift in tokenization performance.\n\nApril 7, 2026 monitoring / iree / tokenizer / tiktoken / huggingface / tokenizers / performance\n\nToday we merged a pretty nice performance improvement to ZML.\n\n[PR #416](https://github.com/zml/zml/pull/416) switches `zml.tokenizer.Tokenizer` from using the Hugging Face [`tokenizers`](https://crates.io/crates/tokenizers) crate to using the [IREE project tokenizer](https://github.com/iree-org/iree/blob/main/runtime/src/iree/tokenizer/README.md) when using Hugging Face `tokenizer.json` files.\n\n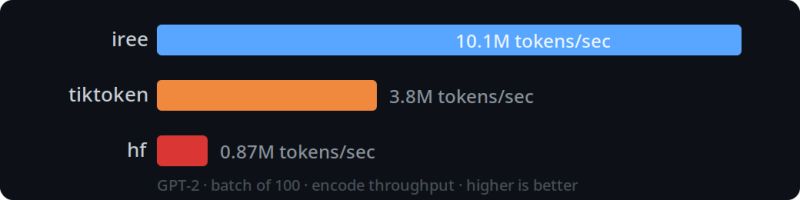\n\n## The (upcoming) problem\n\nTokenizers performance is often overlooked, but it can have a significant impact on the overall latency of LLM inference. In some cases, it can even become the bottleneck of the entire system. This is particularly important as context are becoming bigger and bigger. For code generation, a 1M context window is regular. But a 1M context means 4MB of data (`u32`).\n\nA bad (de)tokenization strategy can severely impact the overall latency of the system, and as such, it’s crucial to have a fast and efficient tokenizer.\n\n## ZML Tokenizers\n\nZML handles 2 types of tokenizers: Hugging Face `tokenizer.json` files and SentencePiece models. This is exposed through the `zml.tokenizer.Tokenizer` union type, which makes this transparent to the user:\n\n```zig\nvar tokenizer: zml.tokenizer.Tokenizer = try .fromFile(allocator, io, \"tokenizer.json\");\ndefer tokenizer.deinit();\nconst token_id = tokenizer.tokenId(\"<|im_start|>\") orelse return error.TokenNotFound;\n```\n\nThe `zml.tokenizer.Tokenizer` types also support the `Encoder` and `Decoder` types for streaming purposes. We are also iterating on a `std.Io.Reader/Writer` based APIs for great composability.\n\nFor SentencePiece, we use the official [google/sentencepiece](https://github.com/google/sentencepiece) implementation.\n\nFor Hugging Face, we leverage the [tokenizers crate](https://crates.io/crates/tokenizers) via a [C trampoline](https://github.com/zml/zml/blob/70c5d1c5883813e13481cf35fab841f8a18152aa/zml/tokenizer/hftokenizers/hftokenizers.rs).\n\n## The IREE tokenizer\n\nThe IREE tokenizer, introduced by [Stella Laurenzo in her LinkedIn post](https://www.linkedin.com/posts/stellalaurenzo_fastest-llm-tokenizer-on-the-internet-authored-activity-7435479758118989825--wDF) is a C reimplementation of the Hugging Face and TikToken tokenizers. The interesting part is that it was generated by agents, orchestrated and reviewed by Ben Vanik.\n\n**It also happens to be 10x faster than everything else.**\n\n\n\nWe’re sold.\n\n## Easily integrated via Bazel\n\nAt its core, the IREE tokenizer is a pretty straightforward C API. Simple right? Well, as always, there are strings attached. However, because ZML and IREE are built with Bazel, and thanks to our [native `translate-c` support in rules\\_zig](https://github.com/zml/rules_zig/blob/zig-0.16/zig/private/common/translate_c.bzl), integration was super easy.\n\nIREE being a pretty big project. We had to be careful to only pull in the tokenizer and its dependencies. This is done via a [git sparse checkout](https://git-scm.com/docs/git-sparse-checkout) and a [little patch](https://github.com/zml/zml/blob/master/third_party/iree/tokenizer-only.patch) to shim or remove a few graph dependencies. No biggie.\n\nAfter that, we just had to [depend on a few targets](https://github.com/zml/zml/blob/adee932efa875d181cfc3ec8cbc4eb822db76035/zml/tokenizer/iree/BUILD.bazel#L9-L11), bind it to our abstractions and we were good to go.\n\n## Benchmarks\n\nWith all said and done, here are the benchmarks when integrated in ZML with a ~100k tokens text:\n\n| Model | Hugging Face (ms) | IREE oneshot / stream (ms) | Speedup |\n| --------------------------------------- | ----------------- | -------------------------- | --------------- |\n| liquidai/LFM2.5-1.2B-Instruct | 40.5 | 8.5 / 7.3 | **4.8x / 5.5x** |\n| Qwen/Qwen3.5-9B | 59.4 | 6.0 / 8.2 | **9.9x / 7.2x** |\n| mistralai/Ministral-3-3B-Reasoning-2512 | 59.2 | 7.4 / 6.9 | **8x / 8.6x** |\n\n## Sunsetting the Rust implementation\n\nWe’re pretty happy with the IREE tokenizer. It has been a long discussion at ZML on wether we should rewrite our own implementation in Zig, mostly because we had some ideas to optimize the tokenization process. That said, the performance uplift is so significant that we don’t think it’s worth it for now.\n\nAs such, we’ll be removing the Rust implementation and it will be done in a separate PR.\n\nHappy hacking!\n", "dateCreated": "2026-09-08T10:17:10.166315+00:00", "date_created": "2026-04-07T08:00:00+00:00", "date_modified": "2026-04-07T08:00:00+00:00", "date_published": "2026-04-07T08:00:00+00:00", "description": "Today we merged a pretty nice performance improvement to ZML. PR #416 switches zml.tokenizer.Tokenizer from using the Hugging Face tokenizers crate to using the IREE project tokenizer when using Hugging Face tokenizer.json files. The…", "external_url": "https://zml.ai/posts/iree-tokenizer/", "git": { "commit": "ebb0941c5c06a2ab2377342d607535262a3e969e", "path": "items/zml-ai/2026/04/2026-04-07-10x-faster-tokenization.md", "permalink": "https://github.com/aymericbeaumet/aggr-instance/blob/ebb0941c5c06a2ab2377342d607535262a3e969e/items/zml-ai/2026/04/2026-04-07-10x-faster-tokenization.md" }, "id": "urn:aggr:item:80d81f34a0f86e3dc0e7da6da052ad1ca224efb8", "isBasedOn": { "@id": "https://zml.ai/posts/iree-tokenizer/" }, "mainEntity": { "@id": "https://zml.ai/posts/iree-tokenizer/", "@type": "CreativeWork", "archivedAt": { "@id": "https://aggr.aymericbeaumet.com/items/zml-ai/2026-04-07-10x-faster-tokenization/#webpage" }, "dateModified": "2026-04-07T08:00:00+00:00", "datePublished": "2026-04-07T08:00:00+00:00", "headline": "10x faster tokenization", "timeRequired": "PT3M", "url": "https://zml.ai/posts/iree-tokenizer/", "wordCount": 537 }, "name": "Archived snapshot: 10x faster tokenization", "preview": null, "reading_minutes": 3, "replicated_at": null, "source": "zml-ai", "source_name": "ZML - Model to Metal", "summary": "Today we merged a pretty nice performance improvement to ZML. PR #416 switches zml.tokenizer.Tokenizer from using the Hugging Face tokenizers crate to using the IREE project tokenizer when using Hugging Face tokenizer.json files. The (upcoming) problem Tokenizers performance is often overlooked, but it can have a significant impact on the overall latency of LLM inference. In some cases, it can even become the bottleneck of the entire system. This is particularly important as context are becoming bigger and bigger. For code generation, a 1M context window is regular. But a 1M context means 4MB of data (u32).", "tags": [], "temporalCoverage": "2026-09-08T10:17:10.166315+00:00", "title": "10x faster tokenization", "url": "https://aggr.aymericbeaumet.com/items/zml-ai/2026-04-07-10x-faster-tokenization/", "word_count": 537 }