
Introducing Kimi K3.1 Pro (via) Kimi K3.1 Pro landed on the Kimi API today - it's not yet open weights, but Moonshot promise "Full model weights will be released by Nov 4, 2026".
\nThey're also offering a "Highspeed" version that's 2-3x faster, at twice the price (except for input token cache hits, which are priced the same).
\nThe US dollar pricing is $2.00/million tokens for input and $10/million for output - the same as GPT-6.1 Sol and half the price of Claude Opus 5.5.
\nMoonshot's own benchmarks show Kimi as approximately level with Opus 5.5 and GPT-6 Astra - beating them on a few benchmarks, coming close on others.
\nArtificial Analysis scored Kimi at 55 - ahead of Claude Fable 5.1, GPT-6 Astra, and Gemini 4 Argon (all at 53) and behind only Claude Opus 5.5 (58).
\nThis is the first time a (soon-to-be) open weight model has scored this highly against the frontier.
\nI tried it out via the Moonshot API using the llm openai endpoint command I added to LLM 0.32 back in August:
\nllm openai endpoint \\\n https://api.moonshot.ai/v1 \\\n --key kimi \\\n -m kimi-k3.1-pro \\\n "Generate an SVG of a pelican riding a bicycle" \\\n --responses \\\n -o reasoning_effort low \\\n > kimi-k3.1-pro-pelican-low.stdout.txt \\\n 2> kimi-k3.1-pro-pelican-low.stderr.txt\nllm openai endpoint can run prompts against any OpenAI-compatible endpoint but doesn't log the results, hence the extra options to save stdout and stderr (the reasoning trace).
Here are the pelicans I got for Kimi K3.1 Pro on the three reasoning levels it supports - low, medium, and max. This is max:
\n
For comparison, I ran fresh pelicans against Kimi K3 on those three reasoning levels.
\n", "content_markdown": "**[Introducing Kimi K3.1 Pro](https://www.kimi.ai/blog/kimi-k3-1-pro)** ([via](https://news.ycombinator.com/item?id=50212065 \"Hacker News\")) Kimi K3.1 Pro landed on the Kimi API today - it's not yet open weights, but Moonshot promise \"Full model weights will be released by Nov 4, 2026\".\n\nThey're also offering a \"Highspeed\" version that's 2-3x faster, at twice the price (except for input token cache hits, which are priced the same).\n\nThe [US dollar pricing](https://platform.kimi.ai/docs/pricing/chat) is $2.00/million tokens for input and $10/million for output - the same as GPT-6.1 Sol and half the price of Claude Opus 5.5.\n\nMoonshot's own benchmarks show Kimi as approximately level with Opus 5.5 and GPT-6 Astra - beating them on a few benchmarks, coming close on others.\n\nArtificial Analysis [scored Kimi at 55](https://artificialanalysis.ai/models/kimi-k3-1-pro) - ahead of Claude Fable 5.1, GPT-6 Astra, and Gemini 4 Argon (all at 53) and behind only Claude Opus 5.5 (58).\n\nThis is the first time a (soon-to-be) open weight model has scored this highly against the frontier.\n\nI tried it out via the [Moonshot API](https://platform.kimi.ai/docs/get-your-api-key) using the [llm openai endpoint](https://llm.datasette.io/en/stable/other-models.html#openai-endpoint) command I added to [LLM 0.32](https://llm.datasette.io/en/stable/changelog.html#v0-32) back in August:\n\n```\nllm openai endpoint \\\n https://api.moonshot.ai/v1 \\\n --key kimi \\\n -m kimi-k3.1-pro \\\n \"Generate an SVG of a pelican riding a bicycle\" \\\n --responses \\\n -o reasoning_effort low \\\n > kimi-k3.1-pro-pelican-low.stdout.txt \\\n 2> kimi-k3.1-pro-pelican-low.stderr.txt\n```\n\n`llm openai endpoint` can run prompts against any OpenAI-compatible endpoint but doesn't log the results, hence the extra options to save stdout and stderr (the reasoning trace).\n\nHere [are the pelicans](https://tools.simonwillison.net/markdown-svg-renderer?url=https%3A%2F%2Fgist.github.com%2Fsimonw%2F9b7181492209387da1d4f53002f26663) I got for Kimi K3.1 Pro on the three reasoning levels it supports - low, medium, and max. This is max:\n\n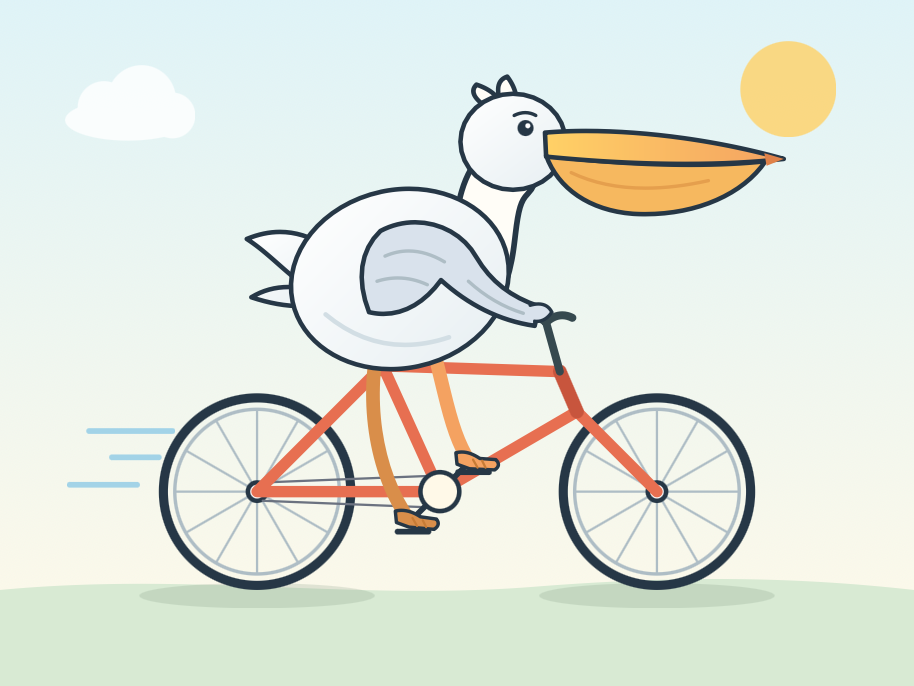\n\nFor comparison, I ran fresh [pelicans against Kimi K3](https://tools.simonwillison.net/markdown-svg-renderer?url=https%3A%2F%2Fgist.github.com%2Fsimonw%2Feba9a4283c9e94cbbb5325902a3921a8) on those three reasoning levels.\n", "dateCreated": "2026-10-23T22:00:18.516360473+00:00", "date_created": "2026-10-23T19:40:54+00:00", "date_modified": "2026-10-23T19:40:54+00:00", "date_published": "2026-10-23T19:40:54+00:00", "description": "Introducing Kimi K3.1 Pro Kimi K3.1 Pro landed on the Kimi API today - it's not yet open weights, but Moonshot promise \"Full model weights will be released by Nov 4, 2026\". They're also offering a \"Highspeed\" version that's 2-3x faster, at…", "external_url": "https://simonwillison.net/2026/Oct/23/kimi-k31-pro/", "git": { "commit": "20068632b65d2830a2d54f25ca1d90d697bea2c0", "path": "items/simonwillison-net/2026/10/2026-10-23-introducing-kimi-k3-1-pro.md", "permalink": "https://github.com/aymericbeaumet/aggr-instance/blob/20068632b65d2830a2d54f25ca1d90d697bea2c0/items/simonwillison-net/2026/10/2026-10-23-introducing-kimi-k3-1-pro.md" }, "id": "urn:aggr:item:d3d671fd70bf111c804c95c8c473a26e2d71c842", "isBasedOn": { "@id": "https://simonwillison.net/2026/Oct/23/kimi-k31-pro/" }, "mainEntity": { "@id": "https://simonwillison.net/2026/Oct/23/kimi-k31-pro/", "@type": "CreativeWork", "archivedAt": { "@id": "https://aggr.aymericbeaumet.com/items/simonwillison-net/2026-10-23-introducing-kimi-k3-1-pro/#webpage" }, "dateModified": "2026-10-23T19:40:54+00:00", "datePublished": "2026-10-23T19:40:54+00:00", "headline": "Introducing Kimi K3.1 Pro", "image": { "@type": "ImageObject", "caption": null, "height": 90, "url": "https://static.simonwillison.net/static/2026/kimi-k3.1-card.jpg", "width": 160 }, "timeRequired": "PT2M", "url": "https://simonwillison.net/2026/Oct/23/kimi-k31-pro/", "wordCount": 282 }, "name": "Archived snapshot: Introducing Kimi K3.1 Pro", "preview": { "alt": null, "color": null, "height": 90, "placeholder": { "data_url": "data:image/png;base64,iVBORw0KGgoAAAANSUhEUgAAAAEAAAABCAQAAAC1HAwCAAAAC0lEQVR42mNk+A8AAQUBAScY42YAAAAASUVORK5CYII=", "hash": "" }, "url": "https://static.simonwillison.net/static/2026/kimi-k3.1-card.jpg", "width": 160 }, "reading_minutes": 2, "replicated_at": null, "source": "simonwillison-net", "source_name": "Simon Willison's Weblog", "summary": "Introducing Kimi K3.1 Pro Kimi K3.1 Pro landed on the Kimi API today - it's not yet open weights, but Moonshot promise \"Full model weights will be released by Nov 4, 2026\". They're also offering a \"Highspeed\" version that's 2-3x faster, at twice the price (except for input token cache hits, which are priced the same). The US dollar pricing is $2.00/million tokens for input and $10/million for output - the same as GPT-6.1 Sol and half the price of Claude Opus 5.5. Moonshot's own benchmarks show Kimi as approximately level with Opus 5.5 and GPT-6 Astra - beating them on a few benchmarks, coming close on others. Artificial Analysis scored Kimi at 55 - ahead of Claude Fable 5.1, GPT-6 Astra, and Gemini 4 Argon (all at 53) and behind only Claude Opus 5.5 (58). This is the first time a (soon-to-be) open weight model has scored this highly against the frontier. I tried it out via the Moonshot API using the llm openai endpoint command I added to LLM 0.32 back in August: llm openai endpoint \\ https://api.moonshot.ai/v1 \\ --key kimi \\ -m kimi-k3.1-pro \\ \"Generate an SVG of a pelican riding a bicycle\" \\ --responses \\ -o reasoning_effort low \\ > kimi-k3.1-pro-pelican-low.stdout.txt \\ 2> kimi-k3.1-pro-pelican-low.stderr.txt llm openai endpoint can run prompts against any OpenAI-compatible endpoint but doesn't log the results, hence the extra options to save stdout and stderr (the reasoning trace). Here are the pelicans I got for Kimi K3.1 Pro on the three reasoning levels it supports - low, medium, and max. This is max: For comparison, I ran fresh pelicans against Kimi K3 on those three reasoning levels. Via Hacker News Tags: ai, generative-ai, llms, llm, llm-pricing, pelican-riding-a-bicycle, llm-release, ai-in-china, moonshot, kimi", "tags": [ "ai", "ai-in-china", "generative-ai", "kimi", "llm", "llm-pricing", "llm-release", "llms", "moonshot", "pelican-riding-a-bicycle" ], "temporalCoverage": "2026-10-23T22:00:18.516360473+00:00", "title": "Introducing Kimi K3.1 Pro", "url": "https://aggr.aymericbeaumet.com/items/simonwillison-net/2026-10-23-introducing-kimi-k3-1-pro/", "word_count": 282 }