{
  "@context": "https://schema.org",
  "@id": "https://aggr.aymericbeaumet.com/items/qwen-ai/2026-09-20-qwen-image-2-1-compact-efficient-and-unified-image-creation/#webpage",
  "@type": [
    "WebPage",
    "ArchiveComponent"
  ],
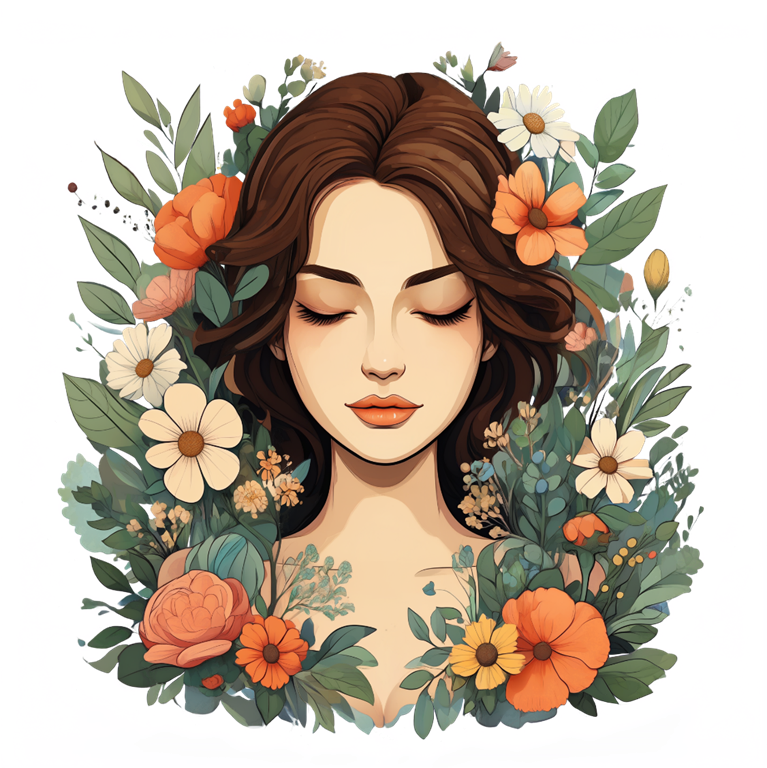
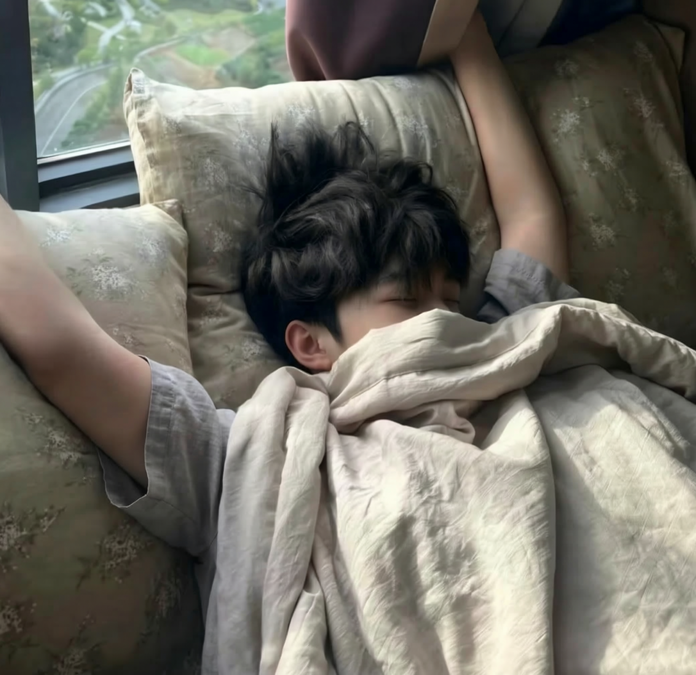
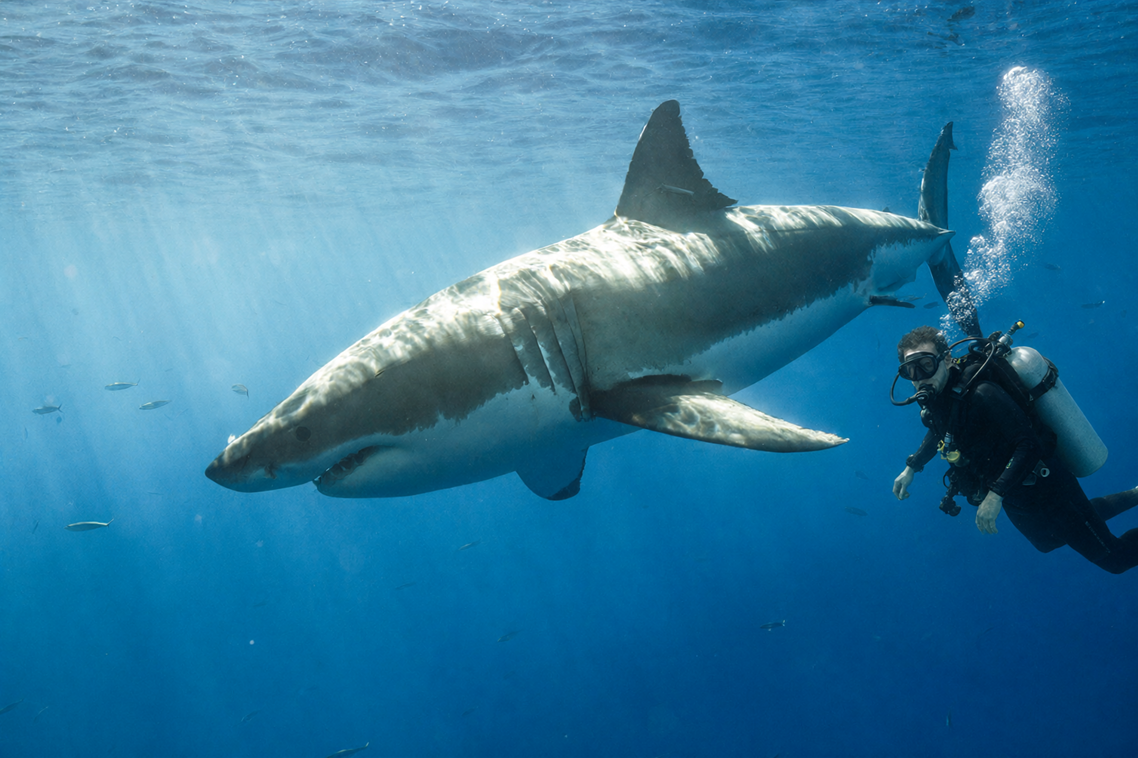
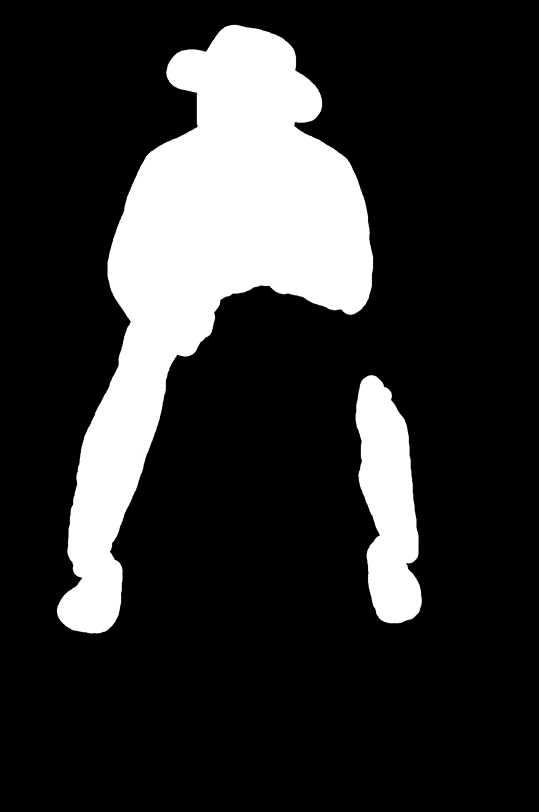
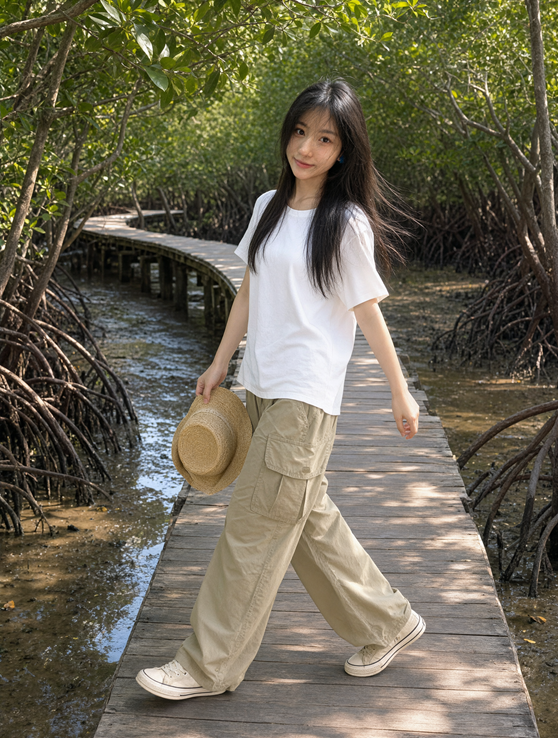
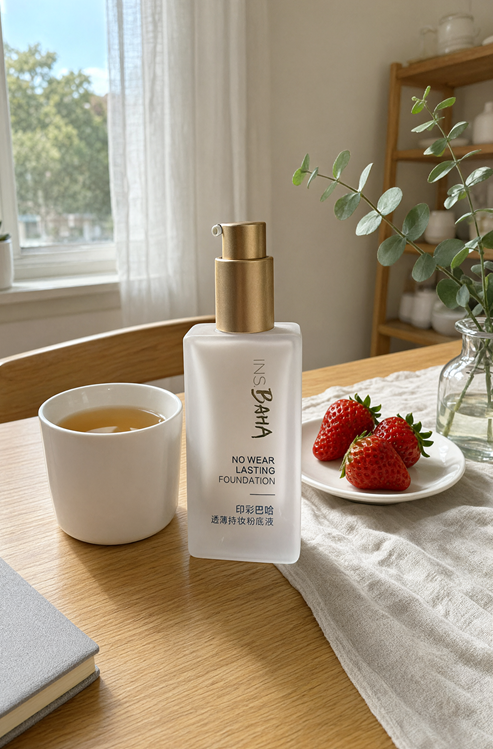
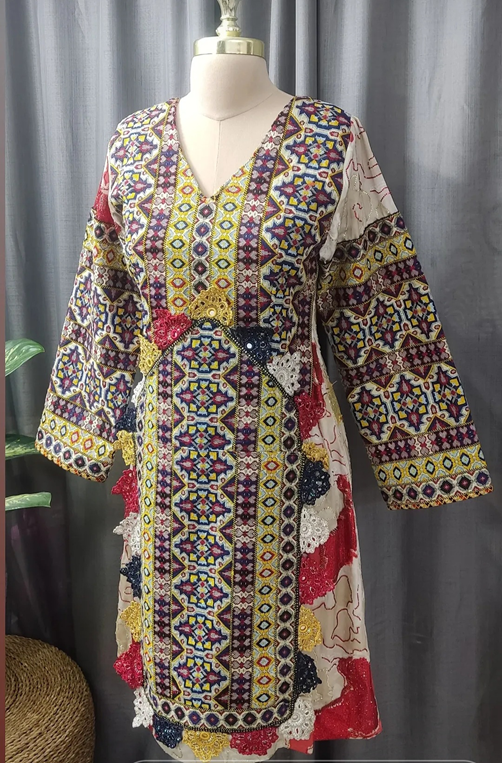
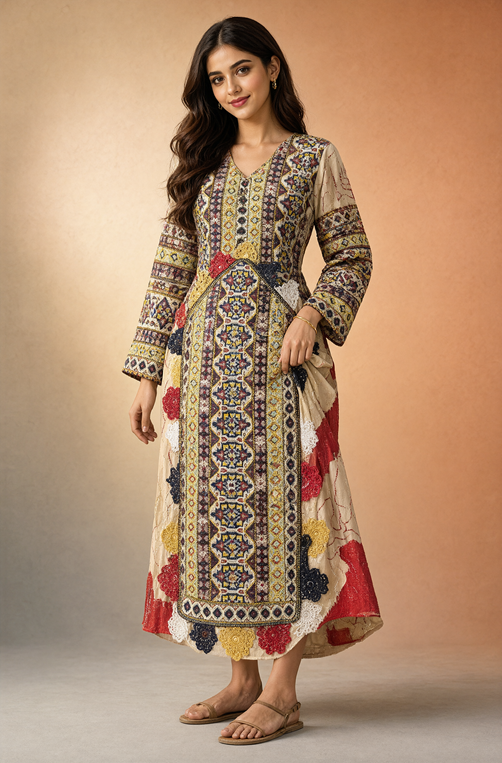
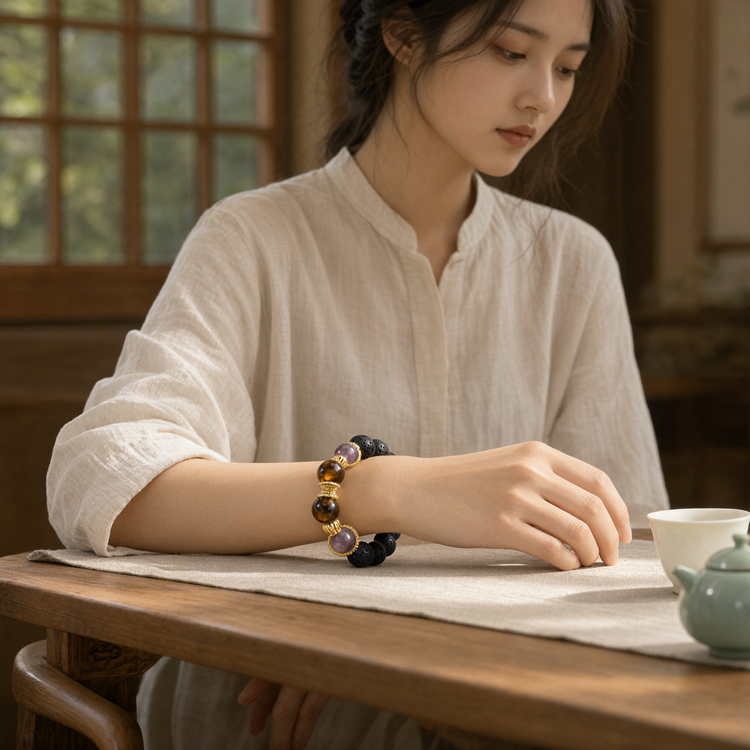
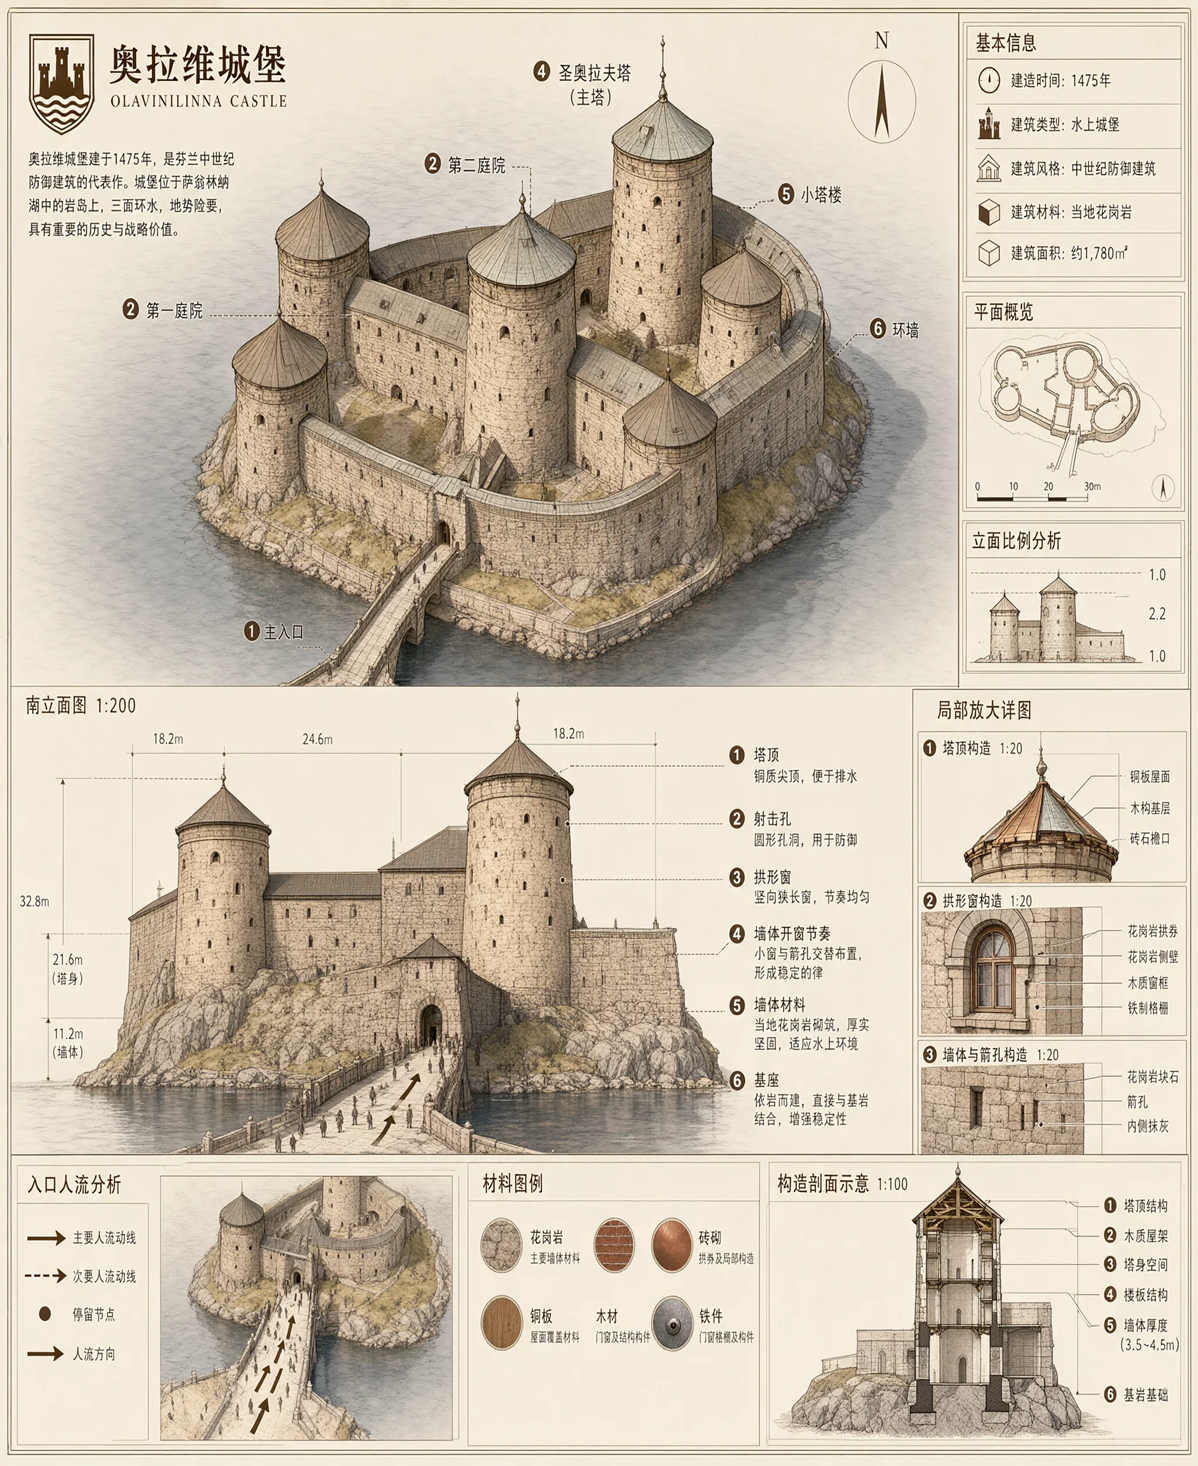
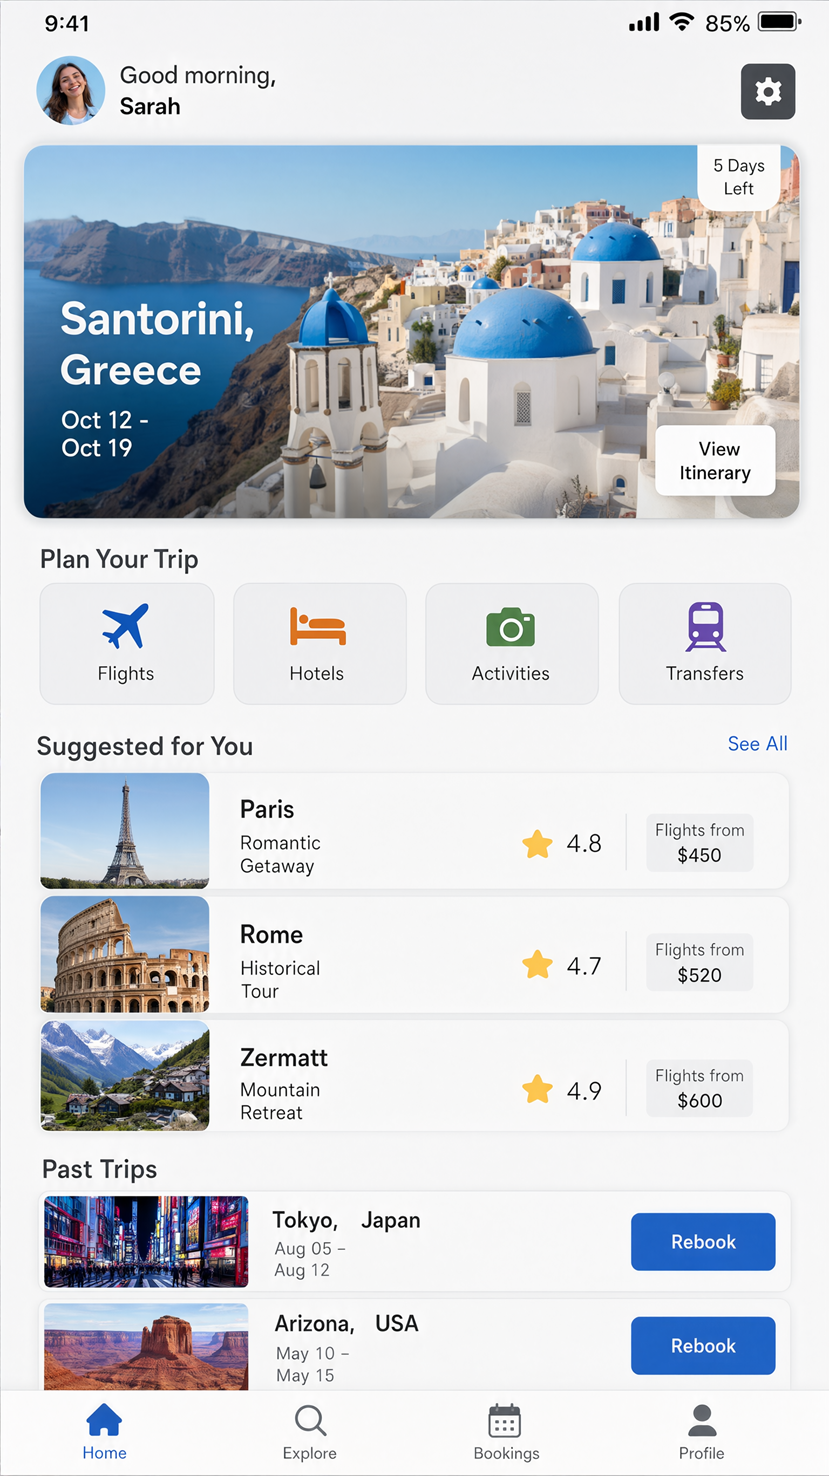
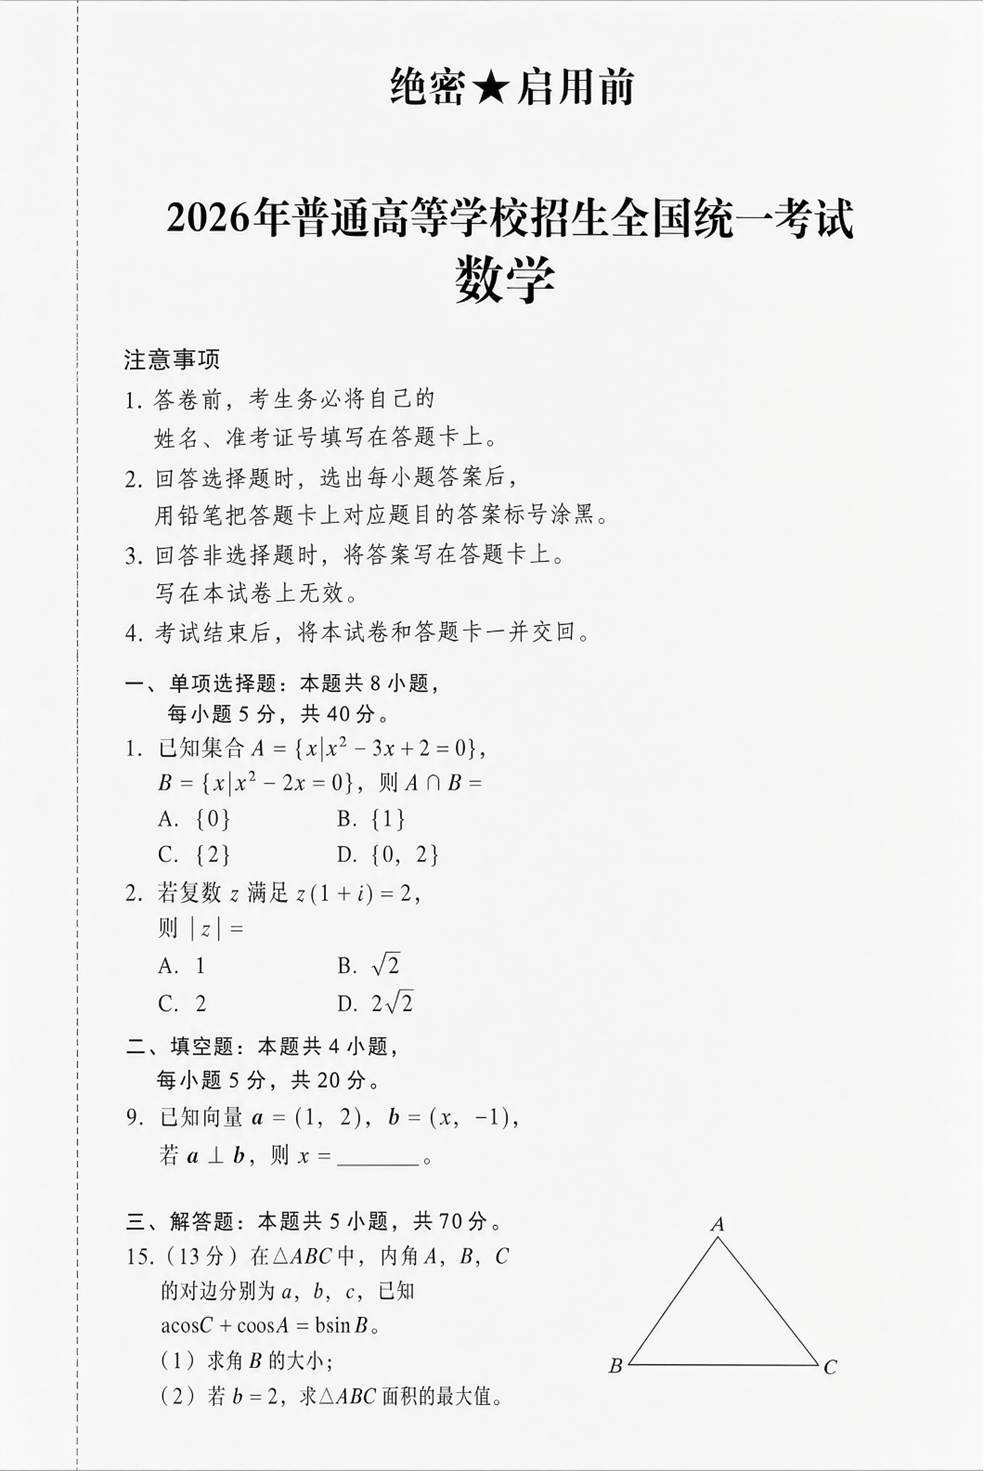
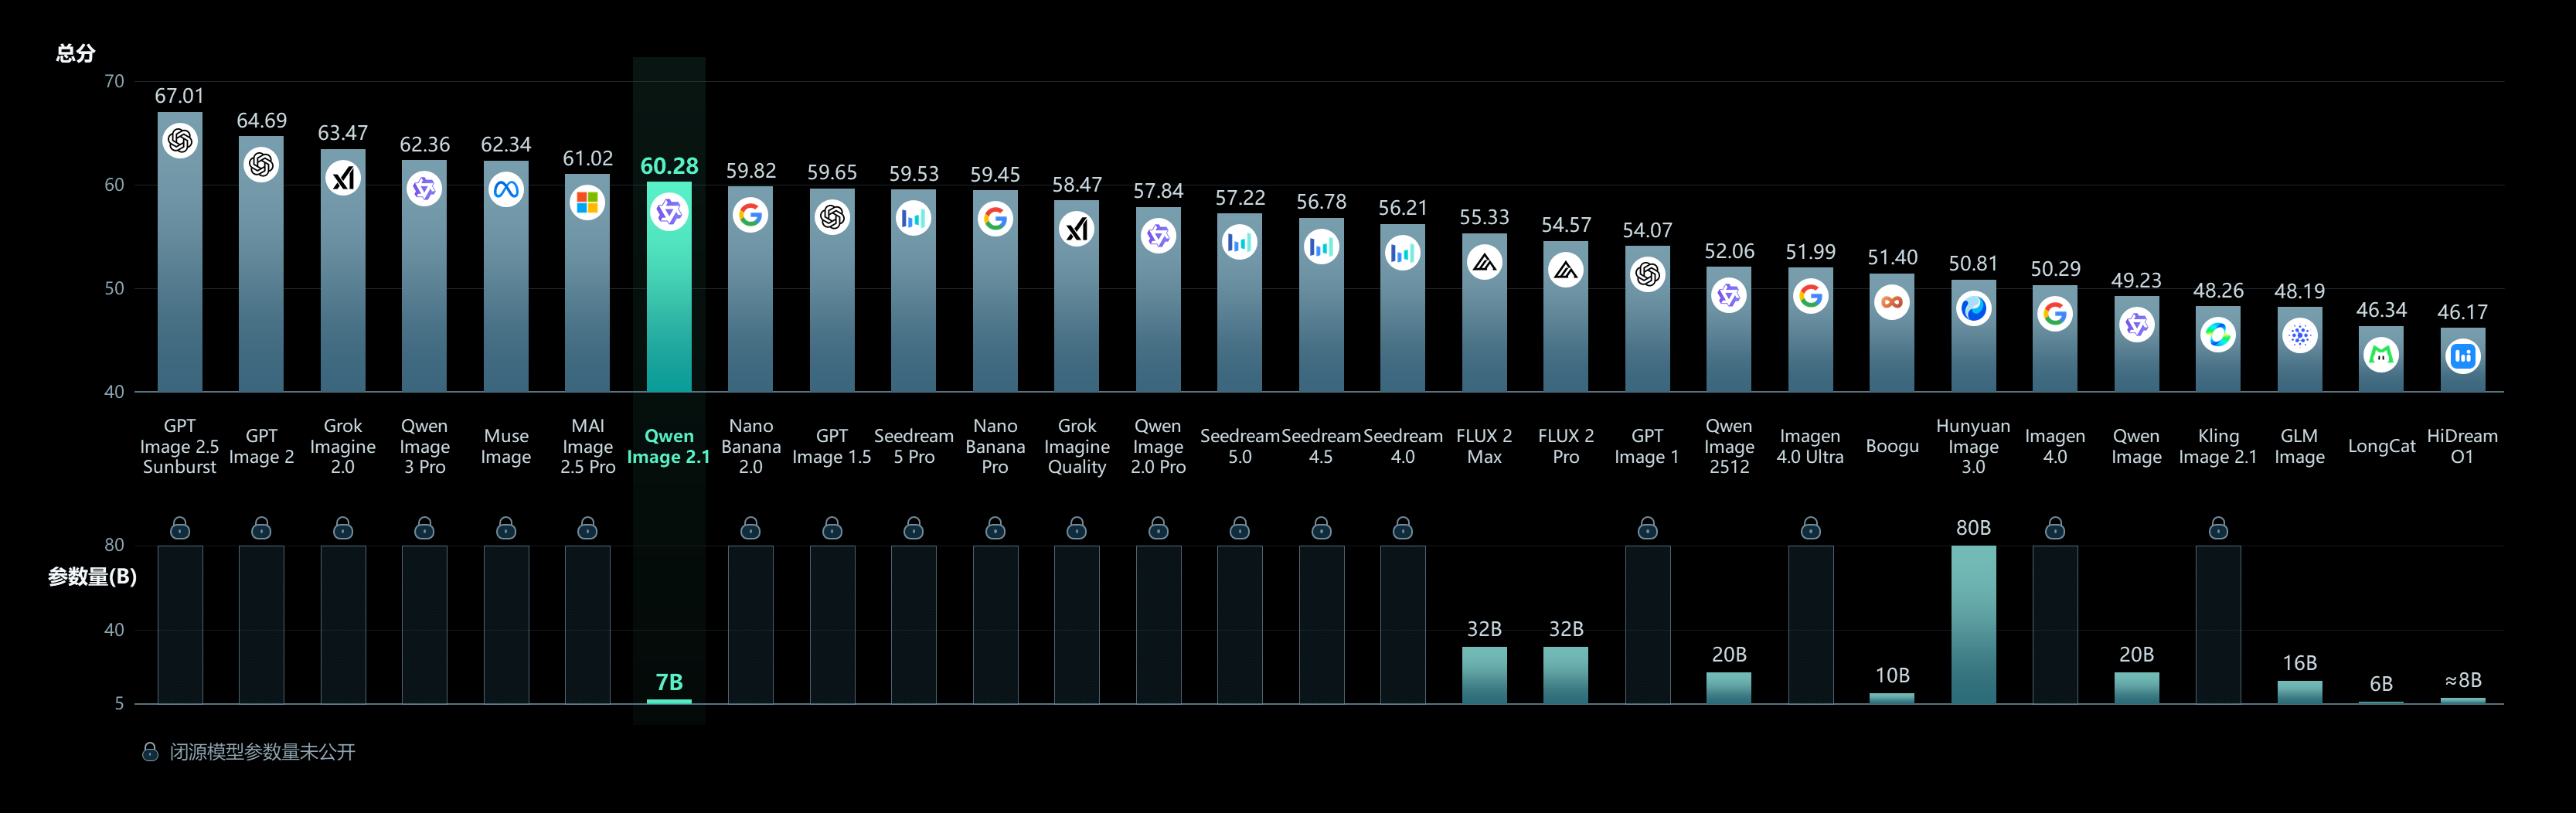
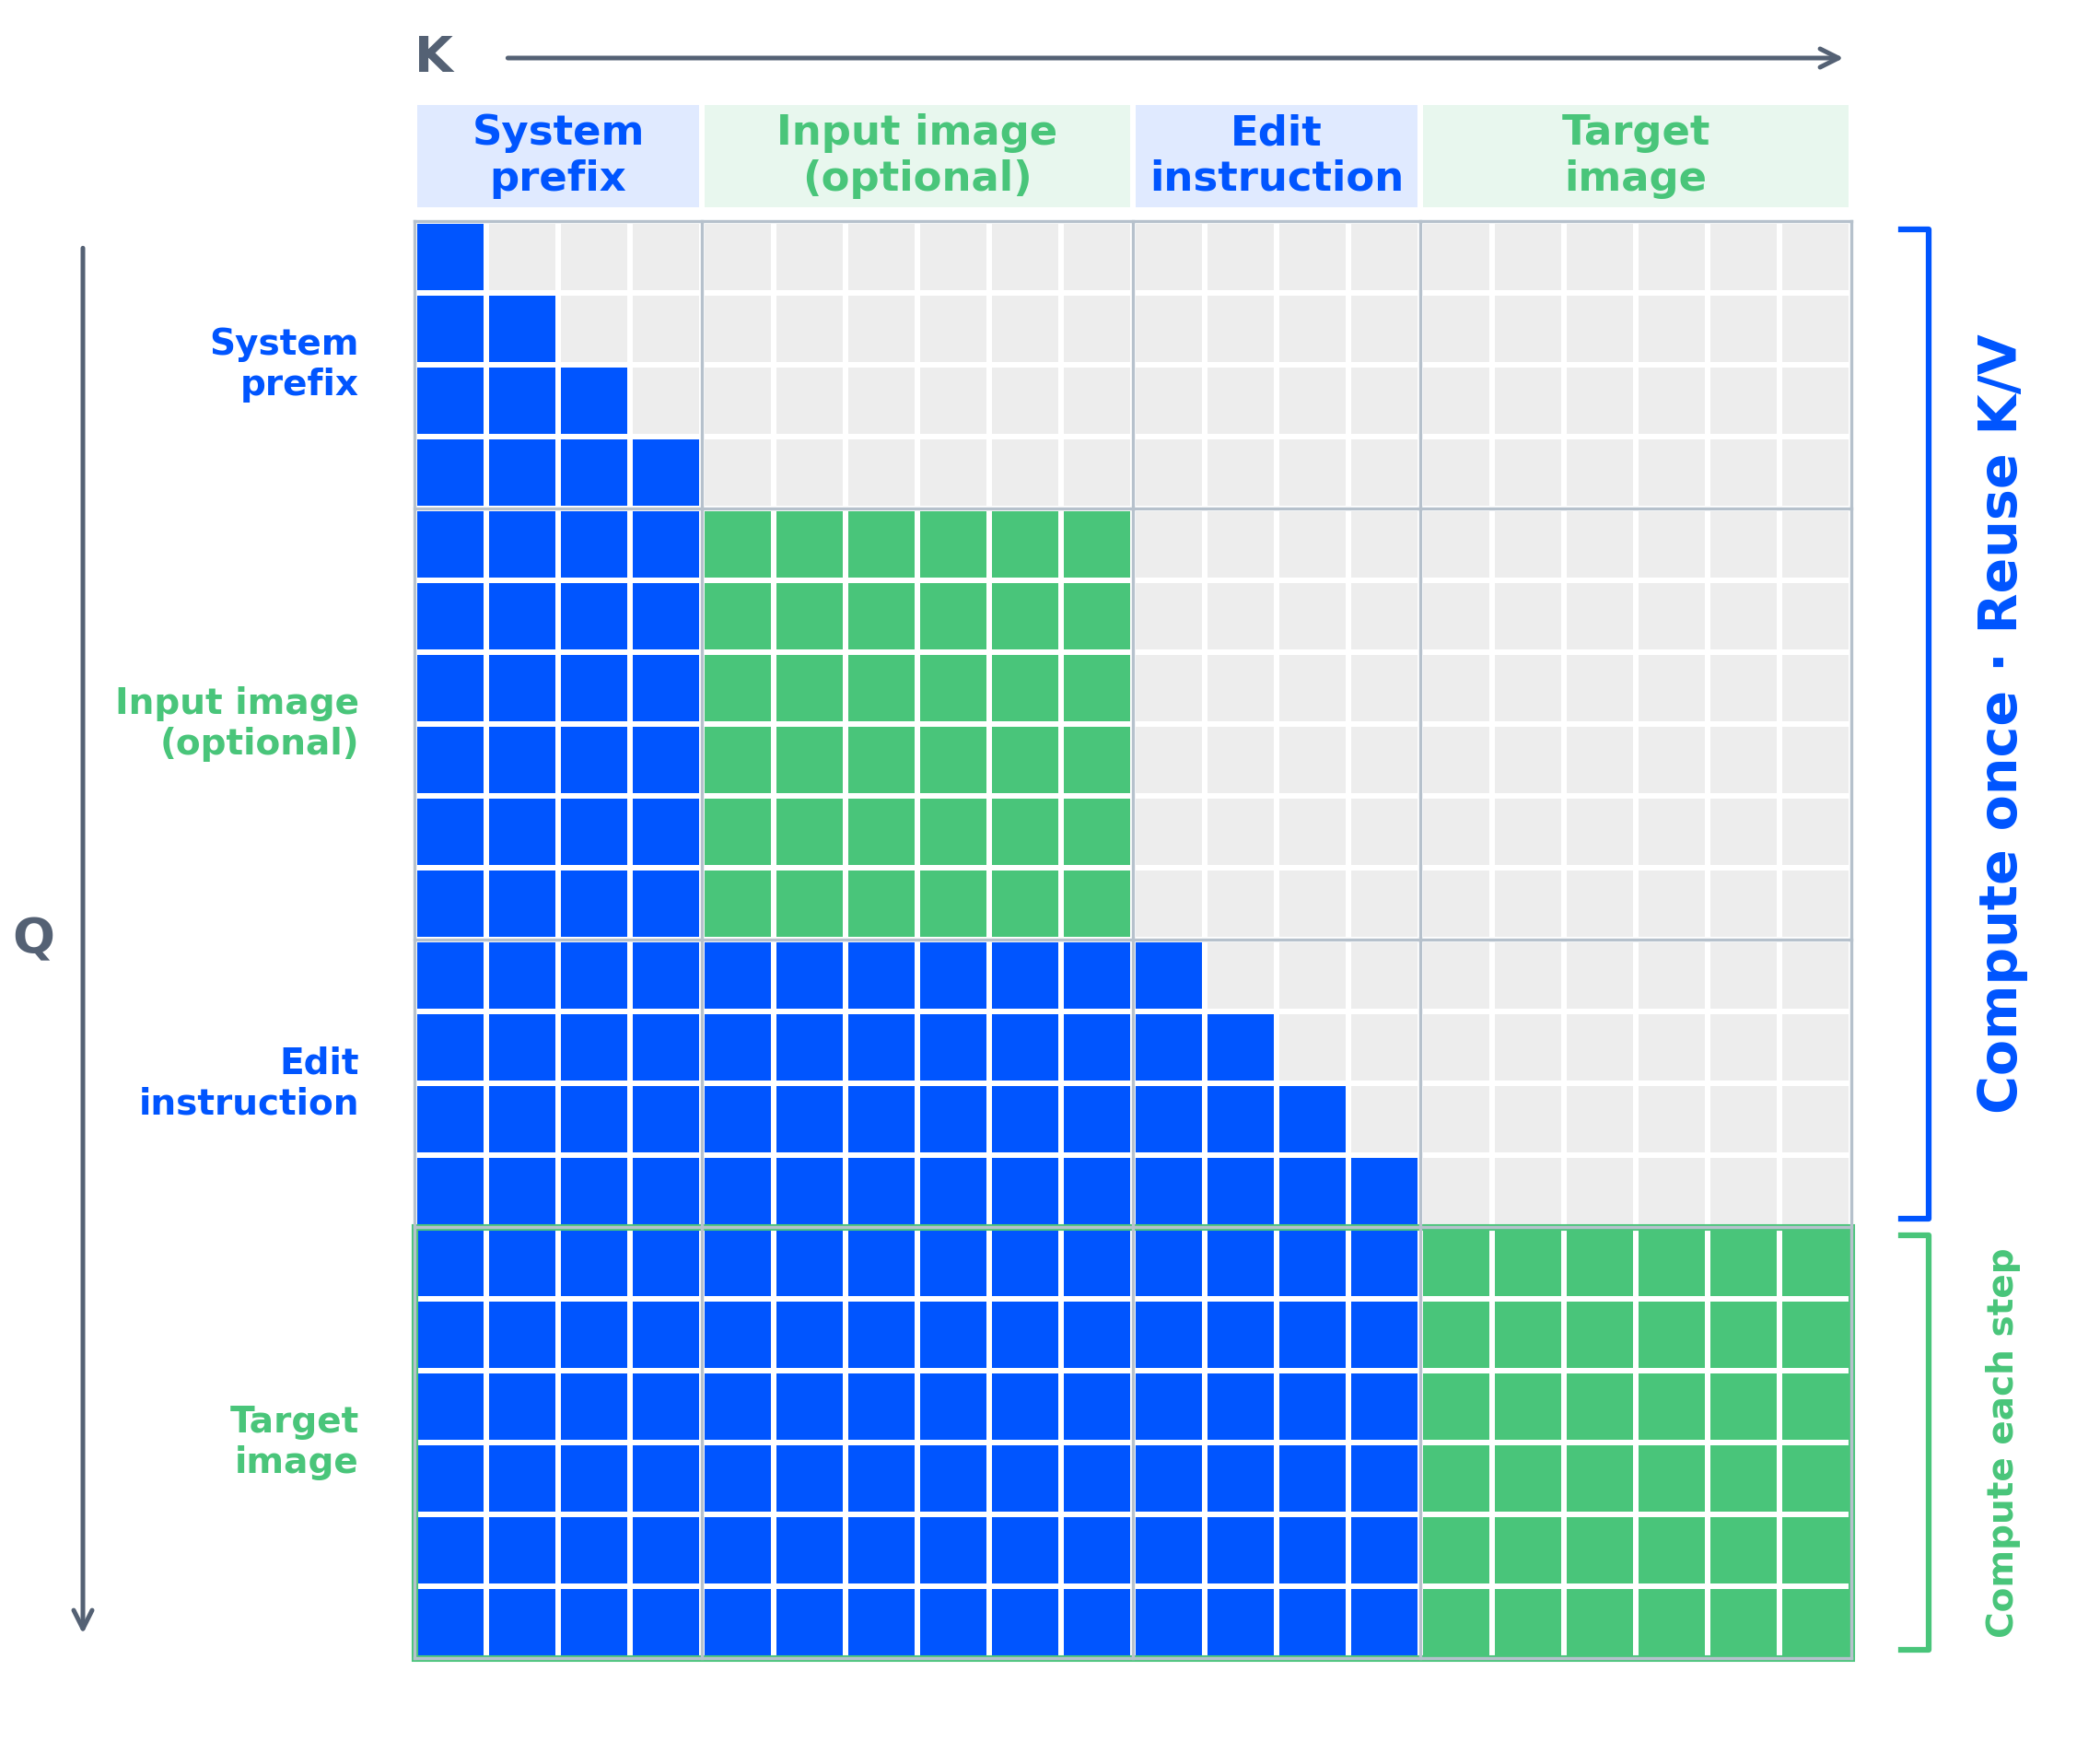
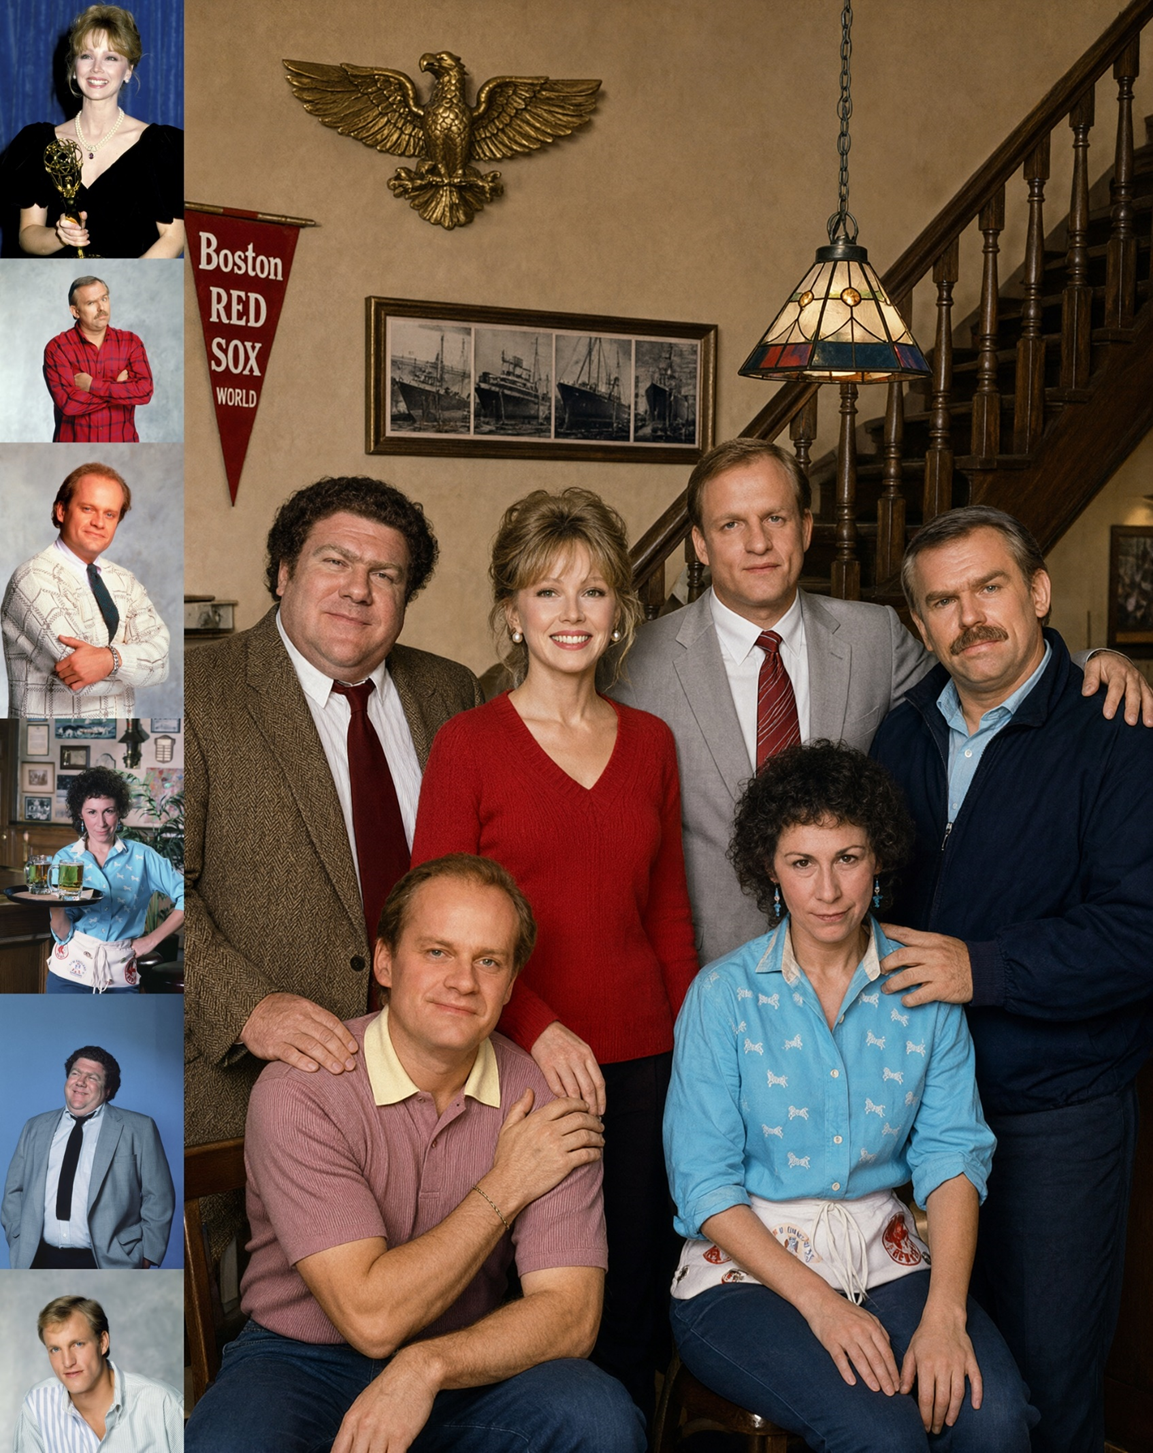
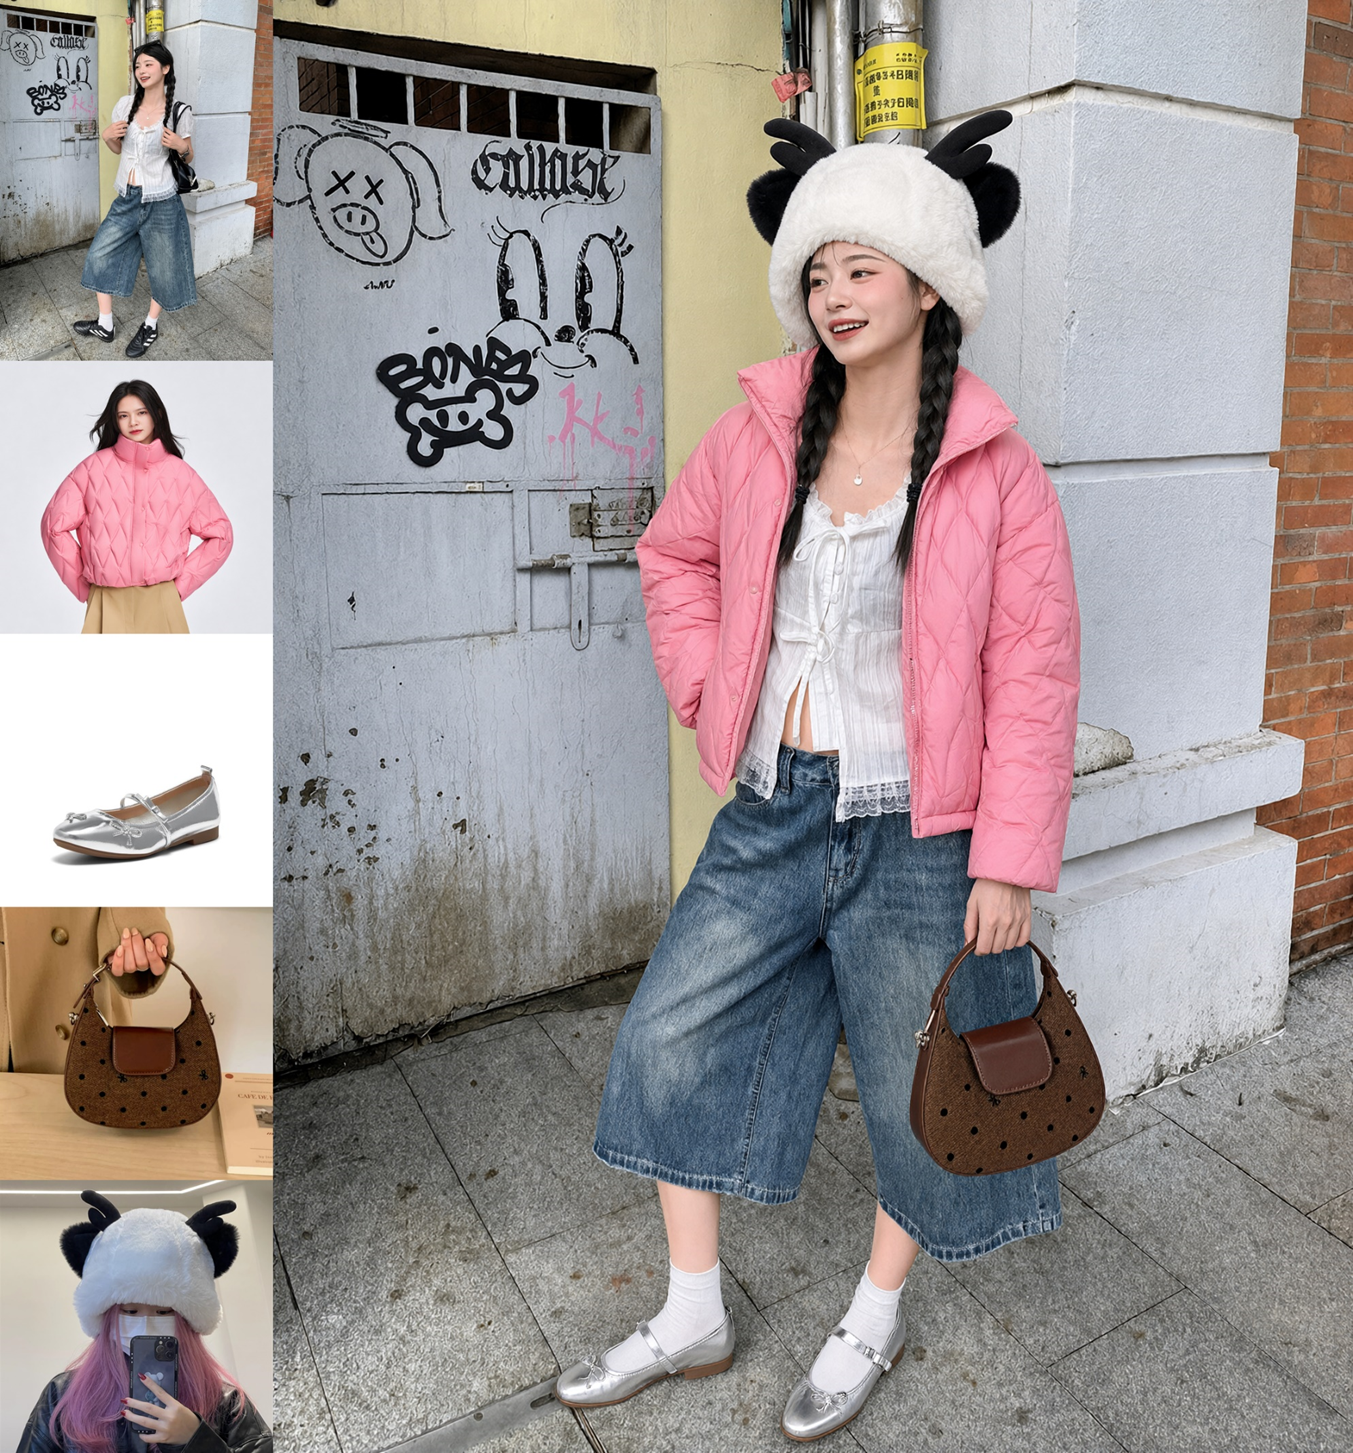
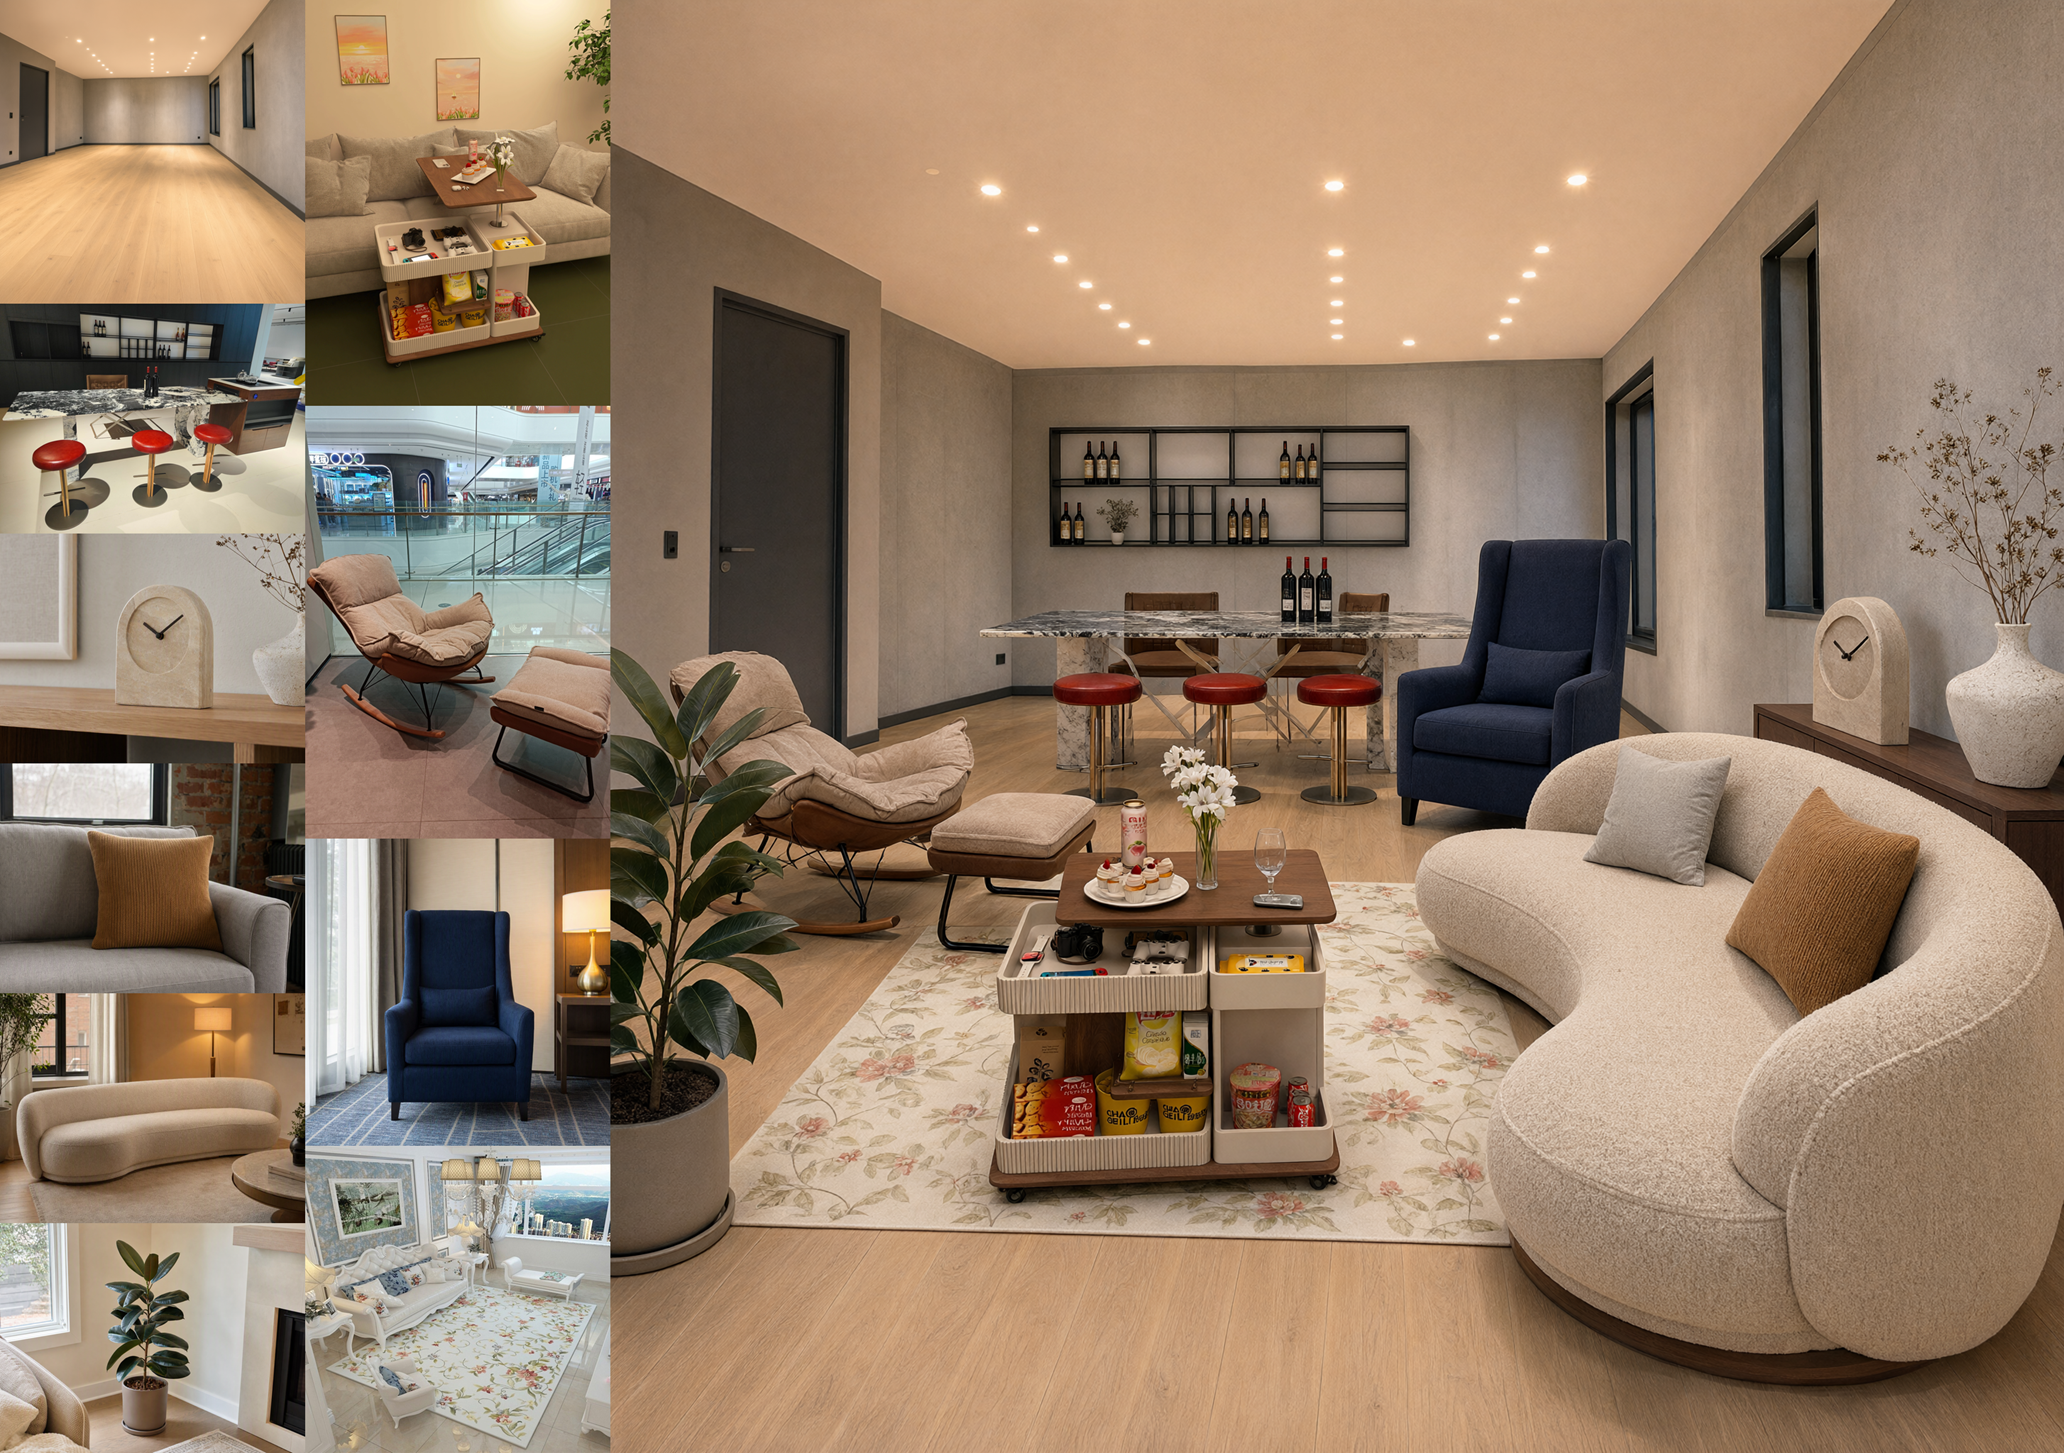
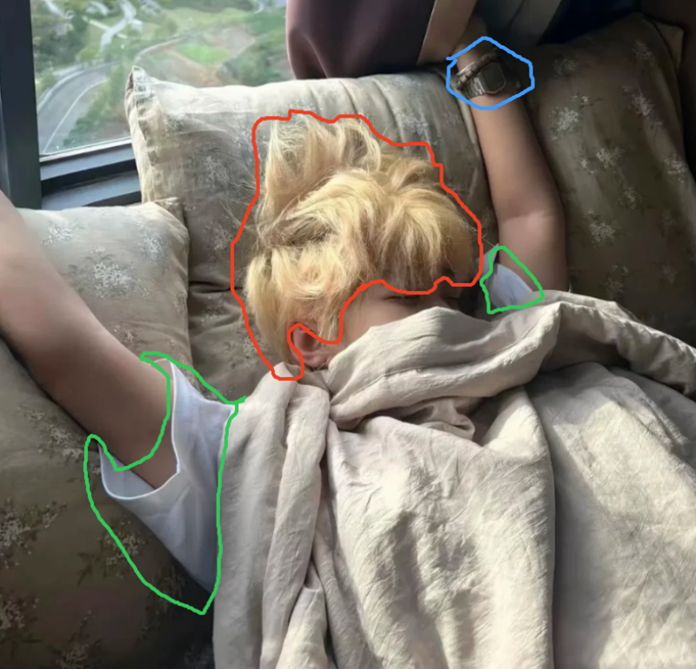
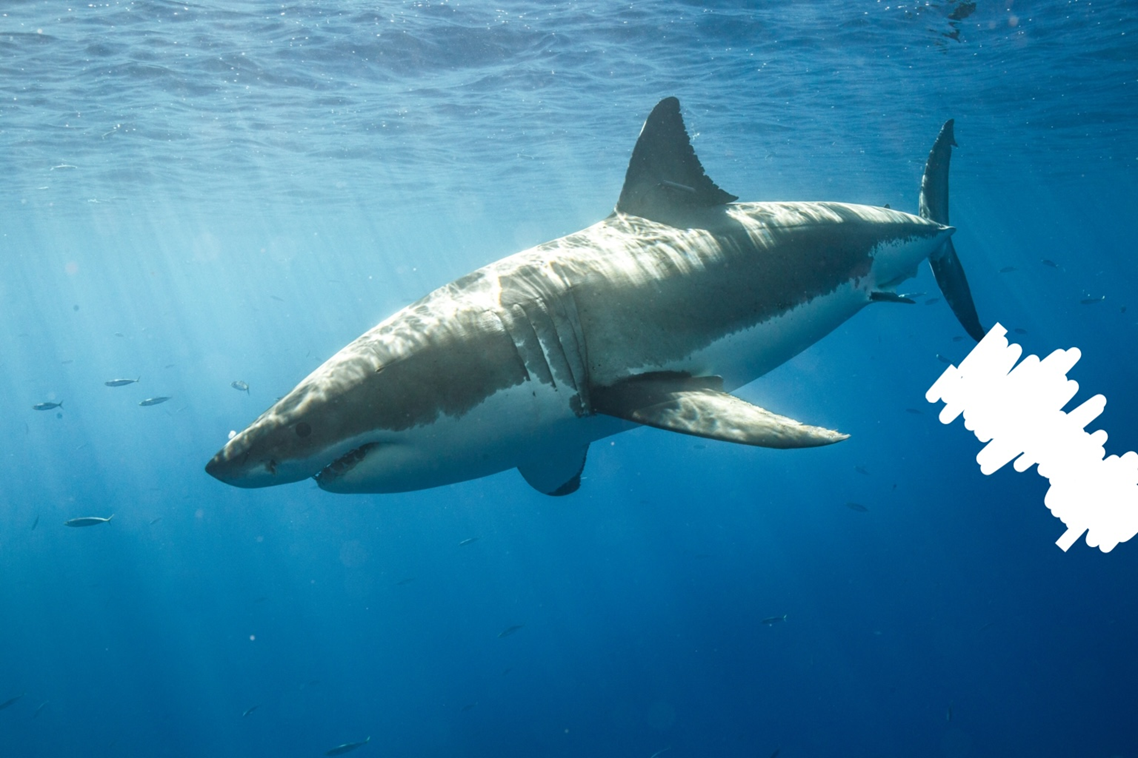
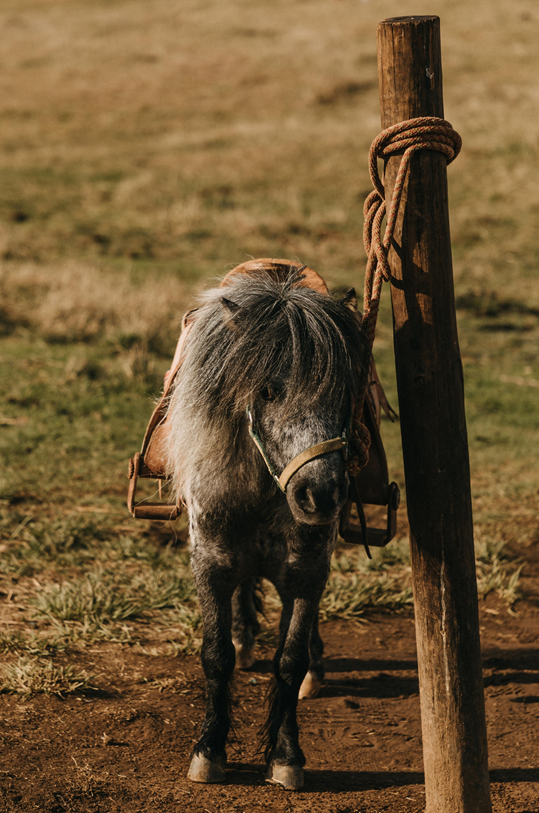
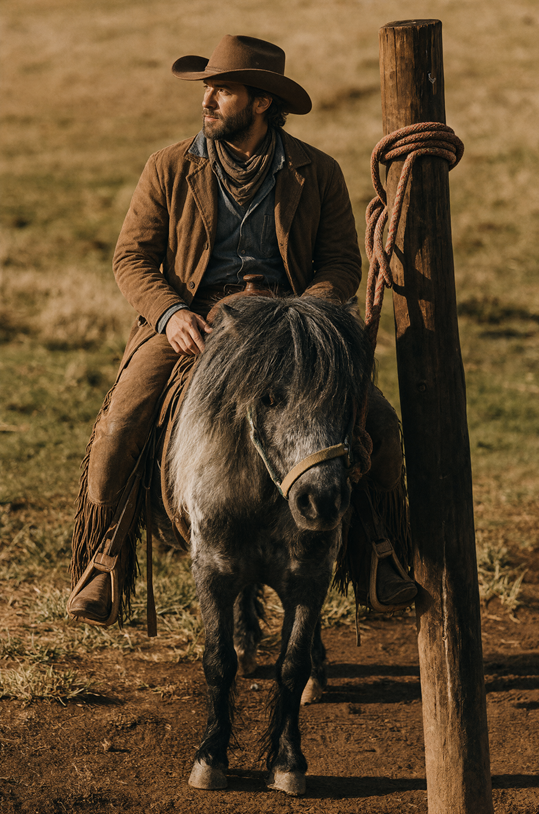
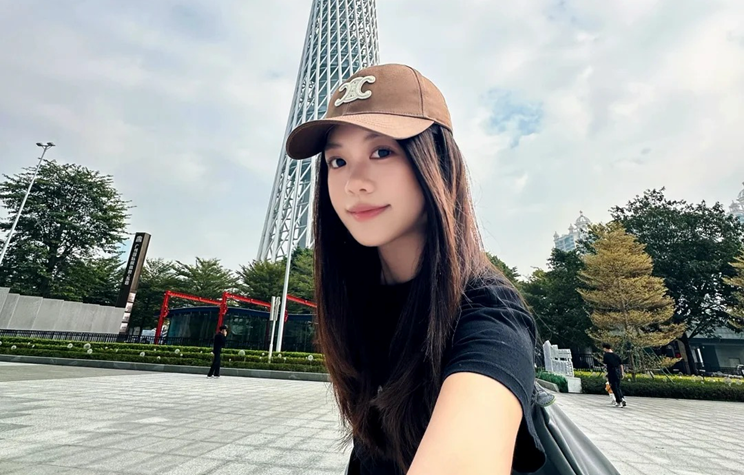
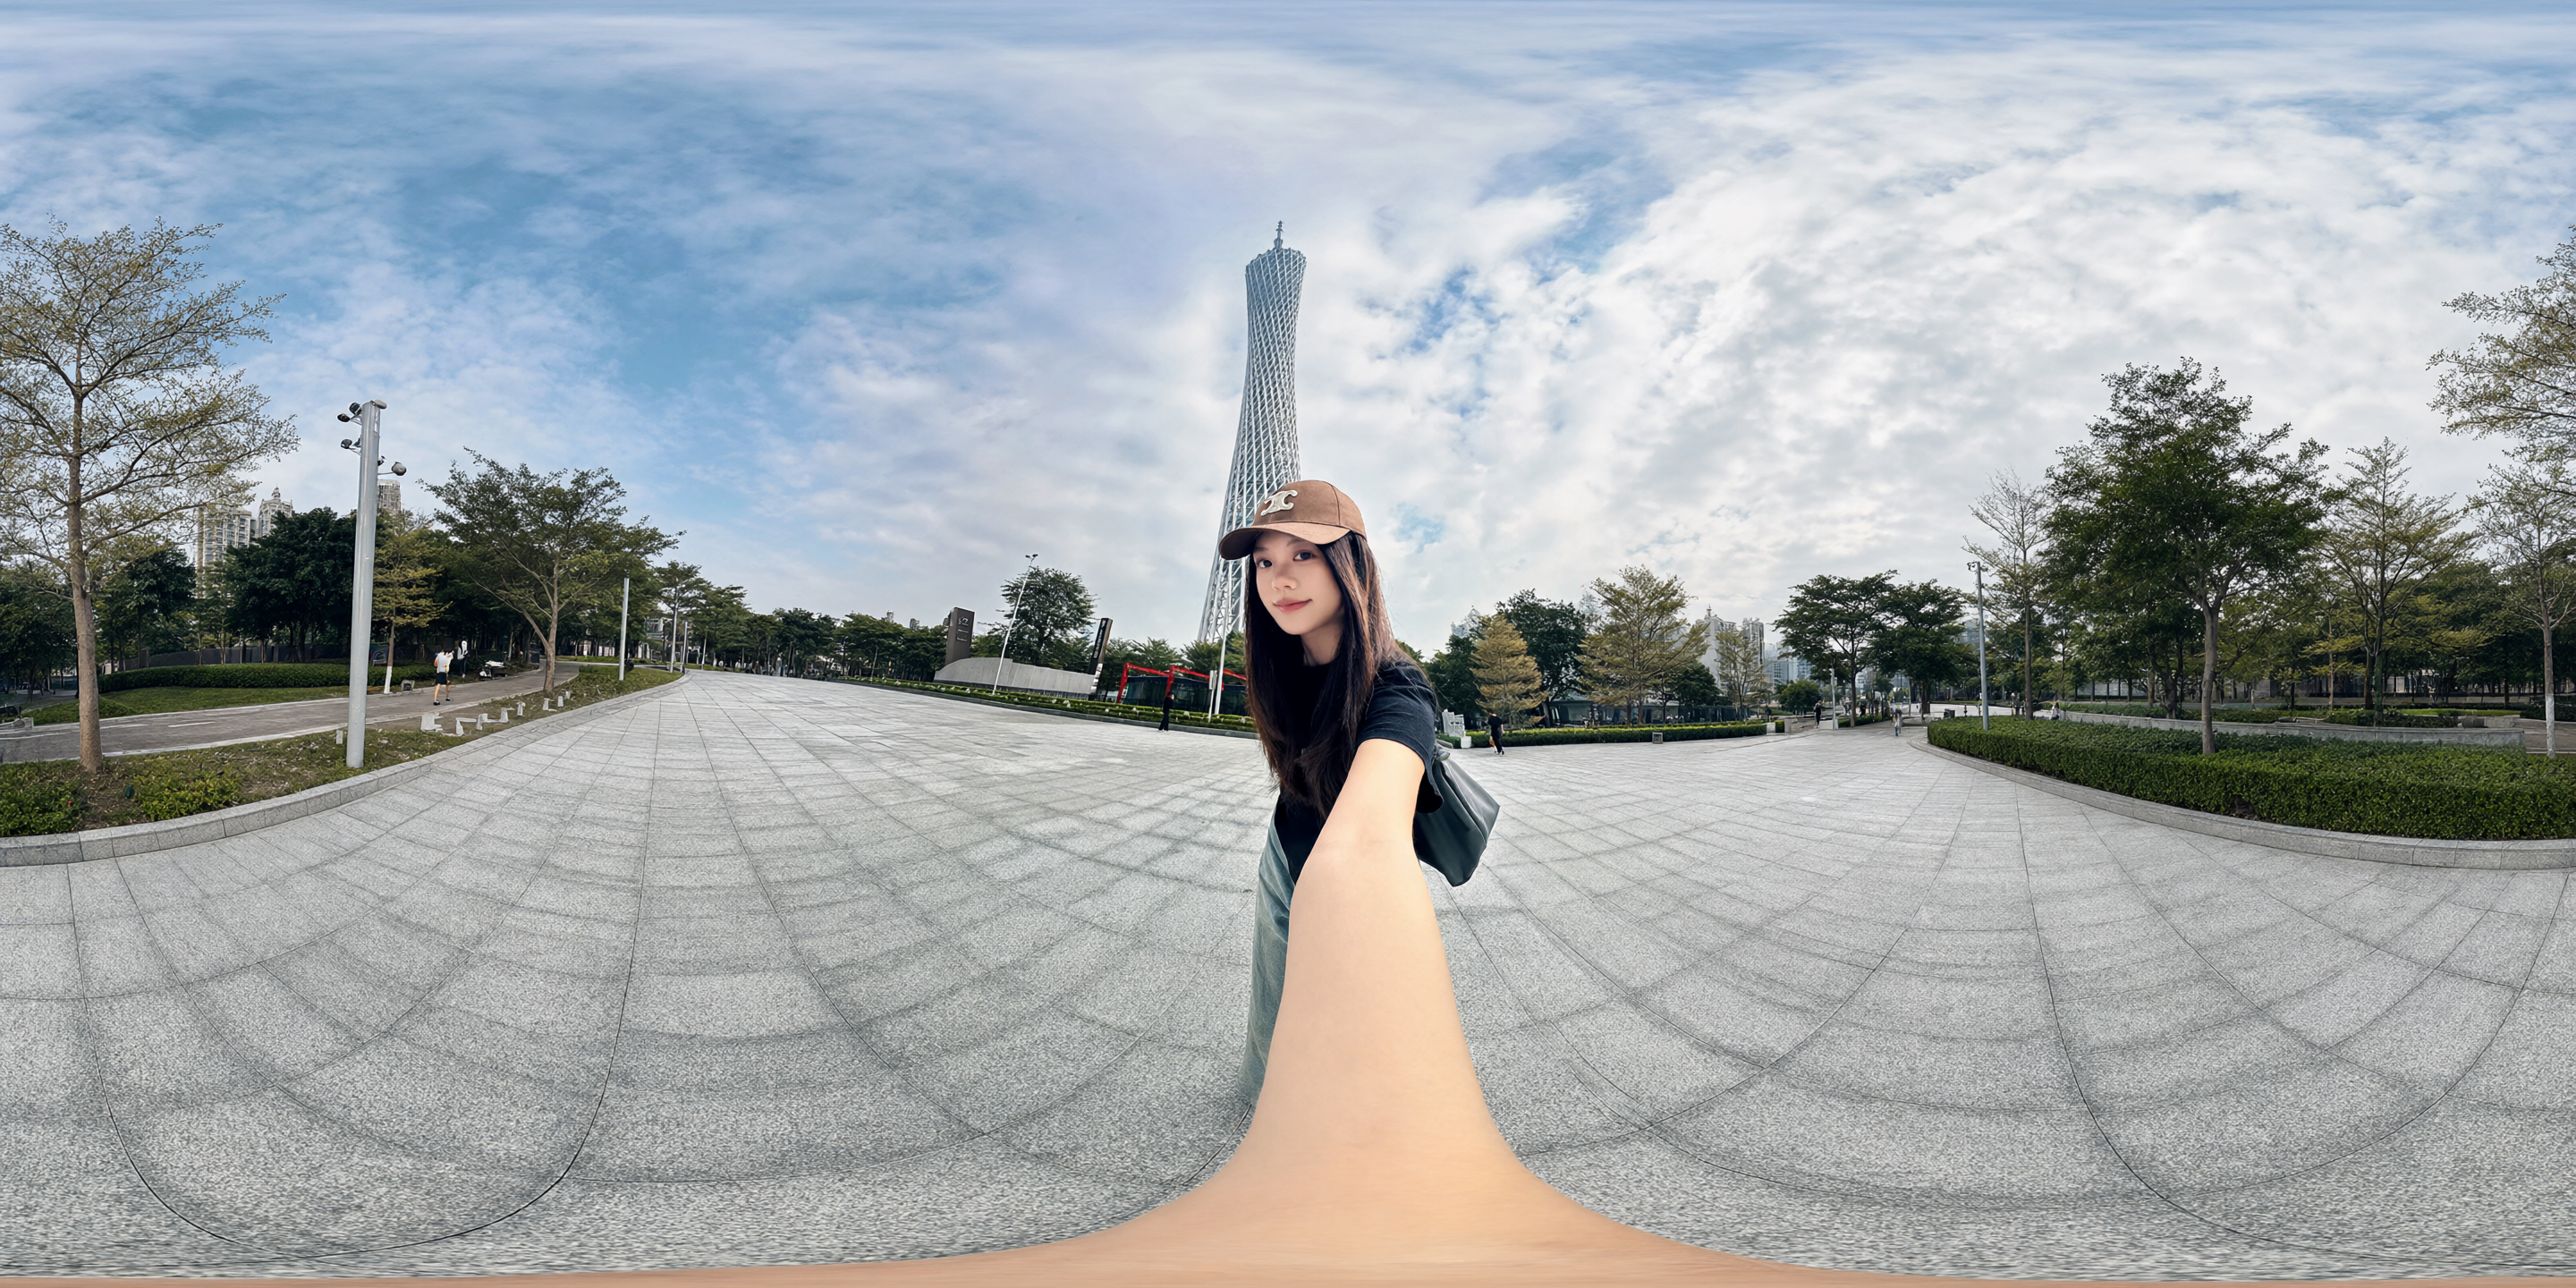
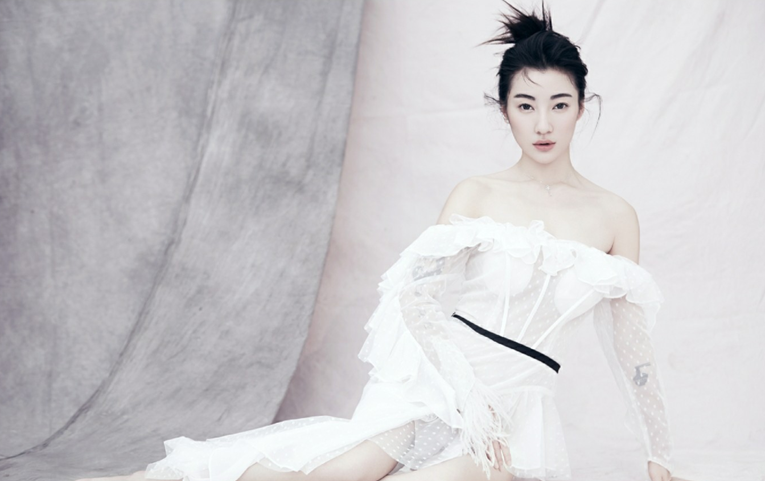
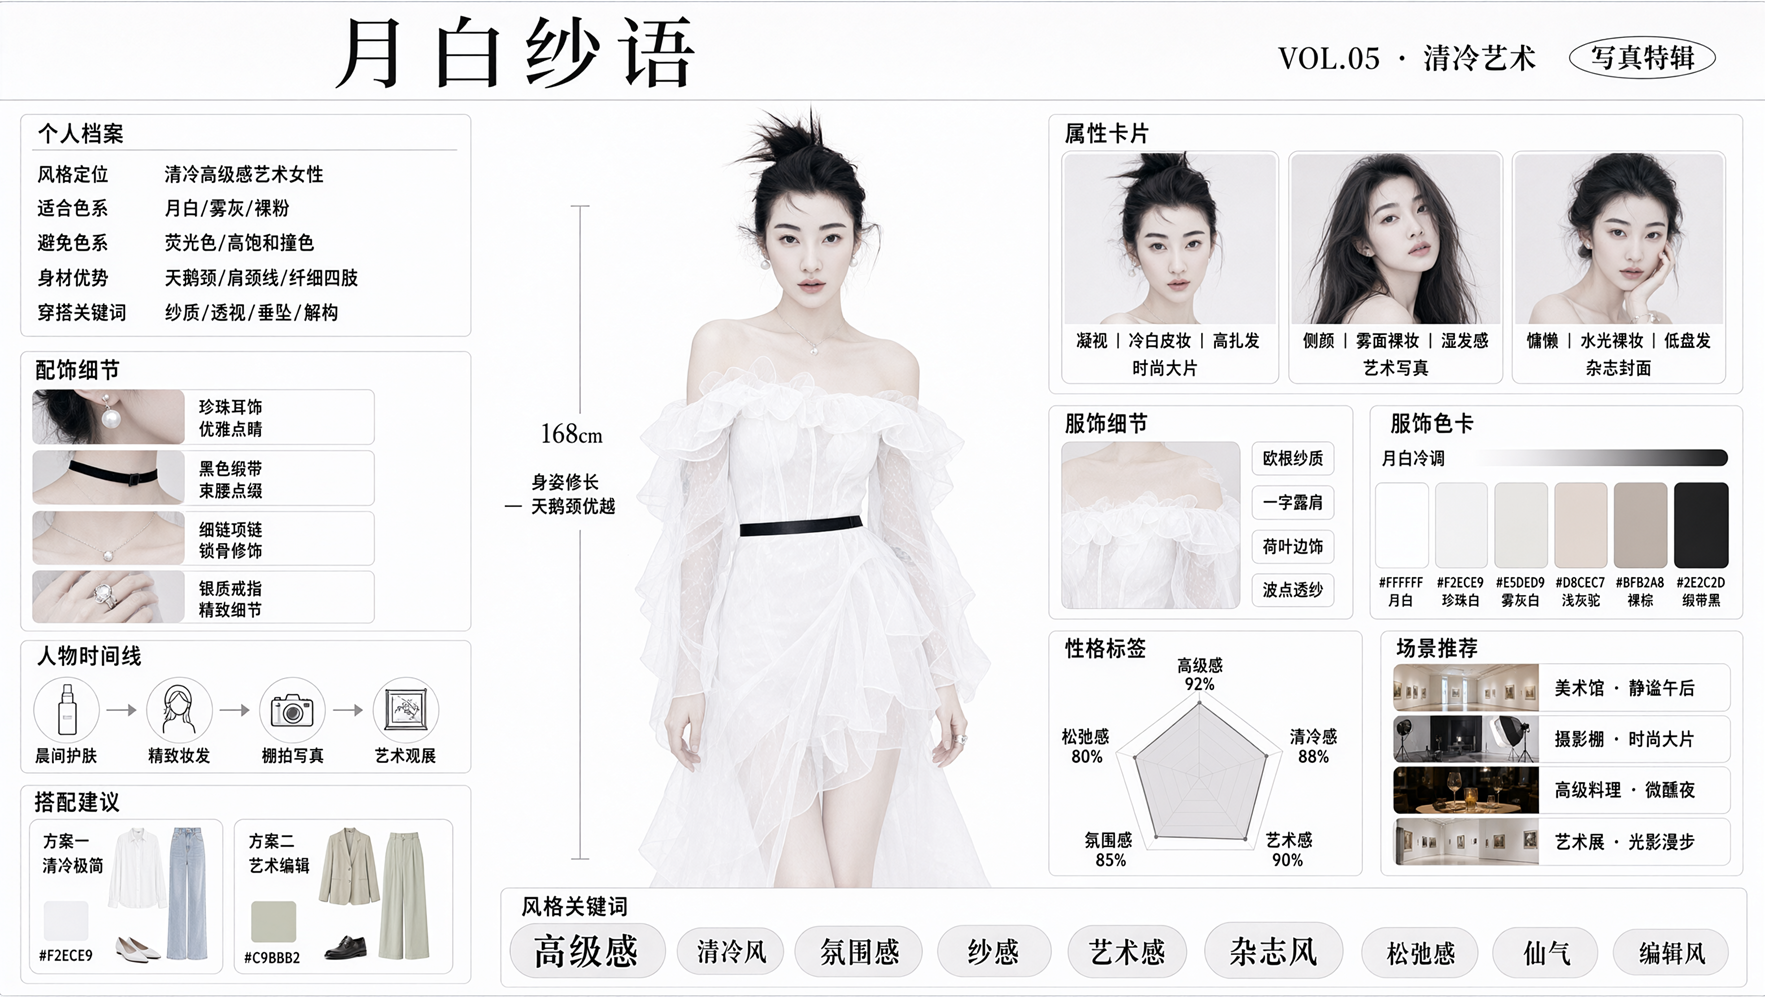
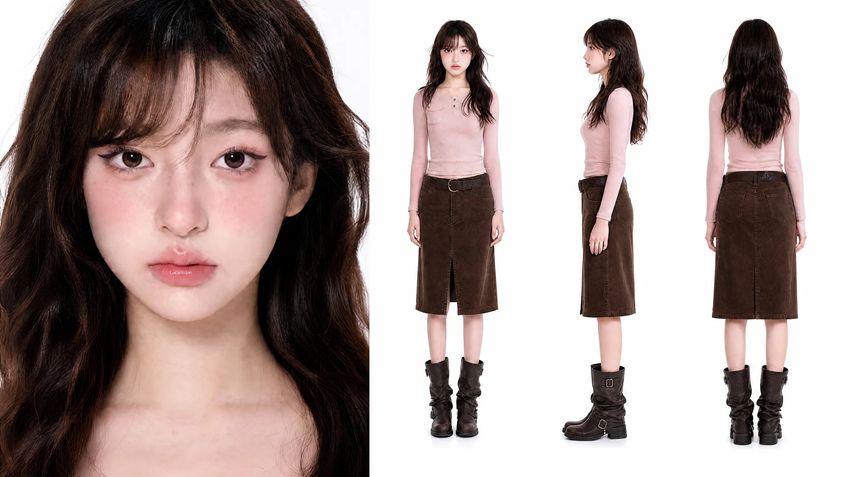
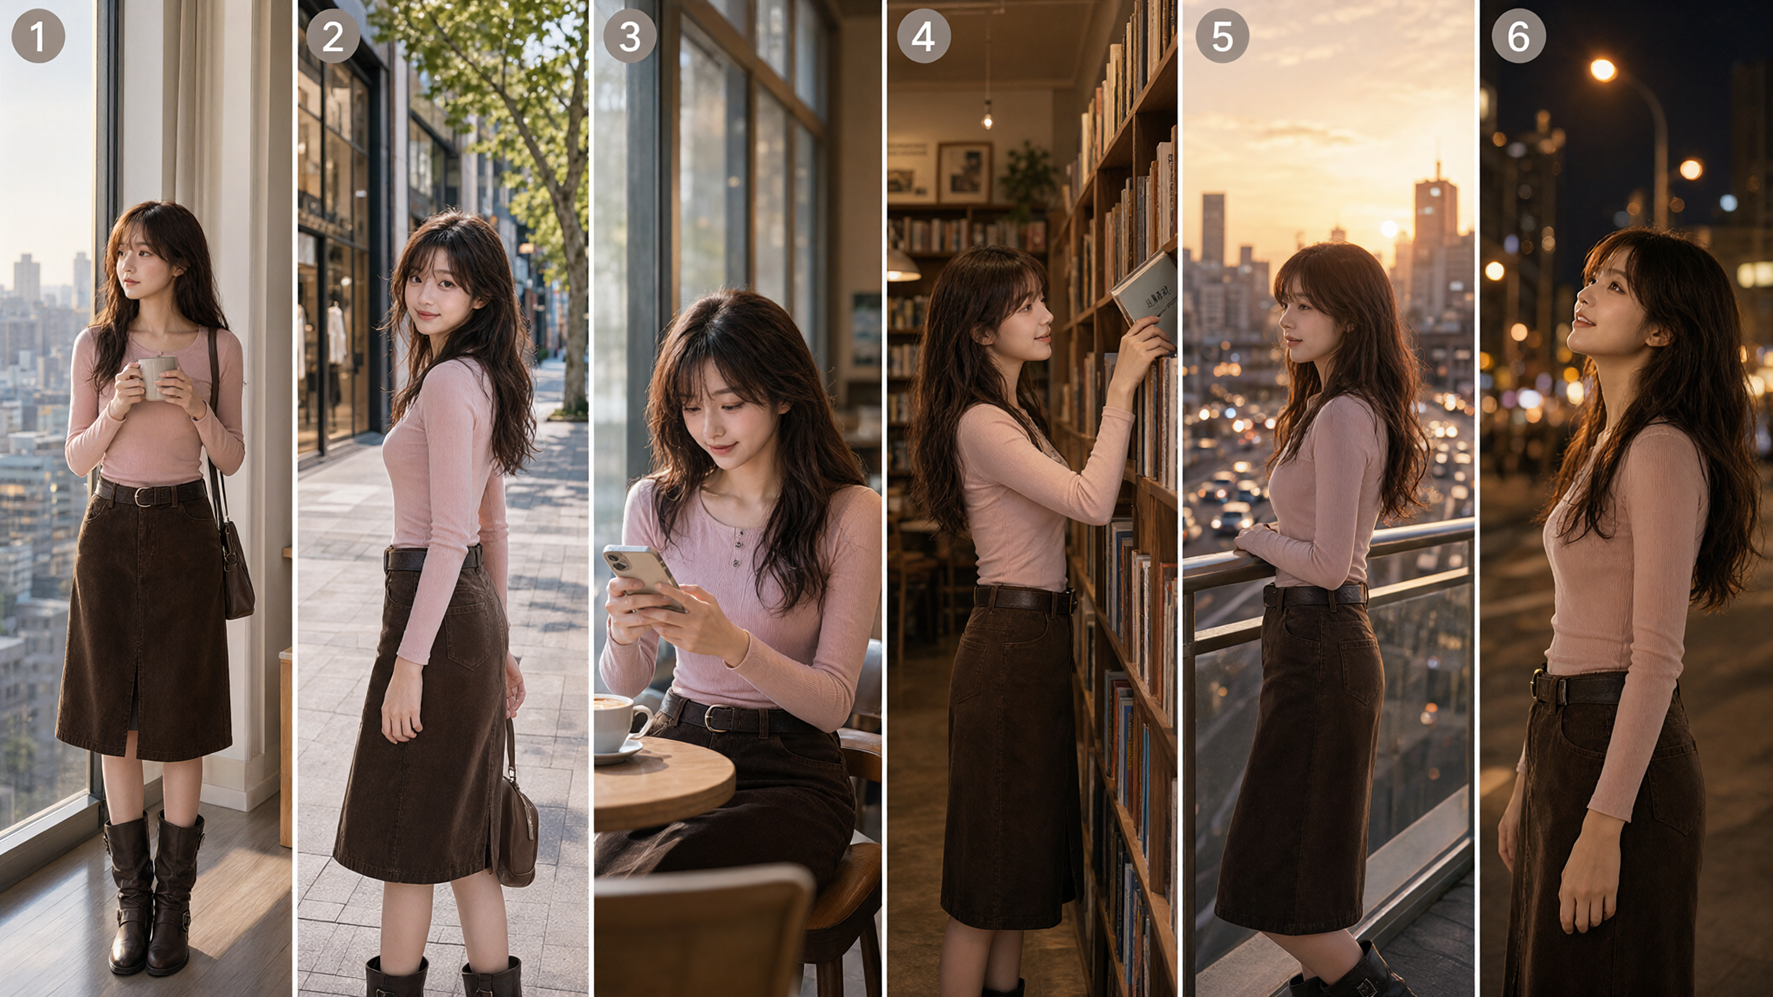
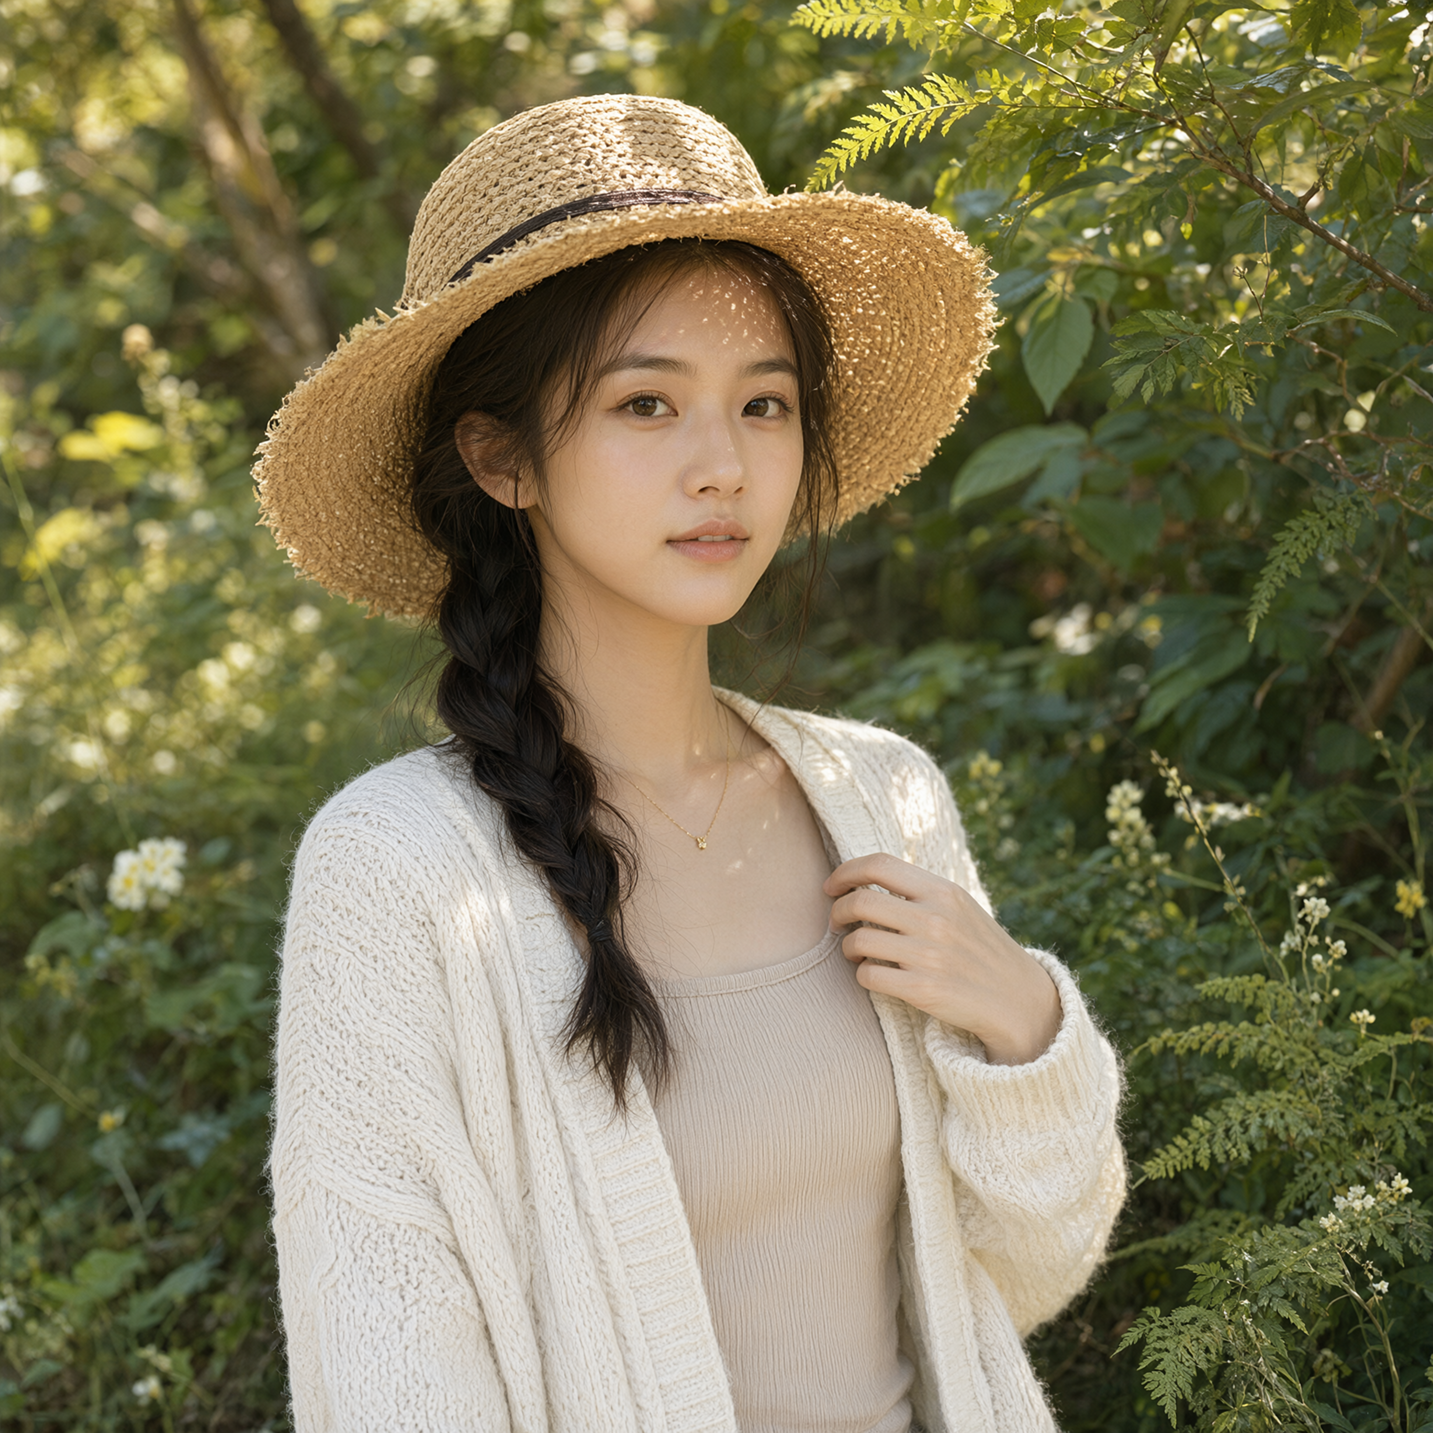
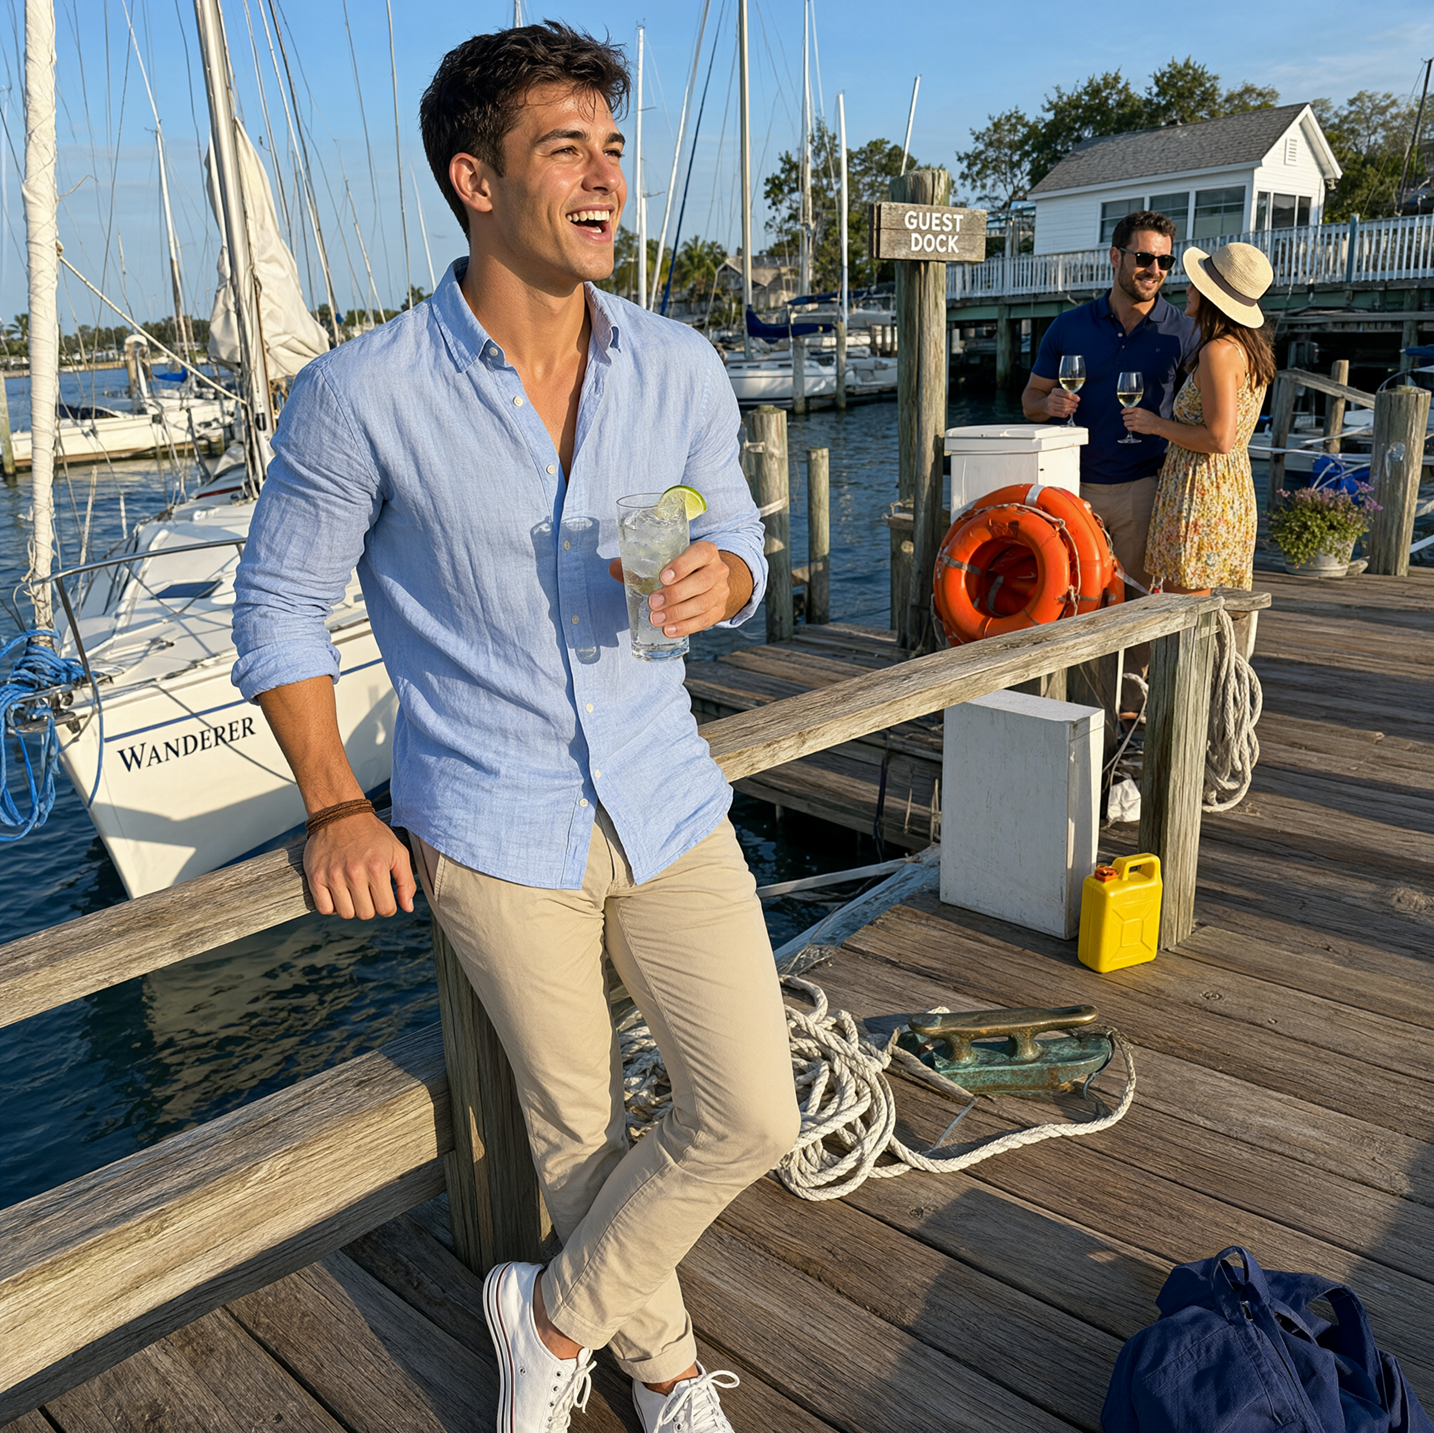
  "articleBody": "![Qwen-Image-2.1 banner](https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/banner_en.png)\n\n[GITHUB](https://github.com/QwenLM/Qwen-Image-2.1) [HUGGING FACE](https://huggingface.co/Qwen/Qwen-Image-2.1) [MODELSCOPE](https://www.modelscope.cn/models/Qwen/Qwen-Image-2.1)\n\nWe are excited to open-source **Qwen-Image-2.1**, an image model in the Qwen family that balances generation quality, inference efficiency, and cost. Qwen-Image-2.1 unifies text-to-image generation and image editing in a single model, with just **7B parameters in its visual generation component** and native support for generating and editing transparent images.\n\nThis update introduces four key improvements:\n\n- **Compact and efficient**: A lightweight architecture and inference optimizations balance image quality and computational cost.\n- **Native transparency, unified creation and editing**: Generate regular or transparent images from prompts, edit transparent layers, and extract subjects from photos.\n- **Versatile editing**: Use up to **10 reference images**, specify local edits, preserve people and products, and handle a wide range of tasks.\n- **Realistic textures and refined aesthetics**: Improved typography, portrait lighting, and fine details make generated images more visually compelling.\n\n## Compact and Efficient\n\nQwen-Image-2.1 uses a lightweight architecture. Its visual generation component contains **32 Single-Stream DiT layers and 7B parameters**. Despite its compact size, the model delivers strong image generation quality. The Qwen-Image-Bench comparison below shows its performance alongside other open-source and closed-source models.\n\n![Qwen-Image-Bench evaluation comparison](https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-01.png)\n\nQwen-Image-Bench evaluation comparison\n\nInference efficiency is another focus, particularly when editing with multiple input images. This optimization comes from a **mixed-granularity attention architecture**. Text, including the system prefix and editing instructions, uses a token-level causal mask, while image generation uses a chunk-level mask. **KV cache reuse** allows input images and editing instructions to serve as static context, computed and cached in the first step to improve inference efficiency and reduce memory usage.\n\n![Qwen-Image-2.1 mixed-granularity attention architecture](https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-03.png)\n\nQwen-Image-2.1 mixed-granularity attention architecture\n\n## Native Transparency, Unified Creation and Editing\n\nNative transparency is a major addition in this release. In December 2025, we introduced Qwen-Image-Layered as a dedicated model supporting transparent image generation. Qwen-Image-2.1 now integrates this capability into a unified model, using the prompt to determine whether to output a regular image or an image with a transparency channel.\n\nHere are examples of transparent images generated directly from text:\n\n![Transparent images generated from text (1)](https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-04.png) ![Transparent images generated from text (2)](https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-05.png) ![Transparent images generated from text (3)](https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-06.png)\n\nBeyond individual subjects, the model can generate more complex transparent images composed of multiple elements, opening up further possibilities for design and asset creation.\n\n![Transparent compositions with multiple elements (1)](https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-07.png) ![Transparent compositions with multiple elements (2)](https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-08.png?v=cac12076c2cd)\n\nBy unifying generation and editing, Qwen-Image-2.1 also supports editing transparent images directly. For example, it can change a subject’s expression while retaining the transparent background. The input is on the left and the edited result on the right.\n\n![Expression editing on a transparent image: input and result (1)](https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-09.png?v=ee4de1b5241d) ![Expression editing on a transparent image: input and result (2)](https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-10.png?v=611bf03abb39)\n\nText within a transparent layer can also be edited. In the following example, “BLOOM” is replaced with “Qwen-Image”.\n\n![Transparent text editing: replacing BLOOM with Qwen-Image (1)](https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-11.png?v=1f2803db504a) ![Transparent text editing: replacing BLOOM with Qwen-Image (2)](https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-12.png?v=9d0fa2b0e13a)\n\nThis capability extends to real photographs. Given an RGB image, the model can extract the desired subject as an RGBA layer with transparency, making it easier to reuse elements in subsequent design and composition work.\n\n![Extracting a transparent RGBA layer from an RGB photograph (1)](https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-13.png) ![Extracting a transparent RGBA layer from an RGB photograph (2)](https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-14.png)\n\n## Versatile Editing\n\nQwen-Image-2.1 improves editing in four areas: multiple reference images, local editing, fidelity preservation, and task coverage.\n\n### Multiple References: Up to 10 Input Images\n\nQwen-Image-2.1 supports **up to 10 reference images**, combining multiple subjects and assets into a coherent composition. In the group portrait example below, six individual portraits on the left are brought together in one photograph.\n\n![A group photograph generated from six portrait references](https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-15.png)\n\nA group photograph generated from six portrait references\n\nFor virtual try-on, five inputs—a model, clothing, shoes, a bag, and a hat—can be combined into a complete outfit.\n\n![A complete outfit generated from five reference images](https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-16.png)\n\nA complete outfit generated from five reference images\n\nFor interior design, the model can use 10 images of furnishings to generate a complete room arrangement.\n\n![An interior generated from ten furnishing references](https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-17.png)\n\nAn interior generated from ten furnishing references\n\n### Local Editing: Flexible Region Selection\n\nQwen-Image-2.1 supports circles, painted annotations, and separate masks to specify where an edit should take place.\n\nThe first example uses circles of different colors to identify three regions at once: “Remove the metal watch in the blue circle, change the hair in the red circle to black, and replace the area in the green circle with gray short-sleeved linen pajamas.” The annotated input is on the left, and the result is on the right.\n\n![Circle-guided editing of a watch, hair, and clothing (1)](https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-18.png) ![Circle-guided editing of a watch, hair, and clothing (2)](https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-19.png)\n\nPainted annotations provide another way to identify a region. In this example, the model adds a diver to the area marked in white on the right side of the input image.\n\n![Paint-guided editing: adding a diver to the marked region (1)](https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-20.png) ![Paint-guided editing: adding a diver to the marked region (2)](https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-21.png)\n\nCircles and painted annotations obscure some of the original content. To preserve the complete input, Qwen-Image-2.1 also accepts **the original image and a separate mask as two inputs**. The following example asks the model to generate a cowboy on horseback, using these two images:\n\n![Local editing inputs: original image and separate mask (1)](https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-22.png) ![Local editing inputs: original image and separate mask (2)](https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-23.png)\n\nThe model edits the region specified by the mask, producing the following result:\n\n![Mask-guided editing result: a cowboy on horseback](https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-24.png)\n\nMask-guided editing result: a cowboy on horseback\n\nLocal editing can also support sequential creation. By making successive changes while preserving the rest of the scene, edited images can be assembled into simple animations, as illustrated by the capybara Calabash Brothers example below.\n\n[Capybara Calabash Brothers: animation through successive local edits](https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/videos/hulu_final_48f_6fps.mp4)\n\n### Fidelity: Preserving People and Products\n\nFidelity improvements focus on **portrait identity** and **product consistency**. For portraits, the model better preserves facial features so that a person’s identity remains more consistent across edits. Each pair below shows the input on the left and the edited result on the right.\n\n![Portrait fidelity example one: input and result (1)](https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-25.png) ![Portrait fidelity example one: input and result (2)](https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-26.png)\n\n![Portrait fidelity example two: input and result (1)](https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-27.png) ![Portrait fidelity example two: input and result (2)](https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-28.png)\n\n![Portrait fidelity example three: input and result (1)](https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-29.png) ![Portrait fidelity example three: input and result (2)](https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-30.png)\n\nFor product editing, the model aims to preserve text, textures, and shape, keeping the product’s defining features consistent in a new image.\n\n![Product fidelity example one: input and result (1)](https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-31.png) ![Product fidelity example one: input and result (2)](https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-32.png)\n\n![Product fidelity example two: input and result (1)](https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-33.png) ![Product fidelity example two: input and result (2)](https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-34.png)\n\n![Product fidelity example three: input and result (1)](https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-35.png) ![Product fidelity example three: input and result (2)](https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-36.png)\n\n### Task Coverage: Panoramas, Infographics, and Storyboards\n\nQwen-Image-2.1 supports a broad range of editing tasks, including panorama, infographic, and storyboard generation, balancing capabilities across different applications.\n\nFor example, starting from this selfie:\n\n![Input selfie for panorama generation](https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-37.png)\n\nInput selfie for panorama generation\n\nThe model generates the following panorama:\n\n![Panorama generated from the selfie](https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-38.png)\n\nPanorama generated from the selfie\n\nThe panorama can then be explored from different viewing directions in a visualization tool.\n\n[Panorama visualization demonstration](https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/videos/pano_video2_10s_noaudio.mp4)\n\nFor infographic generation, a model photograph can be expanded into a detailed, information-rich composition.\n\n![Input model photograph for infographic generation](https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-39.png)\n\nInput model photograph for infographic generation\n\n![Complex infographic generated from the model photograph](https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-40.png)\n\nComplex infographic generated from the model photograph\n\nThe model can also turn a three-view character reference into a complete storyboard, providing material for storytelling and visual narratives.\n\n![Three-view character reference for storyboard generation](https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-41.png)\n\nThree-view character reference for storyboard generation\n\n![Complete storyboard generated from the character reference](https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-42.png)\n\nComplete storyboard generated from the character reference\n\n## Realistic Textures and Refined Aesthetics\n\nQwen-Image-2.1 further improves visual quality, with particular attention to typography and portraits. Text rendering considers not only the content itself, but also type styles, layout, and their relationship to the overall composition. The following examples showcase text rendering across different settings.\n\n![Text rendering example one](https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-43.png)\n\nText rendering example one\n\n![Text rendering example two](https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-44.png)\n\nText rendering example two\n\n![Text rendering example three](https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-45.png)\n\nText rendering example three\n\n![Text rendering example four](https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-46.png)\n\nText rendering example four\n\nFor portraits, improved lighting and fine details give generated images a more realistic appearance.\n\n![Portrait lighting and detail example one](https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-47.png)\n\nPortrait lighting and detail example one\n\n![Portrait lighting and detail example two](https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-48.png)\n\nPortrait lighting and detail example two\n\n## Conclusion\n\nWith a compact 7B visual generation component, Qwen-Image-2.1 brings image generation, transparency, and a wide range of editing capabilities together in one model. Faster inference, support for up to 10 reference images, flexible local editing, and improved fidelity for people and products make it a practical tool for design, content creation, e-commerce, and visual storytelling.\n\nWe hope you enjoy creating with Qwen-Image-2.1!\n",
  "authors": [
    "QwenTeam"
  ],
  "captured_at": "2026-10-19T01:26:53.998049939+00:00",
  "category": "ai",
  "content_html": "<p><picture class=\"article-picture article-picture-fallback\" style=\"--image-ratio:16 / 9\"><img src=\"https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/banner_en.png\" alt=\"Qwen-Image-2.1 banner\" loading=\"eager\" decoding=\"async\" fetchpriority=\"high\" referrerpolicy=\"no-referrer\" class=\"progressive-image\"></picture></p>\n<p><a target=\"_blank\" rel=\"noopener noreferrer\" href=\"https://github.com/QwenLM/Qwen-Image-2.1\">GITHUB</a> <a target=\"_blank\" rel=\"noopener noreferrer\" href=\"https://huggingface.co/Qwen/Qwen-Image-2.1\">HUGGING FACE</a> <a target=\"_blank\" rel=\"noopener noreferrer\" href=\"https://www.modelscope.cn/models/Qwen/Qwen-Image-2.1\">MODELSCOPE</a></p>\n<p>We are excited to open-source <strong>Qwen-Image-2.1</strong>, an image model in the Qwen family that balances generation quality, inference efficiency, and cost. Qwen-Image-2.1 unifies text-to-image generation and image editing in a single model, with just <strong>7B parameters in its visual generation component</strong> and native support for generating and editing transparent images.</p>\n<p>This update introduces four key improvements:</p>\n<ul>\n<li><strong>Compact and efficient</strong>: A lightweight architecture and inference optimizations balance image quality and computational cost.</li>\n<li><strong>Native transparency, unified creation and editing</strong>: Generate regular or transparent images from prompts, edit transparent layers, and extract subjects from photos.</li>\n<li><strong>Versatile editing</strong>: Use up to <strong>10 reference images</strong>, specify local edits, preserve people and products, and handle a wide range of tasks.</li>\n<li><strong>Realistic textures and refined aesthetics</strong>: Improved typography, portrait lighting, and fine details make generated images more visually compelling.</li>\n</ul>\n<h2>Compact and Efficient</h2>\n<p>Qwen-Image-2.1 uses a lightweight architecture. Its visual generation component contains <strong>32 Single-Stream DiT layers and 7B parameters</strong>. Despite its compact size, the model delivers strong image generation quality. The Qwen-Image-Bench comparison below shows its performance alongside other open-source and closed-source models.</p>\n<p><picture class=\"article-picture article-picture-fallback\" style=\"--image-ratio:16 / 9\"><img src=\"https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-01.png\" alt=\"Qwen-Image-Bench evaluation comparison\" loading=\"lazy\" decoding=\"async\" fetchpriority=\"low\" referrerpolicy=\"no-referrer\" class=\"progressive-image\"></picture></p>\n<p>Qwen-Image-Bench evaluation comparison</p>\n<p>Inference efficiency is another focus, particularly when editing with multiple input images. This optimization comes from a <strong>mixed-granularity attention architecture</strong>. Text, including the system prefix and editing instructions, uses a token-level causal mask, while image generation uses a chunk-level mask. <strong>KV cache reuse</strong> allows input images and editing instructions to serve as static context, computed and cached in the first step to improve inference efficiency and reduce memory usage.</p>\n<p><picture class=\"article-picture article-picture-fallback\" style=\"--image-ratio:16 / 9\"><img src=\"https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-03.png\" alt=\"Qwen-Image-2.1 mixed-granularity attention architecture\" loading=\"lazy\" decoding=\"async\" fetchpriority=\"low\" referrerpolicy=\"no-referrer\" class=\"progressive-image\"></picture></p>\n<p>Qwen-Image-2.1 mixed-granularity attention architecture</p>\n<h2>Native Transparency, Unified Creation and Editing</h2>\n<p>Native transparency is a major addition in this release. In December 2025, we introduced Qwen-Image-Layered as a dedicated model supporting transparent image generation. Qwen-Image-2.1 now integrates this capability into a unified model, using the prompt to determine whether to output a regular image or an image with a transparency channel.</p>\n<p>Here are examples of transparent images generated directly from text:</p>\n<p><picture class=\"article-picture article-picture-fallback\" style=\"--image-ratio:16 / 9\"><img src=\"https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-04.png\" alt=\"Transparent images generated from text (1)\" loading=\"lazy\" decoding=\"async\" fetchpriority=\"low\" referrerpolicy=\"no-referrer\" class=\"progressive-image\"></picture> <picture class=\"article-picture article-picture-fallback\" style=\"--image-ratio:16 / 9\"><img src=\"https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-05.png\" alt=\"Transparent images generated from text (2)\" loading=\"lazy\" decoding=\"async\" fetchpriority=\"low\" referrerpolicy=\"no-referrer\" class=\"progressive-image\"></picture> <picture class=\"article-picture article-picture-fallback\" style=\"--image-ratio:16 / 9\"><img src=\"https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-06.png\" alt=\"Transparent images generated from text (3)\" loading=\"lazy\" decoding=\"async\" fetchpriority=\"low\" referrerpolicy=\"no-referrer\" class=\"progressive-image\"></picture></p>\n<p>Beyond individual subjects, the model can generate more complex transparent images composed of multiple elements, opening up further possibilities for design and asset creation.</p>\n<p><picture class=\"article-picture article-picture-fallback\" style=\"--image-ratio:16 / 9\"><img src=\"https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-07.png\" alt=\"Transparent compositions with multiple elements (1)\" loading=\"lazy\" decoding=\"async\" fetchpriority=\"low\" referrerpolicy=\"no-referrer\" class=\"progressive-image\"></picture> <picture class=\"article-picture article-picture-fallback\" style=\"--image-ratio:16 / 9\"><img src=\"https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-08.png?v=cac12076c2cd\" alt=\"Transparent compositions with multiple elements (2)\" loading=\"lazy\" decoding=\"async\" fetchpriority=\"low\" referrerpolicy=\"no-referrer\" class=\"progressive-image\"></picture></p>\n<p>By unifying generation and editing, Qwen-Image-2.1 also supports editing transparent images directly. For example, it can change a subject’s expression while retaining the transparent background. The input is on the left and the edited result on the right.</p>\n<p><picture class=\"article-picture article-picture-fallback\" style=\"--image-ratio:16 / 9\"><img src=\"https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-09.png?v=ee4de1b5241d\" alt=\"Expression editing on a transparent image: input and result (1)\" loading=\"lazy\" decoding=\"async\" fetchpriority=\"low\" referrerpolicy=\"no-referrer\" class=\"progressive-image\"></picture> <picture class=\"article-picture article-picture-fallback\" style=\"--image-ratio:16 / 9\"><img src=\"https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-10.png?v=611bf03abb39\" alt=\"Expression editing on a transparent image: input and result (2)\" loading=\"lazy\" decoding=\"async\" fetchpriority=\"low\" referrerpolicy=\"no-referrer\" class=\"progressive-image\"></picture></p>\n<p>Text within a transparent layer can also be edited. In the following example, “BLOOM” is replaced with “Qwen-Image”.</p>\n<p><picture class=\"article-picture article-picture-fallback\" style=\"--image-ratio:16 / 9\"><img src=\"https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-11.png?v=1f2803db504a\" alt=\"Transparent text editing: replacing BLOOM with Qwen-Image (1)\" loading=\"lazy\" decoding=\"async\" fetchpriority=\"low\" referrerpolicy=\"no-referrer\" class=\"progressive-image\"></picture> <picture class=\"article-picture article-picture-fallback\" style=\"--image-ratio:16 / 9\"><img src=\"https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-12.png?v=9d0fa2b0e13a\" alt=\"Transparent text editing: replacing BLOOM with Qwen-Image (2)\" loading=\"lazy\" decoding=\"async\" fetchpriority=\"low\" referrerpolicy=\"no-referrer\" class=\"progressive-image\"></picture></p>\n<p>This capability extends to real photographs. Given an RGB image, the model can extract the desired subject as an RGBA layer with transparency, making it easier to reuse elements in subsequent design and composition work.</p>\n<p><picture class=\"article-picture article-picture-fallback\" style=\"--image-ratio:16 / 9\"><img src=\"https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-13.png\" alt=\"Extracting a transparent RGBA layer from an RGB photograph (1)\" loading=\"lazy\" decoding=\"async\" fetchpriority=\"low\" referrerpolicy=\"no-referrer\" class=\"progressive-image\"></picture> <picture class=\"article-picture article-picture-fallback\" style=\"--image-ratio:16 / 9\"><img src=\"https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-14.png\" alt=\"Extracting a transparent RGBA layer from an RGB photograph (2)\" loading=\"lazy\" decoding=\"async\" fetchpriority=\"low\" referrerpolicy=\"no-referrer\" class=\"progressive-image\"></picture></p>\n<h2>Versatile Editing</h2>\n<p>Qwen-Image-2.1 improves editing in four areas: multiple reference images, local editing, fidelity preservation, and task coverage.</p>\n<h3>Multiple References: Up to 10 Input Images</h3>\n<p>Qwen-Image-2.1 supports <strong>up to 10 reference images</strong>, combining multiple subjects and assets into a coherent composition. In the group portrait example below, six individual portraits on the left are brought together in one photograph.</p>\n<p><picture class=\"article-picture article-picture-fallback\" style=\"--image-ratio:16 / 9\"><img src=\"https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-15.png\" alt=\"A group photograph generated from six portrait references\" loading=\"lazy\" decoding=\"async\" fetchpriority=\"low\" referrerpolicy=\"no-referrer\" class=\"progressive-image\"></picture></p>\n<p>A group photograph generated from six portrait references</p>\n<p>For virtual try-on, five inputs—a model, clothing, shoes, a bag, and a hat—can be combined into a complete outfit.</p>\n<p><picture class=\"article-picture article-picture-fallback\" style=\"--image-ratio:16 / 9\"><img src=\"https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-16.png\" alt=\"A complete outfit generated from five reference images\" loading=\"lazy\" decoding=\"async\" fetchpriority=\"low\" referrerpolicy=\"no-referrer\" class=\"progressive-image\"></picture></p>\n<p>A complete outfit generated from five reference images</p>\n<p>For interior design, the model can use 10 images of furnishings to generate a complete room arrangement.</p>\n<p><picture class=\"article-picture article-picture-fallback\" style=\"--image-ratio:16 / 9\"><img src=\"https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-17.png\" alt=\"An interior generated from ten furnishing references\" loading=\"lazy\" decoding=\"async\" fetchpriority=\"low\" referrerpolicy=\"no-referrer\" class=\"progressive-image\"></picture></p>\n<p>An interior generated from ten furnishing references</p>\n<h3>Local Editing: Flexible Region Selection</h3>\n<p>Qwen-Image-2.1 supports circles, painted annotations, and separate masks to specify where an edit should take place.</p>\n<p>The first example uses circles of different colors to identify three regions at once: “Remove the metal watch in the blue circle, change the hair in the red circle to black, and replace the area in the green circle with gray short-sleeved linen pajamas.” The annotated input is on the left, and the result is on the right.</p>\n<p><picture class=\"article-picture article-picture-fallback\" style=\"--image-ratio:16 / 9\"><img src=\"https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-18.png\" alt=\"Circle-guided editing of a watch, hair, and clothing (1)\" loading=\"lazy\" decoding=\"async\" fetchpriority=\"low\" referrerpolicy=\"no-referrer\" class=\"progressive-image\"></picture> <picture class=\"article-picture article-picture-fallback\" style=\"--image-ratio:16 / 9\"><img src=\"https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-19.png\" alt=\"Circle-guided editing of a watch, hair, and clothing (2)\" loading=\"lazy\" decoding=\"async\" fetchpriority=\"low\" referrerpolicy=\"no-referrer\" class=\"progressive-image\"></picture></p>\n<p>Painted annotations provide another way to identify a region. In this example, the model adds a diver to the area marked in white on the right side of the input image.</p>\n<p><picture class=\"article-picture article-picture-fallback\" style=\"--image-ratio:16 / 9\"><img src=\"https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-20.png\" alt=\"Paint-guided editing: adding a diver to the marked region (1)\" loading=\"lazy\" decoding=\"async\" fetchpriority=\"low\" referrerpolicy=\"no-referrer\" class=\"progressive-image\"></picture> <picture class=\"article-picture article-picture-fallback\" style=\"--image-ratio:16 / 9\"><img src=\"https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-21.png\" alt=\"Paint-guided editing: adding a diver to the marked region (2)\" loading=\"lazy\" decoding=\"async\" fetchpriority=\"low\" referrerpolicy=\"no-referrer\" class=\"progressive-image\"></picture></p>\n<p>Circles and painted annotations obscure some of the original content. To preserve the complete input, Qwen-Image-2.1 also accepts <strong>the original image and a separate mask as two inputs</strong>. The following example asks the model to generate a cowboy on horseback, using these two images:</p>\n<p><picture class=\"article-picture article-picture-fallback\" style=\"--image-ratio:16 / 9\"><img src=\"https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-22.png\" alt=\"Local editing inputs: original image and separate mask (1)\" loading=\"lazy\" decoding=\"async\" fetchpriority=\"low\" referrerpolicy=\"no-referrer\" class=\"progressive-image\"></picture> <picture class=\"article-picture article-picture-fallback\" style=\"--image-ratio:16 / 9\"><img src=\"https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-23.png\" alt=\"Local editing inputs: original image and separate mask (2)\" loading=\"lazy\" decoding=\"async\" fetchpriority=\"low\" referrerpolicy=\"no-referrer\" class=\"progressive-image\"></picture></p>\n<p>The model edits the region specified by the mask, producing the following result:</p>\n<p><picture class=\"article-picture article-picture-fallback\" style=\"--image-ratio:16 / 9\"><img src=\"https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-24.png\" alt=\"Mask-guided editing result: a cowboy on horseback\" loading=\"lazy\" decoding=\"async\" fetchpriority=\"low\" referrerpolicy=\"no-referrer\" class=\"progressive-image\"></picture></p>\n<p>Mask-guided editing result: a cowboy on horseback</p>\n<p>Local editing can also support sequential creation. By making successive changes while preserving the rest of the scene, edited images can be assembled into simple animations, as illustrated by the capybara Calabash Brothers example below.</p>\n<p><a target=\"_blank\" rel=\"noopener noreferrer\" href=\"https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/videos/hulu_final_48f_6fps.mp4\">Capybara Calabash Brothers: animation through successive local edits</a></p>\n<h3>Fidelity: Preserving People and Products</h3>\n<p>Fidelity improvements focus on <strong>portrait identity</strong> and <strong>product consistency</strong>. For portraits, the model better preserves facial features so that a person’s identity remains more consistent across edits. Each pair below shows the input on the left and the edited result on the right.</p>\n<p><picture class=\"article-picture article-picture-fallback\" style=\"--image-ratio:16 / 9\"><img src=\"https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-25.png\" alt=\"Portrait fidelity example one: input and result (1)\" loading=\"lazy\" decoding=\"async\" fetchpriority=\"low\" referrerpolicy=\"no-referrer\" class=\"progressive-image\"></picture> <picture class=\"article-picture article-picture-fallback\" style=\"--image-ratio:16 / 9\"><img src=\"https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-26.png\" alt=\"Portrait fidelity example one: input and result (2)\" loading=\"lazy\" decoding=\"async\" fetchpriority=\"low\" referrerpolicy=\"no-referrer\" class=\"progressive-image\"></picture></p>\n<p><picture class=\"article-picture article-picture-fallback\" style=\"--image-ratio:16 / 9\"><img src=\"https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-27.png\" alt=\"Portrait fidelity example two: input and result (1)\" loading=\"lazy\" decoding=\"async\" fetchpriority=\"low\" referrerpolicy=\"no-referrer\" class=\"progressive-image\"></picture> <picture class=\"article-picture article-picture-fallback\" style=\"--image-ratio:16 / 9\"><img src=\"https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-28.png\" alt=\"Portrait fidelity example two: input and result (2)\" loading=\"lazy\" decoding=\"async\" fetchpriority=\"low\" referrerpolicy=\"no-referrer\" class=\"progressive-image\"></picture></p>\n<p><picture class=\"article-picture article-picture-fallback\" style=\"--image-ratio:16 / 9\"><img src=\"https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-29.png\" alt=\"Portrait fidelity example three: input and result (1)\" loading=\"lazy\" decoding=\"async\" fetchpriority=\"low\" referrerpolicy=\"no-referrer\" class=\"progressive-image\"></picture> <picture class=\"article-picture article-picture-fallback\" style=\"--image-ratio:16 / 9\"><img src=\"https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-30.png\" alt=\"Portrait fidelity example three: input and result (2)\" loading=\"lazy\" decoding=\"async\" fetchpriority=\"low\" referrerpolicy=\"no-referrer\" class=\"progressive-image\"></picture></p>\n<p>For product editing, the model aims to preserve text, textures, and shape, keeping the product’s defining features consistent in a new image.</p>\n<p><picture class=\"article-picture article-picture-fallback\" style=\"--image-ratio:16 / 9\"><img src=\"https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-31.png\" alt=\"Product fidelity example one: input and result (1)\" loading=\"lazy\" decoding=\"async\" fetchpriority=\"low\" referrerpolicy=\"no-referrer\" class=\"progressive-image\"></picture> <picture class=\"article-picture article-picture-fallback\" style=\"--image-ratio:16 / 9\"><img src=\"https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-32.png\" alt=\"Product fidelity example one: input and result (2)\" loading=\"lazy\" decoding=\"async\" fetchpriority=\"low\" referrerpolicy=\"no-referrer\" class=\"progressive-image\"></picture></p>\n<p><picture class=\"article-picture article-picture-fallback\" style=\"--image-ratio:16 / 9\"><img src=\"https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-33.png\" alt=\"Product fidelity example two: input and result (1)\" loading=\"lazy\" decoding=\"async\" fetchpriority=\"low\" referrerpolicy=\"no-referrer\" class=\"progressive-image\"></picture> <picture class=\"article-picture article-picture-fallback\" style=\"--image-ratio:16 / 9\"><img src=\"https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-34.png\" alt=\"Product fidelity example two: input and result (2)\" loading=\"lazy\" decoding=\"async\" fetchpriority=\"low\" referrerpolicy=\"no-referrer\" class=\"progressive-image\"></picture></p>\n<p><picture class=\"article-picture article-picture-fallback\" style=\"--image-ratio:16 / 9\"><img src=\"https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-35.png\" alt=\"Product fidelity example three: input and result (1)\" loading=\"lazy\" decoding=\"async\" fetchpriority=\"low\" referrerpolicy=\"no-referrer\" class=\"progressive-image\"></picture> <picture class=\"article-picture article-picture-fallback\" style=\"--image-ratio:16 / 9\"><img src=\"https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-36.png\" alt=\"Product fidelity example three: input and result (2)\" loading=\"lazy\" decoding=\"async\" fetchpriority=\"low\" referrerpolicy=\"no-referrer\" class=\"progressive-image\"></picture></p>\n<h3>Task Coverage: Panoramas, Infographics, and Storyboards</h3>\n<p>Qwen-Image-2.1 supports a broad range of editing tasks, including panorama, infographic, and storyboard generation, balancing capabilities across different applications.</p>\n<p>For example, starting from this selfie:</p>\n<p><picture class=\"article-picture article-picture-fallback\" style=\"--image-ratio:16 / 9\"><img src=\"https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-37.png\" alt=\"Input selfie for panorama generation\" loading=\"lazy\" decoding=\"async\" fetchpriority=\"low\" referrerpolicy=\"no-referrer\" class=\"progressive-image\"></picture></p>\n<p>Input selfie for panorama generation</p>\n<p>The model generates the following panorama:</p>\n<p><picture class=\"article-picture article-picture-fallback\" style=\"--image-ratio:16 / 9\"><img src=\"https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-38.png\" alt=\"Panorama generated from the selfie\" loading=\"lazy\" decoding=\"async\" fetchpriority=\"low\" referrerpolicy=\"no-referrer\" class=\"progressive-image\"></picture></p>\n<p>Panorama generated from the selfie</p>\n<p>The panorama can then be explored from different viewing directions in a visualization tool.</p>\n<p><a target=\"_blank\" rel=\"noopener noreferrer\" href=\"https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/videos/pano_video2_10s_noaudio.mp4\">Panorama visualization demonstration</a></p>\n<p>For infographic generation, a model photograph can be expanded into a detailed, information-rich composition.</p>\n<p><picture class=\"article-picture article-picture-fallback\" style=\"--image-ratio:16 / 9\"><img src=\"https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-39.png\" alt=\"Input model photograph for infographic generation\" loading=\"lazy\" decoding=\"async\" fetchpriority=\"low\" referrerpolicy=\"no-referrer\" class=\"progressive-image\"></picture></p>\n<p>Input model photograph for infographic generation</p>\n<p><picture class=\"article-picture article-picture-fallback\" style=\"--image-ratio:16 / 9\"><img src=\"https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-40.png\" alt=\"Complex infographic generated from the model photograph\" loading=\"lazy\" decoding=\"async\" fetchpriority=\"low\" referrerpolicy=\"no-referrer\" class=\"progressive-image\"></picture></p>\n<p>Complex infographic generated from the model photograph</p>\n<p>The model can also turn a three-view character reference into a complete storyboard, providing material for storytelling and visual narratives.</p>\n<p><picture class=\"article-picture article-picture-fallback\" style=\"--image-ratio:16 / 9\"><img src=\"https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-41.png\" alt=\"Three-view character reference for storyboard generation\" loading=\"lazy\" decoding=\"async\" fetchpriority=\"low\" referrerpolicy=\"no-referrer\" class=\"progressive-image\"></picture></p>\n<p>Three-view character reference for storyboard generation</p>\n<p><picture class=\"article-picture article-picture-fallback\" style=\"--image-ratio:16 / 9\"><img src=\"https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-42.png\" alt=\"Complete storyboard generated from the character reference\" loading=\"lazy\" decoding=\"async\" fetchpriority=\"low\" referrerpolicy=\"no-referrer\" class=\"progressive-image\"></picture></p>\n<p>Complete storyboard generated from the character reference</p>\n<h2>Realistic Textures and Refined Aesthetics</h2>\n<p>Qwen-Image-2.1 further improves visual quality, with particular attention to typography and portraits. Text rendering considers not only the content itself, but also type styles, layout, and their relationship to the overall composition. The following examples showcase text rendering across different settings.</p>\n<p><picture class=\"article-picture article-picture-fallback\" style=\"--image-ratio:16 / 9\"><img src=\"https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-43.png\" alt=\"Text rendering example one\" loading=\"lazy\" decoding=\"async\" fetchpriority=\"low\" referrerpolicy=\"no-referrer\" class=\"progressive-image\"></picture></p>\n<p>Text rendering example one</p>\n<p><picture class=\"article-picture article-picture-fallback\" style=\"--image-ratio:16 / 9\"><img src=\"https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-44.png\" alt=\"Text rendering example two\" loading=\"lazy\" decoding=\"async\" fetchpriority=\"low\" referrerpolicy=\"no-referrer\" class=\"progressive-image\"></picture></p>\n<p>Text rendering example two</p>\n<p><picture class=\"article-picture article-picture-fallback\" style=\"--image-ratio:16 / 9\"><img src=\"https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-45.png\" alt=\"Text rendering example three\" loading=\"lazy\" decoding=\"async\" fetchpriority=\"low\" referrerpolicy=\"no-referrer\" class=\"progressive-image\"></picture></p>\n<p>Text rendering example three</p>\n<p><picture class=\"article-picture article-picture-fallback\" style=\"--image-ratio:16 / 9\"><img src=\"https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-46.png\" alt=\"Text rendering example four\" loading=\"lazy\" decoding=\"async\" fetchpriority=\"low\" referrerpolicy=\"no-referrer\" class=\"progressive-image\"></picture></p>\n<p>Text rendering example four</p>\n<p>For portraits, improved lighting and fine details give generated images a more realistic appearance.</p>\n<p><picture class=\"article-picture article-picture-fallback\" style=\"--image-ratio:16 / 9\"><img src=\"https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-47.png\" alt=\"Portrait lighting and detail example one\" loading=\"lazy\" decoding=\"async\" fetchpriority=\"low\" referrerpolicy=\"no-referrer\" class=\"progressive-image\"></picture></p>\n<p>Portrait lighting and detail example one</p>\n<p><picture class=\"article-picture article-picture-fallback\" style=\"--image-ratio:16 / 9\"><img src=\"https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-48.png\" alt=\"Portrait lighting and detail example two\" loading=\"lazy\" decoding=\"async\" fetchpriority=\"low\" referrerpolicy=\"no-referrer\" class=\"progressive-image\"></picture></p>\n<p>Portrait lighting and detail example two</p>\n<h2>Conclusion</h2>\n<p>With a compact 7B visual generation component, Qwen-Image-2.1 brings image generation, transparency, and a wide range of editing capabilities together in one model. Faster inference, support for up to 10 reference images, flexible local editing, and improved fidelity for people and products make it a practical tool for design, content creation, e-commerce, and visual storytelling.</p>\n<p>We hope you enjoy creating with Qwen-Image-2.1!</p>\n",
  "content_markdown": "![Qwen-Image-2.1 banner](https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/banner_en.png)\n\n[GITHUB](https://github.com/QwenLM/Qwen-Image-2.1) [HUGGING FACE](https://huggingface.co/Qwen/Qwen-Image-2.1) [MODELSCOPE](https://www.modelscope.cn/models/Qwen/Qwen-Image-2.1)\n\nWe are excited to open-source **Qwen-Image-2.1**, an image model in the Qwen family that balances generation quality, inference efficiency, and cost. Qwen-Image-2.1 unifies text-to-image generation and image editing in a single model, with just **7B parameters in its visual generation component** and native support for generating and editing transparent images.\n\nThis update introduces four key improvements:\n\n- **Compact and efficient**: A lightweight architecture and inference optimizations balance image quality and computational cost.\n- **Native transparency, unified creation and editing**: Generate regular or transparent images from prompts, edit transparent layers, and extract subjects from photos.\n- **Versatile editing**: Use up to **10 reference images**, specify local edits, preserve people and products, and handle a wide range of tasks.\n- **Realistic textures and refined aesthetics**: Improved typography, portrait lighting, and fine details make generated images more visually compelling.\n\n## Compact and Efficient\n\nQwen-Image-2.1 uses a lightweight architecture. Its visual generation component contains **32 Single-Stream DiT layers and 7B parameters**. Despite its compact size, the model delivers strong image generation quality. The Qwen-Image-Bench comparison below shows its performance alongside other open-source and closed-source models.\n\n![Qwen-Image-Bench evaluation comparison](https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-01.png)\n\nQwen-Image-Bench evaluation comparison\n\nInference efficiency is another focus, particularly when editing with multiple input images. This optimization comes from a **mixed-granularity attention architecture**. Text, including the system prefix and editing instructions, uses a token-level causal mask, while image generation uses a chunk-level mask. **KV cache reuse** allows input images and editing instructions to serve as static context, computed and cached in the first step to improve inference efficiency and reduce memory usage.\n\n![Qwen-Image-2.1 mixed-granularity attention architecture](https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-03.png)\n\nQwen-Image-2.1 mixed-granularity attention architecture\n\n## Native Transparency, Unified Creation and Editing\n\nNative transparency is a major addition in this release. In December 2025, we introduced Qwen-Image-Layered as a dedicated model supporting transparent image generation. Qwen-Image-2.1 now integrates this capability into a unified model, using the prompt to determine whether to output a regular image or an image with a transparency channel.\n\nHere are examples of transparent images generated directly from text:\n\n![Transparent images generated from text (1)](https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-04.png) ![Transparent images generated from text (2)](https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-05.png) ![Transparent images generated from text (3)](https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-06.png)\n\nBeyond individual subjects, the model can generate more complex transparent images composed of multiple elements, opening up further possibilities for design and asset creation.\n\n![Transparent compositions with multiple elements (1)](https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-07.png) ![Transparent compositions with multiple elements (2)](https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-08.png?v=cac12076c2cd)\n\nBy unifying generation and editing, Qwen-Image-2.1 also supports editing transparent images directly. For example, it can change a subject’s expression while retaining the transparent background. The input is on the left and the edited result on the right.\n\n![Expression editing on a transparent image: input and result (1)](https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-09.png?v=ee4de1b5241d) ![Expression editing on a transparent image: input and result (2)](https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-10.png?v=611bf03abb39)\n\nText within a transparent layer can also be edited. In the following example, “BLOOM” is replaced with “Qwen-Image”.\n\n![Transparent text editing: replacing BLOOM with Qwen-Image (1)](https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-11.png?v=1f2803db504a) ![Transparent text editing: replacing BLOOM with Qwen-Image (2)](https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-12.png?v=9d0fa2b0e13a)\n\nThis capability extends to real photographs. Given an RGB image, the model can extract the desired subject as an RGBA layer with transparency, making it easier to reuse elements in subsequent design and composition work.\n\n![Extracting a transparent RGBA layer from an RGB photograph (1)](https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-13.png) ![Extracting a transparent RGBA layer from an RGB photograph (2)](https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-14.png)\n\n## Versatile Editing\n\nQwen-Image-2.1 improves editing in four areas: multiple reference images, local editing, fidelity preservation, and task coverage.\n\n### Multiple References: Up to 10 Input Images\n\nQwen-Image-2.1 supports **up to 10 reference images**, combining multiple subjects and assets into a coherent composition. In the group portrait example below, six individual portraits on the left are brought together in one photograph.\n\n![A group photograph generated from six portrait references](https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-15.png)\n\nA group photograph generated from six portrait references\n\nFor virtual try-on, five inputs—a model, clothing, shoes, a bag, and a hat—can be combined into a complete outfit.\n\n![A complete outfit generated from five reference images](https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-16.png)\n\nA complete outfit generated from five reference images\n\nFor interior design, the model can use 10 images of furnishings to generate a complete room arrangement.\n\n![An interior generated from ten furnishing references](https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-17.png)\n\nAn interior generated from ten furnishing references\n\n### Local Editing: Flexible Region Selection\n\nQwen-Image-2.1 supports circles, painted annotations, and separate masks to specify where an edit should take place.\n\nThe first example uses circles of different colors to identify three regions at once: “Remove the metal watch in the blue circle, change the hair in the red circle to black, and replace the area in the green circle with gray short-sleeved linen pajamas.” The annotated input is on the left, and the result is on the right.\n\n![Circle-guided editing of a watch, hair, and clothing (1)](https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-18.png) ![Circle-guided editing of a watch, hair, and clothing (2)](https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-19.png)\n\nPainted annotations provide another way to identify a region. In this example, the model adds a diver to the area marked in white on the right side of the input image.\n\n![Paint-guided editing: adding a diver to the marked region (1)](https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-20.png) ![Paint-guided editing: adding a diver to the marked region (2)](https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-21.png)\n\nCircles and painted annotations obscure some of the original content. To preserve the complete input, Qwen-Image-2.1 also accepts **the original image and a separate mask as two inputs**. The following example asks the model to generate a cowboy on horseback, using these two images:\n\n![Local editing inputs: original image and separate mask (1)](https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-22.png) ![Local editing inputs: original image and separate mask (2)](https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-23.png)\n\nThe model edits the region specified by the mask, producing the following result:\n\n![Mask-guided editing result: a cowboy on horseback](https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-24.png)\n\nMask-guided editing result: a cowboy on horseback\n\nLocal editing can also support sequential creation. By making successive changes while preserving the rest of the scene, edited images can be assembled into simple animations, as illustrated by the capybara Calabash Brothers example below.\n\n[Capybara Calabash Brothers: animation through successive local edits](https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/videos/hulu_final_48f_6fps.mp4)\n\n### Fidelity: Preserving People and Products\n\nFidelity improvements focus on **portrait identity** and **product consistency**. For portraits, the model better preserves facial features so that a person’s identity remains more consistent across edits. Each pair below shows the input on the left and the edited result on the right.\n\n![Portrait fidelity example one: input and result (1)](https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-25.png) ![Portrait fidelity example one: input and result (2)](https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-26.png)\n\n![Portrait fidelity example two: input and result (1)](https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-27.png) ![Portrait fidelity example two: input and result (2)](https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-28.png)\n\n![Portrait fidelity example three: input and result (1)](https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-29.png) ![Portrait fidelity example three: input and result (2)](https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-30.png)\n\nFor product editing, the model aims to preserve text, textures, and shape, keeping the product’s defining features consistent in a new image.\n\n![Product fidelity example one: input and result (1)](https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-31.png) ![Product fidelity example one: input and result (2)](https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-32.png)\n\n![Product fidelity example two: input and result (1)](https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-33.png) ![Product fidelity example two: input and result (2)](https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-34.png)\n\n![Product fidelity example three: input and result (1)](https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-35.png) ![Product fidelity example three: input and result (2)](https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-36.png)\n\n### Task Coverage: Panoramas, Infographics, and Storyboards\n\nQwen-Image-2.1 supports a broad range of editing tasks, including panorama, infographic, and storyboard generation, balancing capabilities across different applications.\n\nFor example, starting from this selfie:\n\n![Input selfie for panorama generation](https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-37.png)\n\nInput selfie for panorama generation\n\nThe model generates the following panorama:\n\n![Panorama generated from the selfie](https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-38.png)\n\nPanorama generated from the selfie\n\nThe panorama can then be explored from different viewing directions in a visualization tool.\n\n[Panorama visualization demonstration](https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/videos/pano_video2_10s_noaudio.mp4)\n\nFor infographic generation, a model photograph can be expanded into a detailed, information-rich composition.\n\n![Input model photograph for infographic generation](https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-39.png)\n\nInput model photograph for infographic generation\n\n![Complex infographic generated from the model photograph](https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-40.png)\n\nComplex infographic generated from the model photograph\n\nThe model can also turn a three-view character reference into a complete storyboard, providing material for storytelling and visual narratives.\n\n![Three-view character reference for storyboard generation](https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-41.png)\n\nThree-view character reference for storyboard generation\n\n![Complete storyboard generated from the character reference](https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-42.png)\n\nComplete storyboard generated from the character reference\n\n## Realistic Textures and Refined Aesthetics\n\nQwen-Image-2.1 further improves visual quality, with particular attention to typography and portraits. Text rendering considers not only the content itself, but also type styles, layout, and their relationship to the overall composition. The following examples showcase text rendering across different settings.\n\n![Text rendering example one](https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-43.png)\n\nText rendering example one\n\n![Text rendering example two](https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-44.png)\n\nText rendering example two\n\n![Text rendering example three](https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-45.png)\n\nText rendering example three\n\n![Text rendering example four](https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-46.png)\n\nText rendering example four\n\nFor portraits, improved lighting and fine details give generated images a more realistic appearance.\n\n![Portrait lighting and detail example one](https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-47.png)\n\nPortrait lighting and detail example one\n\n![Portrait lighting and detail example two](https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen-Image/image2.1/images/example-48.png)\n\nPortrait lighting and detail example two\n\n## Conclusion\n\nWith a compact 7B visual generation component, Qwen-Image-2.1 brings image generation, transparency, and a wide range of editing capabilities together in one model. Faster inference, support for up to 10 reference images, flexible local editing, and improved fidelity for people and products make it a practical tool for design, content creation, e-commerce, and visual storytelling.\n\nWe hope you enjoy creating with Qwen-Image-2.1!\n",
  "dateCreated": "2026-10-19T01:26:53.998049939+00:00",
  "date_created": "2026-09-20T12:00:00+00:00",
  "date_modified": null,
  "date_published": "2026-09-20T12:00:00+00:00",
  "description": "We are excited to open-source Qwen-Image-2.1, an image model in the Qwen family that balances generation quality, inference efficiency, and cost. Qwen-Image-2.1 unifies text-to-image generation and image editing in a single model, with…",
  "external_url": "https://qwen.ai/blog?id=qwen-image-2.1",
  "git": {
    "commit": "ebb0941c5c06a2ab2377342d607535262a3e969e",
    "path": "items/qwen-ai/2026/09/2026-09-20-qwen-image-2-1-compact-efficient-and-unified-image-creation.md",
    "permalink": "https://github.com/aymericbeaumet/aggr-instance/blob/ebb0941c5c06a2ab2377342d607535262a3e969e/items/qwen-ai/2026/09/2026-09-20-qwen-image-2-1-compact-efficient-and-unified-image-creation.md"
  },
  "id": "urn:aggr:item:d9b80432196d17341a4c91c7124d7e940a57c118",
  "isBasedOn": {
    "@id": "https://qwen.ai/blog?id=qwen-image-2.1"
  },
  "mainEntity": {
    "@id": "https://qwen.ai/blog?id=qwen-image-2.1",
    "@type": "CreativeWork",
    "archivedAt": {
      "@id": "https://aggr.aymericbeaumet.com/items/qwen-ai/2026-09-20-qwen-image-2-1-compact-efficient-and-unified-image-creation/#webpage"
    },
    "author": [
      {
        "@type": "Person",
        "name": "QwenTeam"
      }
    ],
    "datePublished": "2026-09-20T12:00:00+00:00",
    "headline": "Qwen-Image-2.1: Compact, Efficient, and Unified Image Creation",
    "image": {
      "@type": "ImageObject",
      "caption": null,
      "height": 90,
      "url": "https://img.alicdn.com/imgextra/i1/O1CN01XLHYPGwKvuI29R4a_!!6000000005961-2-tps-1060-636.png",
      "width": 160
    },
    "timeRequired": "PT6M",
    "url": "https://qwen.ai/blog?id=qwen-image-2.1",
    "wordCount": 1167
  },
  "name": "Archived snapshot: Qwen-Image-2.1: Compact, Efficient, and Unified Image Creation",
  "preview": {
    "alt": null,
    "color": null,
    "height": 90,
    "placeholder": {
      "data_url": "data:image/png;base64,iVBORw0KGgoAAAANSUhEUgAAAAEAAAABCAQAAAC1HAwCAAAAC0lEQVR42mNk+A8AAQUBAScY42YAAAAASUVORK5CYII=",
      "hash": ""
    },
    "url": "https://img.alicdn.com/imgextra/i1/O1CN01XLHYPGwKvuI29R4a_!!6000000005961-2-tps-1060-636.png",
    "width": 160
  },
  "reading_minutes": 6,
  "replicated_at": null,
  "source": "qwen-ai",
  "source_name": "Qwen",
  "summary": null,
  "tags": [
    "open-source"
  ],
  "temporalCoverage": "2026-10-19T01:26:53.998049939+00:00",
  "title": "Qwen-Image-2.1: Compact, Efficient, and Unified Image Creation",
  "url": "https://aggr.aymericbeaumet.com/items/qwen-ai/2026-09-20-qwen-image-2-1-compact-efficient-and-unified-image-creation/",
  "word_count": 1167
}