
Voice was humanity’s first interface—long before writing or typing, it let us share ideas, coordinate work, and build relationships. As digital systems become more capable, voice is returning as our most natural form of human-computer interaction.
\nYet today’s systems remain limited—unreliable, proprietary, and too brittle for real-world use. Closing this gap demands tools with exceptional transcription, deep understanding, multilingual fluency, and open, flexible deployment.
\nWe release the Voxtral models to accelerate this future. These state‑of‑the‑art speech understanding models are available in two sizes—a 24B variant for production-scale applications and a 3B variant for local and edge deployments. Both versions are released under the Apache 2.0 license, and are also available on our API. The API routes transcription queries to a transcribe-optimized version of Voxtral Mini (Voxtral Mini Transcribe) that delivers unparalleled cost and latency-efficiency. For a comprehensive understanding of the research and development behind Voxtral, please refer to our detailed research paper, available for download here.
\nUntil recently, gaining truly usable speech intelligence in production meant choosing between two trade-offs:
\nOpen-source ASR systems with high word error rates and limited semantic understanding
\nClosed, proprietary APIs that combine strong transcription with language understanding, but at significantly higher cost and with less control over deployment
\nVoxtral bridges this gap. It offers state-of-the-art accuracy and native semantic understanding in the open, at less than half the price of comparable APIs. This makes high-quality speech intelligence accessible and controllable at scale.
\nBoth Voxtral models go beyond simple transcription with capabilities that include:
\nLong-form context: with a 32k token context length, Voxtral handles audios up to 30 minutes for transcription, or 40 minutes for understanding
\nBuilt-in Q&A and summarization: Supports asking questions directly about the audio content or generating structured summaries, without the need to chain separate ASR and language models
\nNatively multilingual: Automatic language detection and state-of-the-art performance in the world’s most widely used languages (English, Spanish, French, Portuguese, Hindi, German, Dutch, Italian, to name a few), helping teams serve global audiences with a single system
\nFunction-calling straight from voice: Enables direct triggering of backend functions, workflows, or API calls based on spoken user intents, turning voice interactions into actionable system commands without intermediate parsing steps.
\nHighly capable at text: Retains the text understanding capabilities of its language model backbone, Mistral Small 3.1
\nThese capabilities make the Voxtral models ideal for real-world interactions and downstream actions, such as summaries, answers, analysis, and insights. For cost-sensitive use-cases, Voxtral Mini Transcribe outperforms OpenAI Whisper for less than half the price. For premium use cases, Voxtral Small matches the performance of ElevenLabs Scribe, also for less than half the price.
\nTo assess Voxtral’s transcription capabilities, we evaluate it on a range of English and multilingual benchmarks. For each task, we report the macro-average word error rate (lower is better) across languages. For English, we report a short-form (<30-seconds) and long-form (>30-seconds) average.
\nVoxtral comprehensively outperforms Whisper large-v3, the current leading open-source Speech Transcription model. It beats GPT-4o mini Transcribe and Gemini 2.5 Flash across all tasks, and achieves state-of-the-art results on English short-form and Mozilla Common Voice, surpassing ElevenLabs Scribe and demonstrating its strong multilingual capabilities.
\n
When evaluated across languages in FLEURS, Voxtral Small outperforms Whisper on every task, achieving state-of-the-art performance in a number of European languages.
\n
Macro-average details:
\nEn short-form: LibriSpeech Clean, LibriSpeech Other, GigaSpeech, VoxPopuli, Switchboard, CHiME-4, SPGISpeech
\nEn long-form: Earnings-21 10-m, Earnings-22 10-m
\nMozilla Common Voice 15.1: English, French, German, Spanish, Italian, Portuguese, Dutch, Hindi
\nFLEURS: English, French, German, Spanish, Italian, Portuguese, Dutch, Hindi, Arabic
\nVoxtral Small and Mini are capable of answering questions directly from speech, or by providing an audio and a text-based prompt. To evaluate Audio Understanding capabilities, we create speech-synthesized versions of three common Text Understanding tasks. We also evaluate the models on an in-house Audio Understanding (AU) Benchmark, where the model is tasked with answering challenging questions on 40 long-form audio examples. Finally, we assess Speech Translation capabilities on the FLEURS-Translation benchmark.
\nVoxtral Small is competitive with GPT-4o-mini and Gemini 2.5 Flash across all tasks, achieving state-of-the-art performance in Speech Translation.
\n
Voxtral retains the text capabilities of its Language-Model backbone, enabling it to be used as a drop-in replacement for Ministral and Mistral Small 3.1 respectively.
\n
Whether you’re prototyping on a laptop, running private workloads on-premises, or scaling to production in the cloud, getting started is straightforward.
\nDownload and run locally: Both Voxtral (24B) and Voxtral Mini (3B) are available to download on Hugging Face
\nTry the API: Integrate frontier speech intelligence into your application with a single API call. Pricing starts at $0.001 per minute, making high-quality transcription and understanding affordable at scale. Check out our documentation here.
\nTry it on Le Chat: Try Voxtral in Le Chat’s voice mode (rolling out to all users in the next couple of weeks)—on web or mobile. Record or upload audio, get transcriptions, ask questions, or generate summaries.
\nWe also offer capabilities for Voxtral designed for enterprises with higher security, scale, or domain-specific requirements. Please reach out to us if you are considering:
\nPrivate deployment at production-scale: Our solutions team can help you set up Voxtral for production-scale inference entirely within your own infrastructure. This is ideal for use cases in regulated industries with strict data privacy requirements. This includes guidance and tooling for deploying Voxtral across multiple GPUs or nodes, with quantized builds optimized for production throughput and cost efficiency.
\nDomain-specific fine-tuning: Work with our applied AI team to adapt Voxtral to specialized contexts—such as legal, medical, customer support, or internal knowledge bases—improving accuracy for your use case.
\nAdvanced context: We’re inviting design partners to build support for speaker identification, emotion detection, advanced diarization, and even longer context windows to meet a wider variety of needs out of the box.
\nDedicated integration support: Priority access to engineering resources and consulting to help integrate Voxtral cleanly into your existing workflows, products, or data pipelines.
\nWe will be hosting a live webinar with our friends at Inworld (check out their cool speech-to-speech demo with Voxtral and Inworld TTS!) to showcase how you can build end-to-end voice-powered agents on Wednesday, Aug 6. If you’re interested, please register here.
\nWe’re working on making our audio capabilities more feature-rich in the forthcoming months. In addition to speech understanding, will we soon support:
\nSpeaker segmentation
\nAudio markups such as age and emotion
\nWord-level timestamps
\nNon-speech audio recognition
\nAnd more!
\nWe’re excited to see what you will build with Voxtral.
\nThe release of our Voxtral models marks a significant step forward, but our journey is far from over. Our ambition is to build the most natural, delightful near-human-like voice interfaces and there's lot more work to do. We are actively expanding our nascent audio team and looking for talented research scientists and engineers who share our ambition.
\nIf you’re interested in joining us on our mission to democratize artificial intelligenceI, we welcome your applications to join our team!
\n", "content_markdown": "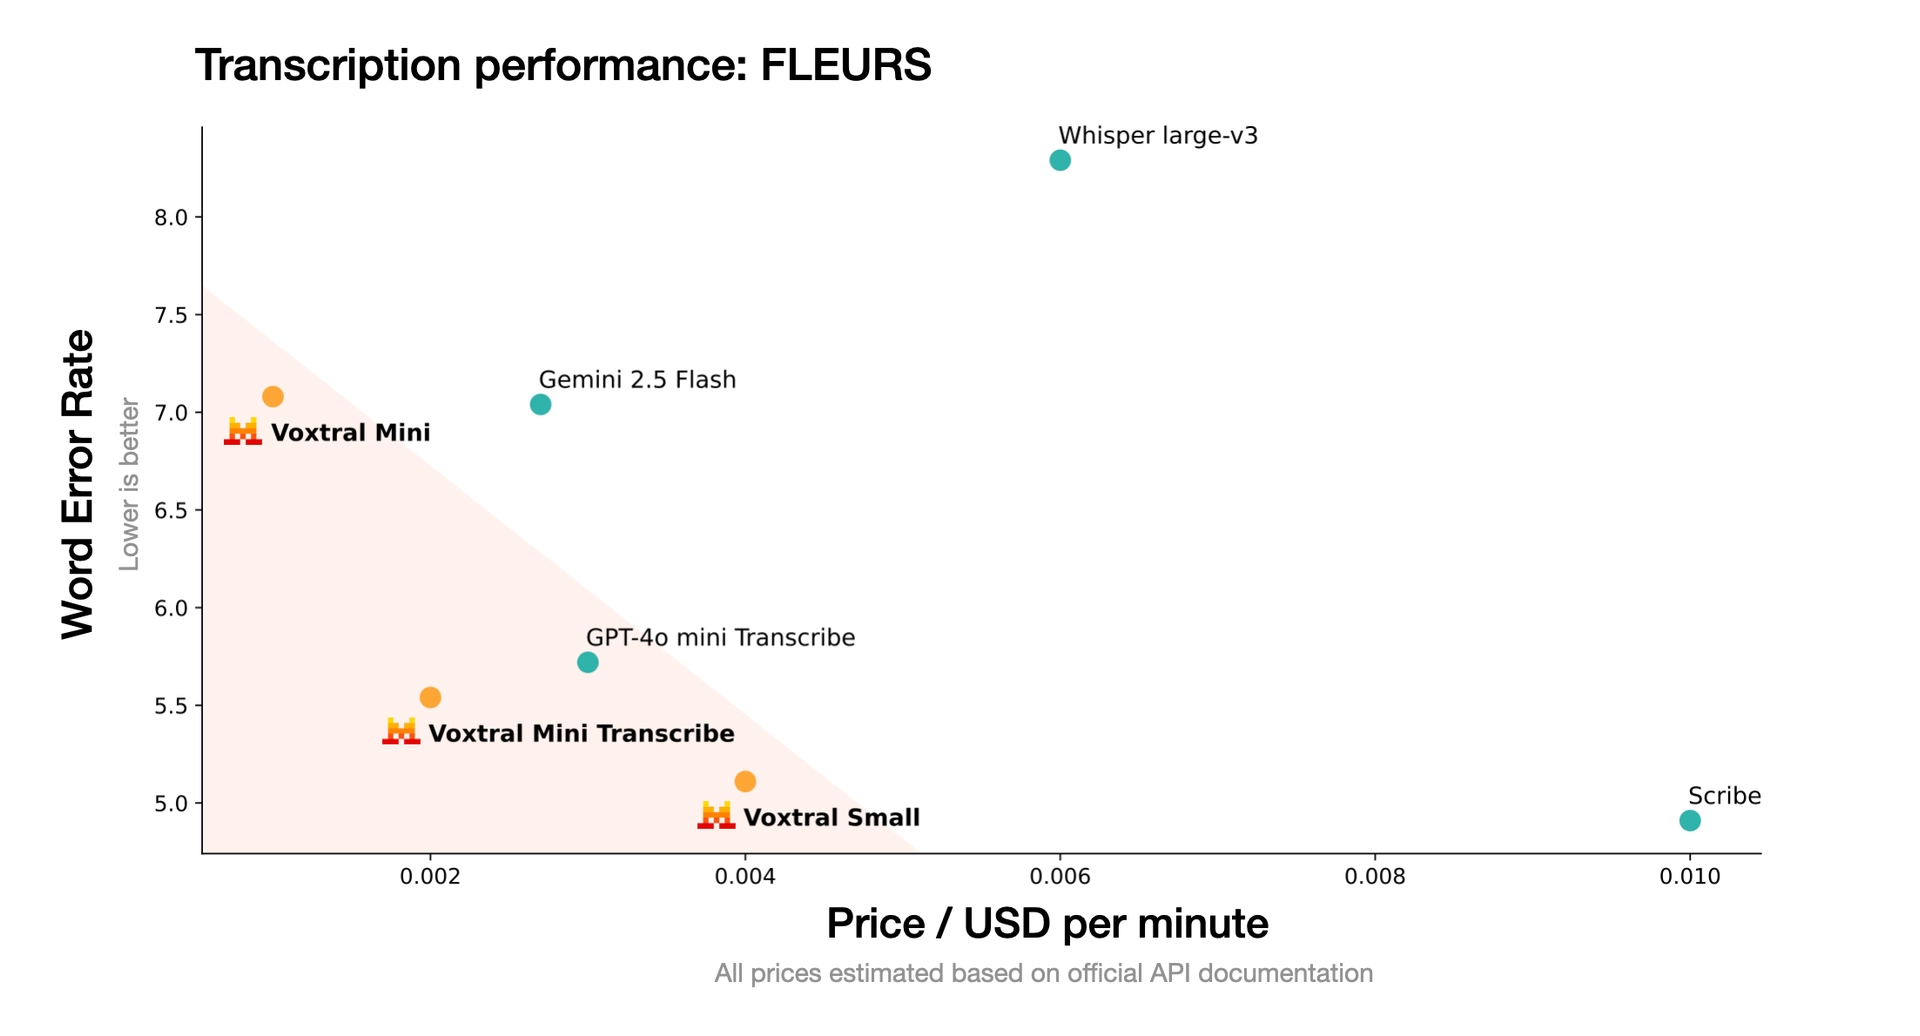\n\n### Voice: the original UI.\n\nVoice was humanity’s first interface—long before writing or typing, it let us share ideas, coordinate work, and build relationships. As digital systems become more capable, voice is returning as our most natural form of human-computer interaction.\n\nYet today’s systems remain limited—unreliable, proprietary, and too brittle for real-world use. Closing this gap demands tools with exceptional transcription, deep understanding, multilingual fluency, and open, flexible deployment.\n\nWe release the Voxtral models to accelerate this future. These state‑of‑the‑art speech understanding models are available in two sizes—a 24B variant for production-scale applications and a 3B variant for local and edge deployments. Both versions are released under the Apache 2.0 license, and are also available on our [API](https://docs.mistral.ai/capabilities/audio/#transcription). The API routes transcription queries to a transcribe-optimized version of Voxtral Mini (Voxtral Mini Transcribe) that delivers unparalleled cost and latency-efficiency. For a comprehensive understanding of the research and development behind Voxtral, please refer to our detailed research paper, available for download [here](https://arxiv.org/abs/2507.13264).\n\n### Open, affordable, and production-ready speech understanding for everyone.\n\nUntil recently, gaining truly usable speech intelligence in production meant choosing between two trade-offs:\n\n1. Open-source ASR systems with high word error rates and limited semantic understanding\n\n2. Closed, proprietary APIs that combine strong transcription with language understanding, but at significantly higher cost and with less control over deployment\n\nVoxtral bridges this gap. It offers state-of-the-art accuracy and native semantic understanding in the open, at less than half the price of comparable APIs. This makes high-quality speech intelligence accessible and controllable at scale.\n\nBoth Voxtral models go beyond simple transcription with capabilities that include:\n\n- *Long-form context:* with a 32k token context length, Voxtral handles audios up to 30 minutes for transcription, or 40 minutes for understanding\n\n- *Built-in Q&A and summarization:* Supports asking questions directly about the audio content or generating structured summaries, without the need to chain separate ASR and language models\n\n- *Natively multilingual:* Automatic language detection and state-of-the-art performance in the world’s most widely used languages (English, Spanish, French, Portuguese, Hindi, German, Dutch, Italian, to name a few), helping teams serve global audiences with a single system\n\n- *Function-calling straight from voice:* Enables direct triggering of backend functions, workflows, or API calls based on spoken user intents, turning voice interactions into actionable system commands without intermediate parsing steps.\n\n- *Highly capable at text:* Retains the text understanding capabilities of its language model backbone, Mistral Small 3.1\n\nThese capabilities make the Voxtral models ideal for real-world interactions and downstream actions, such as summaries, answers, analysis, and insights. For cost-sensitive use-cases, Voxtral Mini Transcribe outperforms OpenAI Whisper for less than half the price. For premium use cases, Voxtral Small matches the performance of ElevenLabs Scribe, also for less than half the price.\n\n## Benchmarks\n\n### Speech Transcription\n\nTo assess Voxtral’s transcription capabilities, we evaluate it on a range of English and multilingual benchmarks. For each task, we report the macro-average word error rate (lower is better) across languages. For English, we report a short-form (<30-seconds) and long-form (>30-seconds) average.\n\nVoxtral comprehensively outperforms Whisper large-v3, the current leading open-source Speech Transcription model. It beats GPT-4o mini Transcribe and Gemini 2.5 Flash across all tasks, and achieves state-of-the-art results on English short-form and Mozilla Common Voice, surpassing ElevenLabs Scribe and demonstrating its strong multilingual capabilities.\n\n\n\nWhen evaluated across languages in FLEURS, Voxtral Small outperforms Whisper on every task, achieving state-of-the-art performance in a number of European languages.\n\n\n\nMacro-average details:\n\n- En short-form: LibriSpeech Clean, LibriSpeech Other, GigaSpeech, VoxPopuli, Switchboard, CHiME-4, SPGISpeech\n\n- En long-form: Earnings-21 10-m, Earnings-22 10-m\n\n- Mozilla Common Voice 15.1: English, French, German, Spanish, Italian, Portuguese, Dutch, Hindi\n\n- FLEURS: English, French, German, Spanish, Italian, Portuguese, Dutch, Hindi, Arabic\n\n### Audio Understanding\n\nVoxtral Small and Mini are capable of answering questions directly from speech, or by providing an audio and a text-based prompt. To evaluate Audio Understanding capabilities, we create speech-synthesized versions of three common Text Understanding tasks. We also evaluate the models on an in-house Audio Understanding (AU) Benchmark, where the model is tasked with answering challenging questions on 40 long-form audio examples. Finally, we assess Speech Translation capabilities on the FLEURS-Translation benchmark.\n\nVoxtral Small is competitive with GPT-4o-mini and Gemini 2.5 Flash across all tasks, achieving state-of-the-art performance in Speech Translation.\n\n\n\n### **Text**\n\nVoxtral retains the text capabilities of its Language-Model backbone, enabling it to be used as a drop-in replacement for Ministral and Mistral Small 3.1 respectively.\n\n\n\n## Try it for free\n\nWhether you’re prototyping on a laptop, running private workloads on-premises, or scaling to production in the cloud, getting started is straightforward.\n\n- Download and run locally: Both Voxtral (24B) and Voxtral Mini (3B) are available to [download](https://huggingface.co/mistralai/) on Hugging Face\n\n- Try the API: Integrate frontier speech intelligence into your application with a single [API call](https://console.mistral.ai/). Pricing starts at $0.001 per minute, making high-quality transcription and understanding affordable at scale. Check out our documentation [here](https://docs.mistral.ai/capabilities/audio/).\n\n- Try it on Le Chat: Try Voxtral in [Le Chat](http://chat.mistral.ai)’s voice mode (rolling out to all users in the next couple of weeks)—on web or mobile. Record or upload audio, get transcriptions, ask questions, or generate summaries.\n\n### Advanced enterprise features.\n\nWe also offer capabilities for Voxtral designed for enterprises with higher security, scale, or domain-specific requirements. Please [reach out to us](https://mistral.ai/contact) if you are considering:\n\n- Private deployment at production-scale: Our solutions team can help you set up Voxtral for production-scale inference entirely within your own infrastructure. This is ideal for use cases in regulated industries with strict data privacy requirements. This includes guidance and tooling for deploying Voxtral across multiple GPUs or nodes, with quantized builds optimized for production throughput and cost efficiency.\n\n- Domain-specific fine-tuning: Work with our [applied AI](https://mistral.ai/services) team to adapt Voxtral to specialized contexts—such as legal, medical, customer support, or internal knowledge bases—improving accuracy for your use case.\n\n- Advanced context: We’re inviting design partners to build support for speaker identification, emotion detection, advanced diarization, and even longer context windows to meet a wider variety of needs out of the box.\n\n- Dedicated integration support: Priority access to engineering resources and consulting to help integrate Voxtral cleanly into your existing workflows, products, or data pipelines.\n\n### Coming up.\n\nWe will be hosting a live webinar with our friends at Inworld (check out their cool speech-to-speech [demo](https://inworld-mistral-demo.inworld.ai/) with Voxtral and Inworld TTS!) to showcase how you can build end-to-end voice-powered agents on Wednesday, Aug 6. If you’re interested, please register [here](https://lu.ma/zzgc68zw).\n\nWe’re working on making our audio capabilities more feature-rich in the forthcoming months. In addition to speech understanding, will we soon support:\n\n- Speaker segmentation\n\n- Audio markups such as age and emotion\n\n- Word-level timestamps\n\n- Non-speech audio recognition\n\n- And more!\n\nWe’re excited to see what you will build with Voxtral.\n\n## BTW, we’re hiring!\n\nThe release of our Voxtral models marks a significant step forward, but our journey is far from over. Our ambition is to build the most natural, delightful near-human-like voice interfaces and there's lot more work to do. We are actively expanding our nascent audio team and looking for talented research scientists and engineers who share our ambition.\n\nIf you’re interested in joining us on our mission to democratize artificial intelligenceI, we welcome your applications to [join our team](https://mistral.ai/careers)!\n", "dateCreated": "2026-10-19T01:26:53.998049939+00:00", "date_created": "2025-07-15T12:00:00+00:00", "date_modified": "2025-07-15T12:00:00+00:00", "date_published": "2025-07-15T12:00:00+00:00", "description": "Voice: the original UI. Voice was humanity’s first interface—long before writing or typing, it let us share ideas, coordinate work, and build relationships. As digital systems become more capable, voice is returning as our most natural…", "external_url": "https://mistral.ai/news/voxtral/", "git": { "commit": "ebb0941c5c06a2ab2377342d607535262a3e969e", "path": "items/mistral-ai/2025/07/2025-07-15-voxtral.md", "permalink": "https://github.com/aymericbeaumet/aggr-instance/blob/ebb0941c5c06a2ab2377342d607535262a3e969e/items/mistral-ai/2025/07/2025-07-15-voxtral.md" }, "id": "urn:aggr:item:7d46d2a88d6b02075635b296ed636cd92d3de53d", "isBasedOn": { "@id": "https://mistral.ai/news/voxtral/" }, "mainEntity": { "@id": "https://mistral.ai/news/voxtral/", "@type": "CreativeWork", "archivedAt": { "@id": "https://aggr.aymericbeaumet.com/items/mistral-ai/2025-07-15-voxtral/#webpage" }, "dateModified": "2025-07-15T12:00:00+00:00", "datePublished": "2025-07-15T12:00:00+00:00", "headline": "Voxtral", "image": { "@type": "ImageObject", "caption": null, "height": 90, "url": "https://mistral.ai/cms-media/api/media/file/Thumbnail-Model-Voxtral.jpg", "width": 160 }, "timeRequired": "PT6M", "url": "https://mistral.ai/news/voxtral/", "wordCount": 1255 }, "name": "Archived snapshot: Voxtral", "preview": { "alt": null, "color": null, "height": 90, "placeholder": { "data_url": "data:image/png;base64,iVBORw0KGgoAAAANSUhEUgAAAAEAAAABCAQAAAC1HAwCAAAAC0lEQVR42mNk+A8AAQUBAScY42YAAAAASUVORK5CYII=", "hash": "" }, "url": "https://mistral.ai/cms-media/api/media/file/Thumbnail-Model-Voxtral.jpg", "width": 160 }, "reading_minutes": 6, "replicated_at": null, "source": "mistral-ai", "source_name": "Mistral Blog", "summary": null, "tags": [], "temporalCoverage": "2026-10-19T01:26:53.998049939+00:00", "title": "Voxtral", "url": "https://aggr.aymericbeaumet.com/items/mistral-ai/2025-07-15-voxtral/", "word_count": 1255 }