{
  "@context": "https://schema.org",
  "@id": "https://aggr.aymericbeaumet.com/items/magazine-sebastianraschka-com/2026-03-22-a-visual-guide-to-attention-variants-in-modern-llms/#webpage",
  "@type": [
    "WebPage",
    "ArchiveComponent"
  ],
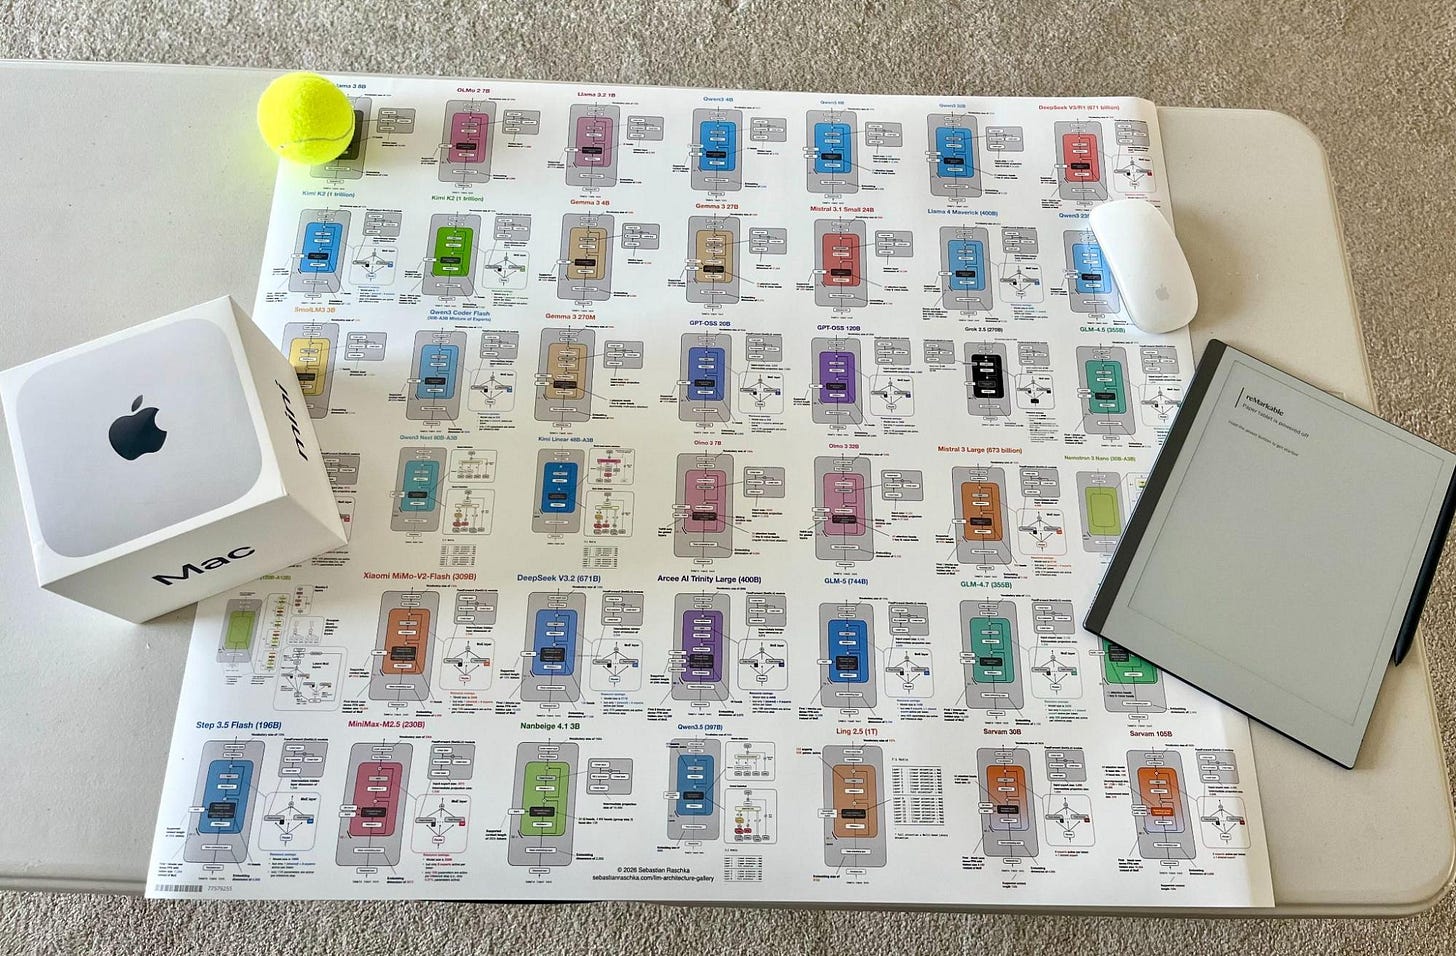
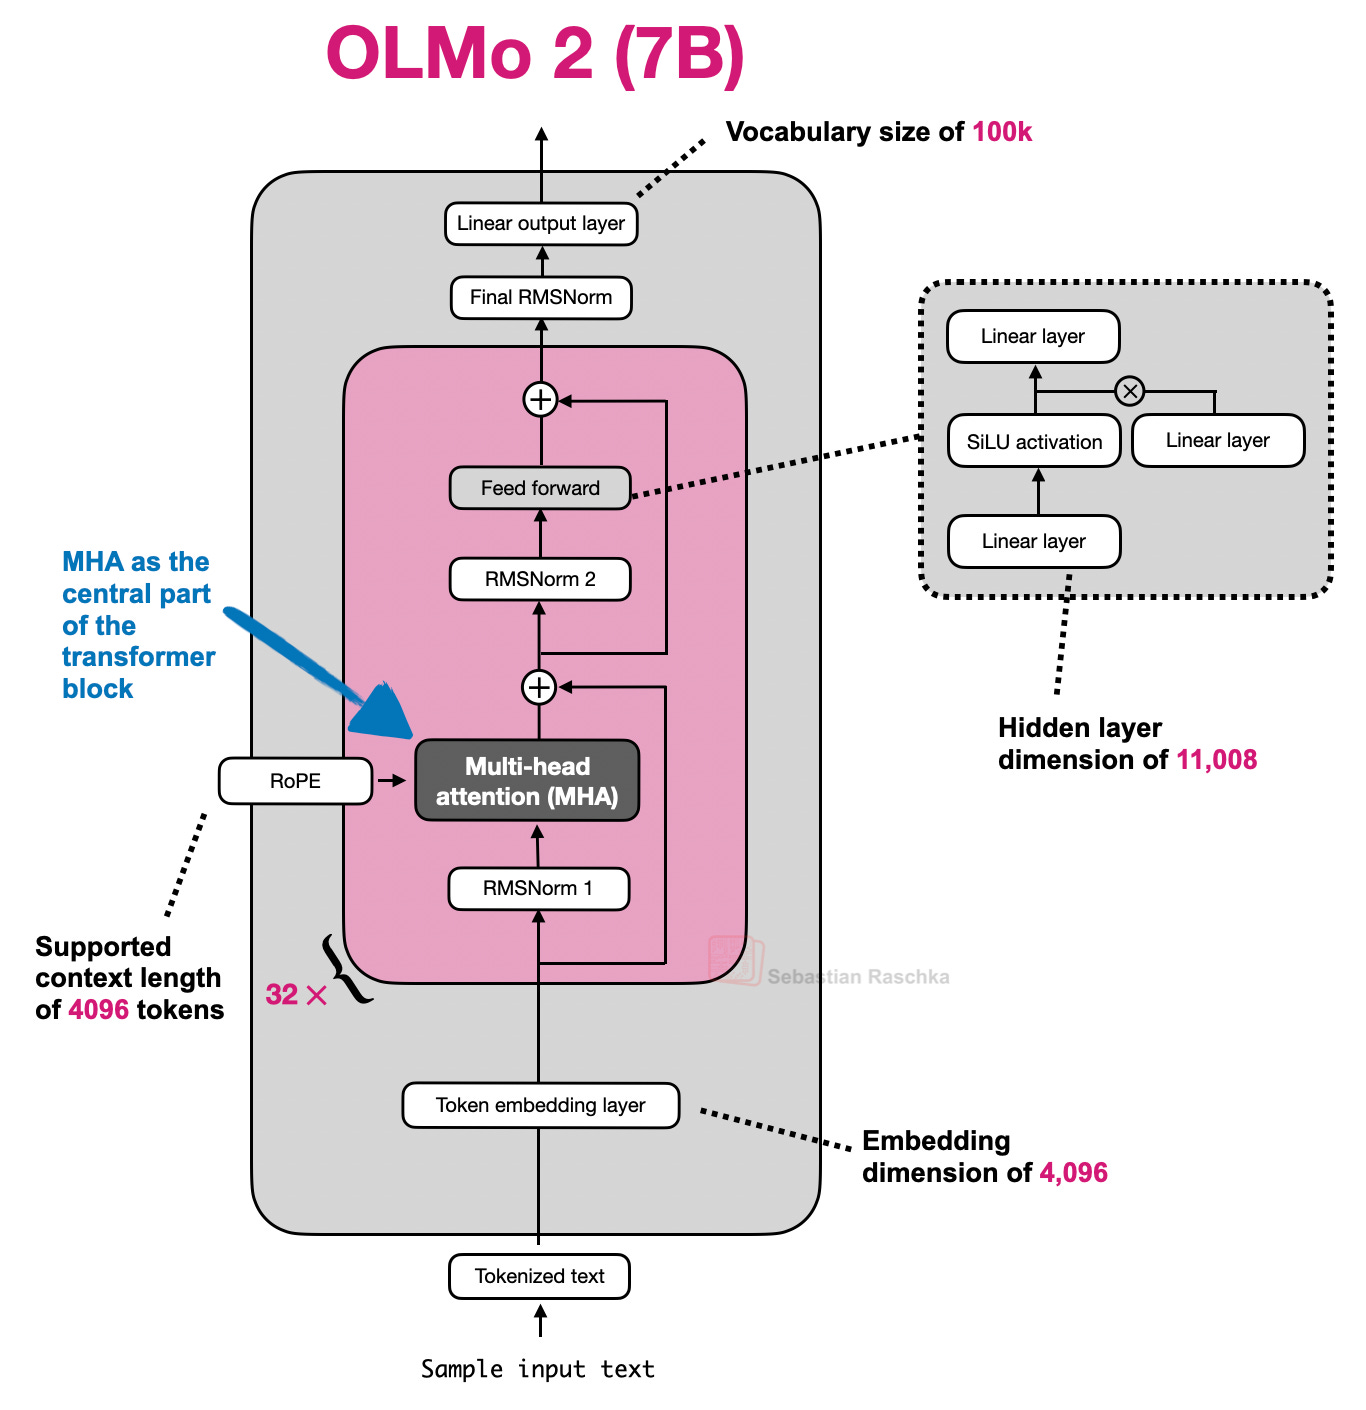
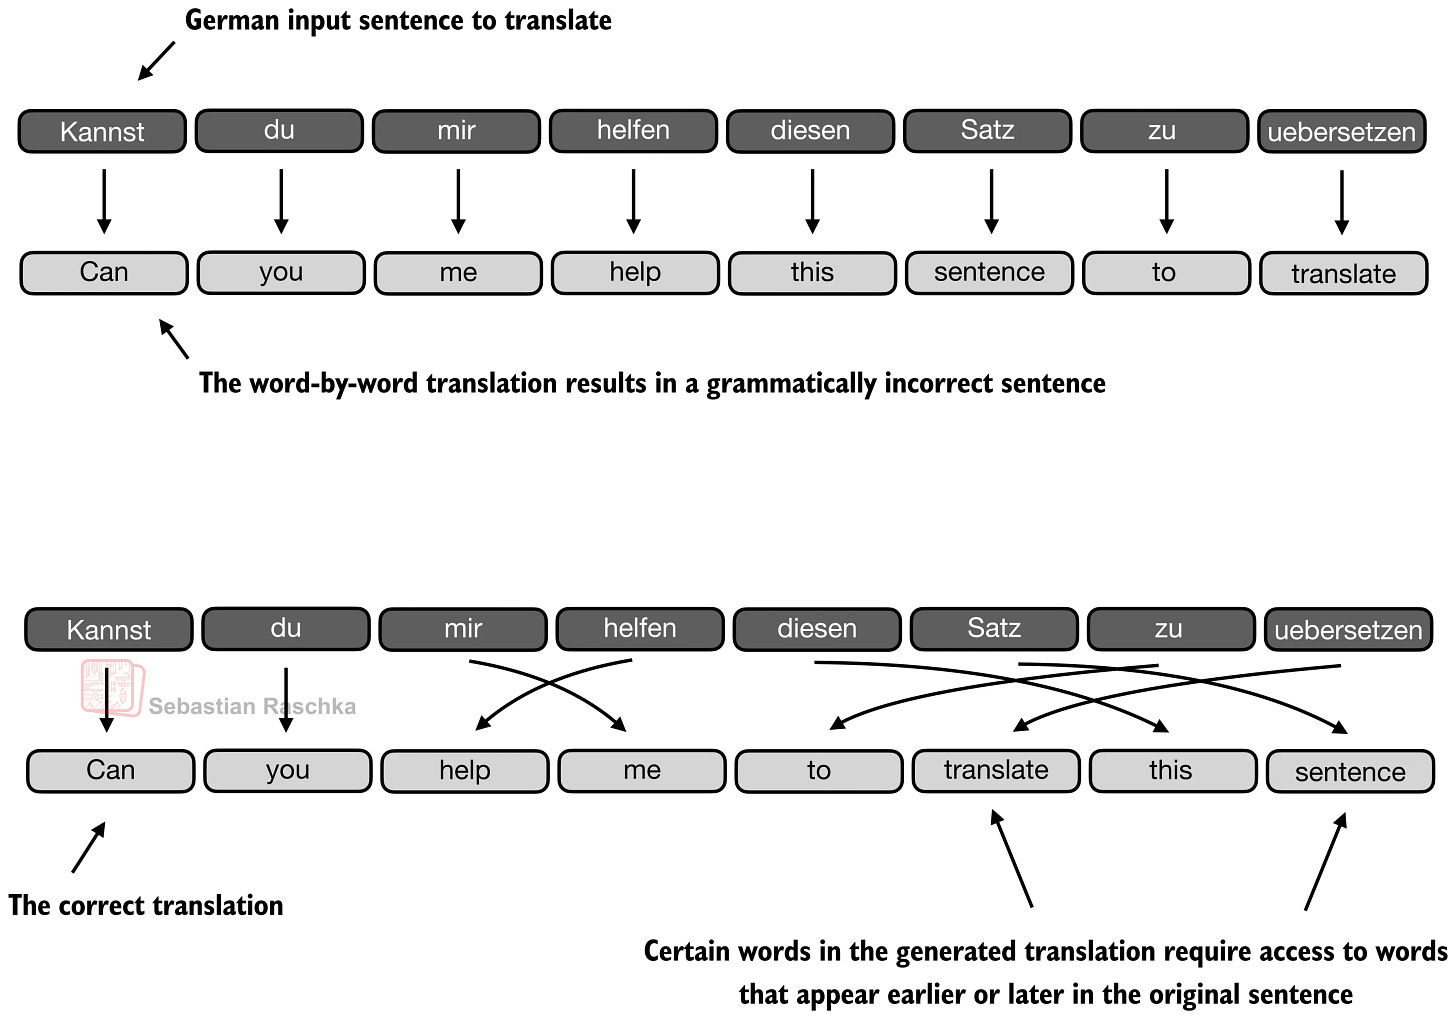
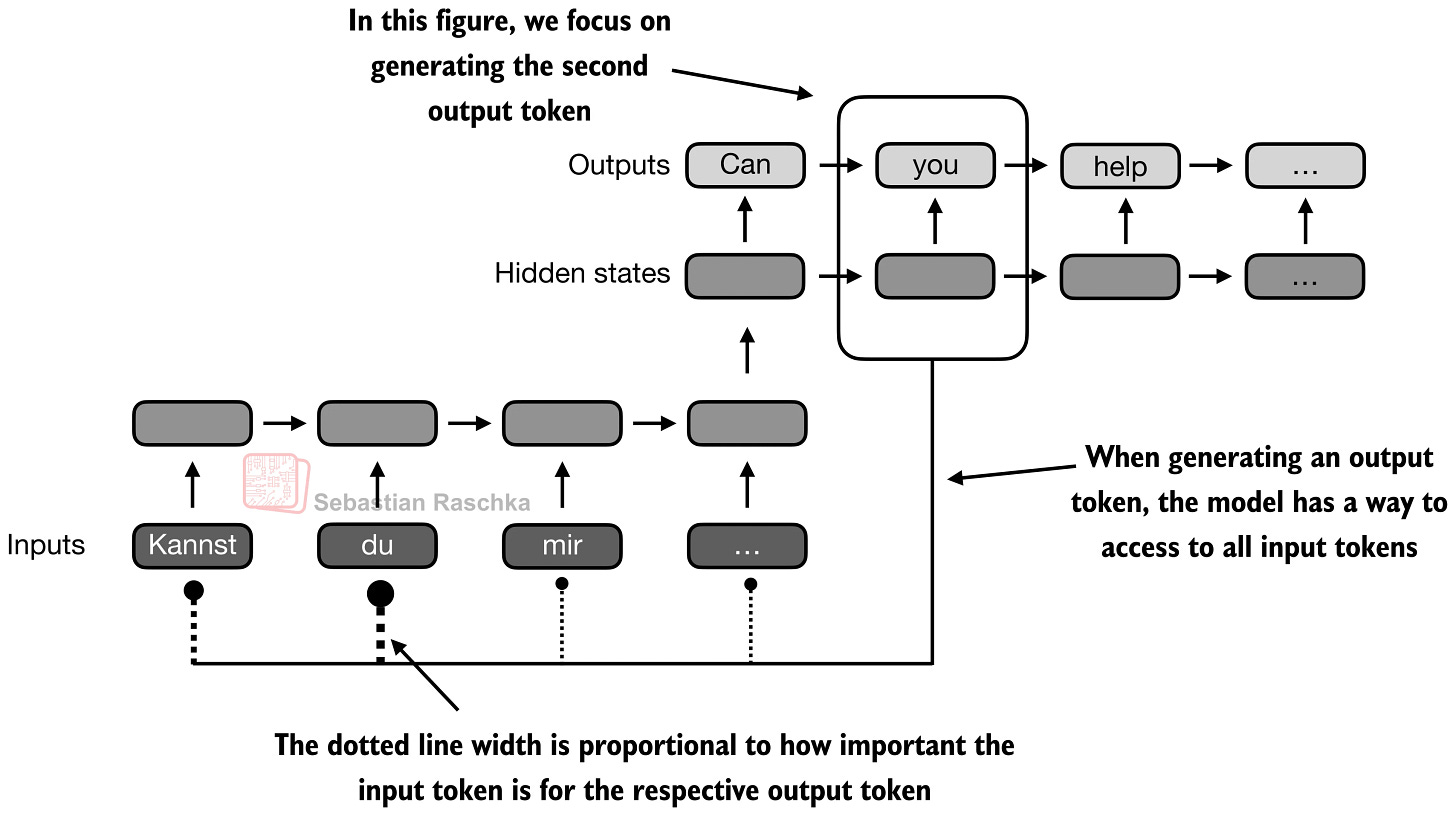
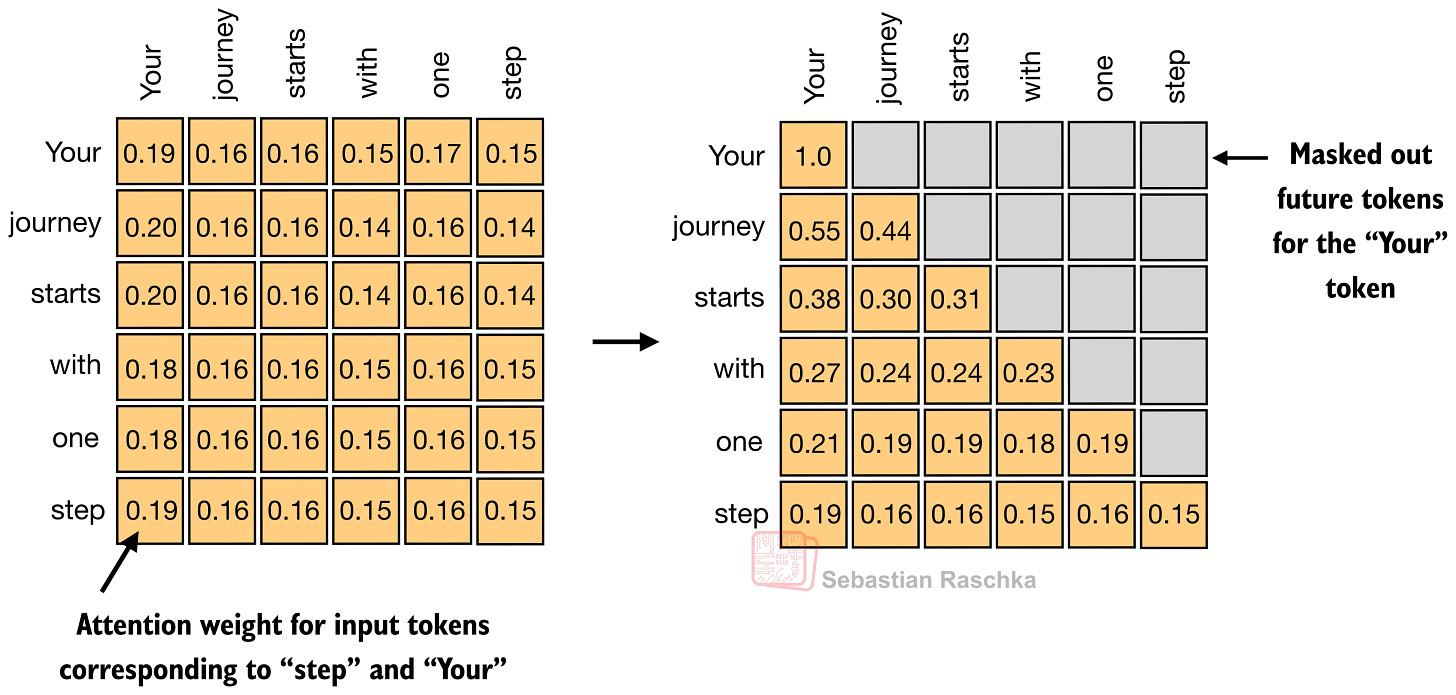
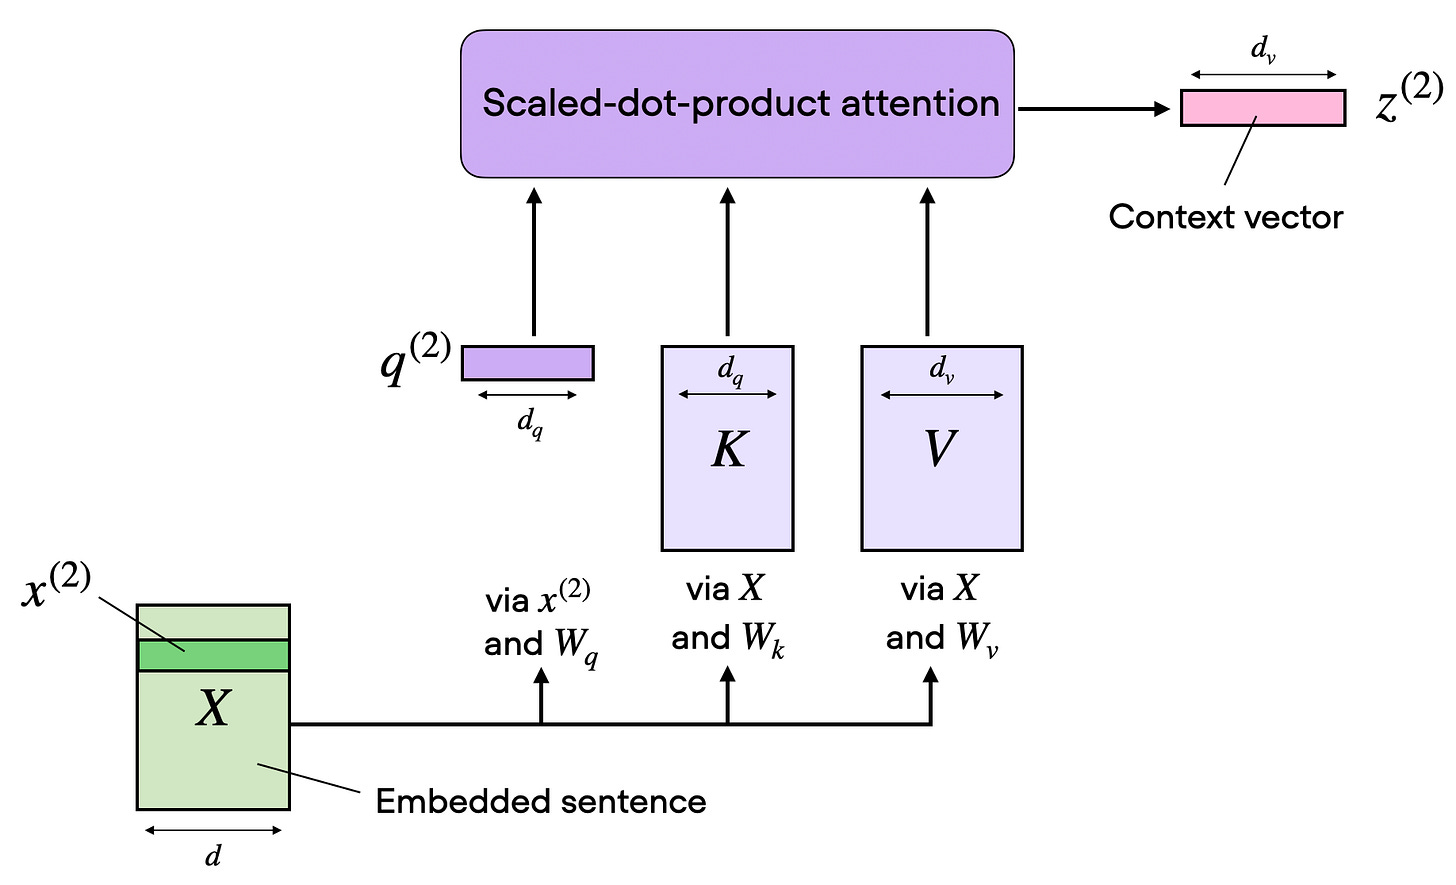
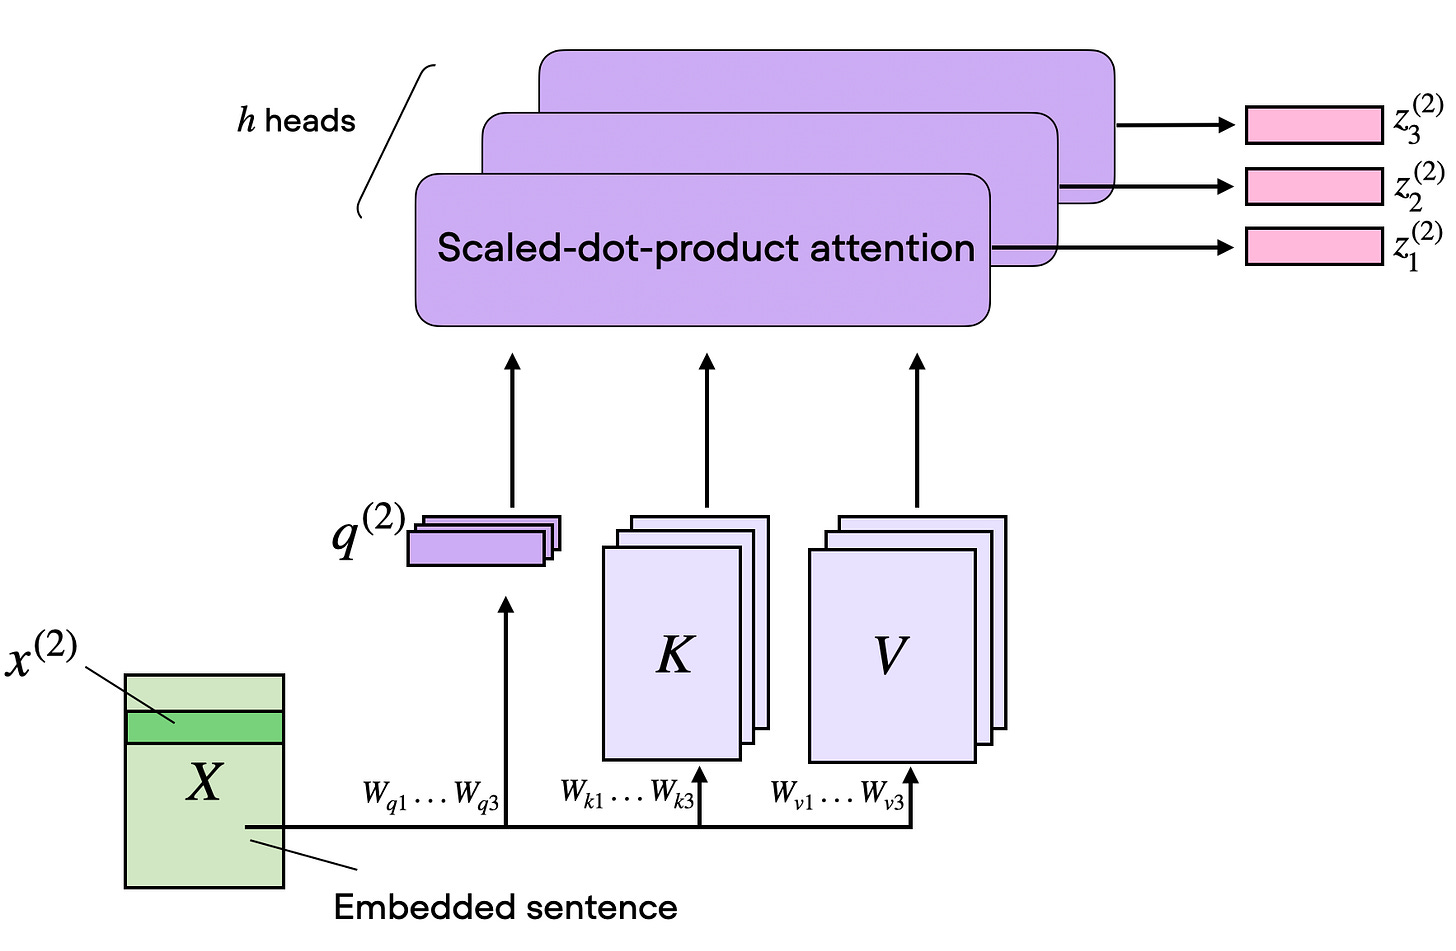
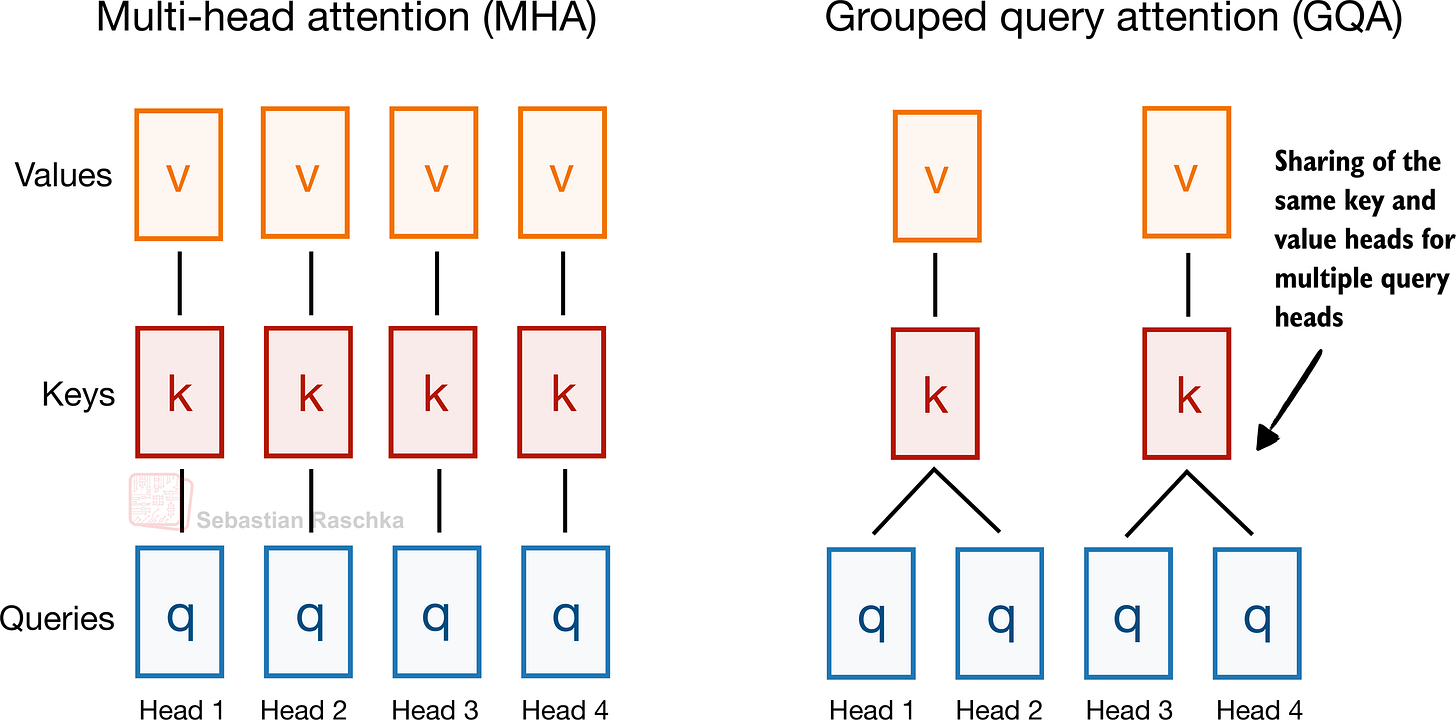
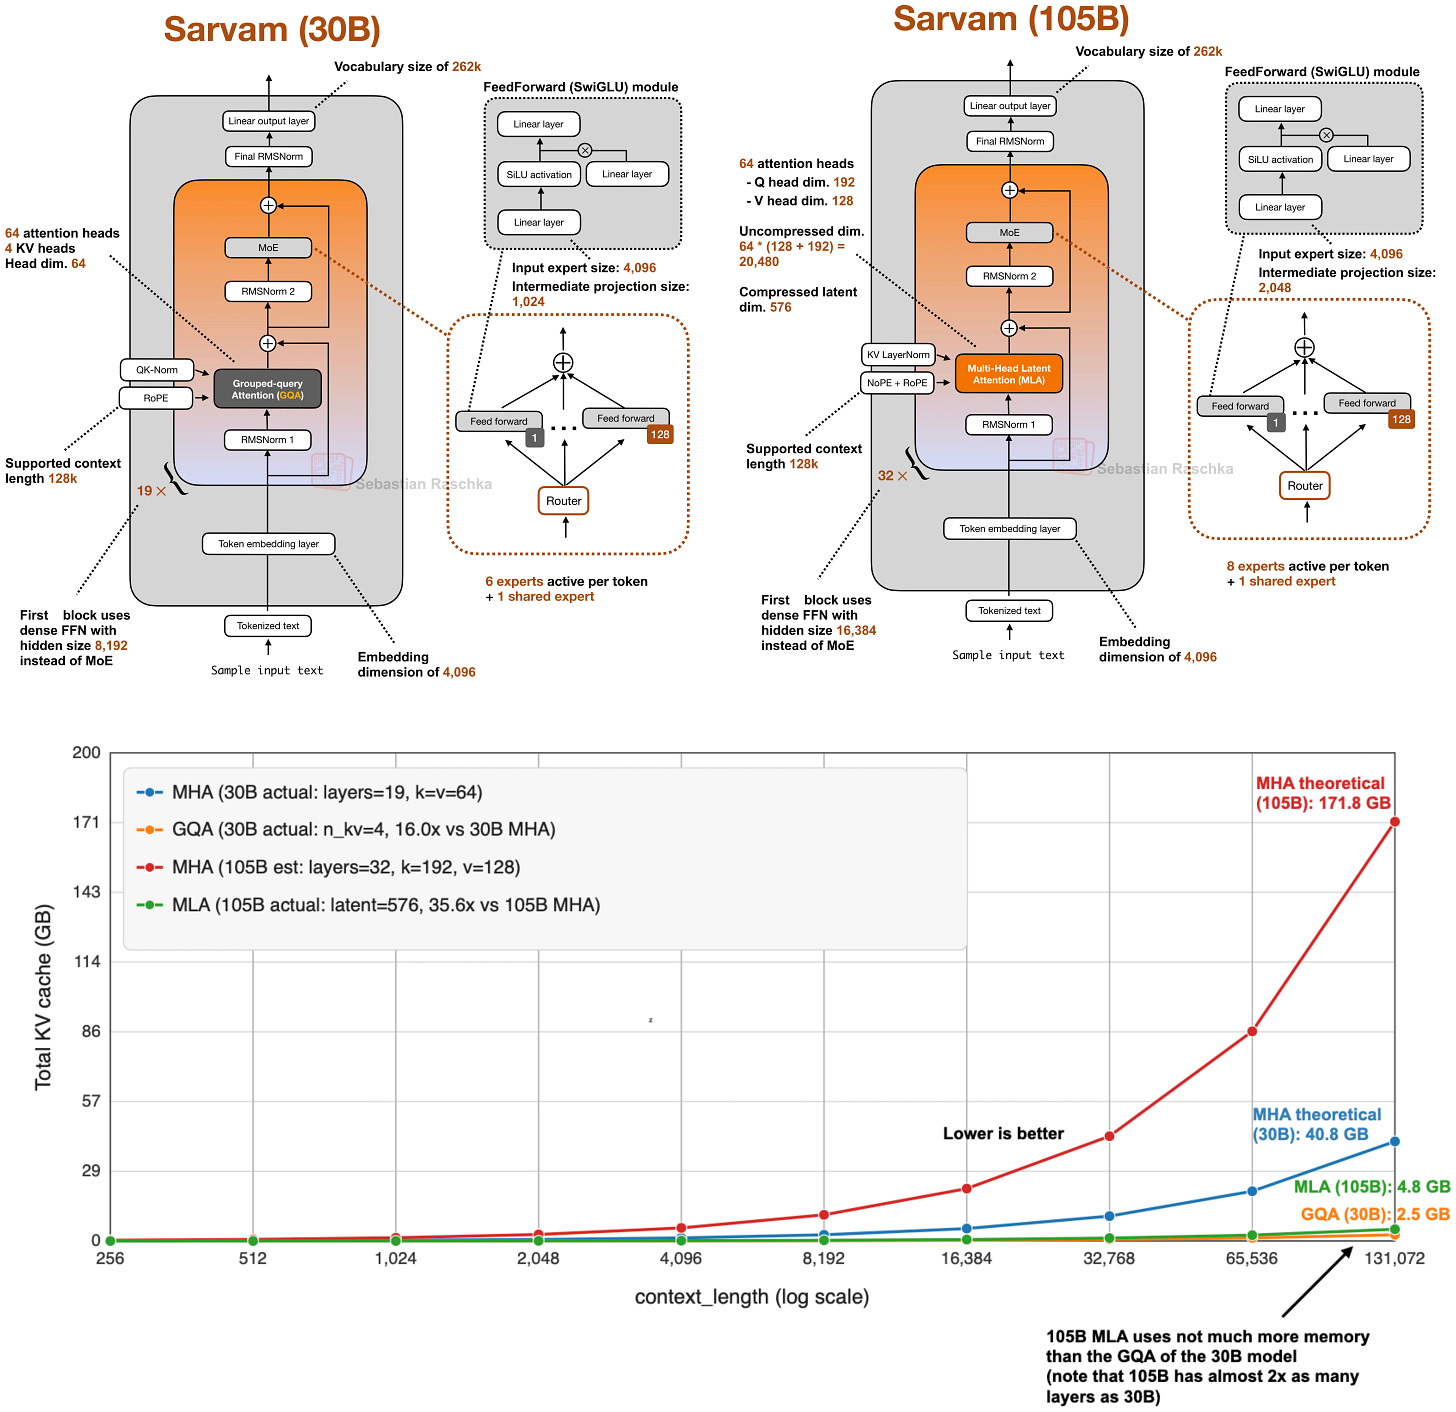
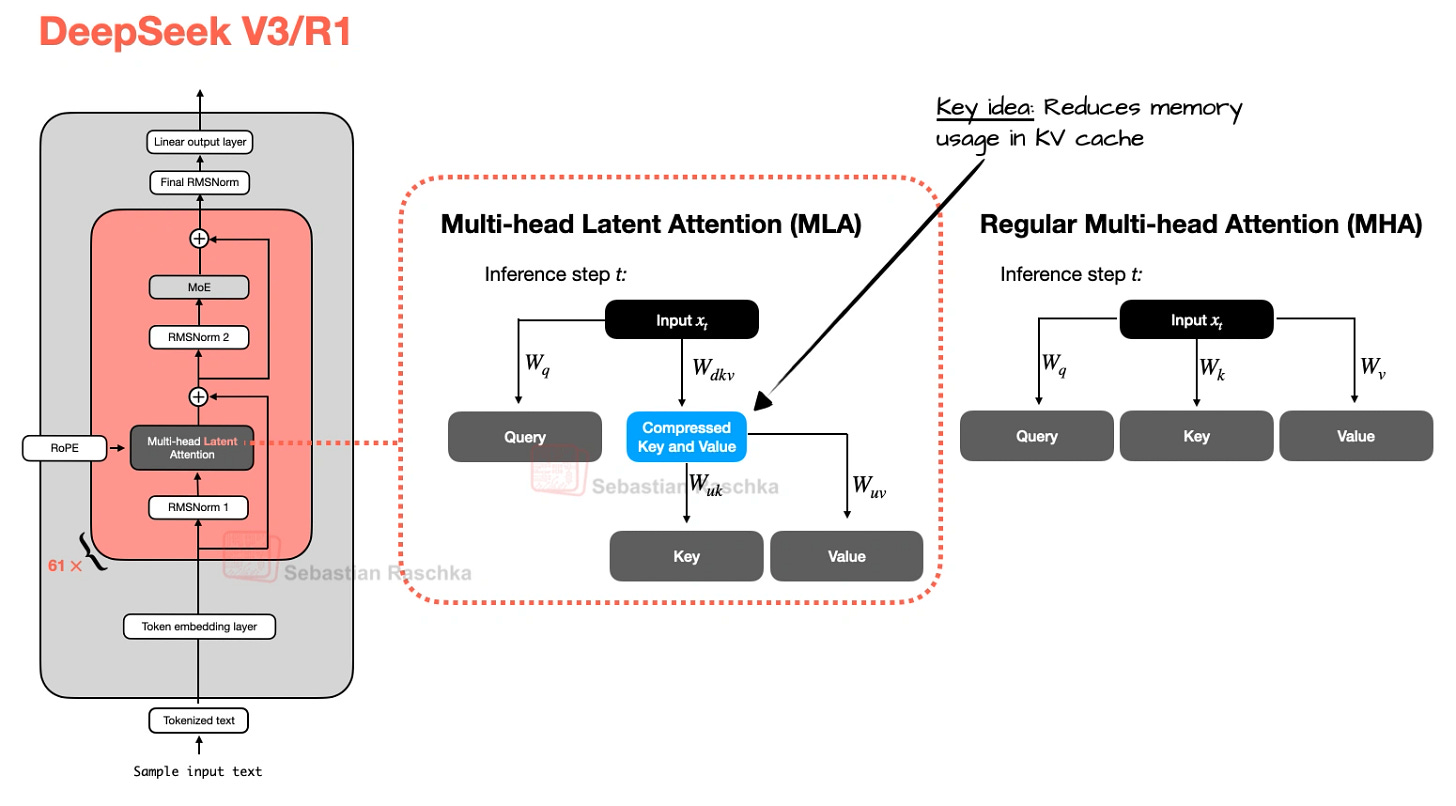
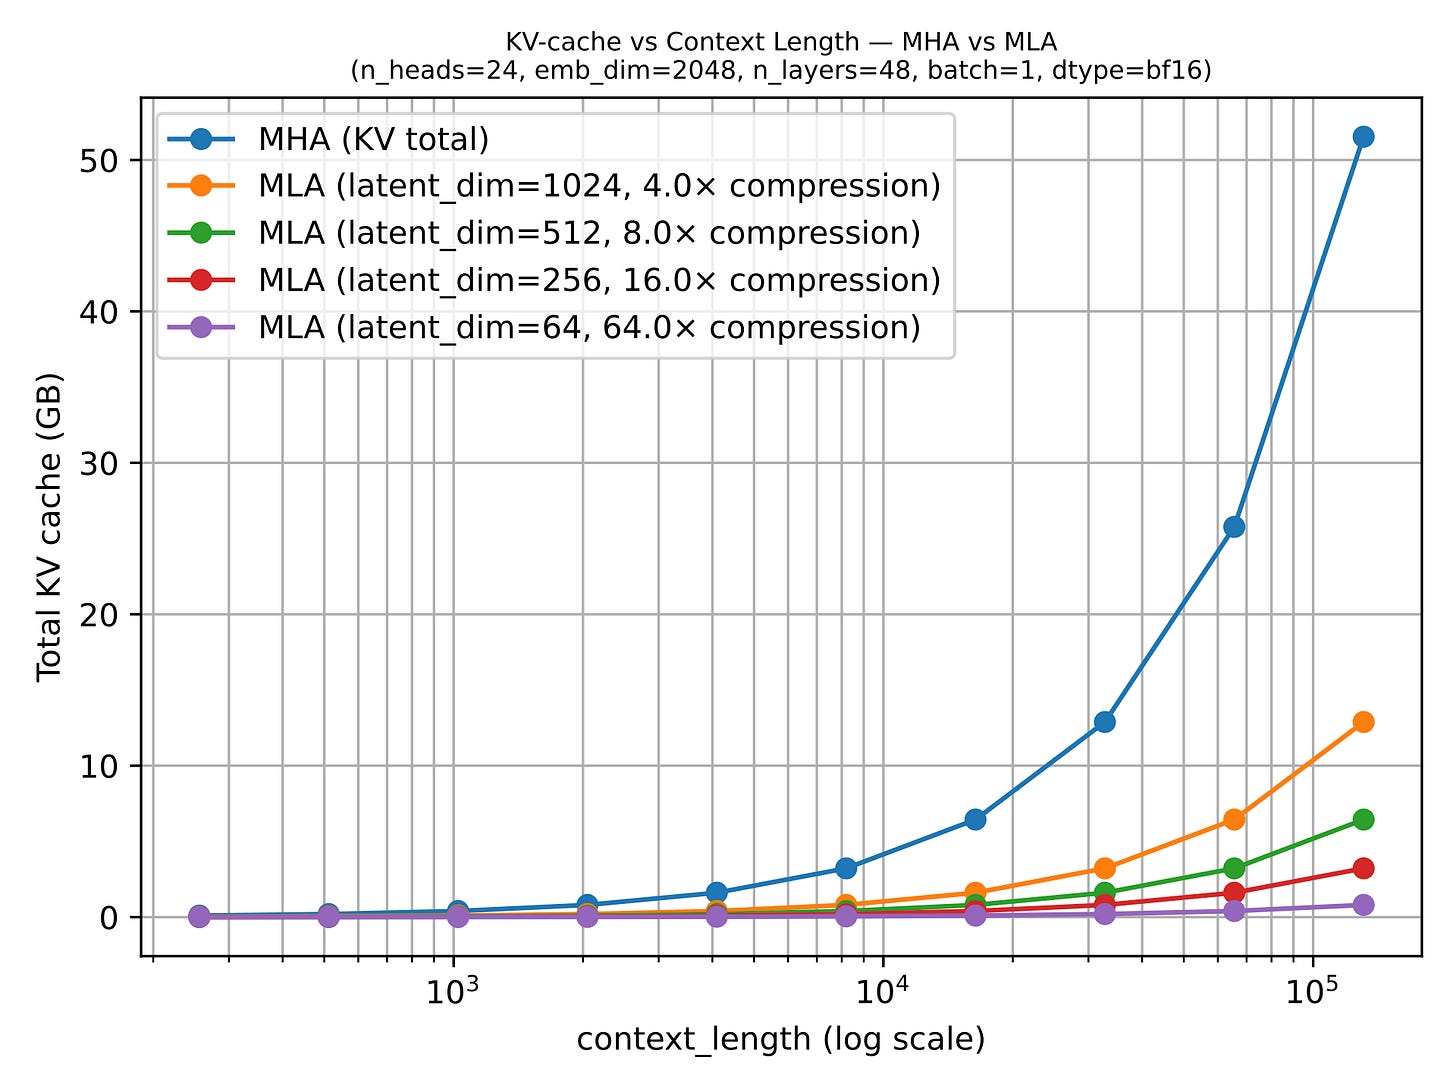
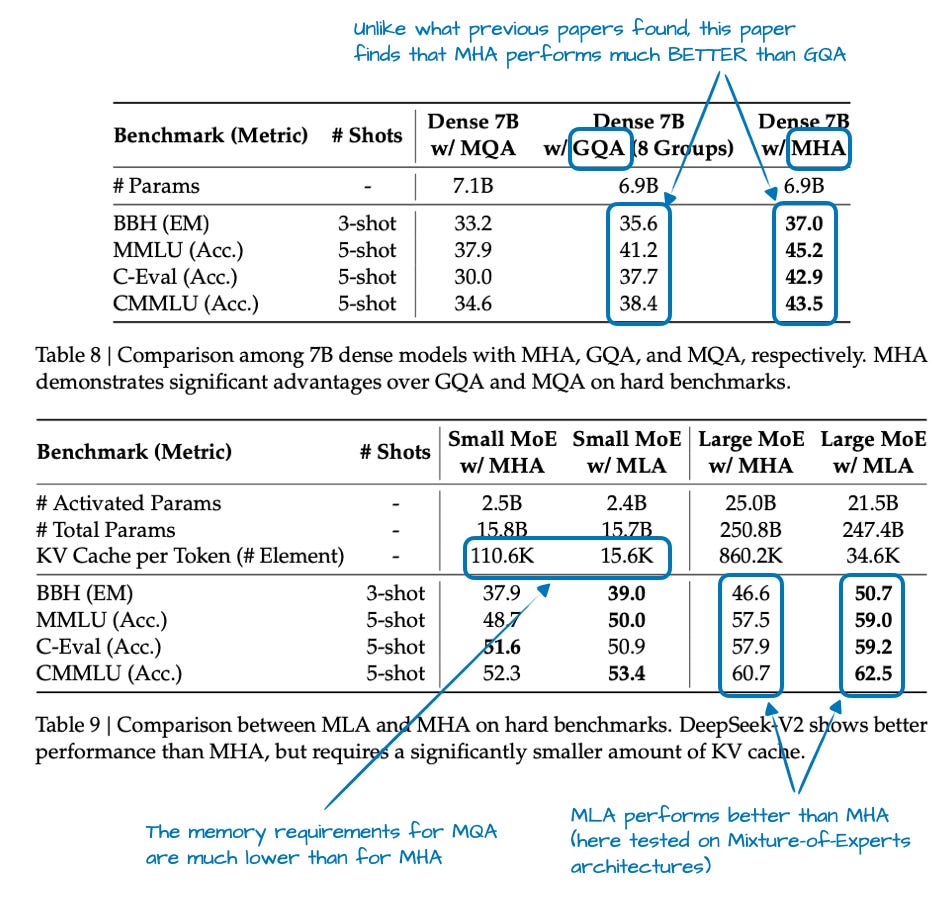
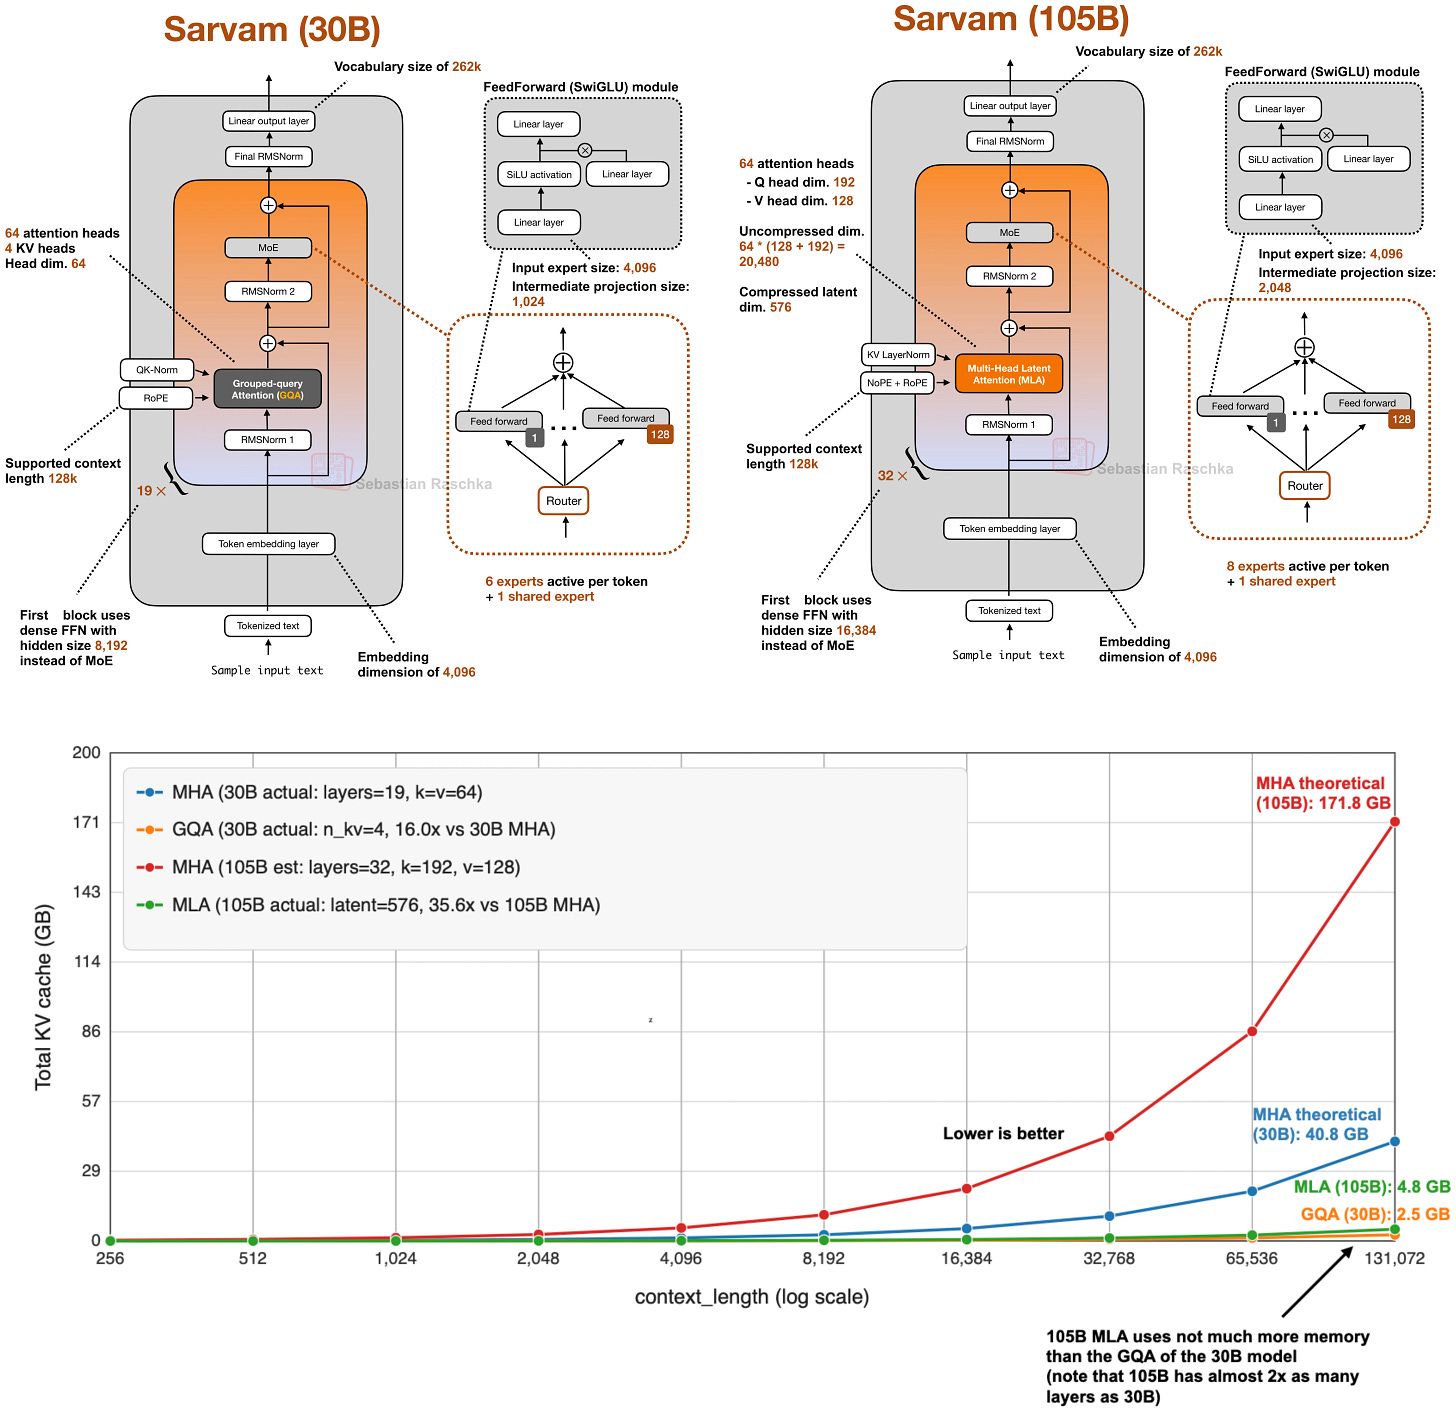
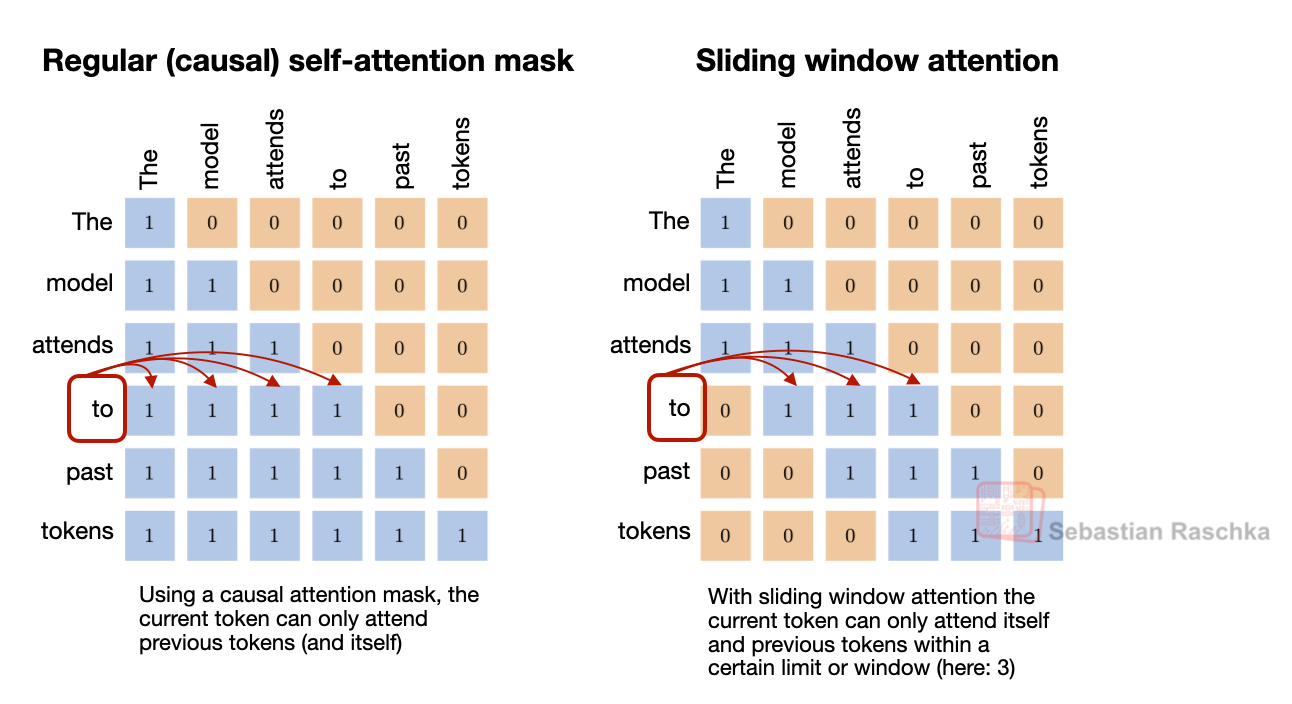
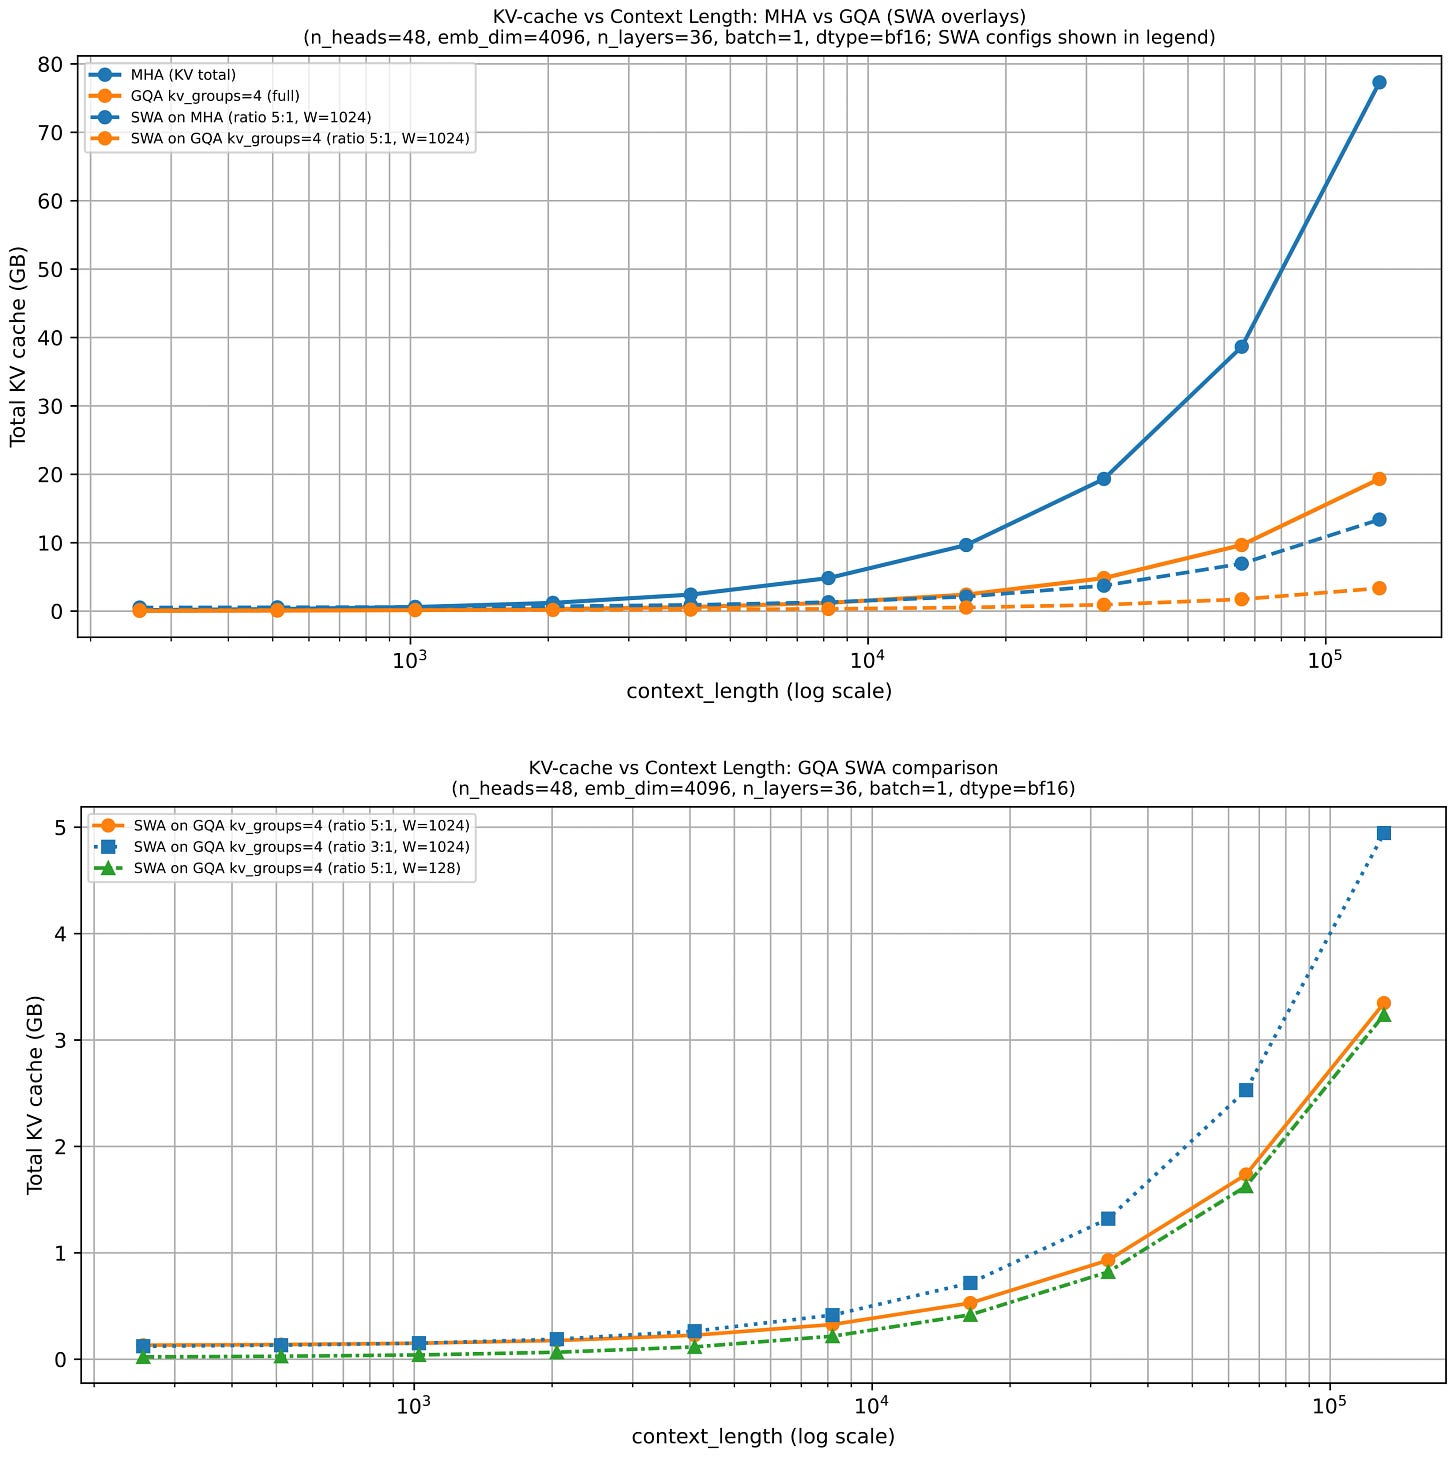
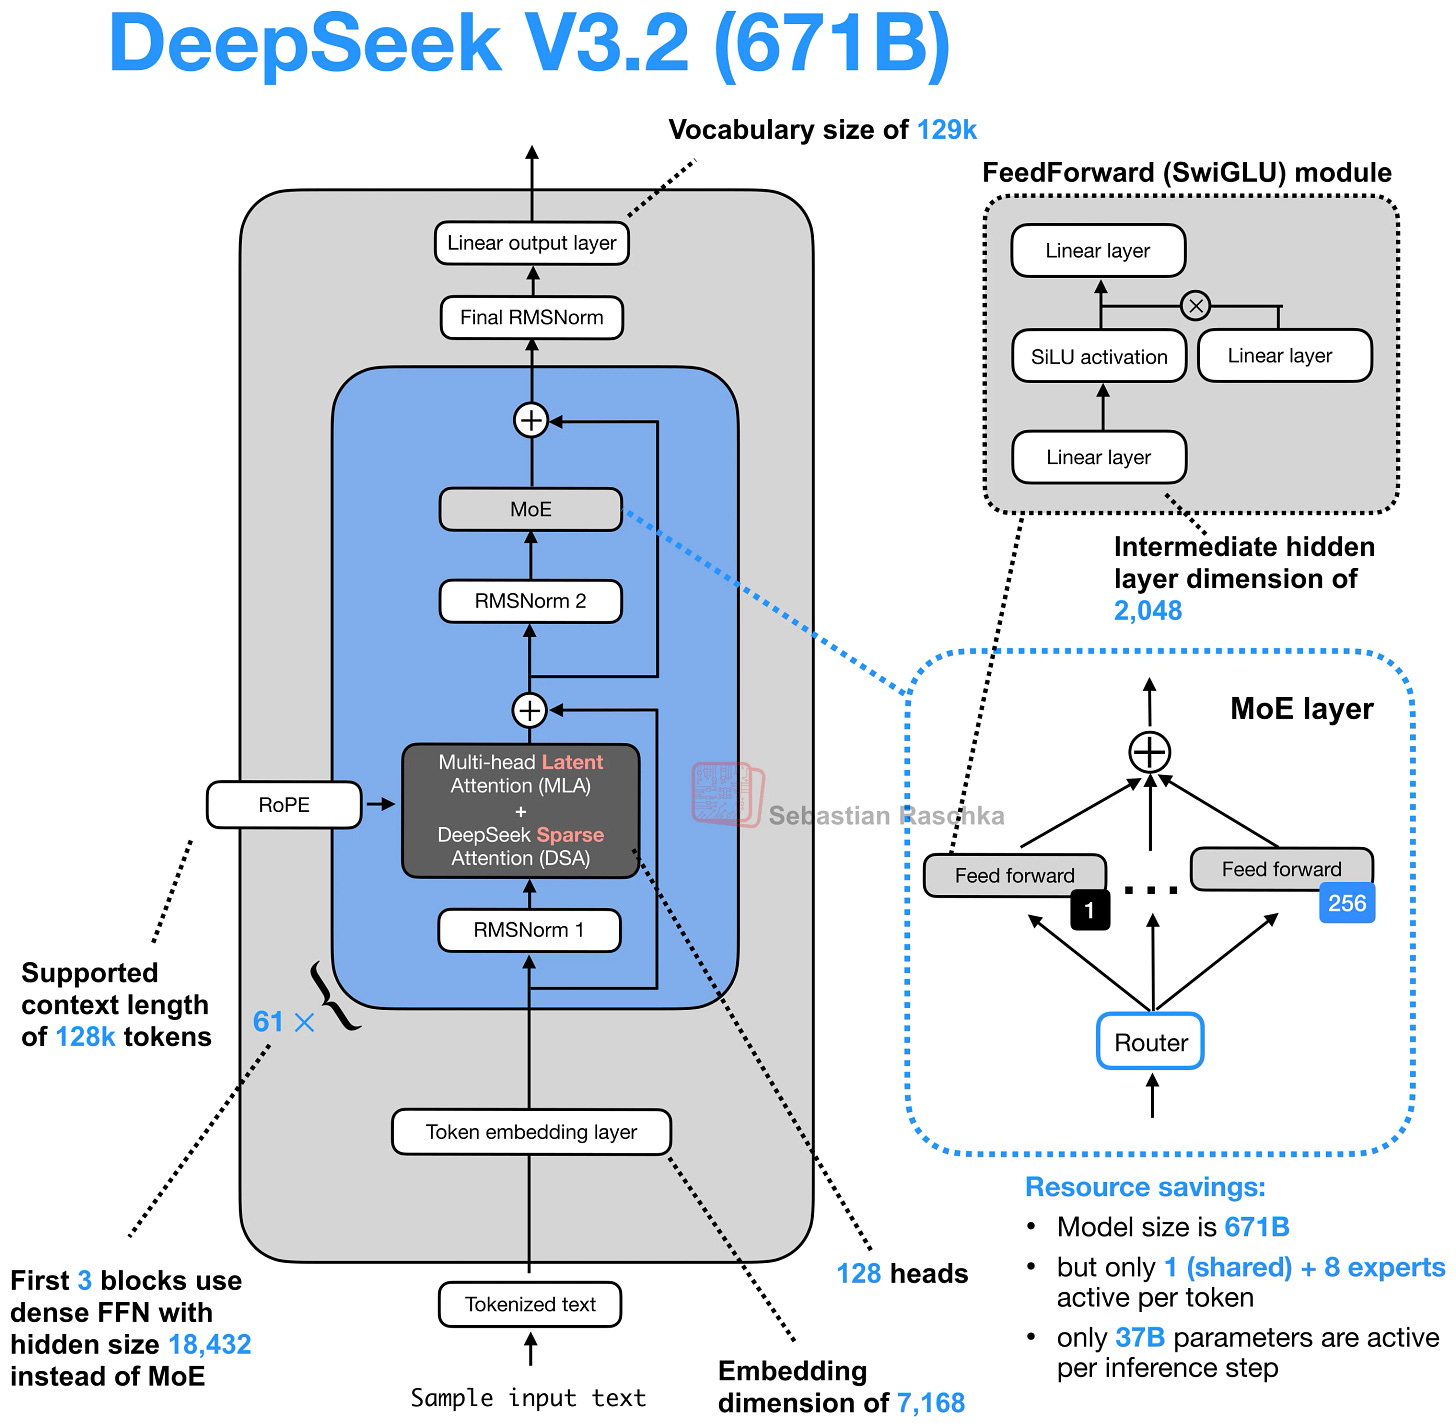
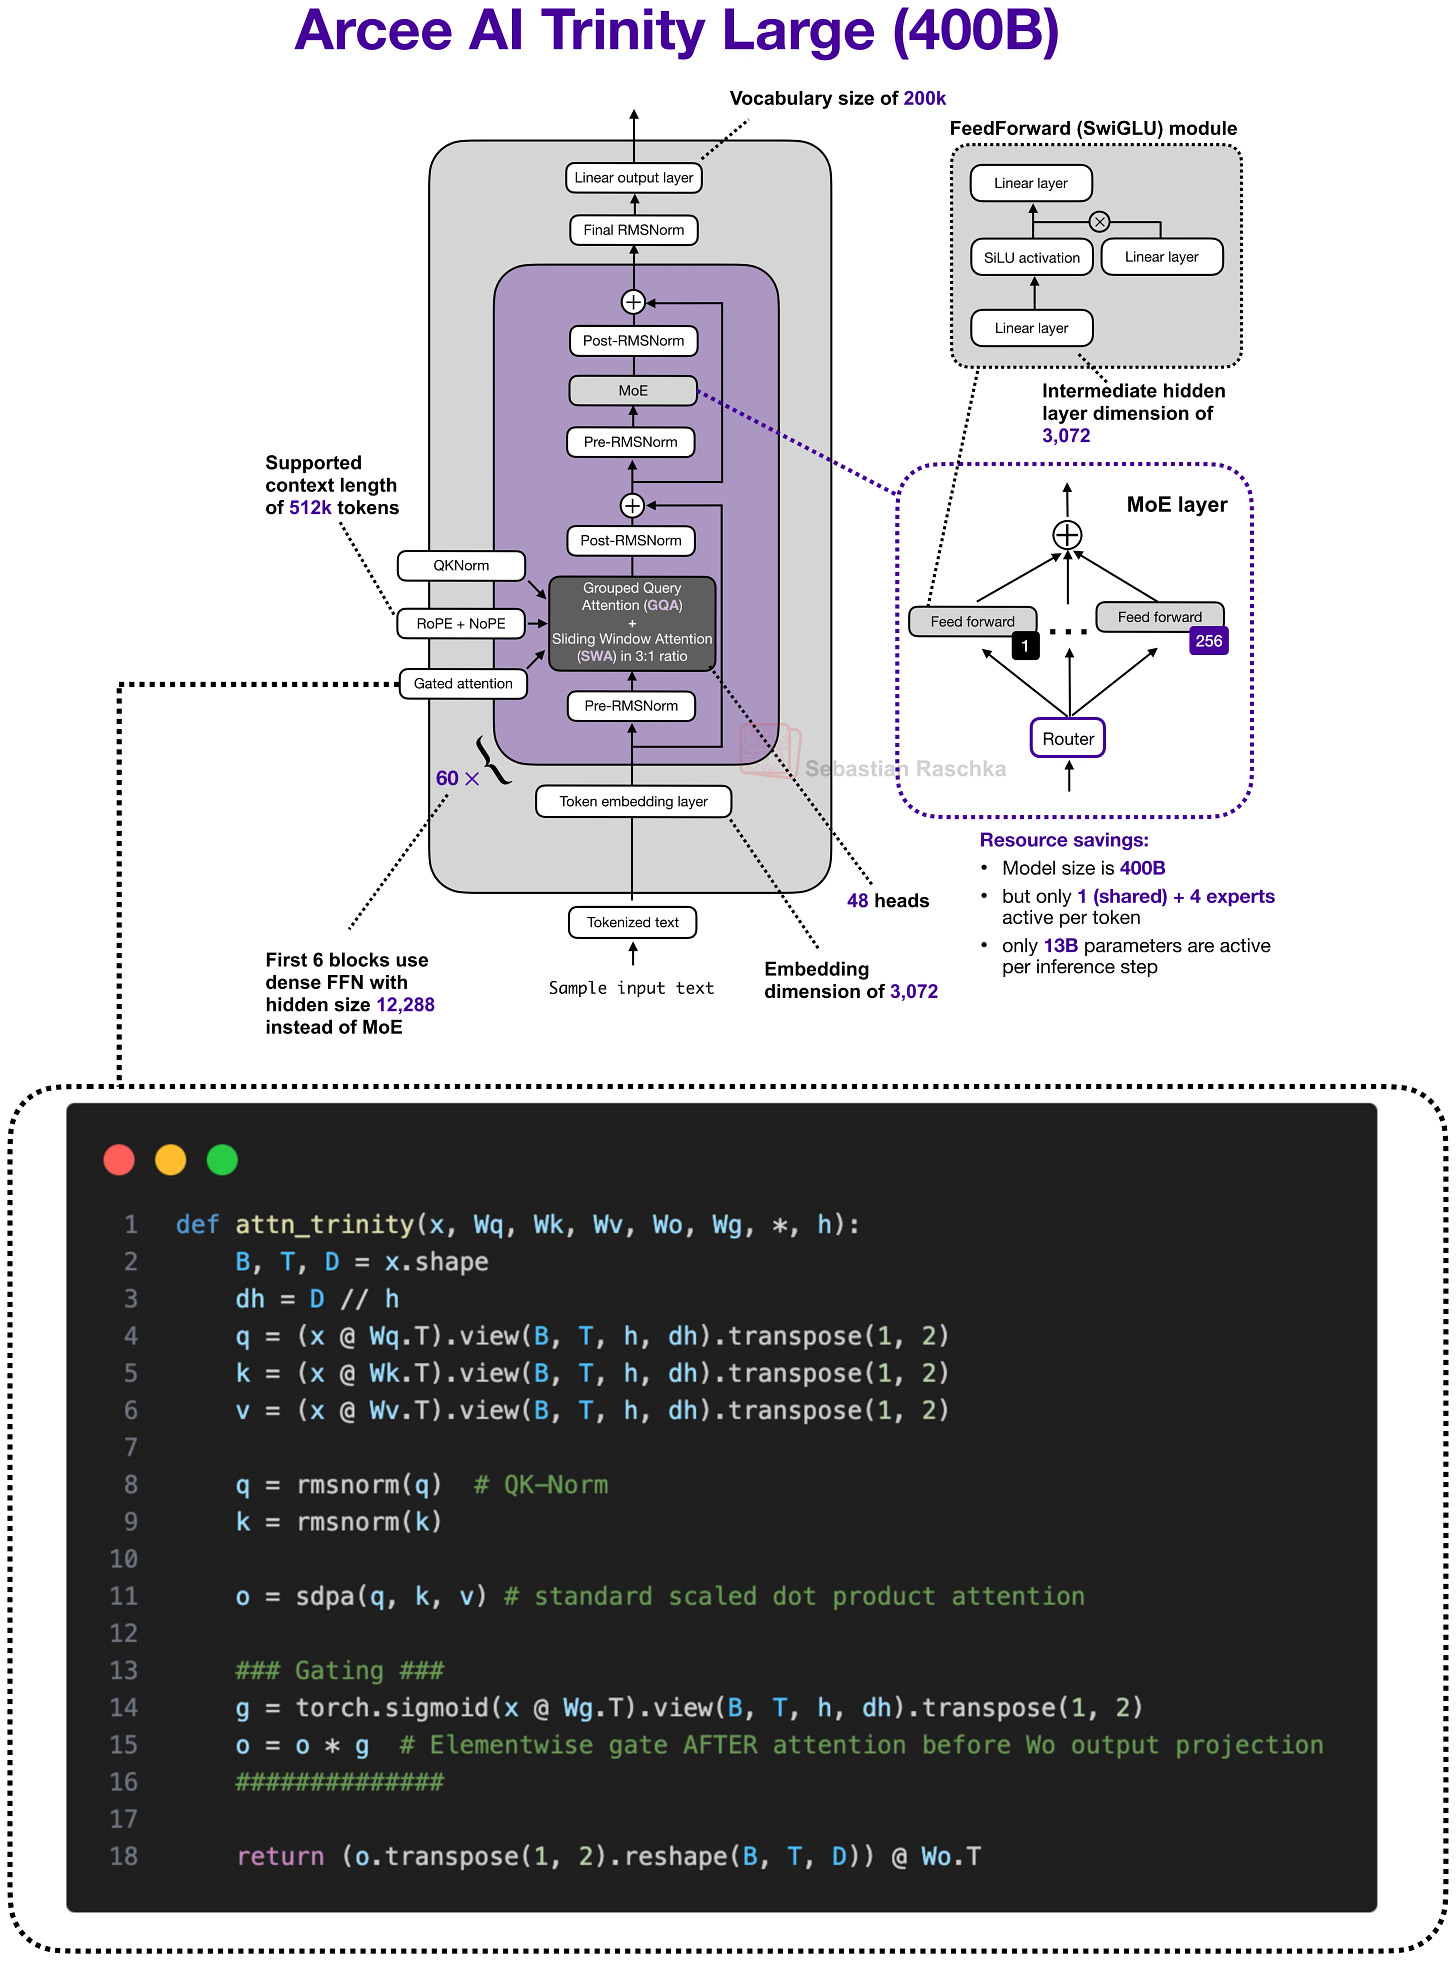
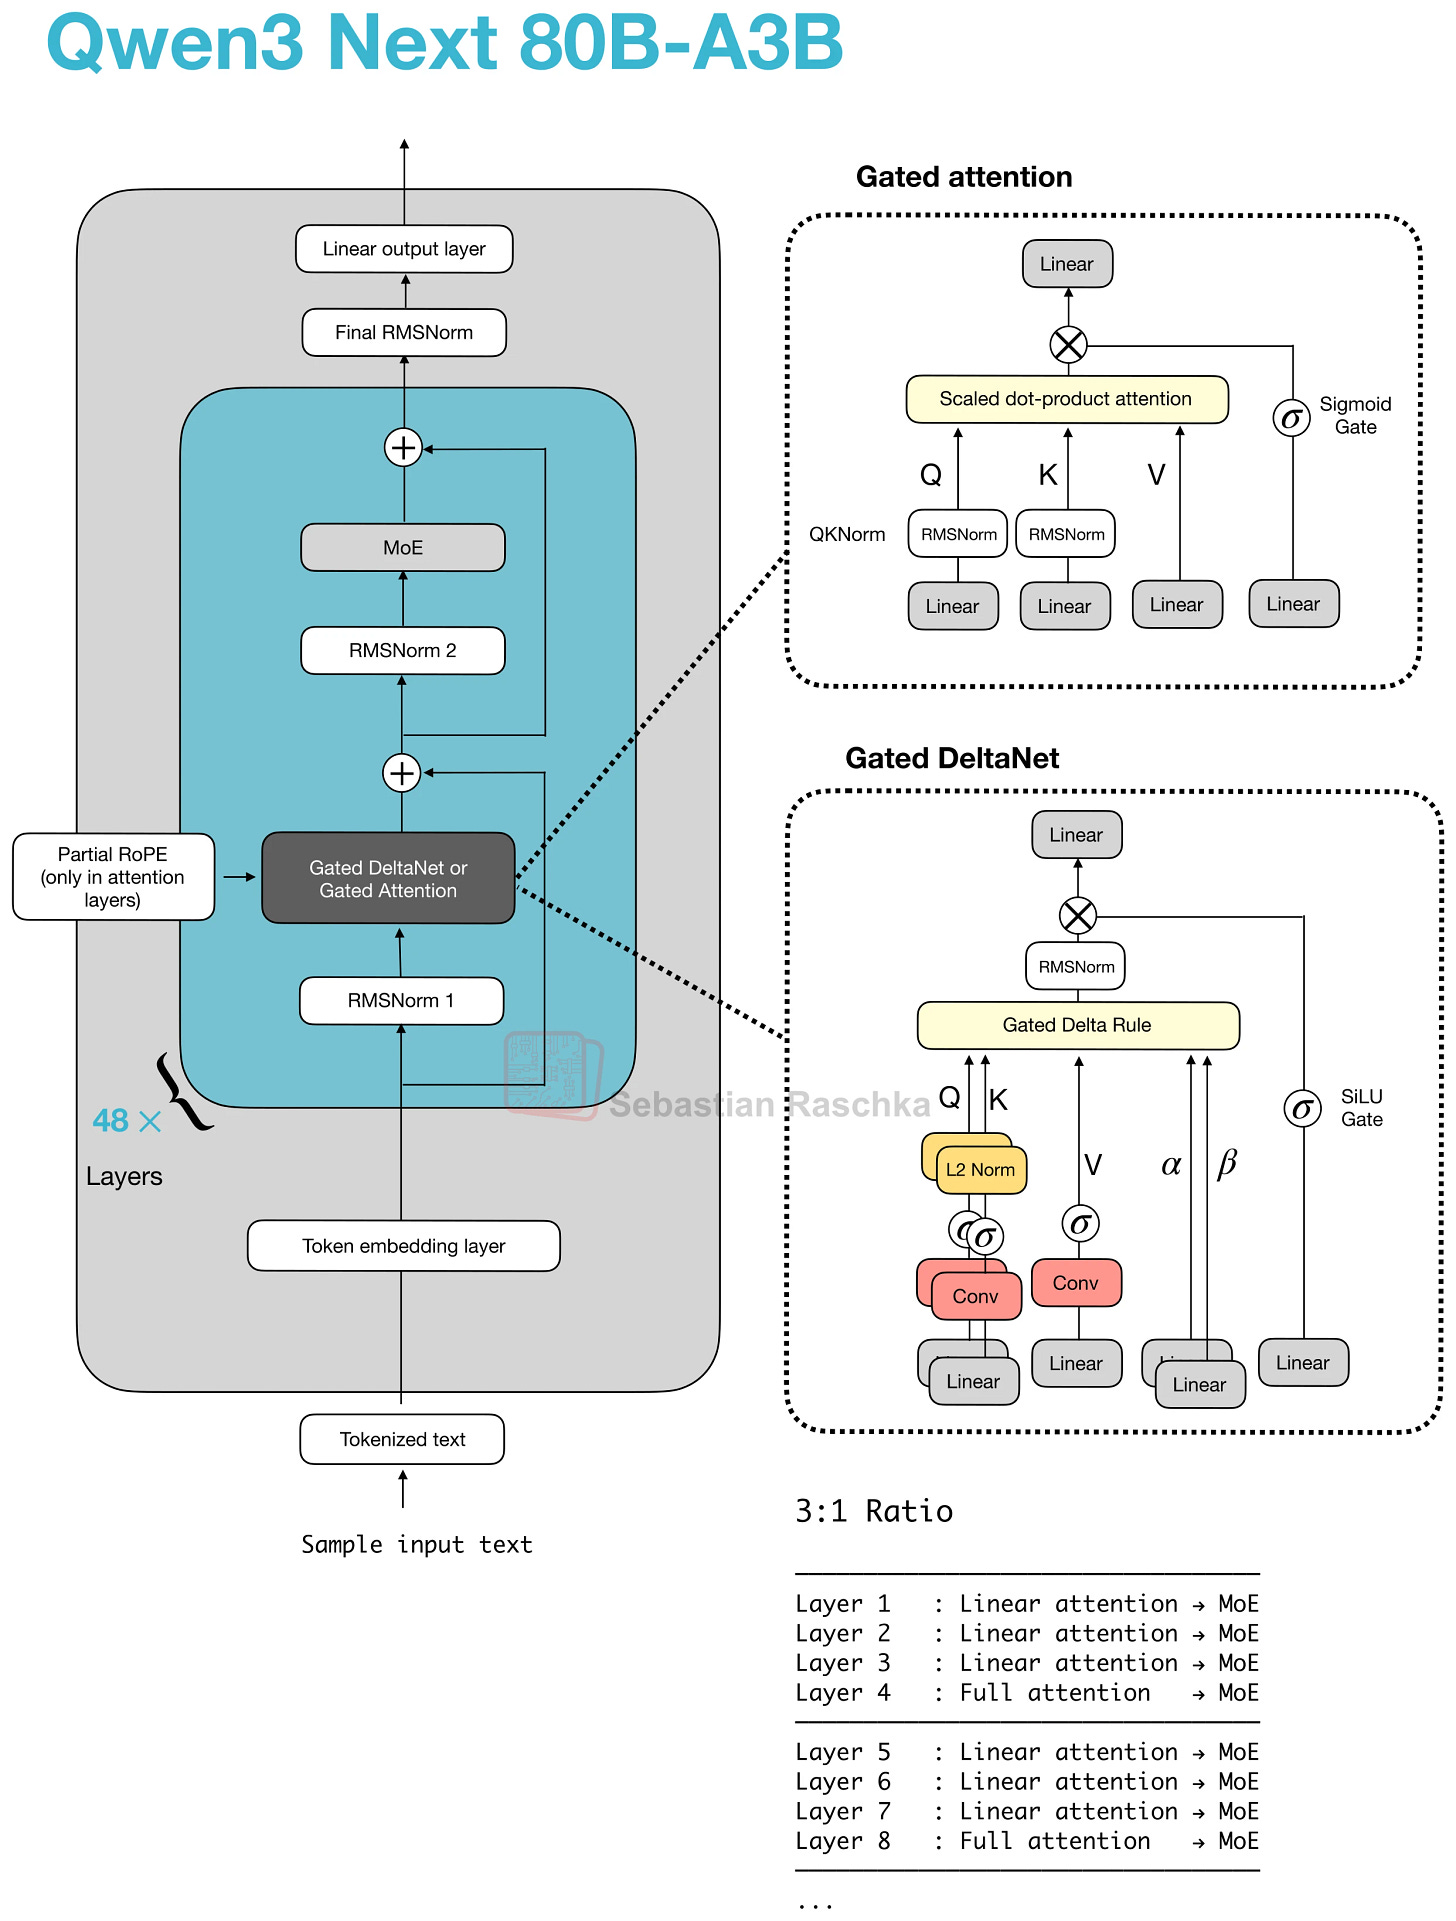
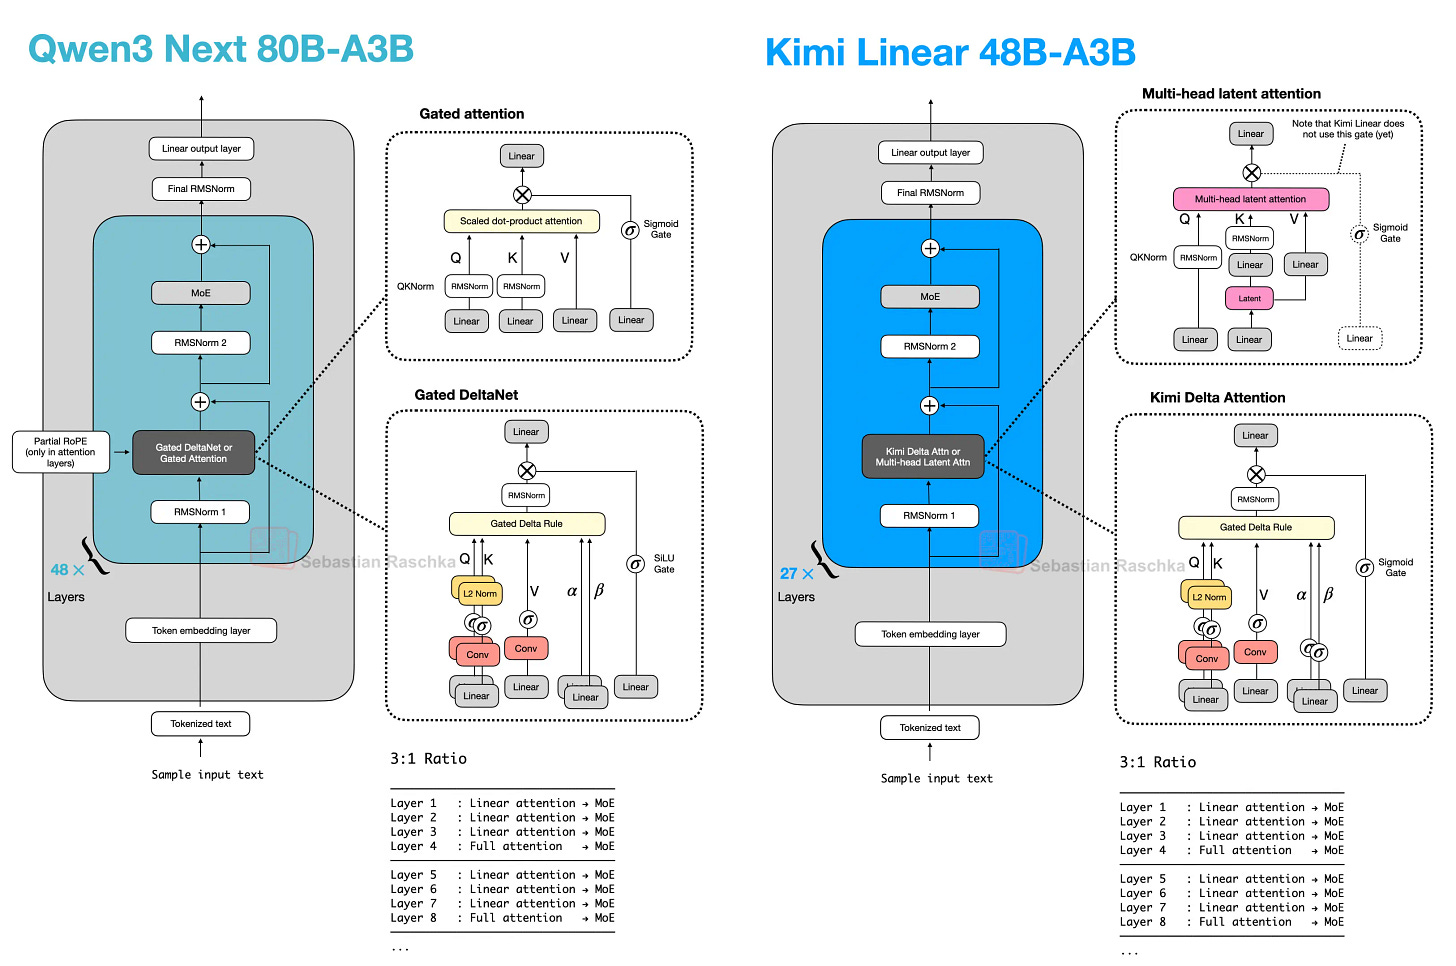
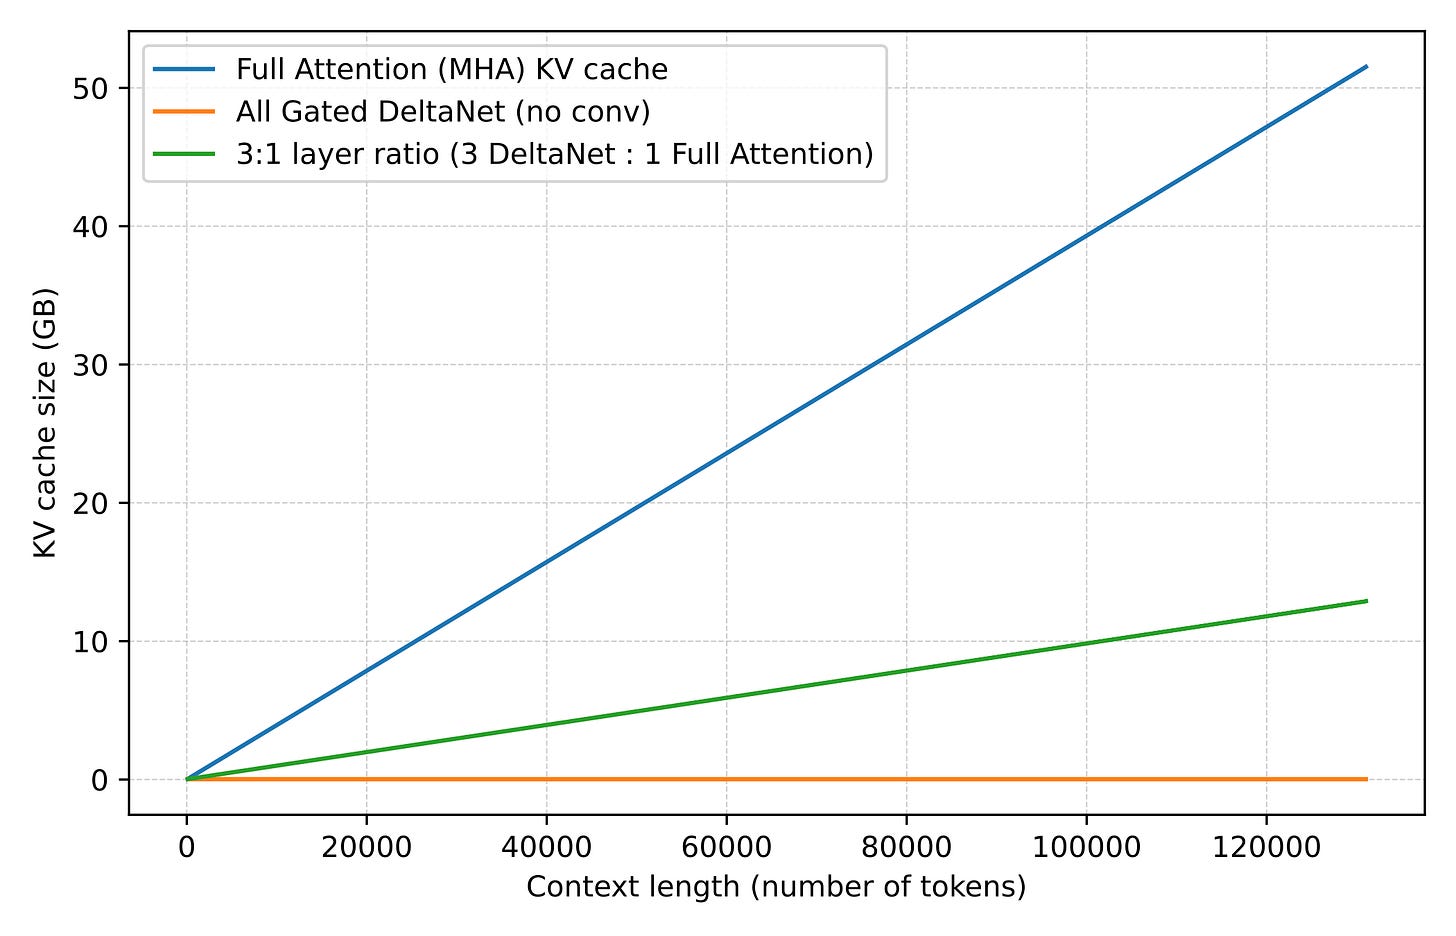
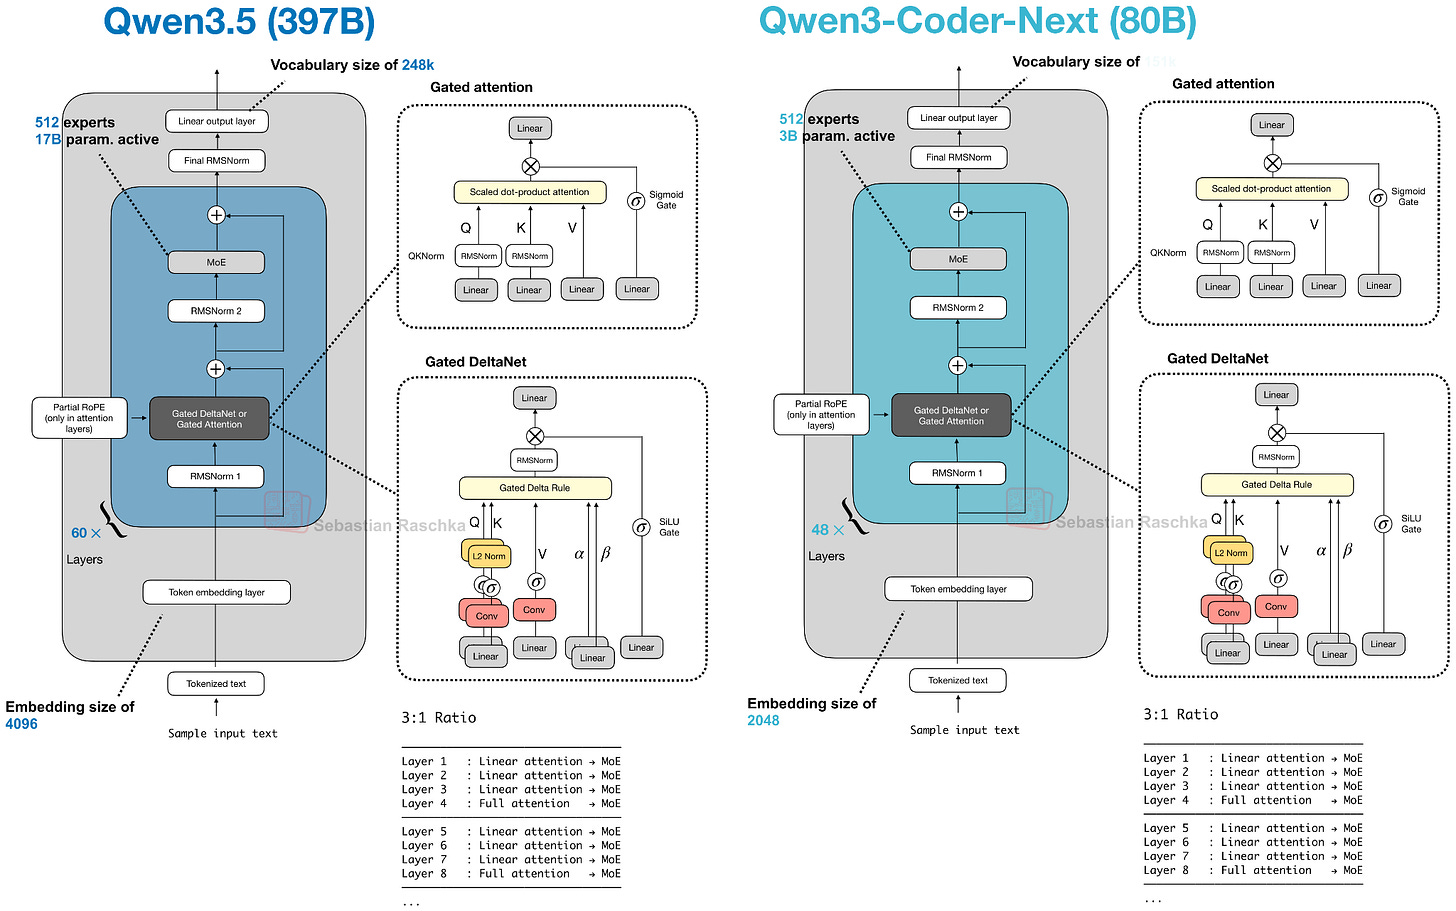
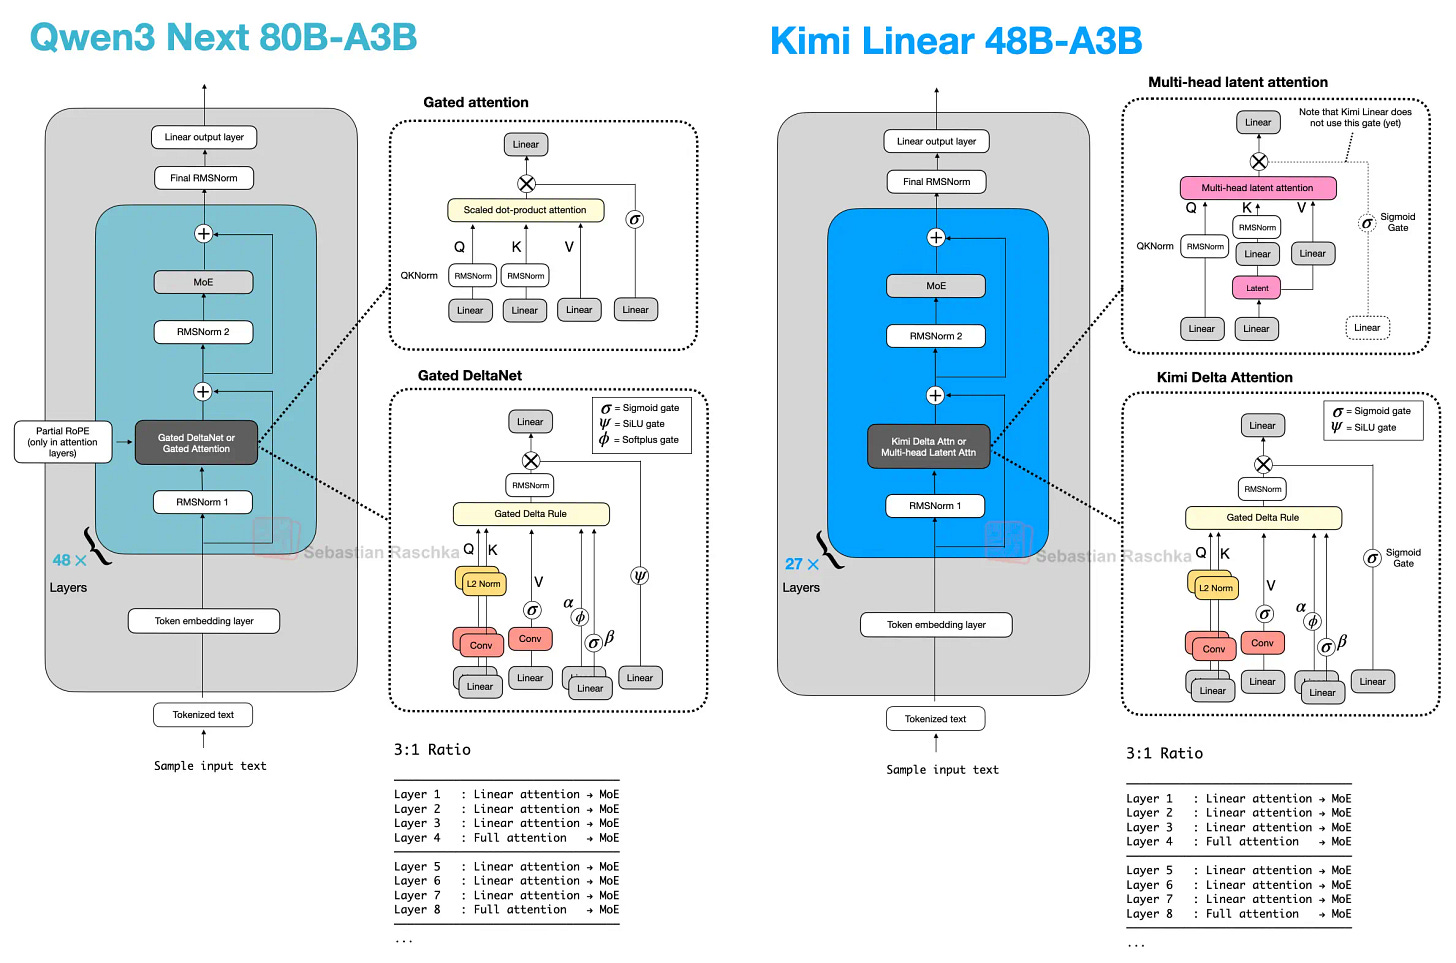
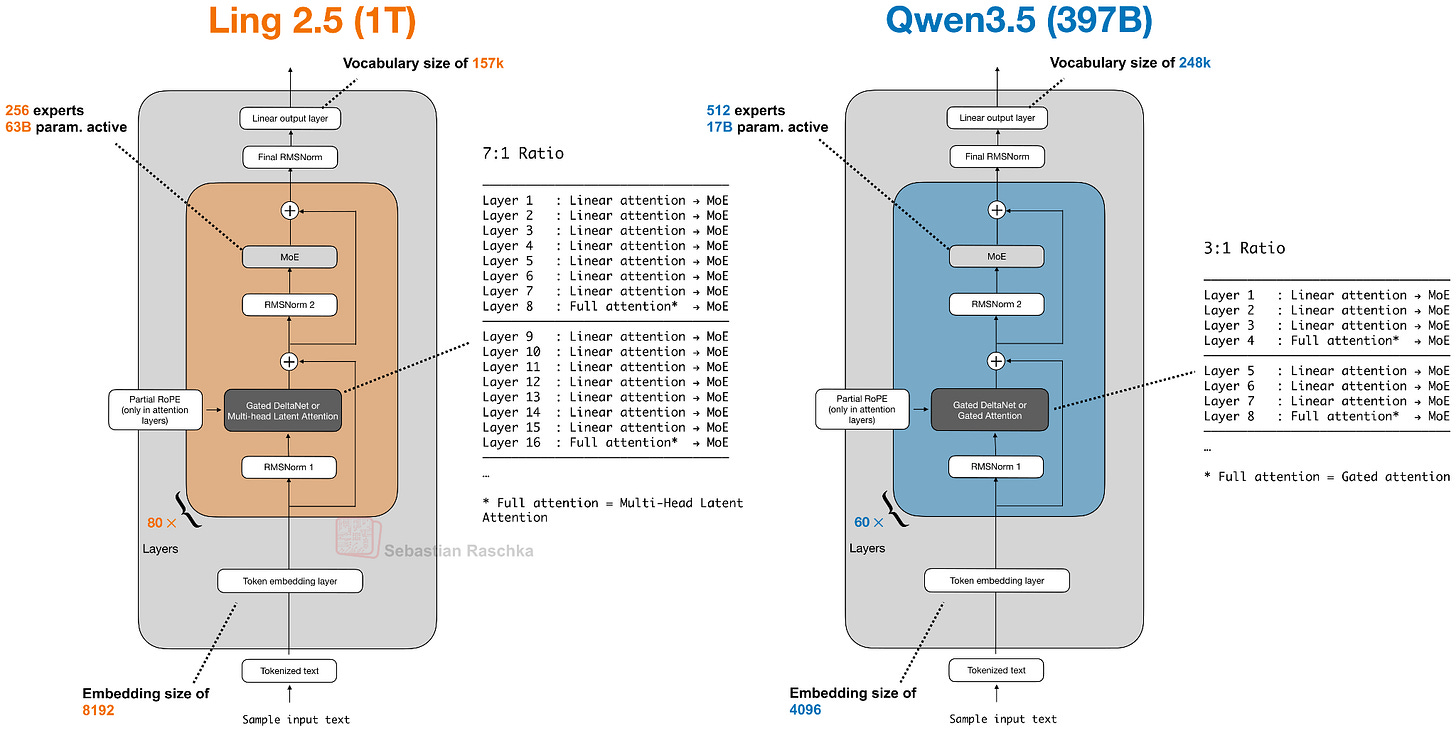
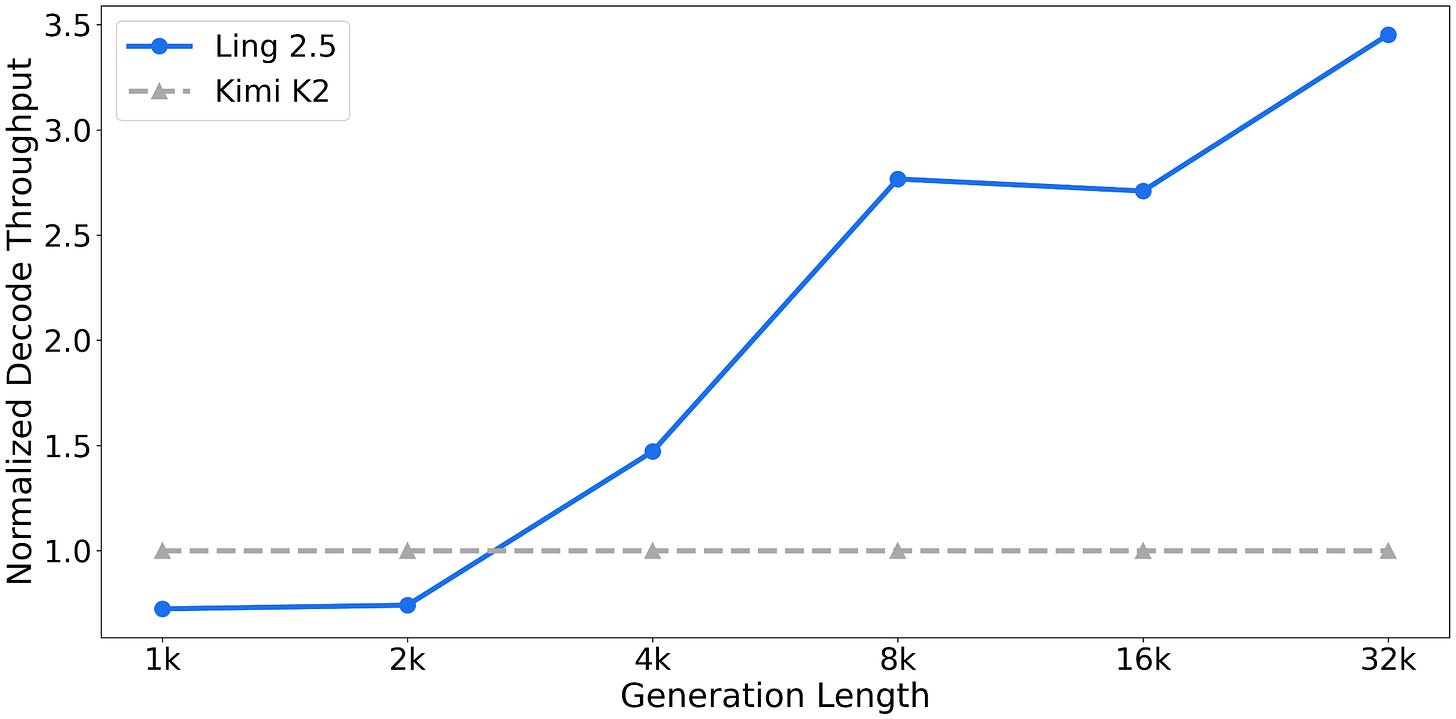
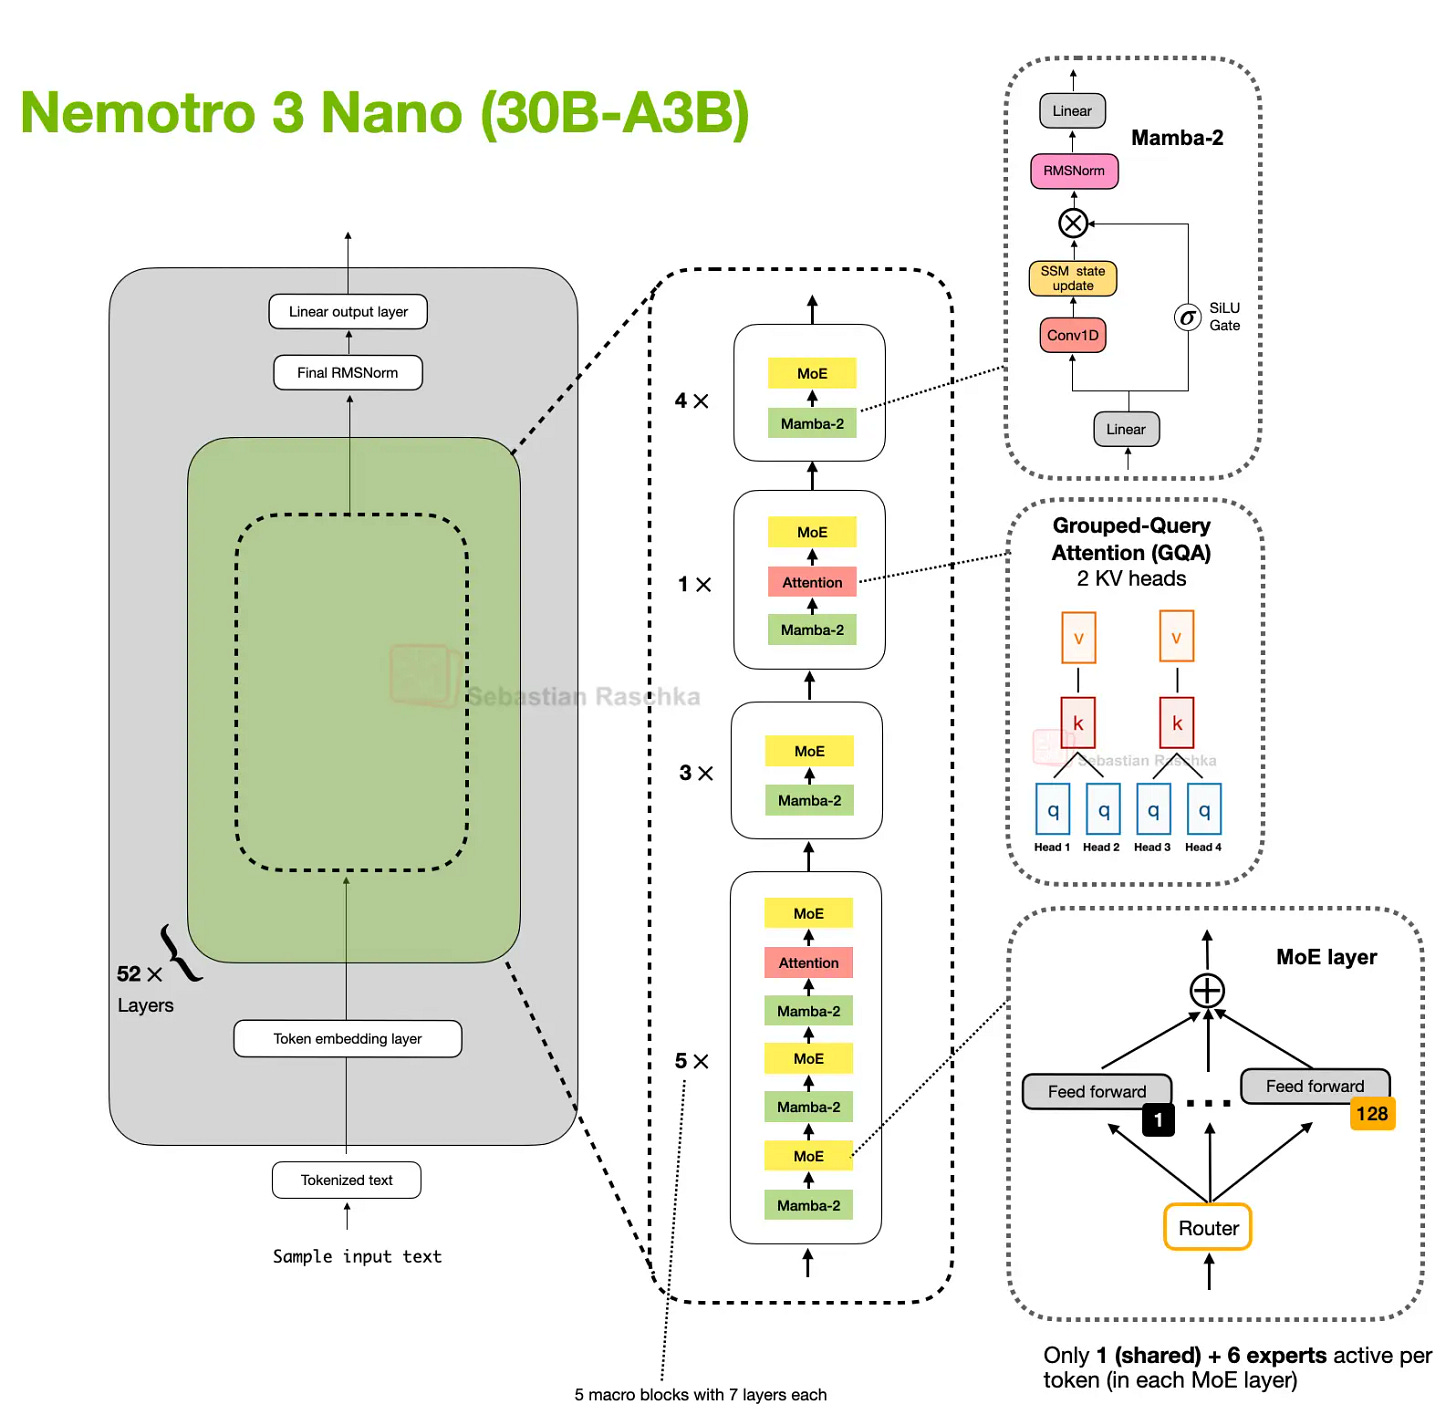
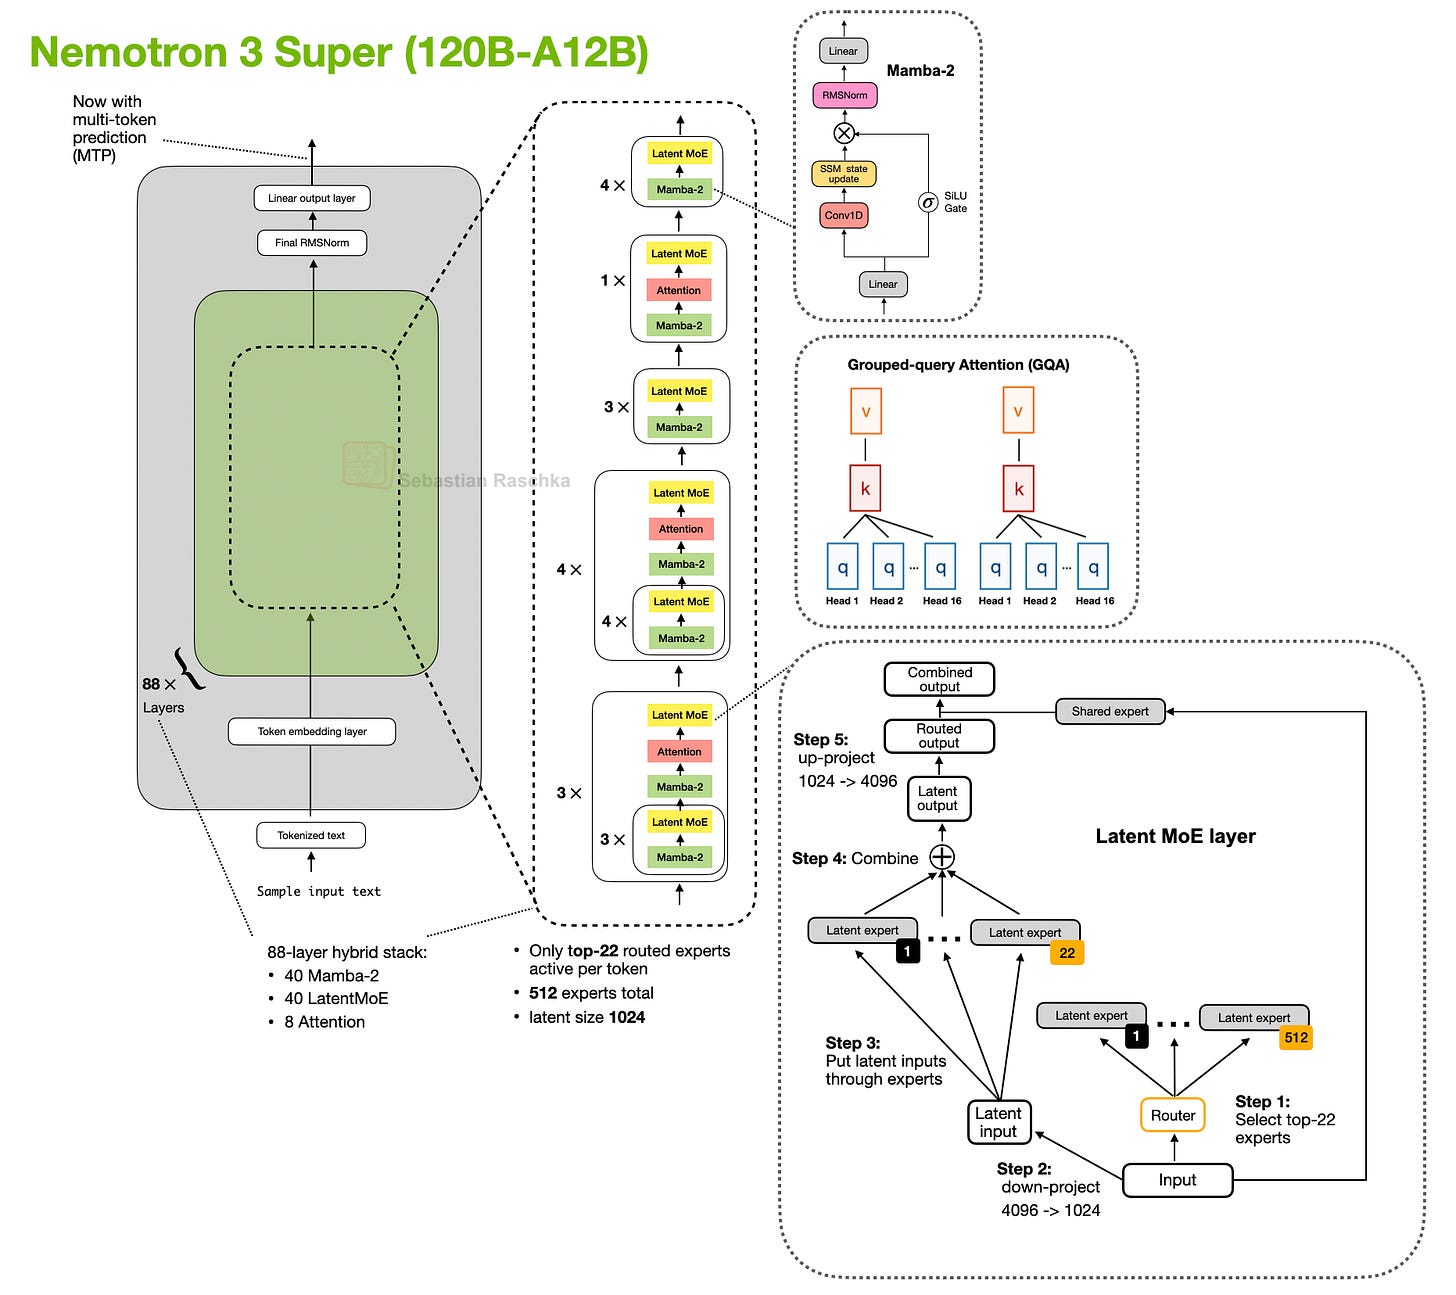
  "articleBody": "I had originally planned to write about DeepSeek V4. Since it still hasn’t been released, I used the time to work on something that had been on my list for a while, namely, collecting, organizing, and refining the different LLM architectures I have covered over the past few years.\n\nSo, over the last two weeks, I turned that effort into an LLM architecture gallery (with 45 entries at the time of this writing), which combines material from earlier articles with several important architectures I had not documented yet. Each entry comes with a visual model card, and I plan to keep the gallery updated regularly.\n\nYou can find the gallery here: [https://sebastianraschka.com/llm-architecture-gallery/](https://sebastianraschka.com/llm-architecture-gallery/)\n\nAfter I shared the initial version, a few readers also asked whether there would be a poster version. So, there is now a [poster version via Redbubble](https://www.redbubble.com/i/poster/LLM-Architecture-Gallery-by-Ahead-of-AI/179274487/flk2). I ordered the Medium size (26.9 x 23.4 in) to check how it looks in print, and the result is sharp and clear. That said, some of the smallest text elements are already quite small at that size, so I would not recommend the smaller versions if you intend to have everything readable.\n\n[![](https://substackcdn.com/image/fetch/$s_!ceew!,w_1456,c_limit,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2F03198b65-472c-495e-92c0-62b6af66d720_1999x1313.jpeg)](https://substackcdn.com/image/fetch/$s_!ceew!,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2F03198b65-472c-495e-92c0-62b6af66d720_1999x1313.jpeg)\n\n*Figure 2: [Poster version](https://www.redbubble.com/i/poster/LLM-Architecture-Gallery-by-Ahead-of-AI/179274487/flk2) of the architecture gallery with some random objects for scale.*\n\nAlongside the gallery, I was/am also working on short explainers for a few core LLM concepts.\n\nSo, in this article, I thought it would be interesting to recap all the recent attention variants that have been developed and used in prominent open-weight architectures in recent years.\n\nMy goal is to make the collection useful both as a reference and as a lightweight learning resource. I hope you find it useful and educational!\n\nSelf-attention lets each token look at the other visible tokens in the sequence, assign them weights, and use those weights to build a new context-aware representation of the input.\n\nMulti-head attention (MHA) is the standard transformer version of that idea. It runs several self-attention heads in parallel with different learned projections, then combines their outputs into one richer representation.\n\n[![](https://substackcdn.com/image/fetch/$s_!GrJT!,w_1456,c_limit,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2Fa3ed41e9-86ee-4c1c-80a5-c9c2ed59dd9c_1366x1410.png)](https://substackcdn.com/image/fetch/$s_!GrJT!,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2Fa3ed41e9-86ee-4c1c-80a5-c9c2ed59dd9c_1366x1410.png)\n\nFigure 3: Olmo 2 as an example architecture using MHA.\n\nThe sections below start with a whirlwind tour of explaining self-attention to explain MHA. It’s more meant as a quick overview to set the stage for related attention concepts like grouped-query attention, sliding window attention, and so on. If you are interested in a longer, more detailed self-attention coverage, you might like my longer [Understanding and Coding Self-Attention, Multi-Head Attention, Causal-Attention, and Cross-Attention in LLMs](https://magazine.sebastianraschka.com/p/understanding-and-coding-self-attention) article.\n\n**EXAMPLE ARCHITECTURES**\n\n[GPT-2](https://sebastianraschka.com/llm-architecture-gallery/#card-gpt-2-xl-1-5b), [OLMo 2 7B](https://sebastianraschka.com/llm-architecture-gallery/#card-olmo-2-7b), and [OLMo 3 7B](https://sebastianraschka.com/llm-architecture-gallery/#card-olmo-3-7b)\n\nAttention predates transformers and MHA. Its immediate background is encoder-decoder RNNs for translation.\n\nIn those older systems, an encoder RNN would read the source sentence token by token and compress it into a sequence of hidden states, or in the simplest version into one final state. Then the decoder RNN had to generate the target sentence from that limited summary. This worked for short and simple cases, but it created an obvious bottleneck once the relevant information for the next output word lived somewhere else in the input sentence.\n\nIn short, the limitation is that the hidden state can’t store infinitely much information or context, and sometimes it would be useful to just refer back to the full input sequence.\n\nThe translation example below shows one of the limitations of this idea. For instance, a sentence can preserve many locally reasonable word choices and still fail as a translation when the model treats the problem too much like a word-by-word mapping. (The top panel shows an exaggerated example where we translate the sentence word by word; obviously, the grammar in the resulting sentence is wrong.) In reality, the correct next word depends on sentence-level structure and on which earlier source words matter at that step. Of course, this could still be translated fine with an RNN, but it would struggle with longer sequences or knowledge retrieval tasks because the hidden state can only store so much information as mentioned earlier.\n\n[![](https://substackcdn.com/image/fetch/$s_!jdH6!,w_1456,c_limit,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2F95e6491c-6457-4af0-83f3-b73310bad668_3566x2495.webp)](https://substackcdn.com/image/fetch/$s_!jdH6!,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2F95e6491c-6457-4af0-83f3-b73310bad668_3566x2495.webp)\n\nFigure 4: Translation can fail even when many individual word choices look reasonable because sentence-level structure still matters (Original source *[LLMs-from-scratch](https://github.com/rasbt/LLMs-from-scratch)*).\n\nThe next figure shows that change more directly. When the decoder is producing an output token, it should not be limited to one compressed memory path. It should be able to reach back to the more relevant input tokens directly.\n\n[![](https://substackcdn.com/image/fetch/$s_!T2XV!,w_1456,c_limit,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2Feaafc89d-0765-4e90-8f2b-881032cb2d5b_3415x1914.webp)](https://substackcdn.com/image/fetch/$s_!T2XV!,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2Feaafc89d-0765-4e90-8f2b-881032cb2d5b_3415x1914.webp)\n\nFigure 5: Attention breaks the RNN bottleneck by letting the current output position revisit the full input sequence instead of relying on one compressed state alone (Original source *[LLMs-from-scratch](https://github.com/rasbt/LLMs-from-scratch)*).\n\nTransformers keep that core idea from the aforementioned attention-modified RNN but remove the recurrence. In the classic *[Attention Is All You Need](https://arxiv.org/abs/1706.03762)* paper, attention becomes the main sequence-processing mechanism itself (instead of being just part of an RNN encoder-decoder.)\n\nIn transformers, that mechanism is called self-attention, where each token in the sequence computes weights over all other tokens and uses them to mix information from those tokens into a new representation. Multi-head attention is the same mechanism run several times in parallel.\n\nFor a sequence of `T` tokens, attention needs one row of weights per token, so overall we get a `T x T`matrix.\n\nEach row answers a simple question. When updating this token, how much should each visible token matter? In a decoder-only LLM, future positions are masked out, which is why the upper-right part of the matrix is grayed out in the figure below.\n\nSelf-attention is fundamentally about learning these token-to-token weight patterns, under a causal mask, and then using them to build context-aware token representations.\n\n[![](https://substackcdn.com/image/fetch/$s_!8wZw!,w_1456,c_limit,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2Fd6e9affd-687b-4170-b1d5-f8e3d2834d2b_3449x1646.webp)](https://substackcdn.com/image/fetch/$s_!8wZw!,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2Fd6e9affd-687b-4170-b1d5-f8e3d2834d2b_3449x1646.webp)\n\nFigure 6: A concrete masked attention matrix where each row belongs to one token, each entry is an attention weight, and future-token entries are removed by the causal mask (Original source *[Understanding and Coding Self-Attention](https://magazine.sebastianraschka.com/p/understanding-and-coding-self-attention)*).\n\nThe next figure shows how the transformer computes the attention matrix (`A`) from the input embeddings `X`, which is then used to produce the transformed inputs (`Z`).\n\nHere `Q`, `K`, and `V` stand for queries, keys, and values. The query for a token represents what that token is looking for, the key represents what each token makes available for matching, and the value represents the information that gets mixed into the output once the attention weights have been computed.\n\nThe steps are as follows:\n\n- `Wq`, `Wk`, and `Wv` are weight matrices that project the input embeddings into `Q`, `K`, and `V`\n\n- `QK^T` produces the raw token-to-token relevance scores\n\n- softmax converts those scores into the normalized attention matrix `A` that we discussed in the previous section\n\n- `A` is applied to `V` to produce the output matrix `Z`\n\nNote that the attention matrix is not a separate hand-written object. It emerges from `Q`, `K`, and softmax.\n\nThe next figure shows the same concept as the previous figure but the attention matrix computation is hidden inside the “scaled-dot-product attention” box, and we perform the computation only for one input token instead of all input tokens. This is to show a compact form of self-attention with a single head before extending this to multi-head attention in the next section.\n\n[![](https://substackcdn.com/image/fetch/$s_!VJyp!,w_1456,c_limit,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2F7dfb70d9-5eb6-44df-a880-3a37dfe72d7f_1836x1116.png)](https://substackcdn.com/image/fetch/$s_!VJyp!,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2F7dfb70d9-5eb6-44df-a880-3a37dfe72d7f_1836x1116.png)\n\nFigure 8: One attention head is already a complete mechanism. One set of learned projections produces one attention matrix and one context-aware output stream (Original source *[Understanding and Coding Self-Attention](https://magazine.sebastianraschka.com/p/understanding-and-coding-self-attention)*).\n\nOne set of `Wq/Wk/Wv` matrices gives us one attention head, which means one attention matrix and one output matrix `Z`. (This concept was illustrated in the previous section.)\n\nMulti-head attention simply runs several of these heads in parallel with different learned projection matrices.\n\nThis is useful because different heads can specialize in different token relationships. One head might focus on short local dependencies, another on broader semantic links, and another on positional or syntactic structure.\n\n[![](https://substackcdn.com/image/fetch/$s_!MSOX!,w_1456,c_limit,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2F5f47ffd2-bb3a-4936-9720-a88b8d867337_1766x1154.png)](https://substackcdn.com/image/fetch/$s_!MSOX!,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2F5f47ffd2-bb3a-4936-9720-a88b8d867337_1766x1154.png)\n\nFigure 9: Multi-head attention keeps the same basic attention recipe, but repeats it across several heads in parallel so the model can learn several token-to-token patterns at once (Original source *[Understanding and Coding Self-Attention](https://magazine.sebastianraschka.com/p/understanding-and-coding-self-attention)*).\n\nGrouped-query attention is an attention variant derived from standard MHA. It was introduced in the 2023 paper *[GQA: Training Generalized Multi-Query Transformer Models from Multi-Head Checkpoints](https://arxiv.org/abs/2305.13245)* by Joshua Ainslie and colleagues.\n\nInstead of giving every query head its own keys and values, it lets several query heads share the same key-value projections, which makes [KV caching](https://magazine.sebastianraschka.com/p/coding-the-kv-cache-in-llms?utm_source=publication-search) much cheaper (primarily as a memory reduction) without changing the overall decoder recipe very much.\n\n[![](https://substackcdn.com/image/fetch/$s_!h6wM!,w_1456,c_limit,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2F6f39923c-8357-487d-9e69-40ee18a902e8_2523x1248.png)](https://substackcdn.com/image/fetch/$s_!h6wM!,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2F6f39923c-8357-487d-9e69-40ee18a902e8_2523x1248.png)\n\nFigure 10: GQA keeps the same overall attention pattern as MHA, but collapses the number of key-value heads by sharing them across multiple query heads (Original source: *[The Big LLM Architecture Comparison](https://magazine.sebastianraschka.com/p/the-big-llm-architecture-comparison)*).\n\n**EXAMPLE ARCHITECTURES**\n\nDense: [Llama 3 8B](https://sebastianraschka.com/llm-architecture-gallery/#card-llama-3-8b), [Qwen3 4B](https://sebastianraschka.com/llm-architecture-gallery/#card-qwen3-4b), [Gemma 3 27B](https://sebastianraschka.com/llm-architecture-gallery/#card-gemma-3-27b), [Mistral Small 3.1 24B](https://sebastianraschka.com/llm-architecture-gallery/#card-mistral-small-3-1-24b), [SmolLM3 3B](https://sebastianraschka.com/llm-architecture-gallery/#card-smollm3-3b), and [Tiny Aya 3.35B](https://sebastianraschka.com/llm-architecture-gallery/#card-tiny-aya-3-35b).\\\nSparse (Mixture-of-Experts): [Llama 4 Maverick](https://sebastianraschka.com/llm-architecture-gallery/#card-llama-4-maverick), [Qwen3 235B-A22B](https://sebastianraschka.com/llm-architecture-gallery/#card-qwen3-235b-a22b), [Step 3.5 Flash 196B](https://sebastianraschka.com/llm-architecture-gallery/#card-step-3-5-flash-196b), and [Sarvam 30B](https://sebastianraschka.com/llm-architecture-gallery/#card-sarvam-30b).\n\nIn my [architecture comparison article](https://magazine.sebastianraschka.com/p/the-big-llm-architecture-comparison), I framed GQA as the new standard replacement for classic multi-head attention (MHA). The reason is that standard MHA gives every head its own keys and values, which is more optimal from a modeling perspective but expensive once we have to keep all of that state in the [KV cache](https://magazine.sebastianraschka.com/p/coding-the-kv-cache-in-llms?utm_source=publication-search) during inference.\n\nIn GQA, we keep a larger set of query heads, but we reduce the number of key-value heads and let multiple queries share them. That lowers both parameter count and [KV-cache](https://magazine.sebastianraschka.com/p/coding-the-kv-cache-in-llms?utm_source=publication-search) traffic without making drastic implementation changes like multi-head latent attention (MLA), which will be discussed later.\n\nIn practice, that made and keeps it a very popular choice for labs that wanted something cheaper than MHA but simpler to implement than newer compression-heavy alternatives like MLA.\n\nGQA results in big savings in KV storage, since the fewer key-value heads we keep per layer, the less cached state we need per token. That is why GQA becomes more useful as sequence length grows.\n\nGQA is also a spectrum. If we reduce all the way down to one shared K/V group, we are effectively in multi-query attention territory, which is even cheaper but can hurt modeling quality more noticeably. The sweet spot is usually somewhere in between multi-query attention (1 shared group) and MHA (where K/V groups are equal to the number of queries), where the cache savings are large but the modeling degradation relative to MHA stays modest.\n\nMore advanced variants such as MLA are becoming popular because they can offer better modeling performance at the same KV efficiency levels (e.g., as discussed in the ablation studies of the [DeepSeek-V2 paper](https://arxiv.org/abs/2405.04434)), but they also involve a more complicated implementation and a more complicated attention stack.\n\nGQA remains appealing because it is robust, easier to implement, and also easier to train (since there are fewer hyperparameter tunings necessary, based on my experience).\n\nThat is why some of the newer releases still stay deliberately classic here. E.g., in my [Spring Architectures](https://magazine.sebastianraschka.com/p/a-dream-of-spring-for-open-weight) article, I mentioned that MiniMax M2.5 and Nanbeige 4.1 as models that remained very classic, using only grouped-query attention without piling on other efficiency tricks. Sarvam is a particularly useful comparison point as well: the 30B model keeps classic GQA, while the 105B version switches to MLA.\n\n[![](https://substackcdn.com/image/fetch/$s_!BMEL!,w_1456,c_limit,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2F2d04f89a-aad5-4af7-8b46-4623d1d53ae9_5860x5682.webp)](https://substackcdn.com/image/fetch/$s_!BMEL!,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2F2d04f89a-aad5-4af7-8b46-4623d1d53ae9_5860x5682.webp)\n\nFigure 12: Total KV cache sizes for 105B Sarvam (using MLA) versus 30B Sarvam (using GQA), versus using plain MHA.\n\nThe motivation behind Multi-head Latent Attention (MLA) is similar to Grouped-Query Attention (GQA). Both are solutions for reducing [KV-cache](https://magazine.sebastianraschka.com/p/coding-the-kv-cache-in-llms?utm_source=publication-search) memory requirements. The difference between GQA and MLA is that MLA shrinks the cache by compressing what gets stored rather than by reducing how many K/Vs are stored by sharing heads.\n\n[![](https://substackcdn.com/image/fetch/$s_!FcJB!,w_1456,c_limit,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2Fe29cb535-8854-4412-af8d-9bca8d8d05f2_1550x858.webp)](https://substackcdn.com/image/fetch/$s_!FcJB!,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2Fe29cb535-8854-4412-af8d-9bca8d8d05f2_1550x858.webp)\n\nFigure 13: Unlike GQA, MLA does not reduce KV cost by grouping heads. It reduces it by caching a compressed latent representation. Note that it is also applied to the query, which is not shown for simplicity (Original source:*[The Big LLM Architecture Comparison](https://magazine.sebastianraschka.com/p/the-big-llm-architecture-comparison)*).\n\nMLA, originally proposed in the [DeepSeek-V2](https://arxiv.org/abs/2405.04434) paper, became such a defining DeepSeek-era idea (especially after DeepSeek-V3 and R1). It is more complicated to implement than GQA, more complicated to serve, but nowadays also often more compelling once model size and context length get large enough that cache traffic starts to dominate, because at the same rate of memory reduction, it could maintain better modeling performance (more on that later).\n\n**EXAMPLE ARCHITECTURES**\n\n[DeepSeek V3](https://sebastianraschka.com/llm-architecture-gallery/#card-deepseek-v3), [Kimi K2](https://sebastianraschka.com/llm-architecture-gallery/#card-kimi-k2), [GLM-5](https://sebastianraschka.com/llm-architecture-gallery/#card-glm-5-744b), [Ling 2.5](https://sebastianraschka.com/llm-architecture-gallery/#card-ling-2-5-1t), [Mistral Large 3](https://sebastianraschka.com/llm-architecture-gallery/#card-mistral-large-3), and [Sarvam 105B](https://sebastianraschka.com/llm-architecture-gallery/#card-sarvam-105b)\n\nInstead of caching full-resolution key and value tensors as in MHA and GQA, MLA stores a latent representation and reconstructs the usable state when needed. Essentially, it is a cache compression strategy embedded inside attention, as illustrated in the previous figure.\n\nThe figure below shows the savings compared to regular MHA.\n\n[![](https://substackcdn.com/image/fetch/$s_!56rA!,w_1456,c_limit,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2F186dfe98-db29-4b12-97ab-39d5b21ab460_1920x1440.png)](https://substackcdn.com/image/fetch/$s_!56rA!,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2F186dfe98-db29-4b12-97ab-39d5b21ab460_1920x1440.png)\n\nFigure 14: Once context length grows, the savings from caching a latent representation instead of full K/V tensors become very visible (Original source: *[LLMs-from-scratch](https://github.com/rasbt/LLMs-from-scratch/tree/main/ch04/05_mla)*[MLA](https://github.com/rasbt/LLMs-from-scratch/tree/main/ch04/05_mla) section).\n\nThe DeepSeek-V2 paper provided some ablations where GQA looked worse than MHA in terms of modeling performance, while MLA held up much better and could even outperform MHA when tuned carefully. That is a much stronger justification than “it (also) saves memory.”\n\nIn other words, MLA is a preferable attention mechanism for DeepSeek not just because it was efficient, but because it looked like a quality-preserving efficiency move at large scale. (But colleagues also told me that MLA only works well at a certain size. For smaller models, let’s say <100B, GQA seems to work better, or, is at least easier to tune and get right.)\n\n[![](https://substackcdn.com/image/fetch/$s_!1yW7!,w_1456,c_limit,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2Ff564ec9f-5fcb-49c3-b728-b4c8a769bb6c_952x902.png)](https://substackcdn.com/image/fetch/$s_!1yW7!,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2Ff564ec9f-5fcb-49c3-b728-b4c8a769bb6c_952x902.png)\n\nFigure 15: GQA drops below MHA here, while MLA remains competitive and can even slightly outperform it. Underlying paper: [DeepSeek-V2](https://arxiv.org/abs/2405.04434).\n\nBelow is again the comparison between GQA in 30B Sarvam versus MLA in 105B Sarvam.\n\n[![](https://substackcdn.com/image/fetch/$s_!cbqs!,w_1456,c_limit,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2Fa425874e-baae-45bb-a199-46648c5db725_5860x5682.webp)](https://substackcdn.com/image/fetch/$s_!cbqs!,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2Fa425874e-baae-45bb-a199-46648c5db725_5860x5682.webp)\n\nFigure 16: GQA and MLA are solving the same bottleneck from different directions. The tradeoff is simplicity versus better modeling performance for larger models.\n\nOnce DeepSeek V3/R1, V3.1 etc. normalized the design after its introduction in V2, it started showing up in a second wave of architectures. Kimi K2 kept the DeepSeek recipe and scaled it up. GLM-5 adopted MLA together with DeepSeek Sparse Attention (from DeepSeek V3.2). Ling 2.5 paired MLA with a linear-attention hybrid. Sarvam released two models where the 30B model stayed with classic GQA and the 105B model switched to MLA.\n\nThat last pair is particularly useful as it puts the technical-complexity discussion aside. I.e., the Sarvam team implemented both variants and deliberately chose to then use GQA for one variant and MLA for the other. So, in a sense, that makes MLA feel less like a theoretical alternative and more like a concrete architectural upgrade path once a family scales up.\n\nSliding window attention reduces the memory and compute cost of long-context inference by limiting how many previous tokens each position can attend to. Instead of attending to the entire prefix, each token only attends to a fixed window of recent tokens around its position. Because attention is restricted to a local token neighborhood, this mechanism is often referred to as local attention.\n\nSome architectures combine these local layers with occasional global attention layers so that information can still propagate across the entire sequence.\n\n[![](https://substackcdn.com/image/fetch/$s_!edFZ!,w_1456,c_limit,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2F48a9cd31-24a5-47d9-ae37-506763ebc67d_1292x704.png)](https://substackcdn.com/image/fetch/$s_!edFZ!,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2F48a9cd31-24a5-47d9-ae37-506763ebc67d_1292x704.png)\n\nFigure 17: The conceptual shift is simple. Regular attention is global attention, while sliding-window attention is local attention. Global attention lets every token see the full prefix; SWA turns many of those layers into local attention layers (Original source: *[The Big LLM Architecture Comparison](https://magazine.sebastianraschka.com/p/the-big-llm-architecture-comparison)*).\n\n**EXAMPLE ARCHITECTURES**\n\n[Gemma 3 27B](https://sebastianraschka.com/llm-architecture-gallery/#card-gemma-3-27b), [OLMo 3 32B](https://sebastianraschka.com/llm-architecture-gallery/#card-olmo-3-32b), [Xiaomi MiMo-V2-Flash](https://sebastianraschka.com/llm-architecture-gallery/#card-xiaomi-mimo-v2-flash-309b), [Arcee Trinity](https://sebastianraschka.com/llm-architecture-gallery/#card-arcee-ai-trinity-large-400b), [Step 3.5 Flash](https://sebastianraschka.com/llm-architecture-gallery/#card-step-3-5-flash-196b), and [Tiny Aya](https://sebastianraschka.com/llm-architecture-gallery/#card-tiny-aya-3-35b)\n\nGemma 3 is still one of the clearest recent SWA examples because it is easy to compare against Gemma 2. Gemma 2 already used a hybrid attention setup with a 1:1 ratio between local and global layers and a 4096-token window. Gemma 3 pushed this further to a 5:1 ratio and reduced the window size to 1024.\n\nThe key finding was not that local attention is cheaper, because that was already known. Here, the more interesting takeaway from the Gemma 3 ablation study was that using this more aggressively seemed to hurt modeling performance only slightly.\n\nIn practice, saying that a model “uses SWA” does not mean it relies on SWA alone. What usually matters are the local-to-global layer pattern and the attention window size. For example:\n\n- Gemma 3 and Xiaomi use a 5:1 local-to-global pattern.\n\n- OLMo 3 and Arcee Trinity use a 3:1 pattern.\n\n- Xiaomi also uses a window size of 128, which is much smaller, and therefore more aggressive, than Gemma’s 1024.\n\nSWA is essentially a knob that can be tuned more or less aggressively.\n\n[![](https://substackcdn.com/image/fetch/$s_!3FBb!,w_1456,c_limit,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2F38e10000-db6c-43fa-844b-ed7d4dfe644c_3299x3302.webp)](https://substackcdn.com/image/fetch/$s_!3FBb!,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2F38e10000-db6c-43fa-844b-ed7d4dfe644c_3299x3302.webp)\n\nFigure 18: The long-context savings come from turning many full-attention layers into local ones, which reduces how much cached context those layers need to consider (Original source: *[LLMs-from-scratch](https://github.com/rasbt/LLMs-from-scratch/tree/main/ch04/06_swa)*[SWA materials](https://github.com/rasbt/LLMs-from-scratch/tree/main/ch04/06_swa)).\n\nSWA often appears together with [GQA](http://127.0.0.1:4000/llm-architecture-gallery/gqa/) because the two ideas address different parts of the same inference problem. SWA reduces how much context a local layer has to consider. GQA reduces how much key-value state each token contributes to the cache.\n\nThat is why many recent dense models use both rather than treating them as alternatives. Gemma 3 is again a good reference point here, since it combines sliding window attention with grouped-query attention in the same architecture.\n\nDeepSeek Sparse Attention is one of the architectural changes that appeared in the [DeepSeek V3.2](https://arxiv.org/abs/2512.02556) line and later showed up again in GLM-5.\n\nSpecifically, DeepSeek V3.2 combines it with [Multi-head Latent Attention (MLA)](https://sebastianraschka.com/llm-architecture-gallery/mla/), and GLM-5 adopts the same pair for the same general reason, namely, reducing inference cost when context lengths get large.\n\n**EXAMPLE ARCHITECTURES**\n\n[DeepSeek V3.2](https://sebastianraschka.com/llm-architecture-gallery/#card-deepseek-v3-2) and [GLM-5](https://sebastianraschka.com/llm-architecture-gallery/#card-glm-5-744b)\n\nIn sliding-window attention, the current token does not attend to the full prefix but only to a fixed local window. This is the same broad idea behind DeepSeek Sparse Attention, where each token also only attends to a subset of previous tokens.\n\nHowever, the selected tokens are not determined by a fixed-width local window. Instead, DeepSeek Sparse Attention uses a learned sparse pattern. In short, it uses an indexer-plus-selector setup, where a lightning indexer computes relevance scores, and a token selector keeps only a smaller set of high-scoring past positions.\n\nThe way the subset of tokens is selected is the main difference from sliding-window attention. Sliding-window attention hard-codes locality. DeepSeek Sparse Attention still limits attention to a subset, but it lets the model decide which prior tokens are worth revisiting.\n\nDeepSeek V3.2 uses both Multi-head Latent Attention (MLA) and DeepSeek Sparse Attention. MLA reduces [KV-cache](https://magazine.sebastianraschka.com/p/coding-the-kv-cache-in-llms?utm_source=publication-search) cost by compressing what gets stored. DeepSeek Sparse Attention reduces how much of the prior context the model has to revisit. Put differently, one optimizes the cache representation, the other optimizes the attention pattern on top of it.\n\n[![](https://substackcdn.com/image/fetch/$s_!B4GF!,w_1456,c_limit,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2Fad5026e1-1dbd-4004-814f-6cd6d735e572_2787x2731.webp)](https://substackcdn.com/image/fetch/$s_!B4GF!,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2Fad5026e1-1dbd-4004-814f-6cd6d735e572_2787x2731.webp)\n\nFigure 20: DeepSeek V3.2 is the obvious reference point, because this is the model family most closely associated with the sparse-attention idea.\n\nThe sparse pattern is not random. The first stage is a lightning indexer that scores previous tokens for each new query token. It uses MLA’s compressed token representations and computes a learned similarity score over the prior context, so the model can rank which earlier positions are worth revisiting.\n\nThe second stage is a token selector. It keeps only a smaller high-scoring subset, for example, a top-`k`set of past positions, and turns that subset into the sparse attention mask. So the main point is that DeepSeek Sparse Attention does not hard-code the sparsity pattern. It learns which past tokens to keep.\n\nDeepSeek Sparse Attention is relatively new and relatively complicated to implement, which is why it has not been so widely adopted as Grouped-Query Attention (GQA) yet.\n\nGated attention is best understood as a modified full-attention block rather than as a separate attention family.\n\nIt usually appears inside hybrid stacks that still keep an occasional full-attention layer for exact content retrieval, but add a few stability-oriented changes on top of an otherwise familiar scaled dot-product attention block.\n\n[![](https://substackcdn.com/image/fetch/$s_!syqZ!,w_1456,c_limit,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2F2d109b38-96a1-4830-b1f0-7274e405317a_3973x5350.webp)](https://substackcdn.com/image/fetch/$s_!syqZ!,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2F2d109b38-96a1-4830-b1f0-7274e405317a_3973x5350.webp)\n\nFigure 22: Trinity Large is a useful comparison because gated attention is not only a Qwen idea (more on that later). Here the gate appears after the scaled dot-product attention output and before the output projection in a different long-context architecture (Original source: *[A Dream of Spring for Open-Weight LLMs](https://magazine.sebastianraschka.com/p/a-dream-of-spring-for-open-weight)*).\n\nThe Qwen3-Next and Qwen3.5 architectures show that recent hybrids (covered in the next section) do not replace attention everywhere. Instead, they replace most attention layers with a cheaper alternative and keep a smaller number of full-attention layers in the stack.\n\nThose remaining full-attention layers are where gated attention typically appears. Qwen3-Next and Qwen3.5 use it together with Gated DeltaNet in a 3:1 pattern.\n\nBut hybrid architectures aside, Trinity uses a related gating idea in a more conventional attention stack, as shown in the previous figure above.\n\nThe gated attention block in Qwen-style hybrids or Trinity (not a hybrid) is essentially standard scaled-dot-product attention with a few changes on top. In the original [Gated Attention paper](https://arxiv.org/abs/2505.06708), those changes are presented as a way to make the retained full-attention layers behave more predictably inside a hybrid stack.\n\nThe block still looks like standard (full) attention, but it adds:\n\n1. an output gate that scales the attention result before it is added back to the residual,\n\n2. a zero-centered QK-Norm variant instead of standard RMSNorm for q and k,\n\n3. partial RoPE.\n\nThese are not changes on the scale of MLA or linear attention but merely stability and control changes applied to an otherwise familiar attention block.\n\n[![](https://substackcdn.com/image/fetch/$s_!VVeK!,w_1456,c_limit,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2Fafe94d77-ab5f-4420-88e4-8ba1f91992e0_2484x3278.webp)](https://substackcdn.com/image/fetch/$s_!VVeK!,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2Fafe94d77-ab5f-4420-88e4-8ba1f91992e0_2484x3278.webp)\n\nFigure 23: In Qwen3-Next and Qwen3.5, gated attention appears as the full-attention layer that periodically breaks up runs of Gated DeltaNet blocks.\n\nNote that the figure above also includes Gated DeltaNet, which we will cover in the next section below.\n\nHybrid attention is a broader design pattern rather than a specific, single mechanism. The overall idea is to keep a transformer-like stack, but replace most of the expensive full-attention layers with cheaper linear or state-space sequence modules.\n\nThe motivation is long-context efficiency. Full attention grows quadratically with sequence length, so once models move to contexts like 128k, 256k, or 1M tokens, attention memory and compute become expensive enough that using cheaper sequence modules in most layers while keeping only a smaller number of heavier retrieval layers starts making more sense. (Note that this comes with a bit of a modeling performance trade-off, though.)\n\nIn Qwen3-Next, this pattern appears as a 3:1 mix of Gated DeltaNet and Gated Attention blocks. Gated DeltaNet is also closely related to Mamba-2 (see the *[Gated Delta Networks: Improving Mamba2 with Delta Rule](https://arxiv.org/abs/2412.06464)* paper, for instance), and the mechanism can be read as a DeltaNet-style fast-weight update combined with Mamba-style gating. Later architectures keep the same overall idea but swap in other lightweight sequence mixers, such as Kimi Delta Attention, Lightning Attention, or standard Mamba-2.\n\n[![](https://substackcdn.com/image/fetch/$s_!XRZY!,w_1456,c_limit,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2F876009cb-5479-4e95-9b7d-faebe1f87e89_3252x2158.webp)](https://substackcdn.com/image/fetch/$s_!XRZY!,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2F876009cb-5479-4e95-9b7d-faebe1f87e89_3252x2158.webp)\n\nFigure 24: The basic hybrid pattern, where most blocks are cheaper sequence mixers and every fourth block restores a heavier attention layer (Original source *[The Big LLM Architecture Comparison](https://magazine.sebastianraschka.com/p/the-big-llm-architecture-comparison)*).\n\nTo my knowledge, the first prominent example of a close-to-flagship LLM with hybrid attention was Qwen3-Next in 2025, which does not remove attention completely but mixes three Gated DeltaNet blocks with one Gated Attention block.\n\nHere, lightweight Gated DeltaNet blocks do most of the long-context work and keep memory growth much flatter than full attention. The heavier gated-attention layer remains because DeltaNet is less exact at content-based retrieval.\n\nInside a Gated DeltaNet block, the model computes query, key, and value vectors together with two learned gates (α, β). Rather than forming the usual token-to-token attention matrix, it writes to a small fast-weight memory using a delta-rule update. In rough terms, the memory stores a compressed running summary of past information, while the gates control how much new information is added and how much previous state is retained.\n\nThat makes Gated DeltaNet a linear-attention or recurrent-style mechanism rather than just another tweak to MHA. Relative to Mamba-2, the close connection is that both belong to the linear-time gated sequence-model family, but Gated DeltaNet uses a DeltaNet-style fast-weight memory update instead of the Mamba state-space update.\n\n[![](https://substackcdn.com/image/fetch/$s_!hK9M!,w_1456,c_limit,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2Fb82c3202-6c49-4cd7-a4eb-ab18edcd908e_2100x1350.png)](https://substackcdn.com/image/fetch/$s_!hK9M!,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2Fb82c3202-6c49-4cd7-a4eb-ab18edcd908e_2100x1350.png)\n\nFigure 25: The practical motivation behind the hybrids is shown here in the memory curve. Hybrid stacks with Gated DeltaNet grow much more slowly with context length than ordinary full attention (Original source *[LLMs-from-scratch](https://github.com/rasbt/LLMs-from-scratch/tree/main/ch04/08_deltanet)*[DeltaNet materials](https://github.com/rasbt/LLMs-from-scratch/tree/main/ch04/08_deltanet)).\n\nQwen3.5 moves the former Qwen3-Next hybrid into Qwen’s main flagship series, which is an interesting move. This basically signals that the hybrid strategy is a success and that we may see more models with this architecture in the future.\n\n[![](https://substackcdn.com/image/fetch/$s_!L9cU!,w_1456,c_limit,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2F11deeb70-5766-41eb-bc93-b7c8f81afcb7_2048x1281.png)](https://substackcdn.com/image/fetch/$s_!L9cU!,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2F11deeb70-5766-41eb-bc93-b7c8f81afcb7_2048x1281.png)\n\nFigure 26: Qwen3.5 shows the Qwen team promoting the former Qwen3-Next side-branch into the main model line rather than leaving it as a one-off efficiency variant (Original source *[A Dream of Spring for Open-Weight LLMs](https://magazine.sebastianraschka.com/p/a-dream-of-spring-for-open-weight)*).\n\nKimi Linear keeps the same broad transformer skeleton and the same 3:1 pattern, but it changes both halves of the recipe.\n\nOn the lightweight side, Kimi Delta Attention is a refinement of Gated DeltaNet. Where Qwen3-Next uses a scalar gate per head to control memory decay, Kimi uses channel-wise gating, which gives finer control over the memory update. On the heavier side, Kimi replaces Qwen3-Next’s gated-attention layers with gated MLA layers.\n\nSo, it’s still the same broader pattern as in Qwen3-Next and Qwen3.5, but both ingredients (slightly) change. I.e., most layers are still handled by a cheaper linear-style mechanism, and periodic heavier layers still remain for stronger retrieval.\n\n[![](https://substackcdn.com/image/fetch/$s_!Q1wq!,w_1456,c_limit,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2F38f5b449-f122-4520-b6ea-a2437fd9508e_2376x1572.webp)](https://substackcdn.com/image/fetch/$s_!Q1wq!,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2F38f5b449-f122-4520-b6ea-a2437fd9508e_2376x1572.webp)\n\nFigure 27: Kimi Linear keeps the same overall hybrid pattern while changing both the lightweight side and the heavier attention side of the stack (Original source *[The Big LLM Architecture Comparison](https://magazine.sebastianraschka.com/p/the-big-llm-architecture-comparison)*).\n\nLing 2.5 shows another swap on the lightweight side. Instead of Gated DeltaNet, Ling uses a slightly simpler recurrent linear attention variant called Lightning Attention. On the heavier side, it keeps MLA from DeepSeek.\n\nMost sequence mixing happens in the cheaper linear-attention blocks, while a smaller number of heavier layers remain to preserve stronger retrieval. The difference is that the specific lightweight mechanism is now Lightning Attention rather than DeltaNet or Kimi Delta Attention.\n\n[![](https://substackcdn.com/image/fetch/$s_!xCw3!,w_1456,c_limit,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2F8ee9eb2d-c95a-4471-b9b3-72e53f78d722_2048x1028.png)](https://substackcdn.com/image/fetch/$s_!xCw3!,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2F8ee9eb2d-c95a-4471-b9b3-72e53f78d722_2048x1028.png)\n\nFigure 28: Ling 2.5 and Qwen3.5 are both linear-attention hybrids, even though Ling swaps in Lightning Attention and MLA instead of the Qwen recipe (Original source *[A Dream of Spring for Open-Weight LLMs](https://magazine.sebastianraschka.com/p/a-dream-of-spring-for-open-weight)*).\n\nLing 2.5 is aimed more at long-context efficiency than at absolute benchmark leadership. According to the Ling team, it was reported as substantially faster than Kimi K2 at 32k tokens, which is the practical payoff these hybrids are aiming for.\n\n[![](https://substackcdn.com/image/fetch/$s_!cinD!,w_1456,c_limit,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2Fb7d49b8b-9ebb-460e-9a51-20bc4126bda1_2048x1012.png)](https://substackcdn.com/image/fetch/$s_!cinD!,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2Fb7d49b8b-9ebb-460e-9a51-20bc4126bda1_2048x1012.png)\n\nFigure 29: Ling 2.5 was presented as a strong efficiency upgrade, with much higher 32k-token throughput than Kimi K2 at the same 1-trillion-parameter scale (Original source *[Ling 2.5 model hub page](https://huggingface.co/inclusionAI/Ling-2.5-1T)*).\n\nNemotron pushes the pattern further away from the transformer baseline. Nemotron 3 Nano is a Mamba-Transformer hybrid that interleaves Mamba-2 sequence-modeling blocks with sparse MoE layers and uses self-attention only in a small subset of layers.\n\nThis is a more extreme version of the same basic tradeoff discussed above. Here, the lightweight sequence module is a Mamba-2 state-space block rather than a DeltaNet-style fast-weight update, but the basic tradeoff is similar.\n\n[![](https://substackcdn.com/image/fetch/$s_!QcU9!,w_1456,c_limit,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2F65b809c5-83be-4cf7-b4a6-e45d16ef86d3_1596x1562.webp)](https://substackcdn.com/image/fetch/$s_!QcU9!,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2F65b809c5-83be-4cf7-b4a6-e45d16ef86d3_1596x1562.webp)\n\nFigure 30: Nemotron 3 Nano uses Mamba-2 for most of the sequence modeling work, with self-attention only appearing in a small subset of layers (Original source *[The Big LLM Architecture Comparison](https://magazine.sebastianraschka.com/p/the-big-llm-architecture-comparison)*).\n\nThe larger Nemotron 3 Super keeps the Mamba-2 hybrid attention approach and adds other efficiency-oriented changes such as latent MoE and shared-weight multi-token prediction (MTP) for speculative decoding.\n\n[![](https://substackcdn.com/image/fetch/$s_!KvOc!,w_1456,c_limit,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2F75c26a29-a18e-4e14-8989-846b0171b9fa_1862x1656.png)](https://substackcdn.com/image/fetch/$s_!KvOc!,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2F75c26a29-a18e-4e14-8989-846b0171b9fa_1862x1656.png)\n\nFigure 31: Nemotron 3 Super keeps the Mamba-2 hybrid attention pattern while adding latent MoE and shared-weight MTP on top (Original source *[The Big LLM Architecture Comparison](https://magazine.sebastianraschka.com/p/the-big-llm-architecture-comparison)*).\n\nOf course, there are many more (mostly niche) attention variants throughout the literature that I haven’t covered here. The focus of this article was on those that are currently used in state-of-the-art (open-weight) models.\n\nIn particular, I am looking forward to (1) seeing the brand new [Mamba-3](https://arxiv.org/abs/2603.15569) layers getting integrated into the aforementioned hybrid architectures (replacing Gated DeltaNet) and (2) [attention residuals](https://arxiv.org/abs/2603.15031) being used in general.\n\nIn practice, you may also wonder what the “best” architecture is at the moment. This is hard to answer, as there are no public experiments that train different architectures on the same training data etc.\n\nHence, we can currently only answer what the best (trained) model choice is for a given problem. In my opinion, hybrid architectures are still a novelty, and the main selling point is mainly (long-context) efficiency versus just modeling performance. Hence, I think they are a great candidate for agent contexts (like OpenClaw).\n\nPersonally, I think the problem with hybrid architectures is also that the inference stacks are not quite as optimized, yet, and I find that I get better tok/sec throughput when running LLMs locally using more classic setups like GPT-OSS with grouped-query attention.\n\nAnyways, I am curious to see what DeepSeek V4 has in store, since DeepSeek has been quite the reliable trend-setter in the recent 2 years.\n\nNo posts\n",
  "authors": [
    "Sebastian Raschka, PhD"
  ],
  "captured_at": "2026-09-27T19:29:15.293681927+00:00",
  "category": "programming",
  "content_html": "<p>I had originally planned to write about DeepSeek V4. Since it still hasn’t been released, I used the time to work on something that had been on my list for a while, namely, collecting, organizing, and refining the different LLM architectures I have covered over the past few years.</p>\n<p>So, over the last two weeks, I turned that effort into an LLM architecture gallery (with 45 entries at the time of this writing), which combines material from earlier articles with several important architectures I had not documented yet. Each entry comes with a visual model card, and I plan to keep the gallery updated regularly.</p>\n<p>You can find the gallery here: <a target=\"_blank\" rel=\"noopener noreferrer\" href=\"https://sebastianraschka.com/llm-architecture-gallery/\">https://sebastianraschka.com/llm-architecture-gallery/</a></p>\n<p>After I shared the initial version, a few readers also asked whether there would be a poster version. So, there is now a <a target=\"_blank\" rel=\"noopener noreferrer\" href=\"https://www.redbubble.com/i/poster/LLM-Architecture-Gallery-by-Ahead-of-AI/179274487/flk2\">poster version via Redbubble</a>. I ordered the Medium size (26.9 x 23.4 in) to check how it looks in print, and the result is sharp and clear. That said, some of the smallest text elements are already quite small at that size, so I would not recommend the smaller versions if you intend to have everything readable.</p>\n<p><a target=\"_blank\" rel=\"noopener noreferrer\" href=\"https://substackcdn.com/image/fetch/$s_!ceew!,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2F03198b65-472c-495e-92c0-62b6af66d720_1999x1313.jpeg\"><picture class=\"article-picture article-picture-fallback\" style=\"--image-ratio:16 / 9\"><img src=\"https://substackcdn.com/image/fetch/$s_!ceew!,w_1456,c_limit,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2F03198b65-472c-495e-92c0-62b6af66d720_1999x1313.jpeg\" alt=\"\" loading=\"eager\" decoding=\"async\" fetchpriority=\"high\" referrerpolicy=\"no-referrer\" class=\"progressive-image\"></picture></a></p>\n<p><em>Figure 2: <a target=\"_blank\" rel=\"noopener noreferrer\" href=\"https://www.redbubble.com/i/poster/LLM-Architecture-Gallery-by-Ahead-of-AI/179274487/flk2\">Poster version</a> of the architecture gallery with some random objects for scale.</em></p>\n<p>Alongside the gallery, I was/am also working on short explainers for a few core LLM concepts.</p>\n<p>So, in this article, I thought it would be interesting to recap all the recent attention variants that have been developed and used in prominent open-weight architectures in recent years.</p>\n<p>My goal is to make the collection useful both as a reference and as a lightweight learning resource. I hope you find it useful and educational!</p>\n<p>Self-attention lets each token look at the other visible tokens in the sequence, assign them weights, and use those weights to build a new context-aware representation of the input.</p>\n<p>Multi-head attention (MHA) is the standard transformer version of that idea. It runs several self-attention heads in parallel with different learned projections, then combines their outputs into one richer representation.</p>\n<p><a target=\"_blank\" rel=\"noopener noreferrer\" href=\"https://substackcdn.com/image/fetch/$s_!GrJT!,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2Fa3ed41e9-86ee-4c1c-80a5-c9c2ed59dd9c_1366x1410.png\"><picture class=\"article-picture article-picture-fallback\" style=\"--image-ratio:16 / 9\"><img src=\"https://substackcdn.com/image/fetch/$s_!GrJT!,w_1456,c_limit,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2Fa3ed41e9-86ee-4c1c-80a5-c9c2ed59dd9c_1366x1410.png\" alt=\"\" loading=\"lazy\" decoding=\"async\" fetchpriority=\"low\" referrerpolicy=\"no-referrer\" class=\"progressive-image\"></picture></a></p>\n<p>Figure 3: Olmo 2 as an example architecture using MHA.</p>\n<p>The sections below start with a whirlwind tour of explaining self-attention to explain MHA. It’s more meant as a quick overview to set the stage for related attention concepts like grouped-query attention, sliding window attention, and so on. If you are interested in a longer, more detailed self-attention coverage, you might like my longer <a target=\"_blank\" rel=\"noopener noreferrer\" href=\"https://magazine.sebastianraschka.com/p/understanding-and-coding-self-attention\">Understanding and Coding Self-Attention, Multi-Head Attention, Causal-Attention, and Cross-Attention in LLMs</a> article.</p>\n<p><strong>EXAMPLE ARCHITECTURES</strong></p>\n<p><a target=\"_blank\" rel=\"noopener noreferrer\" href=\"https://sebastianraschka.com/llm-architecture-gallery/#card-gpt-2-xl-1-5b\">GPT-2</a>, <a target=\"_blank\" rel=\"noopener noreferrer\" href=\"https://sebastianraschka.com/llm-architecture-gallery/#card-olmo-2-7b\">OLMo 2 7B</a>, and <a target=\"_blank\" rel=\"noopener noreferrer\" href=\"https://sebastianraschka.com/llm-architecture-gallery/#card-olmo-3-7b\">OLMo 3 7B</a></p>\n<p>Attention predates transformers and MHA. Its immediate background is encoder-decoder RNNs for translation.</p>\n<p>In those older systems, an encoder RNN would read the source sentence token by token and compress it into a sequence of hidden states, or in the simplest version into one final state. Then the decoder RNN had to generate the target sentence from that limited summary. This worked for short and simple cases, but it created an obvious bottleneck once the relevant information for the next output word lived somewhere else in the input sentence.</p>\n<p>In short, the limitation is that the hidden state can’t store infinitely much information or context, and sometimes it would be useful to just refer back to the full input sequence.</p>\n<p>The translation example below shows one of the limitations of this idea. For instance, a sentence can preserve many locally reasonable word choices and still fail as a translation when the model treats the problem too much like a word-by-word mapping. (The top panel shows an exaggerated example where we translate the sentence word by word; obviously, the grammar in the resulting sentence is wrong.) In reality, the correct next word depends on sentence-level structure and on which earlier source words matter at that step. Of course, this could still be translated fine with an RNN, but it would struggle with longer sequences or knowledge retrieval tasks because the hidden state can only store so much information as mentioned earlier.</p>\n<p><a target=\"_blank\" rel=\"noopener noreferrer\" href=\"https://substackcdn.com/image/fetch/$s_!jdH6!,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2F95e6491c-6457-4af0-83f3-b73310bad668_3566x2495.webp\"><picture class=\"article-picture article-picture-fallback\" style=\"--image-ratio:16 / 9\"><img src=\"https://substackcdn.com/image/fetch/$s_!jdH6!,w_1456,c_limit,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2F95e6491c-6457-4af0-83f3-b73310bad668_3566x2495.webp\" alt=\"\" loading=\"lazy\" decoding=\"async\" fetchpriority=\"low\" referrerpolicy=\"no-referrer\" class=\"progressive-image\"></picture></a></p>\n<p>Figure 4: Translation can fail even when many individual word choices look reasonable because sentence-level structure still matters (Original source <em><a target=\"_blank\" rel=\"noopener noreferrer\" href=\"https://github.com/rasbt/LLMs-from-scratch\">LLMs-from-scratch</a></em>).</p>\n<p>The next figure shows that change more directly. When the decoder is producing an output token, it should not be limited to one compressed memory path. It should be able to reach back to the more relevant input tokens directly.</p>\n<p><a target=\"_blank\" rel=\"noopener noreferrer\" href=\"https://substackcdn.com/image/fetch/$s_!T2XV!,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2Feaafc89d-0765-4e90-8f2b-881032cb2d5b_3415x1914.webp\"><picture class=\"article-picture article-picture-fallback\" style=\"--image-ratio:16 / 9\"><img src=\"https://substackcdn.com/image/fetch/$s_!T2XV!,w_1456,c_limit,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2Feaafc89d-0765-4e90-8f2b-881032cb2d5b_3415x1914.webp\" alt=\"\" loading=\"lazy\" decoding=\"async\" fetchpriority=\"low\" referrerpolicy=\"no-referrer\" class=\"progressive-image\"></picture></a></p>\n<p>Figure 5: Attention breaks the RNN bottleneck by letting the current output position revisit the full input sequence instead of relying on one compressed state alone (Original source <em><a target=\"_blank\" rel=\"noopener noreferrer\" href=\"https://github.com/rasbt/LLMs-from-scratch\">LLMs-from-scratch</a></em>).</p>\n<p>Transformers keep that core idea from the aforementioned attention-modified RNN but remove the recurrence. In the classic <em><a target=\"_blank\" rel=\"noopener noreferrer\" href=\"https://arxiv.org/abs/1706.03762\">Attention Is All You Need</a></em> paper, attention becomes the main sequence-processing mechanism itself (instead of being just part of an RNN encoder-decoder.)</p>\n<p>In transformers, that mechanism is called self-attention, where each token in the sequence computes weights over all other tokens and uses them to mix information from those tokens into a new representation. Multi-head attention is the same mechanism run several times in parallel.</p>\n<p>For a sequence of <code>T</code> tokens, attention needs one row of weights per token, so overall we get a <code>T x T</code>matrix.</p>\n<p>Each row answers a simple question. When updating this token, how much should each visible token matter? In a decoder-only LLM, future positions are masked out, which is why the upper-right part of the matrix is grayed out in the figure below.</p>\n<p>Self-attention is fundamentally about learning these token-to-token weight patterns, under a causal mask, and then using them to build context-aware token representations.</p>\n<p><a target=\"_blank\" rel=\"noopener noreferrer\" href=\"https://substackcdn.com/image/fetch/$s_!8wZw!,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2Fd6e9affd-687b-4170-b1d5-f8e3d2834d2b_3449x1646.webp\"><picture class=\"article-picture article-picture-fallback\" style=\"--image-ratio:16 / 9\"><img src=\"https://substackcdn.com/image/fetch/$s_!8wZw!,w_1456,c_limit,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2Fd6e9affd-687b-4170-b1d5-f8e3d2834d2b_3449x1646.webp\" alt=\"\" loading=\"lazy\" decoding=\"async\" fetchpriority=\"low\" referrerpolicy=\"no-referrer\" class=\"progressive-image\"></picture></a></p>\n<p>Figure 6: A concrete masked attention matrix where each row belongs to one token, each entry is an attention weight, and future-token entries are removed by the causal mask (Original source <em><a target=\"_blank\" rel=\"noopener noreferrer\" href=\"https://magazine.sebastianraschka.com/p/understanding-and-coding-self-attention\">Understanding and Coding Self-Attention</a></em>).</p>\n<p>The next figure shows how the transformer computes the attention matrix (<code>A</code>) from the input embeddings <code>X</code>, which is then used to produce the transformed inputs (<code>Z</code>).</p>\n<p>Here <code>Q</code>, <code>K</code>, and <code>V</code> stand for queries, keys, and values. The query for a token represents what that token is looking for, the key represents what each token makes available for matching, and the value represents the information that gets mixed into the output once the attention weights have been computed.</p>\n<p>The steps are as follows:</p>\n<ul>\n<li>\n<p><code>Wq</code>, <code>Wk</code>, and <code>Wv</code> are weight matrices that project the input embeddings into <code>Q</code>, <code>K</code>, and <code>V</code></p>\n</li>\n<li>\n<p><code>QK^T</code> produces the raw token-to-token relevance scores</p>\n</li>\n<li>\n<p>softmax converts those scores into the normalized attention matrix <code>A</code> that we discussed in the previous section</p>\n</li>\n<li>\n<p><code>A</code> is applied to <code>V</code> to produce the output matrix <code>Z</code></p>\n</li>\n</ul>\n<p>Note that the attention matrix is not a separate hand-written object. It emerges from <code>Q</code>, <code>K</code>, and softmax.</p>\n<p>The next figure shows the same concept as the previous figure but the attention matrix computation is hidden inside the “scaled-dot-product attention” box, and we perform the computation only for one input token instead of all input tokens. This is to show a compact form of self-attention with a single head before extending this to multi-head attention in the next section.</p>\n<p><a target=\"_blank\" rel=\"noopener noreferrer\" href=\"https://substackcdn.com/image/fetch/$s_!VJyp!,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2F7dfb70d9-5eb6-44df-a880-3a37dfe72d7f_1836x1116.png\"><picture class=\"article-picture article-picture-fallback\" style=\"--image-ratio:16 / 9\"><img src=\"https://substackcdn.com/image/fetch/$s_!VJyp!,w_1456,c_limit,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2F7dfb70d9-5eb6-44df-a880-3a37dfe72d7f_1836x1116.png\" alt=\"\" loading=\"lazy\" decoding=\"async\" fetchpriority=\"low\" referrerpolicy=\"no-referrer\" class=\"progressive-image\"></picture></a></p>\n<p>Figure 8: One attention head is already a complete mechanism. One set of learned projections produces one attention matrix and one context-aware output stream (Original source <em><a target=\"_blank\" rel=\"noopener noreferrer\" href=\"https://magazine.sebastianraschka.com/p/understanding-and-coding-self-attention\">Understanding and Coding Self-Attention</a></em>).</p>\n<p>One set of <code>Wq/Wk/Wv</code> matrices gives us one attention head, which means one attention matrix and one output matrix <code>Z</code>. (This concept was illustrated in the previous section.)</p>\n<p>Multi-head attention simply runs several of these heads in parallel with different learned projection matrices.</p>\n<p>This is useful because different heads can specialize in different token relationships. One head might focus on short local dependencies, another on broader semantic links, and another on positional or syntactic structure.</p>\n<p><a target=\"_blank\" rel=\"noopener noreferrer\" href=\"https://substackcdn.com/image/fetch/$s_!MSOX!,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2F5f47ffd2-bb3a-4936-9720-a88b8d867337_1766x1154.png\"><picture class=\"article-picture article-picture-fallback\" style=\"--image-ratio:16 / 9\"><img src=\"https://substackcdn.com/image/fetch/$s_!MSOX!,w_1456,c_limit,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2F5f47ffd2-bb3a-4936-9720-a88b8d867337_1766x1154.png\" alt=\"\" loading=\"lazy\" decoding=\"async\" fetchpriority=\"low\" referrerpolicy=\"no-referrer\" class=\"progressive-image\"></picture></a></p>\n<p>Figure 9: Multi-head attention keeps the same basic attention recipe, but repeats it across several heads in parallel so the model can learn several token-to-token patterns at once (Original source <em><a target=\"_blank\" rel=\"noopener noreferrer\" href=\"https://magazine.sebastianraschka.com/p/understanding-and-coding-self-attention\">Understanding and Coding Self-Attention</a></em>).</p>\n<p>Grouped-query attention is an attention variant derived from standard MHA. It was introduced in the 2023 paper <em><a target=\"_blank\" rel=\"noopener noreferrer\" href=\"https://arxiv.org/abs/2305.13245\">GQA: Training Generalized Multi-Query Transformer Models from Multi-Head Checkpoints</a></em> by Joshua Ainslie and colleagues.</p>\n<p>Instead of giving every query head its own keys and values, it lets several query heads share the same key-value projections, which makes <a target=\"_blank\" rel=\"noopener noreferrer\" href=\"https://magazine.sebastianraschka.com/p/coding-the-kv-cache-in-llms?utm_source=publication-search\">KV caching</a> much cheaper (primarily as a memory reduction) without changing the overall decoder recipe very much.</p>\n<p><a target=\"_blank\" rel=\"noopener noreferrer\" href=\"https://substackcdn.com/image/fetch/$s_!h6wM!,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2F6f39923c-8357-487d-9e69-40ee18a902e8_2523x1248.png\"><picture class=\"article-picture article-picture-fallback\" style=\"--image-ratio:16 / 9\"><img src=\"https://substackcdn.com/image/fetch/$s_!h6wM!,w_1456,c_limit,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2F6f39923c-8357-487d-9e69-40ee18a902e8_2523x1248.png\" alt=\"\" loading=\"lazy\" decoding=\"async\" fetchpriority=\"low\" referrerpolicy=\"no-referrer\" class=\"progressive-image\"></picture></a></p>\n<p>Figure 10: GQA keeps the same overall attention pattern as MHA, but collapses the number of key-value heads by sharing them across multiple query heads (Original source: <em><a target=\"_blank\" rel=\"noopener noreferrer\" href=\"https://magazine.sebastianraschka.com/p/the-big-llm-architecture-comparison\">The Big LLM Architecture Comparison</a></em>).</p>\n<p><strong>EXAMPLE ARCHITECTURES</strong></p>\n<p>Dense: <a target=\"_blank\" rel=\"noopener noreferrer\" href=\"https://sebastianraschka.com/llm-architecture-gallery/#card-llama-3-8b\">Llama 3 8B</a>, <a target=\"_blank\" rel=\"noopener noreferrer\" href=\"https://sebastianraschka.com/llm-architecture-gallery/#card-qwen3-4b\">Qwen3 4B</a>, <a target=\"_blank\" rel=\"noopener noreferrer\" href=\"https://sebastianraschka.com/llm-architecture-gallery/#card-gemma-3-27b\">Gemma 3 27B</a>, <a target=\"_blank\" rel=\"noopener noreferrer\" href=\"https://sebastianraschka.com/llm-architecture-gallery/#card-mistral-small-3-1-24b\">Mistral Small 3.1 24B</a>, <a target=\"_blank\" rel=\"noopener noreferrer\" href=\"https://sebastianraschka.com/llm-architecture-gallery/#card-smollm3-3b\">SmolLM3 3B</a>, and <a target=\"_blank\" rel=\"noopener noreferrer\" href=\"https://sebastianraschka.com/llm-architecture-gallery/#card-tiny-aya-3-35b\">Tiny Aya 3.35B</a>.<br />\nSparse (Mixture-of-Experts): <a target=\"_blank\" rel=\"noopener noreferrer\" href=\"https://sebastianraschka.com/llm-architecture-gallery/#card-llama-4-maverick\">Llama 4 Maverick</a>, <a target=\"_blank\" rel=\"noopener noreferrer\" href=\"https://sebastianraschka.com/llm-architecture-gallery/#card-qwen3-235b-a22b\">Qwen3 235B-A22B</a>, <a target=\"_blank\" rel=\"noopener noreferrer\" href=\"https://sebastianraschka.com/llm-architecture-gallery/#card-step-3-5-flash-196b\">Step 3.5 Flash 196B</a>, and <a target=\"_blank\" rel=\"noopener noreferrer\" href=\"https://sebastianraschka.com/llm-architecture-gallery/#card-sarvam-30b\">Sarvam 30B</a>.</p>\n<p>In my <a target=\"_blank\" rel=\"noopener noreferrer\" href=\"https://magazine.sebastianraschka.com/p/the-big-llm-architecture-comparison\">architecture comparison article</a>, I framed GQA as the new standard replacement for classic multi-head attention (MHA). The reason is that standard MHA gives every head its own keys and values, which is more optimal from a modeling perspective but expensive once we have to keep all of that state in the <a target=\"_blank\" rel=\"noopener noreferrer\" href=\"https://magazine.sebastianraschka.com/p/coding-the-kv-cache-in-llms?utm_source=publication-search\">KV cache</a> during inference.</p>\n<p>In GQA, we keep a larger set of query heads, but we reduce the number of key-value heads and let multiple queries share them. That lowers both parameter count and <a target=\"_blank\" rel=\"noopener noreferrer\" href=\"https://magazine.sebastianraschka.com/p/coding-the-kv-cache-in-llms?utm_source=publication-search\">KV-cache</a> traffic without making drastic implementation changes like multi-head latent attention (MLA), which will be discussed later.</p>\n<p>In practice, that made and keeps it a very popular choice for labs that wanted something cheaper than MHA but simpler to implement than newer compression-heavy alternatives like MLA.</p>\n<p>GQA results in big savings in KV storage, since the fewer key-value heads we keep per layer, the less cached state we need per token. That is why GQA becomes more useful as sequence length grows.</p>\n<p>GQA is also a spectrum. If we reduce all the way down to one shared K/V group, we are effectively in multi-query attention territory, which is even cheaper but can hurt modeling quality more noticeably. The sweet spot is usually somewhere in between multi-query attention (1 shared group) and MHA (where K/V groups are equal to the number of queries), where the cache savings are large but the modeling degradation relative to MHA stays modest.</p>\n<p>More advanced variants such as MLA are becoming popular because they can offer better modeling performance at the same KV efficiency levels (e.g., as discussed in the ablation studies of the <a target=\"_blank\" rel=\"noopener noreferrer\" href=\"https://arxiv.org/abs/2405.04434\">DeepSeek-V2 paper</a>), but they also involve a more complicated implementation and a more complicated attention stack.</p>\n<p>GQA remains appealing because it is robust, easier to implement, and also easier to train (since there are fewer hyperparameter tunings necessary, based on my experience).</p>\n<p>That is why some of the newer releases still stay deliberately classic here. E.g., in my <a target=\"_blank\" rel=\"noopener noreferrer\" href=\"https://magazine.sebastianraschka.com/p/a-dream-of-spring-for-open-weight\">Spring Architectures</a> article, I mentioned that MiniMax M2.5 and Nanbeige 4.1 as models that remained very classic, using only grouped-query attention without piling on other efficiency tricks. Sarvam is a particularly useful comparison point as well: the 30B model keeps classic GQA, while the 105B version switches to MLA.</p>\n<p><a target=\"_blank\" rel=\"noopener noreferrer\" href=\"https://substackcdn.com/image/fetch/$s_!BMEL!,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2F2d04f89a-aad5-4af7-8b46-4623d1d53ae9_5860x5682.webp\"><picture class=\"article-picture article-picture-fallback\" style=\"--image-ratio:16 / 9\"><img src=\"https://substackcdn.com/image/fetch/$s_!BMEL!,w_1456,c_limit,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2F2d04f89a-aad5-4af7-8b46-4623d1d53ae9_5860x5682.webp\" alt=\"\" loading=\"lazy\" decoding=\"async\" fetchpriority=\"low\" referrerpolicy=\"no-referrer\" class=\"progressive-image\"></picture></a></p>\n<p>Figure 12: Total KV cache sizes for 105B Sarvam (using MLA) versus 30B Sarvam (using GQA), versus using plain MHA.</p>\n<p>The motivation behind Multi-head Latent Attention (MLA) is similar to Grouped-Query Attention (GQA). Both are solutions for reducing <a target=\"_blank\" rel=\"noopener noreferrer\" href=\"https://magazine.sebastianraschka.com/p/coding-the-kv-cache-in-llms?utm_source=publication-search\">KV-cache</a> memory requirements. The difference between GQA and MLA is that MLA shrinks the cache by compressing what gets stored rather than by reducing how many K/Vs are stored by sharing heads.</p>\n<p><a target=\"_blank\" rel=\"noopener noreferrer\" href=\"https://substackcdn.com/image/fetch/$s_!FcJB!,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2Fe29cb535-8854-4412-af8d-9bca8d8d05f2_1550x858.webp\"><picture class=\"article-picture article-picture-fallback\" style=\"--image-ratio:16 / 9\"><img src=\"https://substackcdn.com/image/fetch/$s_!FcJB!,w_1456,c_limit,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2Fe29cb535-8854-4412-af8d-9bca8d8d05f2_1550x858.webp\" alt=\"\" loading=\"lazy\" decoding=\"async\" fetchpriority=\"low\" referrerpolicy=\"no-referrer\" class=\"progressive-image\"></picture></a></p>\n<p>Figure 13: Unlike GQA, MLA does not reduce KV cost by grouping heads. It reduces it by caching a compressed latent representation. Note that it is also applied to the query, which is not shown for simplicity (Original source:<em><a target=\"_blank\" rel=\"noopener noreferrer\" href=\"https://magazine.sebastianraschka.com/p/the-big-llm-architecture-comparison\">The Big LLM Architecture Comparison</a></em>).</p>\n<p>MLA, originally proposed in the <a target=\"_blank\" rel=\"noopener noreferrer\" href=\"https://arxiv.org/abs/2405.04434\">DeepSeek-V2</a> paper, became such a defining DeepSeek-era idea (especially after DeepSeek-V3 and R1). It is more complicated to implement than GQA, more complicated to serve, but nowadays also often more compelling once model size and context length get large enough that cache traffic starts to dominate, because at the same rate of memory reduction, it could maintain better modeling performance (more on that later).</p>\n<p><strong>EXAMPLE ARCHITECTURES</strong></p>\n<p><a target=\"_blank\" rel=\"noopener noreferrer\" href=\"https://sebastianraschka.com/llm-architecture-gallery/#card-deepseek-v3\">DeepSeek V3</a>, <a target=\"_blank\" rel=\"noopener noreferrer\" href=\"https://sebastianraschka.com/llm-architecture-gallery/#card-kimi-k2\">Kimi K2</a>, <a target=\"_blank\" rel=\"noopener noreferrer\" href=\"https://sebastianraschka.com/llm-architecture-gallery/#card-glm-5-744b\">GLM-5</a>, <a target=\"_blank\" rel=\"noopener noreferrer\" href=\"https://sebastianraschka.com/llm-architecture-gallery/#card-ling-2-5-1t\">Ling 2.5</a>, <a target=\"_blank\" rel=\"noopener noreferrer\" href=\"https://sebastianraschka.com/llm-architecture-gallery/#card-mistral-large-3\">Mistral Large 3</a>, and <a target=\"_blank\" rel=\"noopener noreferrer\" href=\"https://sebastianraschka.com/llm-architecture-gallery/#card-sarvam-105b\">Sarvam 105B</a></p>\n<p>Instead of caching full-resolution key and value tensors as in MHA and GQA, MLA stores a latent representation and reconstructs the usable state when needed. Essentially, it is a cache compression strategy embedded inside attention, as illustrated in the previous figure.</p>\n<p>The figure below shows the savings compared to regular MHA.</p>\n<p><a target=\"_blank\" rel=\"noopener noreferrer\" href=\"https://substackcdn.com/image/fetch/$s_!56rA!,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2F186dfe98-db29-4b12-97ab-39d5b21ab460_1920x1440.png\"><picture class=\"article-picture article-picture-fallback\" style=\"--image-ratio:16 / 9\"><img src=\"https://substackcdn.com/image/fetch/$s_!56rA!,w_1456,c_limit,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2F186dfe98-db29-4b12-97ab-39d5b21ab460_1920x1440.png\" alt=\"\" loading=\"lazy\" decoding=\"async\" fetchpriority=\"low\" referrerpolicy=\"no-referrer\" class=\"progressive-image\"></picture></a></p>\n<p>Figure 14: Once context length grows, the savings from caching a latent representation instead of full K/V tensors become very visible (Original source: <em><a target=\"_blank\" rel=\"noopener noreferrer\" href=\"https://github.com/rasbt/LLMs-from-scratch/tree/main/ch04/05_mla\">LLMs-from-scratch</a></em><a target=\"_blank\" rel=\"noopener noreferrer\" href=\"https://github.com/rasbt/LLMs-from-scratch/tree/main/ch04/05_mla\">MLA</a> section).</p>\n<p>The DeepSeek-V2 paper provided some ablations where GQA looked worse than MHA in terms of modeling performance, while MLA held up much better and could even outperform MHA when tuned carefully. That is a much stronger justification than “it (also) saves memory.”</p>\n<p>In other words, MLA is a preferable attention mechanism for DeepSeek not just because it was efficient, but because it looked like a quality-preserving efficiency move at large scale. (But colleagues also told me that MLA only works well at a certain size. For smaller models, let’s say &lt;100B, GQA seems to work better, or, is at least easier to tune and get right.)</p>\n<p><a target=\"_blank\" rel=\"noopener noreferrer\" href=\"https://substackcdn.com/image/fetch/$s_!1yW7!,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2Ff564ec9f-5fcb-49c3-b728-b4c8a769bb6c_952x902.png\"><picture class=\"article-picture article-picture-fallback\" style=\"--image-ratio:16 / 9\"><img src=\"https://substackcdn.com/image/fetch/$s_!1yW7!,w_1456,c_limit,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2Ff564ec9f-5fcb-49c3-b728-b4c8a769bb6c_952x902.png\" alt=\"\" loading=\"lazy\" decoding=\"async\" fetchpriority=\"low\" referrerpolicy=\"no-referrer\" class=\"progressive-image\"></picture></a></p>\n<p>Figure 15: GQA drops below MHA here, while MLA remains competitive and can even slightly outperform it. Underlying paper: <a target=\"_blank\" rel=\"noopener noreferrer\" href=\"https://arxiv.org/abs/2405.04434\">DeepSeek-V2</a>.</p>\n<p>Below is again the comparison between GQA in 30B Sarvam versus MLA in 105B Sarvam.</p>\n<p><a target=\"_blank\" rel=\"noopener noreferrer\" href=\"https://substackcdn.com/image/fetch/$s_!cbqs!,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2Fa425874e-baae-45bb-a199-46648c5db725_5860x5682.webp\"><picture class=\"article-picture article-picture-fallback\" style=\"--image-ratio:16 / 9\"><img src=\"https://substackcdn.com/image/fetch/$s_!cbqs!,w_1456,c_limit,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2Fa425874e-baae-45bb-a199-46648c5db725_5860x5682.webp\" alt=\"\" loading=\"lazy\" decoding=\"async\" fetchpriority=\"low\" referrerpolicy=\"no-referrer\" class=\"progressive-image\"></picture></a></p>\n<p>Figure 16: GQA and MLA are solving the same bottleneck from different directions. The tradeoff is simplicity versus better modeling performance for larger models.</p>\n<p>Once DeepSeek V3/R1, V3.1 etc. normalized the design after its introduction in V2, it started showing up in a second wave of architectures. Kimi K2 kept the DeepSeek recipe and scaled it up. GLM-5 adopted MLA together with DeepSeek Sparse Attention (from DeepSeek V3.2). Ling 2.5 paired MLA with a linear-attention hybrid. Sarvam released two models where the 30B model stayed with classic GQA and the 105B model switched to MLA.</p>\n<p>That last pair is particularly useful as it puts the technical-complexity discussion aside. I.e., the Sarvam team implemented both variants and deliberately chose to then use GQA for one variant and MLA for the other. So, in a sense, that makes MLA feel less like a theoretical alternative and more like a concrete architectural upgrade path once a family scales up.</p>\n<p>Sliding window attention reduces the memory and compute cost of long-context inference by limiting how many previous tokens each position can attend to. Instead of attending to the entire prefix, each token only attends to a fixed window of recent tokens around its position. Because attention is restricted to a local token neighborhood, this mechanism is often referred to as local attention.</p>\n<p>Some architectures combine these local layers with occasional global attention layers so that information can still propagate across the entire sequence.</p>\n<p><a target=\"_blank\" rel=\"noopener noreferrer\" href=\"https://substackcdn.com/image/fetch/$s_!edFZ!,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2F48a9cd31-24a5-47d9-ae37-506763ebc67d_1292x704.png\"><picture class=\"article-picture article-picture-fallback\" style=\"--image-ratio:16 / 9\"><img src=\"https://substackcdn.com/image/fetch/$s_!edFZ!,w_1456,c_limit,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2F48a9cd31-24a5-47d9-ae37-506763ebc67d_1292x704.png\" alt=\"\" loading=\"lazy\" decoding=\"async\" fetchpriority=\"low\" referrerpolicy=\"no-referrer\" class=\"progressive-image\"></picture></a></p>\n<p>Figure 17: The conceptual shift is simple. Regular attention is global attention, while sliding-window attention is local attention. Global attention lets every token see the full prefix; SWA turns many of those layers into local attention layers (Original source: <em><a target=\"_blank\" rel=\"noopener noreferrer\" href=\"https://magazine.sebastianraschka.com/p/the-big-llm-architecture-comparison\">The Big LLM Architecture Comparison</a></em>).</p>\n<p><strong>EXAMPLE ARCHITECTURES</strong></p>\n<p><a target=\"_blank\" rel=\"noopener noreferrer\" href=\"https://sebastianraschka.com/llm-architecture-gallery/#card-gemma-3-27b\">Gemma 3 27B</a>, <a target=\"_blank\" rel=\"noopener noreferrer\" href=\"https://sebastianraschka.com/llm-architecture-gallery/#card-olmo-3-32b\">OLMo 3 32B</a>, <a target=\"_blank\" rel=\"noopener noreferrer\" href=\"https://sebastianraschka.com/llm-architecture-gallery/#card-xiaomi-mimo-v2-flash-309b\">Xiaomi MiMo-V2-Flash</a>, <a target=\"_blank\" rel=\"noopener noreferrer\" href=\"https://sebastianraschka.com/llm-architecture-gallery/#card-arcee-ai-trinity-large-400b\">Arcee Trinity</a>, <a target=\"_blank\" rel=\"noopener noreferrer\" href=\"https://sebastianraschka.com/llm-architecture-gallery/#card-step-3-5-flash-196b\">Step 3.5 Flash</a>, and <a target=\"_blank\" rel=\"noopener noreferrer\" href=\"https://sebastianraschka.com/llm-architecture-gallery/#card-tiny-aya-3-35b\">Tiny Aya</a></p>\n<p>Gemma 3 is still one of the clearest recent SWA examples because it is easy to compare against Gemma 2. Gemma 2 already used a hybrid attention setup with a 1:1 ratio between local and global layers and a 4096-token window. Gemma 3 pushed this further to a 5:1 ratio and reduced the window size to 1024.</p>\n<p>The key finding was not that local attention is cheaper, because that was already known. Here, the more interesting takeaway from the Gemma 3 ablation study was that using this more aggressively seemed to hurt modeling performance only slightly.</p>\n<p>In practice, saying that a model “uses SWA” does not mean it relies on SWA alone. What usually matters are the local-to-global layer pattern and the attention window size. For example:</p>\n<ul>\n<li>\n<p>Gemma 3 and Xiaomi use a 5:1 local-to-global pattern.</p>\n</li>\n<li>\n<p>OLMo 3 and Arcee Trinity use a 3:1 pattern.</p>\n</li>\n<li>\n<p>Xiaomi also uses a window size of 128, which is much smaller, and therefore more aggressive, than Gemma’s 1024.</p>\n</li>\n</ul>\n<p>SWA is essentially a knob that can be tuned more or less aggressively.</p>\n<p><a target=\"_blank\" rel=\"noopener noreferrer\" href=\"https://substackcdn.com/image/fetch/$s_!3FBb!,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2F38e10000-db6c-43fa-844b-ed7d4dfe644c_3299x3302.webp\"><picture class=\"article-picture article-picture-fallback\" style=\"--image-ratio:16 / 9\"><img src=\"https://substackcdn.com/image/fetch/$s_!3FBb!,w_1456,c_limit,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2F38e10000-db6c-43fa-844b-ed7d4dfe644c_3299x3302.webp\" alt=\"\" loading=\"lazy\" decoding=\"async\" fetchpriority=\"low\" referrerpolicy=\"no-referrer\" class=\"progressive-image\"></picture></a></p>\n<p>Figure 18: The long-context savings come from turning many full-attention layers into local ones, which reduces how much cached context those layers need to consider (Original source: <em><a target=\"_blank\" rel=\"noopener noreferrer\" href=\"https://github.com/rasbt/LLMs-from-scratch/tree/main/ch04/06_swa\">LLMs-from-scratch</a></em><a target=\"_blank\" rel=\"noopener noreferrer\" href=\"https://github.com/rasbt/LLMs-from-scratch/tree/main/ch04/06_swa\">SWA materials</a>).</p>\n<p>SWA often appears together with <a target=\"_blank\" rel=\"noopener noreferrer\" href=\"http://127.0.0.1:4000/llm-architecture-gallery/gqa/\">GQA</a> because the two ideas address different parts of the same inference problem. SWA reduces how much context a local layer has to consider. GQA reduces how much key-value state each token contributes to the cache.</p>\n<p>That is why many recent dense models use both rather than treating them as alternatives. Gemma 3 is again a good reference point here, since it combines sliding window attention with grouped-query attention in the same architecture.</p>\n<p>DeepSeek Sparse Attention is one of the architectural changes that appeared in the <a target=\"_blank\" rel=\"noopener noreferrer\" href=\"https://arxiv.org/abs/2512.02556\">DeepSeek V3.2</a> line and later showed up again in GLM-5.</p>\n<p>Specifically, DeepSeek V3.2 combines it with <a target=\"_blank\" rel=\"noopener noreferrer\" href=\"https://sebastianraschka.com/llm-architecture-gallery/mla/\">Multi-head Latent Attention (MLA)</a>, and GLM-5 adopts the same pair for the same general reason, namely, reducing inference cost when context lengths get large.</p>\n<p><strong>EXAMPLE ARCHITECTURES</strong></p>\n<p><a target=\"_blank\" rel=\"noopener noreferrer\" href=\"https://sebastianraschka.com/llm-architecture-gallery/#card-deepseek-v3-2\">DeepSeek V3.2</a> and <a target=\"_blank\" rel=\"noopener noreferrer\" href=\"https://sebastianraschka.com/llm-architecture-gallery/#card-glm-5-744b\">GLM-5</a></p>\n<p>In sliding-window attention, the current token does not attend to the full prefix but only to a fixed local window. This is the same broad idea behind DeepSeek Sparse Attention, where each token also only attends to a subset of previous tokens.</p>\n<p>However, the selected tokens are not determined by a fixed-width local window. Instead, DeepSeek Sparse Attention uses a learned sparse pattern. In short, it uses an indexer-plus-selector setup, where a lightning indexer computes relevance scores, and a token selector keeps only a smaller set of high-scoring past positions.</p>\n<p>The way the subset of tokens is selected is the main difference from sliding-window attention. Sliding-window attention hard-codes locality. DeepSeek Sparse Attention still limits attention to a subset, but it lets the model decide which prior tokens are worth revisiting.</p>\n<p>DeepSeek V3.2 uses both Multi-head Latent Attention (MLA) and DeepSeek Sparse Attention. MLA reduces <a target=\"_blank\" rel=\"noopener noreferrer\" href=\"https://magazine.sebastianraschka.com/p/coding-the-kv-cache-in-llms?utm_source=publication-search\">KV-cache</a> cost by compressing what gets stored. DeepSeek Sparse Attention reduces how much of the prior context the model has to revisit. Put differently, one optimizes the cache representation, the other optimizes the attention pattern on top of it.</p>\n<p><a target=\"_blank\" rel=\"noopener noreferrer\" href=\"https://substackcdn.com/image/fetch/$s_!B4GF!,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2Fad5026e1-1dbd-4004-814f-6cd6d735e572_2787x2731.webp\"><picture class=\"article-picture article-picture-fallback\" style=\"--image-ratio:16 / 9\"><img src=\"https://substackcdn.com/image/fetch/$s_!B4GF!,w_1456,c_limit,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2Fad5026e1-1dbd-4004-814f-6cd6d735e572_2787x2731.webp\" alt=\"\" loading=\"lazy\" decoding=\"async\" fetchpriority=\"low\" referrerpolicy=\"no-referrer\" class=\"progressive-image\"></picture></a></p>\n<p>Figure 20: DeepSeek V3.2 is the obvious reference point, because this is the model family most closely associated with the sparse-attention idea.</p>\n<p>The sparse pattern is not random. The first stage is a lightning indexer that scores previous tokens for each new query token. It uses MLA’s compressed token representations and computes a learned similarity score over the prior context, so the model can rank which earlier positions are worth revisiting.</p>\n<p>The second stage is a token selector. It keeps only a smaller high-scoring subset, for example, a top-<code>k</code>set of past positions, and turns that subset into the sparse attention mask. So the main point is that DeepSeek Sparse Attention does not hard-code the sparsity pattern. It learns which past tokens to keep.</p>\n<p>DeepSeek Sparse Attention is relatively new and relatively complicated to implement, which is why it has not been so widely adopted as Grouped-Query Attention (GQA) yet.</p>\n<p>Gated attention is best understood as a modified full-attention block rather than as a separate attention family.</p>\n<p>It usually appears inside hybrid stacks that still keep an occasional full-attention layer for exact content retrieval, but add a few stability-oriented changes on top of an otherwise familiar scaled dot-product attention block.</p>\n<p><a target=\"_blank\" rel=\"noopener noreferrer\" href=\"https://substackcdn.com/image/fetch/$s_!syqZ!,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2F2d109b38-96a1-4830-b1f0-7274e405317a_3973x5350.webp\"><picture class=\"article-picture article-picture-fallback\" style=\"--image-ratio:16 / 9\"><img src=\"https://substackcdn.com/image/fetch/$s_!syqZ!,w_1456,c_limit,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2F2d109b38-96a1-4830-b1f0-7274e405317a_3973x5350.webp\" alt=\"\" loading=\"lazy\" decoding=\"async\" fetchpriority=\"low\" referrerpolicy=\"no-referrer\" class=\"progressive-image\"></picture></a></p>\n<p>Figure 22: Trinity Large is a useful comparison because gated attention is not only a Qwen idea (more on that later). Here the gate appears after the scaled dot-product attention output and before the output projection in a different long-context architecture (Original source: <em><a target=\"_blank\" rel=\"noopener noreferrer\" href=\"https://magazine.sebastianraschka.com/p/a-dream-of-spring-for-open-weight\">A Dream of Spring for Open-Weight LLMs</a></em>).</p>\n<p>The Qwen3-Next and Qwen3.5 architectures show that recent hybrids (covered in the next section) do not replace attention everywhere. Instead, they replace most attention layers with a cheaper alternative and keep a smaller number of full-attention layers in the stack.</p>\n<p>Those remaining full-attention layers are where gated attention typically appears. Qwen3-Next and Qwen3.5 use it together with Gated DeltaNet in a 3:1 pattern.</p>\n<p>But hybrid architectures aside, Trinity uses a related gating idea in a more conventional attention stack, as shown in the previous figure above.</p>\n<p>The gated attention block in Qwen-style hybrids or Trinity (not a hybrid) is essentially standard scaled-dot-product attention with a few changes on top. In the original <a target=\"_blank\" rel=\"noopener noreferrer\" href=\"https://arxiv.org/abs/2505.06708\">Gated Attention paper</a>, those changes are presented as a way to make the retained full-attention layers behave more predictably inside a hybrid stack.</p>\n<p>The block still looks like standard (full) attention, but it adds:</p>\n<ol>\n<li>\n<p>an output gate that scales the attention result before it is added back to the residual,</p>\n</li>\n<li>\n<p>a zero-centered QK-Norm variant instead of standard RMSNorm for q and k,</p>\n</li>\n<li>\n<p>partial RoPE.</p>\n</li>\n</ol>\n<p>These are not changes on the scale of MLA or linear attention but merely stability and control changes applied to an otherwise familiar attention block.</p>\n<p><a target=\"_blank\" rel=\"noopener noreferrer\" href=\"https://substackcdn.com/image/fetch/$s_!VVeK!,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2Fafe94d77-ab5f-4420-88e4-8ba1f91992e0_2484x3278.webp\"><picture class=\"article-picture article-picture-fallback\" style=\"--image-ratio:16 / 9\"><img src=\"https://substackcdn.com/image/fetch/$s_!VVeK!,w_1456,c_limit,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2Fafe94d77-ab5f-4420-88e4-8ba1f91992e0_2484x3278.webp\" alt=\"\" loading=\"lazy\" decoding=\"async\" fetchpriority=\"low\" referrerpolicy=\"no-referrer\" class=\"progressive-image\"></picture></a></p>\n<p>Figure 23: In Qwen3-Next and Qwen3.5, gated attention appears as the full-attention layer that periodically breaks up runs of Gated DeltaNet blocks.</p>\n<p>Note that the figure above also includes Gated DeltaNet, which we will cover in the next section below.</p>\n<p>Hybrid attention is a broader design pattern rather than a specific, single mechanism. The overall idea is to keep a transformer-like stack, but replace most of the expensive full-attention layers with cheaper linear or state-space sequence modules.</p>\n<p>The motivation is long-context efficiency. Full attention grows quadratically with sequence length, so once models move to contexts like 128k, 256k, or 1M tokens, attention memory and compute become expensive enough that using cheaper sequence modules in most layers while keeping only a smaller number of heavier retrieval layers starts making more sense. (Note that this comes with a bit of a modeling performance trade-off, though.)</p>\n<p>In Qwen3-Next, this pattern appears as a 3:1 mix of Gated DeltaNet and Gated Attention blocks. Gated DeltaNet is also closely related to Mamba-2 (see the <em><a target=\"_blank\" rel=\"noopener noreferrer\" href=\"https://arxiv.org/abs/2412.06464\">Gated Delta Networks: Improving Mamba2 with Delta Rule</a></em> paper, for instance), and the mechanism can be read as a DeltaNet-style fast-weight update combined with Mamba-style gating. Later architectures keep the same overall idea but swap in other lightweight sequence mixers, such as Kimi Delta Attention, Lightning Attention, or standard Mamba-2.</p>\n<p><a target=\"_blank\" rel=\"noopener noreferrer\" href=\"https://substackcdn.com/image/fetch/$s_!XRZY!,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2F876009cb-5479-4e95-9b7d-faebe1f87e89_3252x2158.webp\"><picture class=\"article-picture article-picture-fallback\" style=\"--image-ratio:16 / 9\"><img src=\"https://substackcdn.com/image/fetch/$s_!XRZY!,w_1456,c_limit,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2F876009cb-5479-4e95-9b7d-faebe1f87e89_3252x2158.webp\" alt=\"\" loading=\"lazy\" decoding=\"async\" fetchpriority=\"low\" referrerpolicy=\"no-referrer\" class=\"progressive-image\"></picture></a></p>\n<p>Figure 24: The basic hybrid pattern, where most blocks are cheaper sequence mixers and every fourth block restores a heavier attention layer (Original source <em><a target=\"_blank\" rel=\"noopener noreferrer\" href=\"https://magazine.sebastianraschka.com/p/the-big-llm-architecture-comparison\">The Big LLM Architecture Comparison</a></em>).</p>\n<p>To my knowledge, the first prominent example of a close-to-flagship LLM with hybrid attention was Qwen3-Next in 2025, which does not remove attention completely but mixes three Gated DeltaNet blocks with one Gated Attention block.</p>\n<p>Here, lightweight Gated DeltaNet blocks do most of the long-context work and keep memory growth much flatter than full attention. The heavier gated-attention layer remains because DeltaNet is less exact at content-based retrieval.</p>\n<p>Inside a Gated DeltaNet block, the model computes query, key, and value vectors together with two learned gates (α, β). Rather than forming the usual token-to-token attention matrix, it writes to a small fast-weight memory using a delta-rule update. In rough terms, the memory stores a compressed running summary of past information, while the gates control how much new information is added and how much previous state is retained.</p>\n<p>That makes Gated DeltaNet a linear-attention or recurrent-style mechanism rather than just another tweak to MHA. Relative to Mamba-2, the close connection is that both belong to the linear-time gated sequence-model family, but Gated DeltaNet uses a DeltaNet-style fast-weight memory update instead of the Mamba state-space update.</p>\n<p><a target=\"_blank\" rel=\"noopener noreferrer\" href=\"https://substackcdn.com/image/fetch/$s_!hK9M!,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2Fb82c3202-6c49-4cd7-a4eb-ab18edcd908e_2100x1350.png\"><picture class=\"article-picture article-picture-fallback\" style=\"--image-ratio:16 / 9\"><img src=\"https://substackcdn.com/image/fetch/$s_!hK9M!,w_1456,c_limit,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2Fb82c3202-6c49-4cd7-a4eb-ab18edcd908e_2100x1350.png\" alt=\"\" loading=\"lazy\" decoding=\"async\" fetchpriority=\"low\" referrerpolicy=\"no-referrer\" class=\"progressive-image\"></picture></a></p>\n<p>Figure 25: The practical motivation behind the hybrids is shown here in the memory curve. Hybrid stacks with Gated DeltaNet grow much more slowly with context length than ordinary full attention (Original source <em><a target=\"_blank\" rel=\"noopener noreferrer\" href=\"https://github.com/rasbt/LLMs-from-scratch/tree/main/ch04/08_deltanet\">LLMs-from-scratch</a></em><a target=\"_blank\" rel=\"noopener noreferrer\" href=\"https://github.com/rasbt/LLMs-from-scratch/tree/main/ch04/08_deltanet\">DeltaNet materials</a>).</p>\n<p>Qwen3.5 moves the former Qwen3-Next hybrid into Qwen’s main flagship series, which is an interesting move. This basically signals that the hybrid strategy is a success and that we may see more models with this architecture in the future.</p>\n<p><a target=\"_blank\" rel=\"noopener noreferrer\" href=\"https://substackcdn.com/image/fetch/$s_!L9cU!,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2F11deeb70-5766-41eb-bc93-b7c8f81afcb7_2048x1281.png\"><picture class=\"article-picture article-picture-fallback\" style=\"--image-ratio:16 / 9\"><img src=\"https://substackcdn.com/image/fetch/$s_!L9cU!,w_1456,c_limit,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2F11deeb70-5766-41eb-bc93-b7c8f81afcb7_2048x1281.png\" alt=\"\" loading=\"lazy\" decoding=\"async\" fetchpriority=\"low\" referrerpolicy=\"no-referrer\" class=\"progressive-image\"></picture></a></p>\n<p>Figure 26: Qwen3.5 shows the Qwen team promoting the former Qwen3-Next side-branch into the main model line rather than leaving it as a one-off efficiency variant (Original source <em><a target=\"_blank\" rel=\"noopener noreferrer\" href=\"https://magazine.sebastianraschka.com/p/a-dream-of-spring-for-open-weight\">A Dream of Spring for Open-Weight LLMs</a></em>).</p>\n<p>Kimi Linear keeps the same broad transformer skeleton and the same 3:1 pattern, but it changes both halves of the recipe.</p>\n<p>On the lightweight side, Kimi Delta Attention is a refinement of Gated DeltaNet. Where Qwen3-Next uses a scalar gate per head to control memory decay, Kimi uses channel-wise gating, which gives finer control over the memory update. On the heavier side, Kimi replaces Qwen3-Next’s gated-attention layers with gated MLA layers.</p>\n<p>So, it’s still the same broader pattern as in Qwen3-Next and Qwen3.5, but both ingredients (slightly) change. I.e., most layers are still handled by a cheaper linear-style mechanism, and periodic heavier layers still remain for stronger retrieval.</p>\n<p><a target=\"_blank\" rel=\"noopener noreferrer\" href=\"https://substackcdn.com/image/fetch/$s_!Q1wq!,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2F38f5b449-f122-4520-b6ea-a2437fd9508e_2376x1572.webp\"><picture class=\"article-picture article-picture-fallback\" style=\"--image-ratio:16 / 9\"><img src=\"https://substackcdn.com/image/fetch/$s_!Q1wq!,w_1456,c_limit,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2F38f5b449-f122-4520-b6ea-a2437fd9508e_2376x1572.webp\" alt=\"\" loading=\"lazy\" decoding=\"async\" fetchpriority=\"low\" referrerpolicy=\"no-referrer\" class=\"progressive-image\"></picture></a></p>\n<p>Figure 27: Kimi Linear keeps the same overall hybrid pattern while changing both the lightweight side and the heavier attention side of the stack (Original source <em><a target=\"_blank\" rel=\"noopener noreferrer\" href=\"https://magazine.sebastianraschka.com/p/the-big-llm-architecture-comparison\">The Big LLM Architecture Comparison</a></em>).</p>\n<p>Ling 2.5 shows another swap on the lightweight side. Instead of Gated DeltaNet, Ling uses a slightly simpler recurrent linear attention variant called Lightning Attention. On the heavier side, it keeps MLA from DeepSeek.</p>\n<p>Most sequence mixing happens in the cheaper linear-attention blocks, while a smaller number of heavier layers remain to preserve stronger retrieval. The difference is that the specific lightweight mechanism is now Lightning Attention rather than DeltaNet or Kimi Delta Attention.</p>\n<p><a target=\"_blank\" rel=\"noopener noreferrer\" href=\"https://substackcdn.com/image/fetch/$s_!xCw3!,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2F8ee9eb2d-c95a-4471-b9b3-72e53f78d722_2048x1028.png\"><picture class=\"article-picture article-picture-fallback\" style=\"--image-ratio:16 / 9\"><img src=\"https://substackcdn.com/image/fetch/$s_!xCw3!,w_1456,c_limit,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2F8ee9eb2d-c95a-4471-b9b3-72e53f78d722_2048x1028.png\" alt=\"\" loading=\"lazy\" decoding=\"async\" fetchpriority=\"low\" referrerpolicy=\"no-referrer\" class=\"progressive-image\"></picture></a></p>\n<p>Figure 28: Ling 2.5 and Qwen3.5 are both linear-attention hybrids, even though Ling swaps in Lightning Attention and MLA instead of the Qwen recipe (Original source <em><a target=\"_blank\" rel=\"noopener noreferrer\" href=\"https://magazine.sebastianraschka.com/p/a-dream-of-spring-for-open-weight\">A Dream of Spring for Open-Weight LLMs</a></em>).</p>\n<p>Ling 2.5 is aimed more at long-context efficiency than at absolute benchmark leadership. According to the Ling team, it was reported as substantially faster than Kimi K2 at 32k tokens, which is the practical payoff these hybrids are aiming for.</p>\n<p><a target=\"_blank\" rel=\"noopener noreferrer\" href=\"https://substackcdn.com/image/fetch/$s_!cinD!,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2Fb7d49b8b-9ebb-460e-9a51-20bc4126bda1_2048x1012.png\"><picture class=\"article-picture article-picture-fallback\" style=\"--image-ratio:16 / 9\"><img src=\"https://substackcdn.com/image/fetch/$s_!cinD!,w_1456,c_limit,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2Fb7d49b8b-9ebb-460e-9a51-20bc4126bda1_2048x1012.png\" alt=\"\" loading=\"lazy\" decoding=\"async\" fetchpriority=\"low\" referrerpolicy=\"no-referrer\" class=\"progressive-image\"></picture></a></p>\n<p>Figure 29: Ling 2.5 was presented as a strong efficiency upgrade, with much higher 32k-token throughput than Kimi K2 at the same 1-trillion-parameter scale (Original source <em><a target=\"_blank\" rel=\"noopener noreferrer\" href=\"https://huggingface.co/inclusionAI/Ling-2.5-1T\">Ling 2.5 model hub page</a></em>).</p>\n<p>Nemotron pushes the pattern further away from the transformer baseline. Nemotron 3 Nano is a Mamba-Transformer hybrid that interleaves Mamba-2 sequence-modeling blocks with sparse MoE layers and uses self-attention only in a small subset of layers.</p>\n<p>This is a more extreme version of the same basic tradeoff discussed above. Here, the lightweight sequence module is a Mamba-2 state-space block rather than a DeltaNet-style fast-weight update, but the basic tradeoff is similar.</p>\n<p><a target=\"_blank\" rel=\"noopener noreferrer\" href=\"https://substackcdn.com/image/fetch/$s_!QcU9!,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2F65b809c5-83be-4cf7-b4a6-e45d16ef86d3_1596x1562.webp\"><picture class=\"article-picture article-picture-fallback\" style=\"--image-ratio:16 / 9\"><img src=\"https://substackcdn.com/image/fetch/$s_!QcU9!,w_1456,c_limit,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2F65b809c5-83be-4cf7-b4a6-e45d16ef86d3_1596x1562.webp\" alt=\"\" loading=\"lazy\" decoding=\"async\" fetchpriority=\"low\" referrerpolicy=\"no-referrer\" class=\"progressive-image\"></picture></a></p>\n<p>Figure 30: Nemotron 3 Nano uses Mamba-2 for most of the sequence modeling work, with self-attention only appearing in a small subset of layers (Original source <em><a target=\"_blank\" rel=\"noopener noreferrer\" href=\"https://magazine.sebastianraschka.com/p/the-big-llm-architecture-comparison\">The Big LLM Architecture Comparison</a></em>).</p>\n<p>The larger Nemotron 3 Super keeps the Mamba-2 hybrid attention approach and adds other efficiency-oriented changes such as latent MoE and shared-weight multi-token prediction (MTP) for speculative decoding.</p>\n<p><a target=\"_blank\" rel=\"noopener noreferrer\" href=\"https://substackcdn.com/image/fetch/$s_!KvOc!,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2F75c26a29-a18e-4e14-8989-846b0171b9fa_1862x1656.png\"><picture class=\"article-picture article-picture-fallback\" style=\"--image-ratio:16 / 9\"><img src=\"https://substackcdn.com/image/fetch/$s_!KvOc!,w_1456,c_limit,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2F75c26a29-a18e-4e14-8989-846b0171b9fa_1862x1656.png\" alt=\"\" loading=\"lazy\" decoding=\"async\" fetchpriority=\"low\" referrerpolicy=\"no-referrer\" class=\"progressive-image\"></picture></a></p>\n<p>Figure 31: Nemotron 3 Super keeps the Mamba-2 hybrid attention pattern while adding latent MoE and shared-weight MTP on top (Original source <em><a target=\"_blank\" rel=\"noopener noreferrer\" href=\"https://magazine.sebastianraschka.com/p/the-big-llm-architecture-comparison\">The Big LLM Architecture Comparison</a></em>).</p>\n<p>Of course, there are many more (mostly niche) attention variants throughout the literature that I haven’t covered here. The focus of this article was on those that are currently used in state-of-the-art (open-weight) models.</p>\n<p>In particular, I am looking forward to (1) seeing the brand new <a target=\"_blank\" rel=\"noopener noreferrer\" href=\"https://arxiv.org/abs/2603.15569\">Mamba-3</a> layers getting integrated into the aforementioned hybrid architectures (replacing Gated DeltaNet) and (2) <a target=\"_blank\" rel=\"noopener noreferrer\" href=\"https://arxiv.org/abs/2603.15031\">attention residuals</a> being used in general.</p>\n<p>In practice, you may also wonder what the “best” architecture is at the moment. This is hard to answer, as there are no public experiments that train different architectures on the same training data etc.</p>\n<p>Hence, we can currently only answer what the best (trained) model choice is for a given problem. In my opinion, hybrid architectures are still a novelty, and the main selling point is mainly (long-context) efficiency versus just modeling performance. Hence, I think they are a great candidate for agent contexts (like OpenClaw).</p>\n<p>Personally, I think the problem with hybrid architectures is also that the inference stacks are not quite as optimized, yet, and I find that I get better tok/sec throughput when running LLMs locally using more classic setups like GPT-OSS with grouped-query attention.</p>\n<p>Anyways, I am curious to see what DeepSeek V4 has in store, since DeepSeek has been quite the reliable trend-setter in the recent 2 years.</p>\n<p>No posts</p>\n",
  "content_markdown": "I had originally planned to write about DeepSeek V4. Since it still hasn’t been released, I used the time to work on something that had been on my list for a while, namely, collecting, organizing, and refining the different LLM architectures I have covered over the past few years.\n\nSo, over the last two weeks, I turned that effort into an LLM architecture gallery (with 45 entries at the time of this writing), which combines material from earlier articles with several important architectures I had not documented yet. Each entry comes with a visual model card, and I plan to keep the gallery updated regularly.\n\nYou can find the gallery here: [https://sebastianraschka.com/llm-architecture-gallery/](https://sebastianraschka.com/llm-architecture-gallery/)\n\nAfter I shared the initial version, a few readers also asked whether there would be a poster version. So, there is now a [poster version via Redbubble](https://www.redbubble.com/i/poster/LLM-Architecture-Gallery-by-Ahead-of-AI/179274487/flk2). I ordered the Medium size (26.9 x 23.4 in) to check how it looks in print, and the result is sharp and clear. That said, some of the smallest text elements are already quite small at that size, so I would not recommend the smaller versions if you intend to have everything readable.\n\n[![](https://substackcdn.com/image/fetch/$s_!ceew!,w_1456,c_limit,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2F03198b65-472c-495e-92c0-62b6af66d720_1999x1313.jpeg)](https://substackcdn.com/image/fetch/$s_!ceew!,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2F03198b65-472c-495e-92c0-62b6af66d720_1999x1313.jpeg)\n\n*Figure 2: [Poster version](https://www.redbubble.com/i/poster/LLM-Architecture-Gallery-by-Ahead-of-AI/179274487/flk2) of the architecture gallery with some random objects for scale.*\n\nAlongside the gallery, I was/am also working on short explainers for a few core LLM concepts.\n\nSo, in this article, I thought it would be interesting to recap all the recent attention variants that have been developed and used in prominent open-weight architectures in recent years.\n\nMy goal is to make the collection useful both as a reference and as a lightweight learning resource. I hope you find it useful and educational!\n\nSelf-attention lets each token look at the other visible tokens in the sequence, assign them weights, and use those weights to build a new context-aware representation of the input.\n\nMulti-head attention (MHA) is the standard transformer version of that idea. It runs several self-attention heads in parallel with different learned projections, then combines their outputs into one richer representation.\n\n[![](https://substackcdn.com/image/fetch/$s_!GrJT!,w_1456,c_limit,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2Fa3ed41e9-86ee-4c1c-80a5-c9c2ed59dd9c_1366x1410.png)](https://substackcdn.com/image/fetch/$s_!GrJT!,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2Fa3ed41e9-86ee-4c1c-80a5-c9c2ed59dd9c_1366x1410.png)\n\nFigure 3: Olmo 2 as an example architecture using MHA.\n\nThe sections below start with a whirlwind tour of explaining self-attention to explain MHA. It’s more meant as a quick overview to set the stage for related attention concepts like grouped-query attention, sliding window attention, and so on. If you are interested in a longer, more detailed self-attention coverage, you might like my longer [Understanding and Coding Self-Attention, Multi-Head Attention, Causal-Attention, and Cross-Attention in LLMs](https://magazine.sebastianraschka.com/p/understanding-and-coding-self-attention) article.\n\n**EXAMPLE ARCHITECTURES**\n\n[GPT-2](https://sebastianraschka.com/llm-architecture-gallery/#card-gpt-2-xl-1-5b), [OLMo 2 7B](https://sebastianraschka.com/llm-architecture-gallery/#card-olmo-2-7b), and [OLMo 3 7B](https://sebastianraschka.com/llm-architecture-gallery/#card-olmo-3-7b)\n\nAttention predates transformers and MHA. Its immediate background is encoder-decoder RNNs for translation.\n\nIn those older systems, an encoder RNN would read the source sentence token by token and compress it into a sequence of hidden states, or in the simplest version into one final state. Then the decoder RNN had to generate the target sentence from that limited summary. This worked for short and simple cases, but it created an obvious bottleneck once the relevant information for the next output word lived somewhere else in the input sentence.\n\nIn short, the limitation is that the hidden state can’t store infinitely much information or context, and sometimes it would be useful to just refer back to the full input sequence.\n\nThe translation example below shows one of the limitations of this idea. For instance, a sentence can preserve many locally reasonable word choices and still fail as a translation when the model treats the problem too much like a word-by-word mapping. (The top panel shows an exaggerated example where we translate the sentence word by word; obviously, the grammar in the resulting sentence is wrong.) In reality, the correct next word depends on sentence-level structure and on which earlier source words matter at that step. Of course, this could still be translated fine with an RNN, but it would struggle with longer sequences or knowledge retrieval tasks because the hidden state can only store so much information as mentioned earlier.\n\n[![](https://substackcdn.com/image/fetch/$s_!jdH6!,w_1456,c_limit,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2F95e6491c-6457-4af0-83f3-b73310bad668_3566x2495.webp)](https://substackcdn.com/image/fetch/$s_!jdH6!,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2F95e6491c-6457-4af0-83f3-b73310bad668_3566x2495.webp)\n\nFigure 4: Translation can fail even when many individual word choices look reasonable because sentence-level structure still matters (Original source *[LLMs-from-scratch](https://github.com/rasbt/LLMs-from-scratch)*).\n\nThe next figure shows that change more directly. When the decoder is producing an output token, it should not be limited to one compressed memory path. It should be able to reach back to the more relevant input tokens directly.\n\n[![](https://substackcdn.com/image/fetch/$s_!T2XV!,w_1456,c_limit,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2Feaafc89d-0765-4e90-8f2b-881032cb2d5b_3415x1914.webp)](https://substackcdn.com/image/fetch/$s_!T2XV!,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2Feaafc89d-0765-4e90-8f2b-881032cb2d5b_3415x1914.webp)\n\nFigure 5: Attention breaks the RNN bottleneck by letting the current output position revisit the full input sequence instead of relying on one compressed state alone (Original source *[LLMs-from-scratch](https://github.com/rasbt/LLMs-from-scratch)*).\n\nTransformers keep that core idea from the aforementioned attention-modified RNN but remove the recurrence. In the classic *[Attention Is All You Need](https://arxiv.org/abs/1706.03762)* paper, attention becomes the main sequence-processing mechanism itself (instead of being just part of an RNN encoder-decoder.)\n\nIn transformers, that mechanism is called self-attention, where each token in the sequence computes weights over all other tokens and uses them to mix information from those tokens into a new representation. Multi-head attention is the same mechanism run several times in parallel.\n\nFor a sequence of `T` tokens, attention needs one row of weights per token, so overall we get a `T x T`matrix.\n\nEach row answers a simple question. When updating this token, how much should each visible token matter? In a decoder-only LLM, future positions are masked out, which is why the upper-right part of the matrix is grayed out in the figure below.\n\nSelf-attention is fundamentally about learning these token-to-token weight patterns, under a causal mask, and then using them to build context-aware token representations.\n\n[![](https://substackcdn.com/image/fetch/$s_!8wZw!,w_1456,c_limit,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2Fd6e9affd-687b-4170-b1d5-f8e3d2834d2b_3449x1646.webp)](https://substackcdn.com/image/fetch/$s_!8wZw!,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2Fd6e9affd-687b-4170-b1d5-f8e3d2834d2b_3449x1646.webp)\n\nFigure 6: A concrete masked attention matrix where each row belongs to one token, each entry is an attention weight, and future-token entries are removed by the causal mask (Original source *[Understanding and Coding Self-Attention](https://magazine.sebastianraschka.com/p/understanding-and-coding-self-attention)*).\n\nThe next figure shows how the transformer computes the attention matrix (`A`) from the input embeddings `X`, which is then used to produce the transformed inputs (`Z`).\n\nHere `Q`, `K`, and `V` stand for queries, keys, and values. The query for a token represents what that token is looking for, the key represents what each token makes available for matching, and the value represents the information that gets mixed into the output once the attention weights have been computed.\n\nThe steps are as follows:\n\n- `Wq`, `Wk`, and `Wv` are weight matrices that project the input embeddings into `Q`, `K`, and `V`\n\n- `QK^T` produces the raw token-to-token relevance scores\n\n- softmax converts those scores into the normalized attention matrix `A` that we discussed in the previous section\n\n- `A` is applied to `V` to produce the output matrix `Z`\n\nNote that the attention matrix is not a separate hand-written object. It emerges from `Q`, `K`, and softmax.\n\nThe next figure shows the same concept as the previous figure but the attention matrix computation is hidden inside the “scaled-dot-product attention” box, and we perform the computation only for one input token instead of all input tokens. This is to show a compact form of self-attention with a single head before extending this to multi-head attention in the next section.\n\n[![](https://substackcdn.com/image/fetch/$s_!VJyp!,w_1456,c_limit,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2F7dfb70d9-5eb6-44df-a880-3a37dfe72d7f_1836x1116.png)](https://substackcdn.com/image/fetch/$s_!VJyp!,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2F7dfb70d9-5eb6-44df-a880-3a37dfe72d7f_1836x1116.png)\n\nFigure 8: One attention head is already a complete mechanism. One set of learned projections produces one attention matrix and one context-aware output stream (Original source *[Understanding and Coding Self-Attention](https://magazine.sebastianraschka.com/p/understanding-and-coding-self-attention)*).\n\nOne set of `Wq/Wk/Wv` matrices gives us one attention head, which means one attention matrix and one output matrix `Z`. (This concept was illustrated in the previous section.)\n\nMulti-head attention simply runs several of these heads in parallel with different learned projection matrices.\n\nThis is useful because different heads can specialize in different token relationships. One head might focus on short local dependencies, another on broader semantic links, and another on positional or syntactic structure.\n\n[![](https://substackcdn.com/image/fetch/$s_!MSOX!,w_1456,c_limit,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2F5f47ffd2-bb3a-4936-9720-a88b8d867337_1766x1154.png)](https://substackcdn.com/image/fetch/$s_!MSOX!,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2F5f47ffd2-bb3a-4936-9720-a88b8d867337_1766x1154.png)\n\nFigure 9: Multi-head attention keeps the same basic attention recipe, but repeats it across several heads in parallel so the model can learn several token-to-token patterns at once (Original source *[Understanding and Coding Self-Attention](https://magazine.sebastianraschka.com/p/understanding-and-coding-self-attention)*).\n\nGrouped-query attention is an attention variant derived from standard MHA. It was introduced in the 2023 paper *[GQA: Training Generalized Multi-Query Transformer Models from Multi-Head Checkpoints](https://arxiv.org/abs/2305.13245)* by Joshua Ainslie and colleagues.\n\nInstead of giving every query head its own keys and values, it lets several query heads share the same key-value projections, which makes [KV caching](https://magazine.sebastianraschka.com/p/coding-the-kv-cache-in-llms?utm_source=publication-search) much cheaper (primarily as a memory reduction) without changing the overall decoder recipe very much.\n\n[![](https://substackcdn.com/image/fetch/$s_!h6wM!,w_1456,c_limit,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2F6f39923c-8357-487d-9e69-40ee18a902e8_2523x1248.png)](https://substackcdn.com/image/fetch/$s_!h6wM!,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2F6f39923c-8357-487d-9e69-40ee18a902e8_2523x1248.png)\n\nFigure 10: GQA keeps the same overall attention pattern as MHA, but collapses the number of key-value heads by sharing them across multiple query heads (Original source: *[The Big LLM Architecture Comparison](https://magazine.sebastianraschka.com/p/the-big-llm-architecture-comparison)*).\n\n**EXAMPLE ARCHITECTURES**\n\nDense: [Llama 3 8B](https://sebastianraschka.com/llm-architecture-gallery/#card-llama-3-8b), [Qwen3 4B](https://sebastianraschka.com/llm-architecture-gallery/#card-qwen3-4b), [Gemma 3 27B](https://sebastianraschka.com/llm-architecture-gallery/#card-gemma-3-27b), [Mistral Small 3.1 24B](https://sebastianraschka.com/llm-architecture-gallery/#card-mistral-small-3-1-24b), [SmolLM3 3B](https://sebastianraschka.com/llm-architecture-gallery/#card-smollm3-3b), and [Tiny Aya 3.35B](https://sebastianraschka.com/llm-architecture-gallery/#card-tiny-aya-3-35b).\\\nSparse (Mixture-of-Experts): [Llama 4 Maverick](https://sebastianraschka.com/llm-architecture-gallery/#card-llama-4-maverick), [Qwen3 235B-A22B](https://sebastianraschka.com/llm-architecture-gallery/#card-qwen3-235b-a22b), [Step 3.5 Flash 196B](https://sebastianraschka.com/llm-architecture-gallery/#card-step-3-5-flash-196b), and [Sarvam 30B](https://sebastianraschka.com/llm-architecture-gallery/#card-sarvam-30b).\n\nIn my [architecture comparison article](https://magazine.sebastianraschka.com/p/the-big-llm-architecture-comparison), I framed GQA as the new standard replacement for classic multi-head attention (MHA). The reason is that standard MHA gives every head its own keys and values, which is more optimal from a modeling perspective but expensive once we have to keep all of that state in the [KV cache](https://magazine.sebastianraschka.com/p/coding-the-kv-cache-in-llms?utm_source=publication-search) during inference.\n\nIn GQA, we keep a larger set of query heads, but we reduce the number of key-value heads and let multiple queries share them. That lowers both parameter count and [KV-cache](https://magazine.sebastianraschka.com/p/coding-the-kv-cache-in-llms?utm_source=publication-search) traffic without making drastic implementation changes like multi-head latent attention (MLA), which will be discussed later.\n\nIn practice, that made and keeps it a very popular choice for labs that wanted something cheaper than MHA but simpler to implement than newer compression-heavy alternatives like MLA.\n\nGQA results in big savings in KV storage, since the fewer key-value heads we keep per layer, the less cached state we need per token. That is why GQA becomes more useful as sequence length grows.\n\nGQA is also a spectrum. If we reduce all the way down to one shared K/V group, we are effectively in multi-query attention territory, which is even cheaper but can hurt modeling quality more noticeably. The sweet spot is usually somewhere in between multi-query attention (1 shared group) and MHA (where K/V groups are equal to the number of queries), where the cache savings are large but the modeling degradation relative to MHA stays modest.\n\nMore advanced variants such as MLA are becoming popular because they can offer better modeling performance at the same KV efficiency levels (e.g., as discussed in the ablation studies of the [DeepSeek-V2 paper](https://arxiv.org/abs/2405.04434)), but they also involve a more complicated implementation and a more complicated attention stack.\n\nGQA remains appealing because it is robust, easier to implement, and also easier to train (since there are fewer hyperparameter tunings necessary, based on my experience).\n\nThat is why some of the newer releases still stay deliberately classic here. E.g., in my [Spring Architectures](https://magazine.sebastianraschka.com/p/a-dream-of-spring-for-open-weight) article, I mentioned that MiniMax M2.5 and Nanbeige 4.1 as models that remained very classic, using only grouped-query attention without piling on other efficiency tricks. Sarvam is a particularly useful comparison point as well: the 30B model keeps classic GQA, while the 105B version switches to MLA.\n\n[![](https://substackcdn.com/image/fetch/$s_!BMEL!,w_1456,c_limit,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2F2d04f89a-aad5-4af7-8b46-4623d1d53ae9_5860x5682.webp)](https://substackcdn.com/image/fetch/$s_!BMEL!,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2F2d04f89a-aad5-4af7-8b46-4623d1d53ae9_5860x5682.webp)\n\nFigure 12: Total KV cache sizes for 105B Sarvam (using MLA) versus 30B Sarvam (using GQA), versus using plain MHA.\n\nThe motivation behind Multi-head Latent Attention (MLA) is similar to Grouped-Query Attention (GQA). Both are solutions for reducing [KV-cache](https://magazine.sebastianraschka.com/p/coding-the-kv-cache-in-llms?utm_source=publication-search) memory requirements. The difference between GQA and MLA is that MLA shrinks the cache by compressing what gets stored rather than by reducing how many K/Vs are stored by sharing heads.\n\n[![](https://substackcdn.com/image/fetch/$s_!FcJB!,w_1456,c_limit,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2Fe29cb535-8854-4412-af8d-9bca8d8d05f2_1550x858.webp)](https://substackcdn.com/image/fetch/$s_!FcJB!,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2Fe29cb535-8854-4412-af8d-9bca8d8d05f2_1550x858.webp)\n\nFigure 13: Unlike GQA, MLA does not reduce KV cost by grouping heads. It reduces it by caching a compressed latent representation. Note that it is also applied to the query, which is not shown for simplicity (Original source:*[The Big LLM Architecture Comparison](https://magazine.sebastianraschka.com/p/the-big-llm-architecture-comparison)*).\n\nMLA, originally proposed in the [DeepSeek-V2](https://arxiv.org/abs/2405.04434) paper, became such a defining DeepSeek-era idea (especially after DeepSeek-V3 and R1). It is more complicated to implement than GQA, more complicated to serve, but nowadays also often more compelling once model size and context length get large enough that cache traffic starts to dominate, because at the same rate of memory reduction, it could maintain better modeling performance (more on that later).\n\n**EXAMPLE ARCHITECTURES**\n\n[DeepSeek V3](https://sebastianraschka.com/llm-architecture-gallery/#card-deepseek-v3), [Kimi K2](https://sebastianraschka.com/llm-architecture-gallery/#card-kimi-k2), [GLM-5](https://sebastianraschka.com/llm-architecture-gallery/#card-glm-5-744b), [Ling 2.5](https://sebastianraschka.com/llm-architecture-gallery/#card-ling-2-5-1t), [Mistral Large 3](https://sebastianraschka.com/llm-architecture-gallery/#card-mistral-large-3), and [Sarvam 105B](https://sebastianraschka.com/llm-architecture-gallery/#card-sarvam-105b)\n\nInstead of caching full-resolution key and value tensors as in MHA and GQA, MLA stores a latent representation and reconstructs the usable state when needed. Essentially, it is a cache compression strategy embedded inside attention, as illustrated in the previous figure.\n\nThe figure below shows the savings compared to regular MHA.\n\n[![](https://substackcdn.com/image/fetch/$s_!56rA!,w_1456,c_limit,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2F186dfe98-db29-4b12-97ab-39d5b21ab460_1920x1440.png)](https://substackcdn.com/image/fetch/$s_!56rA!,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2F186dfe98-db29-4b12-97ab-39d5b21ab460_1920x1440.png)\n\nFigure 14: Once context length grows, the savings from caching a latent representation instead of full K/V tensors become very visible (Original source: *[LLMs-from-scratch](https://github.com/rasbt/LLMs-from-scratch/tree/main/ch04/05_mla)*[MLA](https://github.com/rasbt/LLMs-from-scratch/tree/main/ch04/05_mla) section).\n\nThe DeepSeek-V2 paper provided some ablations where GQA looked worse than MHA in terms of modeling performance, while MLA held up much better and could even outperform MHA when tuned carefully. That is a much stronger justification than “it (also) saves memory.”\n\nIn other words, MLA is a preferable attention mechanism for DeepSeek not just because it was efficient, but because it looked like a quality-preserving efficiency move at large scale. (But colleagues also told me that MLA only works well at a certain size. For smaller models, let’s say <100B, GQA seems to work better, or, is at least easier to tune and get right.)\n\n[![](https://substackcdn.com/image/fetch/$s_!1yW7!,w_1456,c_limit,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2Ff564ec9f-5fcb-49c3-b728-b4c8a769bb6c_952x902.png)](https://substackcdn.com/image/fetch/$s_!1yW7!,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2Ff564ec9f-5fcb-49c3-b728-b4c8a769bb6c_952x902.png)\n\nFigure 15: GQA drops below MHA here, while MLA remains competitive and can even slightly outperform it. Underlying paper: [DeepSeek-V2](https://arxiv.org/abs/2405.04434).\n\nBelow is again the comparison between GQA in 30B Sarvam versus MLA in 105B Sarvam.\n\n[![](https://substackcdn.com/image/fetch/$s_!cbqs!,w_1456,c_limit,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2Fa425874e-baae-45bb-a199-46648c5db725_5860x5682.webp)](https://substackcdn.com/image/fetch/$s_!cbqs!,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2Fa425874e-baae-45bb-a199-46648c5db725_5860x5682.webp)\n\nFigure 16: GQA and MLA are solving the same bottleneck from different directions. The tradeoff is simplicity versus better modeling performance for larger models.\n\nOnce DeepSeek V3/R1, V3.1 etc. normalized the design after its introduction in V2, it started showing up in a second wave of architectures. Kimi K2 kept the DeepSeek recipe and scaled it up. GLM-5 adopted MLA together with DeepSeek Sparse Attention (from DeepSeek V3.2). Ling 2.5 paired MLA with a linear-attention hybrid. Sarvam released two models where the 30B model stayed with classic GQA and the 105B model switched to MLA.\n\nThat last pair is particularly useful as it puts the technical-complexity discussion aside. I.e., the Sarvam team implemented both variants and deliberately chose to then use GQA for one variant and MLA for the other. So, in a sense, that makes MLA feel less like a theoretical alternative and more like a concrete architectural upgrade path once a family scales up.\n\nSliding window attention reduces the memory and compute cost of long-context inference by limiting how many previous tokens each position can attend to. Instead of attending to the entire prefix, each token only attends to a fixed window of recent tokens around its position. Because attention is restricted to a local token neighborhood, this mechanism is often referred to as local attention.\n\nSome architectures combine these local layers with occasional global attention layers so that information can still propagate across the entire sequence.\n\n[![](https://substackcdn.com/image/fetch/$s_!edFZ!,w_1456,c_limit,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2F48a9cd31-24a5-47d9-ae37-506763ebc67d_1292x704.png)](https://substackcdn.com/image/fetch/$s_!edFZ!,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2F48a9cd31-24a5-47d9-ae37-506763ebc67d_1292x704.png)\n\nFigure 17: The conceptual shift is simple. Regular attention is global attention, while sliding-window attention is local attention. Global attention lets every token see the full prefix; SWA turns many of those layers into local attention layers (Original source: *[The Big LLM Architecture Comparison](https://magazine.sebastianraschka.com/p/the-big-llm-architecture-comparison)*).\n\n**EXAMPLE ARCHITECTURES**\n\n[Gemma 3 27B](https://sebastianraschka.com/llm-architecture-gallery/#card-gemma-3-27b), [OLMo 3 32B](https://sebastianraschka.com/llm-architecture-gallery/#card-olmo-3-32b), [Xiaomi MiMo-V2-Flash](https://sebastianraschka.com/llm-architecture-gallery/#card-xiaomi-mimo-v2-flash-309b), [Arcee Trinity](https://sebastianraschka.com/llm-architecture-gallery/#card-arcee-ai-trinity-large-400b), [Step 3.5 Flash](https://sebastianraschka.com/llm-architecture-gallery/#card-step-3-5-flash-196b), and [Tiny Aya](https://sebastianraschka.com/llm-architecture-gallery/#card-tiny-aya-3-35b)\n\nGemma 3 is still one of the clearest recent SWA examples because it is easy to compare against Gemma 2. Gemma 2 already used a hybrid attention setup with a 1:1 ratio between local and global layers and a 4096-token window. Gemma 3 pushed this further to a 5:1 ratio and reduced the window size to 1024.\n\nThe key finding was not that local attention is cheaper, because that was already known. Here, the more interesting takeaway from the Gemma 3 ablation study was that using this more aggressively seemed to hurt modeling performance only slightly.\n\nIn practice, saying that a model “uses SWA” does not mean it relies on SWA alone. What usually matters are the local-to-global layer pattern and the attention window size. For example:\n\n- Gemma 3 and Xiaomi use a 5:1 local-to-global pattern.\n\n- OLMo 3 and Arcee Trinity use a 3:1 pattern.\n\n- Xiaomi also uses a window size of 128, which is much smaller, and therefore more aggressive, than Gemma’s 1024.\n\nSWA is essentially a knob that can be tuned more or less aggressively.\n\n[![](https://substackcdn.com/image/fetch/$s_!3FBb!,w_1456,c_limit,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2F38e10000-db6c-43fa-844b-ed7d4dfe644c_3299x3302.webp)](https://substackcdn.com/image/fetch/$s_!3FBb!,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2F38e10000-db6c-43fa-844b-ed7d4dfe644c_3299x3302.webp)\n\nFigure 18: The long-context savings come from turning many full-attention layers into local ones, which reduces how much cached context those layers need to consider (Original source: *[LLMs-from-scratch](https://github.com/rasbt/LLMs-from-scratch/tree/main/ch04/06_swa)*[SWA materials](https://github.com/rasbt/LLMs-from-scratch/tree/main/ch04/06_swa)).\n\nSWA often appears together with [GQA](http://127.0.0.1:4000/llm-architecture-gallery/gqa/) because the two ideas address different parts of the same inference problem. SWA reduces how much context a local layer has to consider. GQA reduces how much key-value state each token contributes to the cache.\n\nThat is why many recent dense models use both rather than treating them as alternatives. Gemma 3 is again a good reference point here, since it combines sliding window attention with grouped-query attention in the same architecture.\n\nDeepSeek Sparse Attention is one of the architectural changes that appeared in the [DeepSeek V3.2](https://arxiv.org/abs/2512.02556) line and later showed up again in GLM-5.\n\nSpecifically, DeepSeek V3.2 combines it with [Multi-head Latent Attention (MLA)](https://sebastianraschka.com/llm-architecture-gallery/mla/), and GLM-5 adopts the same pair for the same general reason, namely, reducing inference cost when context lengths get large.\n\n**EXAMPLE ARCHITECTURES**\n\n[DeepSeek V3.2](https://sebastianraschka.com/llm-architecture-gallery/#card-deepseek-v3-2) and [GLM-5](https://sebastianraschka.com/llm-architecture-gallery/#card-glm-5-744b)\n\nIn sliding-window attention, the current token does not attend to the full prefix but only to a fixed local window. This is the same broad idea behind DeepSeek Sparse Attention, where each token also only attends to a subset of previous tokens.\n\nHowever, the selected tokens are not determined by a fixed-width local window. Instead, DeepSeek Sparse Attention uses a learned sparse pattern. In short, it uses an indexer-plus-selector setup, where a lightning indexer computes relevance scores, and a token selector keeps only a smaller set of high-scoring past positions.\n\nThe way the subset of tokens is selected is the main difference from sliding-window attention. Sliding-window attention hard-codes locality. DeepSeek Sparse Attention still limits attention to a subset, but it lets the model decide which prior tokens are worth revisiting.\n\nDeepSeek V3.2 uses both Multi-head Latent Attention (MLA) and DeepSeek Sparse Attention. MLA reduces [KV-cache](https://magazine.sebastianraschka.com/p/coding-the-kv-cache-in-llms?utm_source=publication-search) cost by compressing what gets stored. DeepSeek Sparse Attention reduces how much of the prior context the model has to revisit. Put differently, one optimizes the cache representation, the other optimizes the attention pattern on top of it.\n\n[![](https://substackcdn.com/image/fetch/$s_!B4GF!,w_1456,c_limit,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2Fad5026e1-1dbd-4004-814f-6cd6d735e572_2787x2731.webp)](https://substackcdn.com/image/fetch/$s_!B4GF!,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2Fad5026e1-1dbd-4004-814f-6cd6d735e572_2787x2731.webp)\n\nFigure 20: DeepSeek V3.2 is the obvious reference point, because this is the model family most closely associated with the sparse-attention idea.\n\nThe sparse pattern is not random. The first stage is a lightning indexer that scores previous tokens for each new query token. It uses MLA’s compressed token representations and computes a learned similarity score over the prior context, so the model can rank which earlier positions are worth revisiting.\n\nThe second stage is a token selector. It keeps only a smaller high-scoring subset, for example, a top-`k`set of past positions, and turns that subset into the sparse attention mask. So the main point is that DeepSeek Sparse Attention does not hard-code the sparsity pattern. It learns which past tokens to keep.\n\nDeepSeek Sparse Attention is relatively new and relatively complicated to implement, which is why it has not been so widely adopted as Grouped-Query Attention (GQA) yet.\n\nGated attention is best understood as a modified full-attention block rather than as a separate attention family.\n\nIt usually appears inside hybrid stacks that still keep an occasional full-attention layer for exact content retrieval, but add a few stability-oriented changes on top of an otherwise familiar scaled dot-product attention block.\n\n[![](https://substackcdn.com/image/fetch/$s_!syqZ!,w_1456,c_limit,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2F2d109b38-96a1-4830-b1f0-7274e405317a_3973x5350.webp)](https://substackcdn.com/image/fetch/$s_!syqZ!,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2F2d109b38-96a1-4830-b1f0-7274e405317a_3973x5350.webp)\n\nFigure 22: Trinity Large is a useful comparison because gated attention is not only a Qwen idea (more on that later). Here the gate appears after the scaled dot-product attention output and before the output projection in a different long-context architecture (Original source: *[A Dream of Spring for Open-Weight LLMs](https://magazine.sebastianraschka.com/p/a-dream-of-spring-for-open-weight)*).\n\nThe Qwen3-Next and Qwen3.5 architectures show that recent hybrids (covered in the next section) do not replace attention everywhere. Instead, they replace most attention layers with a cheaper alternative and keep a smaller number of full-attention layers in the stack.\n\nThose remaining full-attention layers are where gated attention typically appears. Qwen3-Next and Qwen3.5 use it together with Gated DeltaNet in a 3:1 pattern.\n\nBut hybrid architectures aside, Trinity uses a related gating idea in a more conventional attention stack, as shown in the previous figure above.\n\nThe gated attention block in Qwen-style hybrids or Trinity (not a hybrid) is essentially standard scaled-dot-product attention with a few changes on top. In the original [Gated Attention paper](https://arxiv.org/abs/2505.06708), those changes are presented as a way to make the retained full-attention layers behave more predictably inside a hybrid stack.\n\nThe block still looks like standard (full) attention, but it adds:\n\n1. an output gate that scales the attention result before it is added back to the residual,\n\n2. a zero-centered QK-Norm variant instead of standard RMSNorm for q and k,\n\n3. partial RoPE.\n\nThese are not changes on the scale of MLA or linear attention but merely stability and control changes applied to an otherwise familiar attention block.\n\n[![](https://substackcdn.com/image/fetch/$s_!VVeK!,w_1456,c_limit,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2Fafe94d77-ab5f-4420-88e4-8ba1f91992e0_2484x3278.webp)](https://substackcdn.com/image/fetch/$s_!VVeK!,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2Fafe94d77-ab5f-4420-88e4-8ba1f91992e0_2484x3278.webp)\n\nFigure 23: In Qwen3-Next and Qwen3.5, gated attention appears as the full-attention layer that periodically breaks up runs of Gated DeltaNet blocks.\n\nNote that the figure above also includes Gated DeltaNet, which we will cover in the next section below.\n\nHybrid attention is a broader design pattern rather than a specific, single mechanism. The overall idea is to keep a transformer-like stack, but replace most of the expensive full-attention layers with cheaper linear or state-space sequence modules.\n\nThe motivation is long-context efficiency. Full attention grows quadratically with sequence length, so once models move to contexts like 128k, 256k, or 1M tokens, attention memory and compute become expensive enough that using cheaper sequence modules in most layers while keeping only a smaller number of heavier retrieval layers starts making more sense. (Note that this comes with a bit of a modeling performance trade-off, though.)\n\nIn Qwen3-Next, this pattern appears as a 3:1 mix of Gated DeltaNet and Gated Attention blocks. Gated DeltaNet is also closely related to Mamba-2 (see the *[Gated Delta Networks: Improving Mamba2 with Delta Rule](https://arxiv.org/abs/2412.06464)* paper, for instance), and the mechanism can be read as a DeltaNet-style fast-weight update combined with Mamba-style gating. Later architectures keep the same overall idea but swap in other lightweight sequence mixers, such as Kimi Delta Attention, Lightning Attention, or standard Mamba-2.\n\n[![](https://substackcdn.com/image/fetch/$s_!XRZY!,w_1456,c_limit,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2F876009cb-5479-4e95-9b7d-faebe1f87e89_3252x2158.webp)](https://substackcdn.com/image/fetch/$s_!XRZY!,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2F876009cb-5479-4e95-9b7d-faebe1f87e89_3252x2158.webp)\n\nFigure 24: The basic hybrid pattern, where most blocks are cheaper sequence mixers and every fourth block restores a heavier attention layer (Original source *[The Big LLM Architecture Comparison](https://magazine.sebastianraschka.com/p/the-big-llm-architecture-comparison)*).\n\nTo my knowledge, the first prominent example of a close-to-flagship LLM with hybrid attention was Qwen3-Next in 2025, which does not remove attention completely but mixes three Gated DeltaNet blocks with one Gated Attention block.\n\nHere, lightweight Gated DeltaNet blocks do most of the long-context work and keep memory growth much flatter than full attention. The heavier gated-attention layer remains because DeltaNet is less exact at content-based retrieval.\n\nInside a Gated DeltaNet block, the model computes query, key, and value vectors together with two learned gates (α, β). Rather than forming the usual token-to-token attention matrix, it writes to a small fast-weight memory using a delta-rule update. In rough terms, the memory stores a compressed running summary of past information, while the gates control how much new information is added and how much previous state is retained.\n\nThat makes Gated DeltaNet a linear-attention or recurrent-style mechanism rather than just another tweak to MHA. Relative to Mamba-2, the close connection is that both belong to the linear-time gated sequence-model family, but Gated DeltaNet uses a DeltaNet-style fast-weight memory update instead of the Mamba state-space update.\n\n[![](https://substackcdn.com/image/fetch/$s_!hK9M!,w_1456,c_limit,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2Fb82c3202-6c49-4cd7-a4eb-ab18edcd908e_2100x1350.png)](https://substackcdn.com/image/fetch/$s_!hK9M!,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2Fb82c3202-6c49-4cd7-a4eb-ab18edcd908e_2100x1350.png)\n\nFigure 25: The practical motivation behind the hybrids is shown here in the memory curve. Hybrid stacks with Gated DeltaNet grow much more slowly with context length than ordinary full attention (Original source *[LLMs-from-scratch](https://github.com/rasbt/LLMs-from-scratch/tree/main/ch04/08_deltanet)*[DeltaNet materials](https://github.com/rasbt/LLMs-from-scratch/tree/main/ch04/08_deltanet)).\n\nQwen3.5 moves the former Qwen3-Next hybrid into Qwen’s main flagship series, which is an interesting move. This basically signals that the hybrid strategy is a success and that we may see more models with this architecture in the future.\n\n[![](https://substackcdn.com/image/fetch/$s_!L9cU!,w_1456,c_limit,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2F11deeb70-5766-41eb-bc93-b7c8f81afcb7_2048x1281.png)](https://substackcdn.com/image/fetch/$s_!L9cU!,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2F11deeb70-5766-41eb-bc93-b7c8f81afcb7_2048x1281.png)\n\nFigure 26: Qwen3.5 shows the Qwen team promoting the former Qwen3-Next side-branch into the main model line rather than leaving it as a one-off efficiency variant (Original source *[A Dream of Spring for Open-Weight LLMs](https://magazine.sebastianraschka.com/p/a-dream-of-spring-for-open-weight)*).\n\nKimi Linear keeps the same broad transformer skeleton and the same 3:1 pattern, but it changes both halves of the recipe.\n\nOn the lightweight side, Kimi Delta Attention is a refinement of Gated DeltaNet. Where Qwen3-Next uses a scalar gate per head to control memory decay, Kimi uses channel-wise gating, which gives finer control over the memory update. On the heavier side, Kimi replaces Qwen3-Next’s gated-attention layers with gated MLA layers.\n\nSo, it’s still the same broader pattern as in Qwen3-Next and Qwen3.5, but both ingredients (slightly) change. I.e., most layers are still handled by a cheaper linear-style mechanism, and periodic heavier layers still remain for stronger retrieval.\n\n[![](https://substackcdn.com/image/fetch/$s_!Q1wq!,w_1456,c_limit,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2F38f5b449-f122-4520-b6ea-a2437fd9508e_2376x1572.webp)](https://substackcdn.com/image/fetch/$s_!Q1wq!,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2F38f5b449-f122-4520-b6ea-a2437fd9508e_2376x1572.webp)\n\nFigure 27: Kimi Linear keeps the same overall hybrid pattern while changing both the lightweight side and the heavier attention side of the stack (Original source *[The Big LLM Architecture Comparison](https://magazine.sebastianraschka.com/p/the-big-llm-architecture-comparison)*).\n\nLing 2.5 shows another swap on the lightweight side. Instead of Gated DeltaNet, Ling uses a slightly simpler recurrent linear attention variant called Lightning Attention. On the heavier side, it keeps MLA from DeepSeek.\n\nMost sequence mixing happens in the cheaper linear-attention blocks, while a smaller number of heavier layers remain to preserve stronger retrieval. The difference is that the specific lightweight mechanism is now Lightning Attention rather than DeltaNet or Kimi Delta Attention.\n\n[![](https://substackcdn.com/image/fetch/$s_!xCw3!,w_1456,c_limit,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2F8ee9eb2d-c95a-4471-b9b3-72e53f78d722_2048x1028.png)](https://substackcdn.com/image/fetch/$s_!xCw3!,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2F8ee9eb2d-c95a-4471-b9b3-72e53f78d722_2048x1028.png)\n\nFigure 28: Ling 2.5 and Qwen3.5 are both linear-attention hybrids, even though Ling swaps in Lightning Attention and MLA instead of the Qwen recipe (Original source *[A Dream of Spring for Open-Weight LLMs](https://magazine.sebastianraschka.com/p/a-dream-of-spring-for-open-weight)*).\n\nLing 2.5 is aimed more at long-context efficiency than at absolute benchmark leadership. According to the Ling team, it was reported as substantially faster than Kimi K2 at 32k tokens, which is the practical payoff these hybrids are aiming for.\n\n[![](https://substackcdn.com/image/fetch/$s_!cinD!,w_1456,c_limit,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2Fb7d49b8b-9ebb-460e-9a51-20bc4126bda1_2048x1012.png)](https://substackcdn.com/image/fetch/$s_!cinD!,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2Fb7d49b8b-9ebb-460e-9a51-20bc4126bda1_2048x1012.png)\n\nFigure 29: Ling 2.5 was presented as a strong efficiency upgrade, with much higher 32k-token throughput than Kimi K2 at the same 1-trillion-parameter scale (Original source *[Ling 2.5 model hub page](https://huggingface.co/inclusionAI/Ling-2.5-1T)*).\n\nNemotron pushes the pattern further away from the transformer baseline. Nemotron 3 Nano is a Mamba-Transformer hybrid that interleaves Mamba-2 sequence-modeling blocks with sparse MoE layers and uses self-attention only in a small subset of layers.\n\nThis is a more extreme version of the same basic tradeoff discussed above. Here, the lightweight sequence module is a Mamba-2 state-space block rather than a DeltaNet-style fast-weight update, but the basic tradeoff is similar.\n\n[![](https://substackcdn.com/image/fetch/$s_!QcU9!,w_1456,c_limit,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2F65b809c5-83be-4cf7-b4a6-e45d16ef86d3_1596x1562.webp)](https://substackcdn.com/image/fetch/$s_!QcU9!,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2F65b809c5-83be-4cf7-b4a6-e45d16ef86d3_1596x1562.webp)\n\nFigure 30: Nemotron 3 Nano uses Mamba-2 for most of the sequence modeling work, with self-attention only appearing in a small subset of layers (Original source *[The Big LLM Architecture Comparison](https://magazine.sebastianraschka.com/p/the-big-llm-architecture-comparison)*).\n\nThe larger Nemotron 3 Super keeps the Mamba-2 hybrid attention approach and adds other efficiency-oriented changes such as latent MoE and shared-weight multi-token prediction (MTP) for speculative decoding.\n\n[![](https://substackcdn.com/image/fetch/$s_!KvOc!,w_1456,c_limit,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2F75c26a29-a18e-4e14-8989-846b0171b9fa_1862x1656.png)](https://substackcdn.com/image/fetch/$s_!KvOc!,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2F75c26a29-a18e-4e14-8989-846b0171b9fa_1862x1656.png)\n\nFigure 31: Nemotron 3 Super keeps the Mamba-2 hybrid attention pattern while adding latent MoE and shared-weight MTP on top (Original source *[The Big LLM Architecture Comparison](https://magazine.sebastianraschka.com/p/the-big-llm-architecture-comparison)*).\n\nOf course, there are many more (mostly niche) attention variants throughout the literature that I haven’t covered here. The focus of this article was on those that are currently used in state-of-the-art (open-weight) models.\n\nIn particular, I am looking forward to (1) seeing the brand new [Mamba-3](https://arxiv.org/abs/2603.15569) layers getting integrated into the aforementioned hybrid architectures (replacing Gated DeltaNet) and (2) [attention residuals](https://arxiv.org/abs/2603.15031) being used in general.\n\nIn practice, you may also wonder what the “best” architecture is at the moment. This is hard to answer, as there are no public experiments that train different architectures on the same training data etc.\n\nHence, we can currently only answer what the best (trained) model choice is for a given problem. In my opinion, hybrid architectures are still a novelty, and the main selling point is mainly (long-context) efficiency versus just modeling performance. Hence, I think they are a great candidate for agent contexts (like OpenClaw).\n\nPersonally, I think the problem with hybrid architectures is also that the inference stacks are not quite as optimized, yet, and I find that I get better tok/sec throughput when running LLMs locally using more classic setups like GPT-OSS with grouped-query attention.\n\nAnyways, I am curious to see what DeepSeek V4 has in store, since DeepSeek has been quite the reliable trend-setter in the recent 2 years.\n\nNo posts\n",
  "dateCreated": "2026-09-27T19:29:15.293681927+00:00",
  "date_created": "2026-03-22T11:55:40+00:00",
  "date_modified": "2026-03-22T11:55:40+00:00",
  "date_published": "2026-03-22T11:55:40+00:00",
  "description": "From MHA and GQA to MLA, sparse attention, and hybrid architectures",
  "external_url": "https://magazine.sebastianraschka.com/p/visual-attention-variants",
  "git": {
    "commit": "ebb0941c5c06a2ab2377342d607535262a3e969e",
    "path": "items/magazine-sebastianraschka-com/2026/03/2026-03-22-a-visual-guide-to-attention-variants-in-modern-llms.md",
    "permalink": "https://github.com/aymericbeaumet/aggr-instance/blob/ebb0941c5c06a2ab2377342d607535262a3e969e/items/magazine-sebastianraschka-com/2026/03/2026-03-22-a-visual-guide-to-attention-variants-in-modern-llms.md"
  },
  "id": "urn:aggr:item:b19aa0df5e41a1a8affaeafa22e65b0efd36d6a8",
  "isBasedOn": {
    "@id": "https://magazine.sebastianraschka.com/p/visual-attention-variants"
  },
  "mainEntity": {
    "@id": "https://magazine.sebastianraschka.com/p/visual-attention-variants",
    "@type": "CreativeWork",
    "archivedAt": {
      "@id": "https://aggr.aymericbeaumet.com/items/magazine-sebastianraschka-com/2026-03-22-a-visual-guide-to-attention-variants-in-modern-llms/#webpage"
    },
    "author": [
      {
        "@type": "Person",
        "name": "Sebastian Raschka, PhD"
      }
    ],
    "dateModified": "2026-03-22T11:55:40+00:00",
    "datePublished": "2026-03-22T11:55:40+00:00",
    "headline": "A Visual Guide to Attention Variants in Modern LLMs",
    "timeRequired": "PT23M",
    "url": "https://magazine.sebastianraschka.com/p/visual-attention-variants",
    "wordCount": 4989
  },
  "name": "Archived snapshot: A Visual Guide to Attention Variants in Modern LLMs",
  "preview": null,
  "reading_minutes": 23,
  "replicated_at": null,
  "source": "magazine-sebastianraschka-com",
  "source_name": "Ahead of AI",
  "summary": "From MHA and GQA to MLA, sparse attention, and hybrid architectures",
  "tags": [],
  "temporalCoverage": "2026-09-27T19:29:15.293681927+00:00",
  "title": "A Visual Guide to Attention Variants in Modern LLMs",
  "url": "https://aggr.aymericbeaumet.com/items/magazine-sebastianraschka-com/2026-03-22-a-visual-guide-to-attention-variants-in-modern-llms/",
  "word_count": 4989
}